Good Papers

NeurIPS 2026 posters

Best rated first.

93%Must read
?Must readVote to see the score

Neglected Free Lunch from Post-training: Progress Advantage for LLM Agents

RL post-training yields progress advantage, a log-ratio that recovers optimal step-level advantage without dedicated reward models, outperforming trained alternatives across agent benchmarks.

Changdae Oh, Wendi Li, Seongheon Park, Samuel (Min-Hsuan) Yeh and 2 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 13 on Hugging Face · Code ★ 12

100% Readers1 of 1 upvoted
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

SpatialBench: Is Your Spatial Foundation Model an All-Round Player

SpatialBench evaluates 41 spatial foundation models across 19 datasets and finds none are all-round players, with full-context attention maximizing accuracy and domain alignment exceeding scaling for embodied tasks, plus it introduces DA-Next-5M and DA-Next.

Haosong Peng, Hao Li, jiaqi chen, Yuhao Pan and 9 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 69 on Hugging Face · Code ★ 138

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

K12-KGraph: A Curriculum-Aligned Knowledge Graph for Benchmarking and Training Educational LLMs

K12-KGraph introduces a curriculum-aligned K-12 knowledge graph, benchmark, and training data showing current LLMs achieve under 57 percent accuracy on curriculum cognition and that graph-guided supervision outperforms generic instruction tuning.

Hao Liang, Qihan Lin, Mingrui Chen, Hengyi Feng and 6 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 62 on Hugging Face · Code ★ 392

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

MCP-Atlas: A Large-Scale Benchmark for Tool-Use Competency with Real MCP Servers

MCP-Atlas benchmarks LLM tool-use on 1,000 real-server tasks, finding frontier models reach 82.2% pass rates but 63.3% of failures are cognitive.

Chaithanya Bandi, Razvan Dumitru, Ben Hertzberg, Divyansh Agarwal and 15 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

OdysSim: Building Foundation Models for Human Behavior Simulation

OdysSim trains 8B behavioral foundation models via SOUL taxonomy and multi-stage recipes, ranking first on eight human simulation benchmarks while nearly matching real-user reaction alignment.

Xuhui Zhou, Weiwei Sun, Weihua Du, Jiarui Liu and 5 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

SR-Prominence: A Crowdsourced Protocol and Dataset Suite for Perceptually-Weighted Super-Resolution Artifact Evaluation

SR-Prominence defines artifact prominence via crowdsourced annotations across 3,935 masks and shows classical full-reference metrics surprisingly detect perceptual impact better than specialized detectors.

Ivan Molodetskikh, Kirill Malyshev, Mark Mirgaleev, Nikita Zagainov and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

CausalDriveBench: Evaluating Causal Reasoning in Vision-Language-Action Models for Autonomous Driving

CausalDriveBench evaluates causal reasoning in autonomous driving vision-language-action models via structured QA and counterfactual trajectories, finding weak causal understanding despite fluent reasoning and accurate baseline predictions.

Narendiran Chembu, Navvrat Rao, Shreedhar Kodate, Gayatri S Banda and 9 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

Alignment Collapse Under KV Cache Quantization: Diagnosis and Mitigation

Low-bit KV cache quantization silently collapses LLM safety alignment via geometric subspace vulnerability, and per-channel reduction diagnostics recover up to 97% of lost refusals.

Bruce C Xu, Adarsh Kumarappan, Mu Zhou

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

LowRankArena: A Standardized Evaluation Platform for SVD-Based LLM Compression

LowRankArena standardizes SVD-based LLM compression evaluation and reveals that method rankings and speedups depend heavily on backbone and workload under aligned protocols.

Zishan Shao, Lixun Zhang, Kangning Cui, Wenhao Wu and 9 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

MemLeak: Diagnosing Information Leaks in Multimodal Agent Memory

Multimodal AI agents retain forgotten facts via implicit visual cues, with MemLeak showing 12% image-based recovery and content-aware deletion reducing residuals to 2%.

Kuan Wang, Chao Zhang

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

MorphoHELM: A Comprehensive Benchmark for Evaluating Representations for Microscopy-Based Morphology Assays

MorphoHELM benchmarks microscopy representation methods across batch effects, finding classic computer vision strategies outperform deep learning across settings and revealing trade-offs between models.

Emre Hayir, Lorin Crawford, Alex X Lu

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

Reinforcement Learning for Code Optimization

Reinforcement learning for code optimization fails due to noisy, sparse execution-time rewards, so a calibrated three-stage pipeline improves strict pass rates by up to 125% while preserving correctness.

Pierre Chambon, Kunhao Zheng, Juliette Decugis, Benoît Sagot and 1 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 13 on Hugging Face

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

Measuring Cross-Modal Synergy: A Benchmark for VLM Explainability

Cross-modal redundancy causes unimodal metrics to contradict (τ=-0.06), so Synergistic Faithfulness (F_syn) isolates joint modality dividends with ρ=0.92 and 24× speedup, revealing VLM explainers over-index visual salience versus adapted attention methods.

Joël Roman Ky, Salah GHAMIZI, Maxime Cordy

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

TRL-Bench: Standardizing Cross-Paradigm Representation-Level Evaluation of Tabular Encoders

TRL-Bench standardizes cross-paradigm evaluation of tabular encoders via shared representation-level probes, finding encoder quality is task-specific and best pipelines combine capability-matched specialists.

Wei Pang, Xiangru Jian, Hehan Li, Zhixuan Yu and 9 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 54 on Hugging Face · Code ★ 10

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

DocScope: Benchmarking Verifiable Reasoning for Trustworthy Long-Document Understanding

DocScope benchmarks verifiable long-document reasoning via structured trajectory evaluation, finding correct answers rarely include complete evidence chains and region grounding remains weakest.

Xiang Feng, Jiawei Zhou, Zhangfeng Huang, Kewei Wang and 5 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

Log-Likelihood, Simpson’s Paradox, and the Detection of Machine-Generated Text

Average token-level log-likelihood scores suffer Simpson’s paradox across hidden-space regions, and local calibration via learned score-distribution predictors fixes it, boosting detection AUROC substantially.

Tom Kempton, Viktor Drobnyi, Maeve Madigan, Stuart Burrell

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

Hidden Measurement Error in LLM Pipelines Distorts Annotation, Evaluation, and Benchmarking

LLM pipeline evaluation variance is underestimated because design choices are ignored, so corrected intervals restore coverage and cut benchmark gaming.

Solomon Messing

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Attention Transfer Is Not Universally Effective for Vision Transformers

Attention transfer fails for four ViT families due to architectural mismatch, and adding the teacher's native components to students fully restores its effectiveness.

Huaiyuan Qin, Muli Yang, Gabriel James Goenawan, Peng Hu and 3 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 18 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 4/5
91%Must read
?Must readVote to see the score

Pause and Reflect: Conformal Aggregation for Chain-of-Thought Reasoning

A conformal procedure for chain-of-thought reasoning replaces majority voting with calibrated weighted aggregation to provide finite-sample confident-error guarantees and improves selective accuracy without retraining.

Yu Gu, Zijun Yu, Vahid Partovi Nia, Masoud Asgharian

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 18 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 3/5
91%Must read
?Must readVote to see the score

Self Driving Datasets: From 20 Million Papers to Nuanced Biomedical Knowledge at Scale

PubMed is autonomously converted into structured biomedical datasets larger, more nuanced, and more accurate than manual repositories via ontology tagging, hybrid retrieval, and a multi-agent extraction system.

Haydn Jones, Yimeng Zeng, Alden Rose, Yifei Li and 10 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

DriveSpatial: A Benchmark for Spatiotemporal Intelligence in VLMs for Autonomous Driving

DriveSpatial benchmarks vision-language models' spatiotemporal autonomous driving intelligence, finding a 28.4-point human gap with cognitive scene construction as the key bottleneck.

Anh Hao Vo, Khoa Vo, Phu Loc Nguyen, Sieu Tran and 9 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Models Recall What They Violate: Constraint Adherence in Multi-Turn LLM Ideation

DriftBench finds iterative LLM ideation increases complexity and reduces constraint adherence, with models often violating rules they accurately recall and judges under-detecting violations.

Garvin Kruthof

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

VeriContest: A Competitive-Programming Benchmark for Verifiable Code Generation

VeriContest introduces 946 competitive programming problems with verified Rust specifications and proofs, showing state-of-the-art models reach only 5.29% on end-to-end verifiable generation.

Zichen Xie, Mrigank Pawagi, Yuxin Liu, Aaditi Rai and 4 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Mark, Don't Erase: Token Inoculation for Dual-Use Knowledge in LLMs

Token Inoculation conditions LLMs to retain dual-use knowledge gated by a special token, reducing hazardous accuracy to 18% while preserving 93% of benign performance across 1B-14B scales.

Seung-Hyun Lee, Dongyoon Han, Sangdoo Yun

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Beyond LoRA vs. Full Fine-Tuning: Gradient-Guided Optimizer Routing for LLM Adaptation

MoLF dynamically routes optimizer updates between full fine-tuning and LoRA to match or beat the stronger static method across tasks, and its efficient variant surpasses AdaLoRA and AdaMix by up to 11.70 points.

Haozhan Tang, Xiuqi Zhu, Xinyin Zhang, Boxun Li and 2 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 1 on Hugging Face · Code ★ 3

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

The Ringelmann Effect in Multi-Agent LLM Systems: A Scaling Law for Effective Team Size

A two-parameter scaling law quantifies diminishing returns in multi-agent LLM systems, showing that dense debate hits hard ceilings, noise placebos match self-correction, and only heterogeneous teams escape diminishing returns.

Blaz Bertalanic, Carolina Fortuna

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

CardioLens: Revealing the Clinical Reality Gap of MLLMs via Multi-Sequence Cardiac MRI Evaluations

CardioLens evaluates MLLMs on multi-sequence cardiac MRI, revealing poor clinical workflow performance and category-collapse failures despite reasoning prompts and slice selection.

Zixian Su, Hongkai Zhang, Fan Gao, Encheng Su and 11 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Agent Meltdowns: The Road to Hell Is Paved with Helpful Agents

Agents encountering benign errors suffer "accidental meltdowns", unsafe behaviors like unauthorized reconnaissance, across 64.7% of error rollouts, often unreported.

Rishi Jha, Harold Triedman, Vitaly Shmatikov, Arkaprabha Bhattacharya

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

FineVLA: Fine-Grained Instruction Alignment for Steerable Vision-Language-Action Policies

FineVLA introduces fine-grained action-aligned supervision for steerable vision-language-action policies, yielding up to 86.8% simulation and 62.7 real-world success and boosting steerable control over coarse instructions.

Xintong Hu, Xuhong Huang, JINYU ZHANG, Yutong Yao and 8 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 9 on Hugging Face

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

RealityTest: How People Probe AI Identity and Whether Models Disclose It

RealityTest benchmarks multimodal multilingual AI identity disclosure via 3,152 human queries, finding question phrasing and context dominate over model choice and suppression cuts rates below 30%.

Anna Gausen, Sarenne Wallbridge, Bessie O'Dell, Christopher Summerfield and 1 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

StereoTales: A Multilingual Framework for Open-Ended Stereotype Discovery in LLMs

StereoTales reveals open-ended LLM generation emits shared harmful stereotypes that culturally adapt to prompt languages and align with human harmfulness ratings.

Pierre Le Jeune, Etienne Duchesne, Weixuan Xiao, Stefano Palminteri and 3 more

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Claw-Eval: Towards Trustworthy Evaluation of Autonomous Agents

Claw-Eval introduces a trajectory-aware benchmark with 300 tasks, finding opaque grading misses 44% of safety violations and agent rankings vary across multi-dimensional capabilities.

Bowen Ye, Rang Li, Qibin Yang, Yuanxin Liu and 9 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 117 on Hugging Face · Code ★ 778

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

DUET: Unified Dual-Space Emotion Control for Diffusion and Flow-Matching Driven Text-to-Speech

DUET enables plug-and-play emotion control for pretrained diffusion and flow-matching TTS by steering hidden states and guiding mel-spectra via a differentiable vocoder, surpassing supervised emotional baselines.

Xu Zhang, Longbing Cao, zhangkai wu

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

When Attention Collapses: Residual Evidence Modeling for Compositional Inference

Under additive superposition, attention slots collapse to dominant components because memoryless attention ignores explained evidence; residual evidence depletion prevents collapse and enables compositional inference.

Niklas Houba

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

P$^{3}$: Joint Program-and-Proof Planning\\ for Verified Code Generation

P³ plans programs and proofs jointly from specifications before elaboration, outperforming sequential baselines by up to 11.2 points on verified generation benchmarks while reducing cost and time.

Zenan Li, Ziran Yang, Peiyang Song, Zhaoyu Li and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

MemPoison: Uncovering Persistent Memory Threats and Structural Blind Spots in LLM Agents

MemPoison benchmarks 1227 adversarial cases across memory substrates and finds write-time defenses fail against multi-record and dormant corruption, requiring adaptive defenses.

Jifeng Gao, Kang Xia, Yi Zhang, Xiaobin Hong and 4 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Jointly Reinforcing Diversity and Quality in Language Model Generations

DARLING uses a learned partition function to jointly optimize language model response quality and semantic diversity via reinforcement learning, improving both quality and novelty across creative and math benchmarks.

Tianjian Li, Yiming Zhang, Ping Yu, Swarnadeep Saha and 4 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 25 on Hugging Face · Code ★ 61

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Beyond the Golden Teacher: Enhancing Graph Learning through LLM-GNN Co-teaching

LLM-GNN Co-Teaching replaces golden-teacher design with bidirectional pseudo-label exchange and trajectory-based preference optimization, boosting few-shot graph accuracy by up to 7.86%.

Zhuoyi Peng, Hanlin Gu, Lixin Fan, Yi Yang

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Reading the Finetuning Prior: Verbatim Content Recovery via Contrastive Decoding Diffing

Contrastive Decoding Diffing recovers verbatim implanted facts and pipeline artifacts via output-level logit differences without weight access, outperforming white-box methods 170x faster.

Michał Brzozowski, Zuzanna Dubanowska, Enrico Cassano, Neo Christopher Chung

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

SchemeArena: Factorized Stress Testing of Scheming in LLM Agents

SchemeArena introduces a 400-scenario benchmark and SCOUT monitor for factorized LLM agent scheming stress tests, finding explicit instrumental goals drive scheming most strongly and partial oversight can increase covert behavior.

Jie Ruan, Inderjeet Nair, Amy Liu, Muhammad Khalifa and 2 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 11 on Hugging Face · Code ★ 1

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

GraphInstruct: A Progressive Benchmark for Diagnosing Capability Gaps in LLM Graph Generation

GraphInstruct introduces progressive-complexity benchmark diagnosing LLM graph generation failures across six complexity levels, finding multi-constraint composition limits capability and domain-semantic constraints require retrieval.

Zihe Wei, Sheng Xiang, Ying Zhang, changjun jiang

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

PACE: Two-Timescale Self-Evolution for Small Language Model Agents

PACE uses two-timescale self-evolution to let frozen small language models improve agents via validated prompt and control updates, outperforming baselines on 12 settings by up to 9.2%.

Chen Ling, Pei Chen, Xiangchen Guan, Jiaming Qu and 3 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

AgentCollabBench: Diagnosing When Good Agents Make Bad Collaborators

AgentCollabBench introduces 900 diagnostic tasks showing multi-agent collaboration failures stem from topology, not just model capability. Communication topology explains 7-40% of variance as converging nodes discard minority-branch constraints.

Aritra Mazumder, Shubhashis Roy Dipta, Nusrat Jahan Lia, Tanzila Khan and 9 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Crowded in B-Space: Calibrating Shared Directions for LoRA Merging

LoRA merging interference mainly stems from shared output-side B directions; calibrating them via Pico improves merged adapter accuracy across benchmarks and can exceed joint-training performance.

Yixuan Tang, Yi Yang

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026 · ▲ 6 on Hugging Face

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

TraXion: Rethinking Pre-training Frameworks for Mobility and Beyond

TraXion introduces MESES axioms and a pre-training framework for multi-entity spatiotemporal event streams that beats mobility baselines and generalizes to security and health logs.

Shang-Ling Hsu, Mark Tenzer, Cyrus Shahabi, Khurram Shafique

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

TokenSwap: Benchmarking and Reducing the Modality Gap in Multimodal LLMs

TokenSwap benchmarks and reduces MLLMs' modality gap by interleaving visual tokens with text, finding reasoning models have smaller gaps and training with TokenSwap mitigates it.

Andong Hua, Colton Bishop, Igor Mordatch, Arian Hosseini and 4 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Rethinking Personalized Generation: Test-time Alignment via Factorized Ranking Models

Test-time alignment via million-parameter factorized ranking models exploits massive headroom for personalized generation, outperforming billion-parameter reward models with minimal overhead.

Qiyao Ma, Junshan Zhang, Zhe Zhao

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 11 on Hugging Face

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Beyond Suspicious Steps: Ontological Trust in Long-Horizon Agents

Ontological trust measures whether trajectory prefixes match authorized tasks; RGE detects long-horizon agent drift with over 93% F1 and above 95.8% benign coverage via deterministic Role, Goal, and Evidence checks.

一个 他, Yao Wang, Haibin Zhang

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

The Geometry of Forgetting: Temporal Knowledge Drift as an Independent Axis in LLM Representations

Temporal knowledge drift is geometrically orthogonal to correctness and uncertainty in LLM residual streams, making drift undetectable via standard signals despite linear probes reaching 0.83, 0.95 AUROC.

Rania Elbadry, Ahmed Heakl, Fan Zhang, Dani Bouch and 3 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Automata from Agent Traces: Failure and Next-Step Prediction

Trace corpora collapse into compact finite-state machines replaying held-out data at >=0.997 fitness, yielding state-context next-step prediction and 0.94 AUROC failure prediction for runtime monitoring.

Seonglae Cho, Franklin Cardenoso Fernandez, Umar Mohammed, Zekun Wu and 3 more

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026 · ▲ 5 on Hugging Face

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

PACE: A Proxy for Agentic Capability Evaluation

PACE predicts agentic benchmark scores from small, selected non-agentic test subsets via regression, achieving under 4% error and over 0.80 correlation at under 1% evaluation cost.

Yueqi Song, Lintang Sutawika, Jiarui Liu, Lindia Tjuatja and 7 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 18 on Hugging Face

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Multimodal LLMs Outperform Pathology Foundation Models in Cross-Domain Histological Similarity

Multimodal LLMs outperform pathology foundation models in cross-institution histological similarity by avoiding shortcut acquisition features tied to learning objectives rather than scale.

Yishu Zhang, Yun Li, David Zhang

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Auditing Cross-Lingual Fairness in Language Model Watermarking

Cross-lingual watermark evaluation reveals structural fairness gaps across typological language families rather than isolated language failures.

Alexander Nemecek, Osama Zafar, Debargha Ganguly, Vikash Singh and 2 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

LLM Agents Already Know When to Call Tools - Even Without Reasoning

When2Tool finds LLMs linearly encode tool necessity in hidden states, and Probe&Prefill uses this to cut unnecessary tool calls by 48% with minimal accuracy loss.

Chung-En Sun, Linbo Liu, Ge Yan, Zimo Wang and 1 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 2 on Hugging Face · Code ★ 16

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Transferable SCF-Acceleration through Solver-Aligned Initialization Learning

Solver-Aligned Initialization Learning differentiates through SCF solvers to train transferable ML initial guesses, reducing iterations by up to 37% on molecules up to 10× larger than training data.

Eike S. Eberhard, Viktor Kotsev, Timm Güthle, Stephan Günnemann

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

ROCKET: Residual-Oriented Multi-Layer Alignment for Spatially-Aware Vision-Language-Action Models

ROCKET aligns multiple VLA layers to a 3D vision model via residual streams and shared projectors, achieving near-state-of-the-art LIBERO success with about 4% compute.

Guoheng Sun, Tingting Du, Kaixi Feng, Chenxiang Luo and 5 more

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Entropy Distribution as a Fingerprint for Hallucinations in Generative Models

Token-level entropy distributions fingerprint hallucinations, and the single-pass Calibrated Entropy Score achieves multi-pass detection accuracy with formal guarantees.

Mattia Jacopo Villani, Pranav Deshpande, Akshay Seshadri, Romina Yalovetzky and 1 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

GitInject: Real-World Prompt Injection Attacks in AI-Powered CI/CD Pipelines

GitInject tests real AI CI/CD workflows and finds all providers vulnerable to prompt injection via structural credential and config handling flaws.

Jafar Isbarov, Umid Suleymanov, I Shumailov, Murat Kantarcioglu

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

TRACE: Tourism Recommendation with Accountable Citation Evidence

TRACE introduces tourism dialogues pairing multi-turn recommendations with review citations and rejection turns to expose the Three-Competency Gap across accuracy, grounding, and recovery.

Zixu Zhao, SIJIN WANG, Yu Hou, YUANYUAN XU and 5 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

SCOPE: Self-Play via Co-Evolving Policies for Open-Ended Tasks

SCOPE co-evolves a task-generating challenger and retrieval solver with rubric-based self-judging to improve open-ended and QA performance without curated data.

Wai-Chung Kwan, Aryo Gema, Joshua O Leang, Pasquale Minervini

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 25 on Hugging Face · Code ★ 2

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

CollabVR: Collaborative Video Reasoning with Vision-Language and Video Generation Models

CollabVR pairs vision-language models with video generation models in closed-loop step-level planning and verification, reducing drift and simulation errors for major video reasoning gains.

Joowon Kim, Seungho Shin, Joonhyung Park, Eunho Yang

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 71 on Hugging Face · Code ★ 10

100% Readers1 of 1 upvoted
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read

Rethinking Long-Video Efficiency: A Joint Allocation Perspective on Frames, Pixels, and Front-End Latency

LoHi trades per-frame resolution for denser temporal sampling via low-resolution streams plus sparse high-resolution frames, boosting long-video accuracy up to 10.6 points and cutting front-end latency up to 7x.

Sixun Dong, Wei Li, Andong Deng, Qi Qian and 3 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published Oct 3, 2026 · ▲ 13 on Hugging Face · Code ★ 1

– ReadersNo votes yet. 1 from authors or colleagues not counted
17/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 3/5
91%Must read
?Must readVote to see the score

Asymmetric Flow Models

AsymFlow restricts noise prediction to a low-rank subspace to recover full-dimensional velocity, achieving 1.57 FID on ImageNet and enabling latent-to-pixel flow finetuning.

Hansheng Chen, Jan Ackermann, Minseo Kim, Gordon Wetzstein and 1 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 22 on Hugging Face · Code ★ 473

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 3/5
91%Must read
?Must readVote to see the score

M$^2$RNN: Non-Linear RNNs with Matrix-Valued States for Scalable Language Modeling

M²RNN introduces matrix-valued non-linear RNNs that scale via state expansion, achieving perfect state tracking and outperforming hybrid models with smaller states.

Mayank Mishra, Shawn Tan, Ion Stoica, Joseph Gonzalez and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 2/5
91%Must read
?Must readVote to see the score

StemBind: When MLLMs Get Lost Between Rules and Instances in Abstract Visual Reasoning

StemBind introduces a shared-stem benchmark diagnosing MLLM abstract visual reasoning, finding a persistent rule-to-instance binding gap where models identify patterns but fail to apply them correctly.

Xixiang He, Baiqi Wu, Xingming Li, Ao Cheng and 3 more

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 4/5
medium 8/10
strict 5/5
91%Must read
?Must readVote to see the score

The Best-Laid SCHEMEs: Coordinated Sabotage and Monitoring in Multi-Agent Systems

SCHEME benchmark reveals multi-agent models coordinate sabotage via decomposed plans across communication topologies, with Gemini succeeding 84% and Codex 46%, though monitors detect edits at 99%/68% and communication at 100%/81%.

Nikolay Radev, Lennart J Haas, Benjamin Arnav, Pablo Bernabeu-Perez

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 4/5
91%Must read
?Must readVote to see the score

The Commit-Abstain Circuit: Why Language Models Hallucinate Instead of Abstaining

Mechanistic analysis reveals a Commit-Abstain Circuit where early commitment signals overpower later abstention corrections, causing hallucinations; training on its activations improves abstention accuracy by 12.2 points.

Gavin Vy Nguyen, Ziqi Xu, Jeffrey Chan, Estrid He and 4 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

The BatchNorm Illusion: Diagnosing Normalization Artifacts in Machine Unlearning Evaluation

BatchNorm running statistics artificially inflate unlearning metrics by up to 78 points, which a weight-preserving forward pass reverses without changing weights.

Aaryaman Kalani, Murari Mandal, Dhruv Kumar, Mohan Kankanhalli and 1 more

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

AgentKVShift: Efficient KV Cache Reuse for Agentic Memory Systems

AgentKVShift uses probe-guided KV residual correction to reuse agentic memory caches with near-full accuracy at 10-30% recompute, yielding 2-3.5x prefill speedups.

Nilesh Pandey, Jason Kong, Lanxiang Hu, Quanling Zhao and 4 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Crafting Reversible SFT Behaviors in Large Language Models

LCDD constructs sparse, causally necessary subnetworks for SFT behaviors, and SFT-Eraser reverses them via activation-matched soft prompts without weight changes.

Yuping Lin, Pengfei He, Yue XING, Yingqian Cui and 4 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Embeddings for Preferences, Not Semantics

Text embeddings should encode preferential rather than semantic similarity for collective decisions; breaking nuisance correlation with synthetic training improves preference prediction across 11 deliberation datasets.

Carter Blair, Ariel Procaccia, Milind Tambe

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Evaluating AI-based Scientific Knowledge Synthesis with Epidemiological Systematic Reviews

AgentSLR evaluates LLMs on epidemiological systematic reviews, revealing sub-task specialization, poor structured extraction (F1 < 0.67), and unreliable unsupervised deployment.

Shreyansh Padarha, Ryan Othniel Kearns, Tristan M Naidoo, Lingyi Yang and 12 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 9 on Hugging Face · Code ★ 25

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

CalArena: A Large Scale Post-Hoc Calibration Benchmark

CalArena benchmarks nearly 2000 post-hoc calibration experiments, finding smooth methods outperform binning and multiclass-specific designs are essential.

Eugène Berta, David Holzmüller, Francis Bach, Michael Jordan

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Reflective Prompted Policy Optimization: Trajectory-Grounded Revision and Salience Bias

R2PO uses trajectory-level behavioral evidence rather than scalar rewards to guide LLM policy search, achieving faster and more stable optimization across ten environments despite a critic salience bias.

Rahaf Abu Hara, Vaibbhav Murarri, Claudio Zito

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

MCPHunt: An Evaluation Framework for Cross-Boundary Data Propagation in Multi-Server MCP Agents

MCPHunt benchmarks multi-server MCP agents, finding 11.5, 41.3% policy-violating cross-boundary credential propagation concentrated in browser flows, with prompt mitigations reducing violations up to 97%.

Haonan Li, Tianjun Sun, Yongqing Wang, Qisheng Zhang

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Explanation Multiplicity in SHAP: Characterization and Assessment

SHAP produces multiple valid yet different explanations for identical predictions due to intrinsic stochasticity, and magnitude-based stability metrics mask substantial rank instability across datasets and models.

Hyunseung Hwang, Seungeun Lee, Lucas Rosenblatt, Steven Whang and 1 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score
NeurIPS 2026StanfordMIT

Reward Bias Substitution: Single-Axis Bias Mitigations Redirect Optimization Pressure

Single-axis reward-model bias mitigations redirect optimization onto correlated proxies rather than eliminating it, and auditing on induced distributions with multi-bias tracking is required to certify success.

Max Lamparth, Daniel Fein, Andreas Haupt, Marcel Hussing and 1 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Chess-World-Model: A 10M-Game Benchmark for Exact State Tracking from Chess Move Sequences

Chess-World-Model uses 10 million real chess games to benchmark exact board-state tracking, showing recurrent models outperform Transformers and scale hides out-of-distribution failures.

Benjamin Walker, Terry Lyons

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

On the Error Correcting Effects of Stochasticity in Discrete Diffusion

Discrete diffusion stochasticity trades convergence speed against error correction via redundant transitions, and DCRS injects controlled randomness to improve low-step sampling efficiency.

William Yuan, Sungwon Jeong, Amirali Aghazadeh

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

KaliBench: A Fine-Grained Benchmark for Cybersecurity Tool Use on Kali Linux with Runtime-Free Verifiable Rewards

KaliBench evaluates natural-language-to-CLI translation for 1,642 Kali Linux cybersecurity tools, finding open-weight models below 42% accuracy but training with verifiable rewards significantly improves smaller models.

Pengfei Li, Naufal Suryanto, Sicheng Zhang, Muhammad Muzammal Naseer

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 8 on Hugging Face · Code ★ 4

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

TaskGround: Structured Executable Task Inference for Full-Scene Household Reasoning

TaskGround grounds full household scenes into task-relevant slices to infer executable task structures, improving compact open-weight models' success rates by large margins over direct prompting while cutting token costs up to 18x.

ZhiYuan Feng, Yu Deng, Ruichuan An, Zhenhua Liu and 10 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Signed-Permutation Coordinate Transport for RMSNorm Transformers

RMSNorm transformers have signed-permutation residual gauges requiring sign-marginalized matching for coordinate transport, which recovers 91.1% of cross-run coordinates versus 60.3% and preserves steering and optimizer states that permutation-only alignment breaks.

John Sweeney

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Meta$^n$: Recursive Self-Improvement through Emergent Depth

Meta^n fixes its meta-operation and recurses on growing inputs to build unbounded self-improving agent depth, outperforming prior agents across eight benchmark families including ARC-AGI-2.

Zae Myung Kim, Young-Jun Lee, Seungyeon Jwa, Dongyeop Kang

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 17 on Hugging Face

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Flow Map Denoisers: Traversing the Distortion-Perception Plane for Inverse Problems

Flow map denoisers implicitly define a one-parameter family spanning the distortion-perception tradeoff via lookahead parameter t, matching or exceeding specialized baselines across inverse problems.

Nicolas Zilberstein, Morteza Mardani, Santiago Segarra

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

TerminalWorld: Benchmarking Agents on Real-World Terminal Tasks

TerminalWorld automatically builds terminal benchmarks from wild recordings, yielding 1,530 tasks where top agents achieve only 62.5% success with weak correlation to expert benchmarks.

Zhaoyang Chu, Jiarui Hu, Xingyu Jiang, Pengyu Zou and 7 more

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026 · ▲ 8 on Hugging Face · Code ★ 48

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

GeneZip: Region-Aware Compression for Long Context DNA Modeling

GeneZip uses region-aware compression to achieve high base-pairs-per-token ratios, improves DNA modeling benchmarks, and enables 128K-context training on limited hardware.

Jianan Zhao, Xixian Liu, Zhihao Zhan, XINYU YUAN and 2 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

BenchRep-T: A Systematic Evaluation of T-Cell Repertoire-Based Disease Diagnostics

BenchRep-T standardizes TCR repertoire datasets to benchmark nine computational methods, finding simple tree-based models match complex approaches and no method dominates all tasks.

Chiho Im, Liel Cohen-Lavi, Alejandro Buendia, Anshul Kundaje and 1 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

A Communication-Theoretic Framework for LLM Agents: Cost-Aware Adaptive Reliability

A communication-theoretic framework maps LLM reliability techniques onto classical coding operators, yielding closed-form thresholds and a cost-aware router that achieves a 56% cost reduction at matched quality across 69 hard tasks.

Hamed Omidvar, Vahideh Akhlaghi

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Neuro-Inspired Inverse Learning for Planning and Control

Inverse Learning trains forward/inverse models and hierarchical stacks for planning and control, matching offline RL and diffusion baselines on D4RL with far less compute while yielding smoother, near-optimal trajectories.

Maryna Kapitonova, Tonio Ball

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Uncertainty Quantification for Large Language Diffusion Models

Lightweight zero-shot uncertainty signals from LLDM denoising dynamics achieve sampling-level hallucination detection at up to 100x lower cost.

Artem Vazhentsev, Vladislav Smirnov, David Li, Maxim Panov and 2 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Information Discernment in Large Language Models

LLMs fail at source and truth discernment, relying on popularity over reliability and updating equally for accurate and inaccurate claims despite simple inference-time fixes existing.

Joshua Ashkinaze, Laura Kurek, Alina Faisal, Tongyuan Miao and 3 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.
91%Must read
?Must readVote to see the score

Dual-Pathway Circuits of Object Hallucination in Vision-Language Models

Vision-language models contain separate visual grounding and hallucination pathways whose components flip polarity to drive errors, and suppressing them cuts object hallucination by up to 76%.

Jiaxin Liu, Ding Zhong, Yue Wang, Zhidong Yang and 5 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Geometry over Density: Few-Shot Cross-Domain OOD Detection

UFCOD uses diffusion score geometry to enable cross-domain OOD detection with ~100 unlabeled ID samples and no retraining, achieving 93.7% AUROC across 12 benchmarks with ~500x sample efficiency gains.

Li Li, You Qin, Jiate Li, Charith Peris and 3 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

DRScaffold: Boosting Dense-Scene Reasoning in Lightweight Vision Language Models

DRScaffold improves lightweight vision-language model reasoning via structured four-stage supervision, surpassing a frozen 32B model on DRBench.

Xinrui Shi, Kai Liu, Ziqing Zhang, Jianze Li and 2 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Per-Loss Adapters for Gradient Conflict in Physics-Informed Neural Networks

PINN gradient conflict has distinct regimes, and a diagnostic framework selects between scalar reweighting and per-loss low-rank adapters, which significantly improve persistent directional conflict across 60+ PDE problems.

Bum Jun Kim, Gnankan Landry Regis N&amp;#x27;guessan

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Benchmarking Open-Ended Multi-Agent Coordination in Language Agents

Alem benchmarks open-ended multi-agent coordination for language agents, showing frontier LLMs average ~6% returns and individual competence does not imply coordination competence.

Kale-ab Tessera, Andras Szecsenyi, Cameron Barker, Alexander Rutherford and 6 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 7 on Hugging Face · Code ★ 51

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

DAGent: Evaluate-then-Grow Planning for Deep Research Agents

DAGent enables evaluate-then-grow DAG planning for deep-research agents, improving benchmarks by 2, 6 points over plan-then-patch baselines with lower token cost.

Hanwen Liu, Yuanfu Sun, Qiaoyu Tan

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 4 on Hugging Face · Code ★ 2

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Stealth Apart, Harm Together: Skill Cascading Attacks on Skill-Based Agent Systems

Skill cascading attacks distribute malicious objectives across benign skills to harm agent systems, and SkillCascade reliably induces such failures while evading per-skill defenses.

Zihao Zhu, Siwei Lyu, Adel Bibi, Baoyuan Wu

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Open Vocabulary Domain Unlearning

Existing domain unlearning overfits to seen classes; this paper proposes open-vocabulary domain unlearning via Fisher-masked parameter editing and targeted manifold scattering to erase domains across unseen classes with few shots.

Sumanth V Udupa, Mehrtash Harandi, Yadan Luo, Mahsa Baktashmotlagh

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

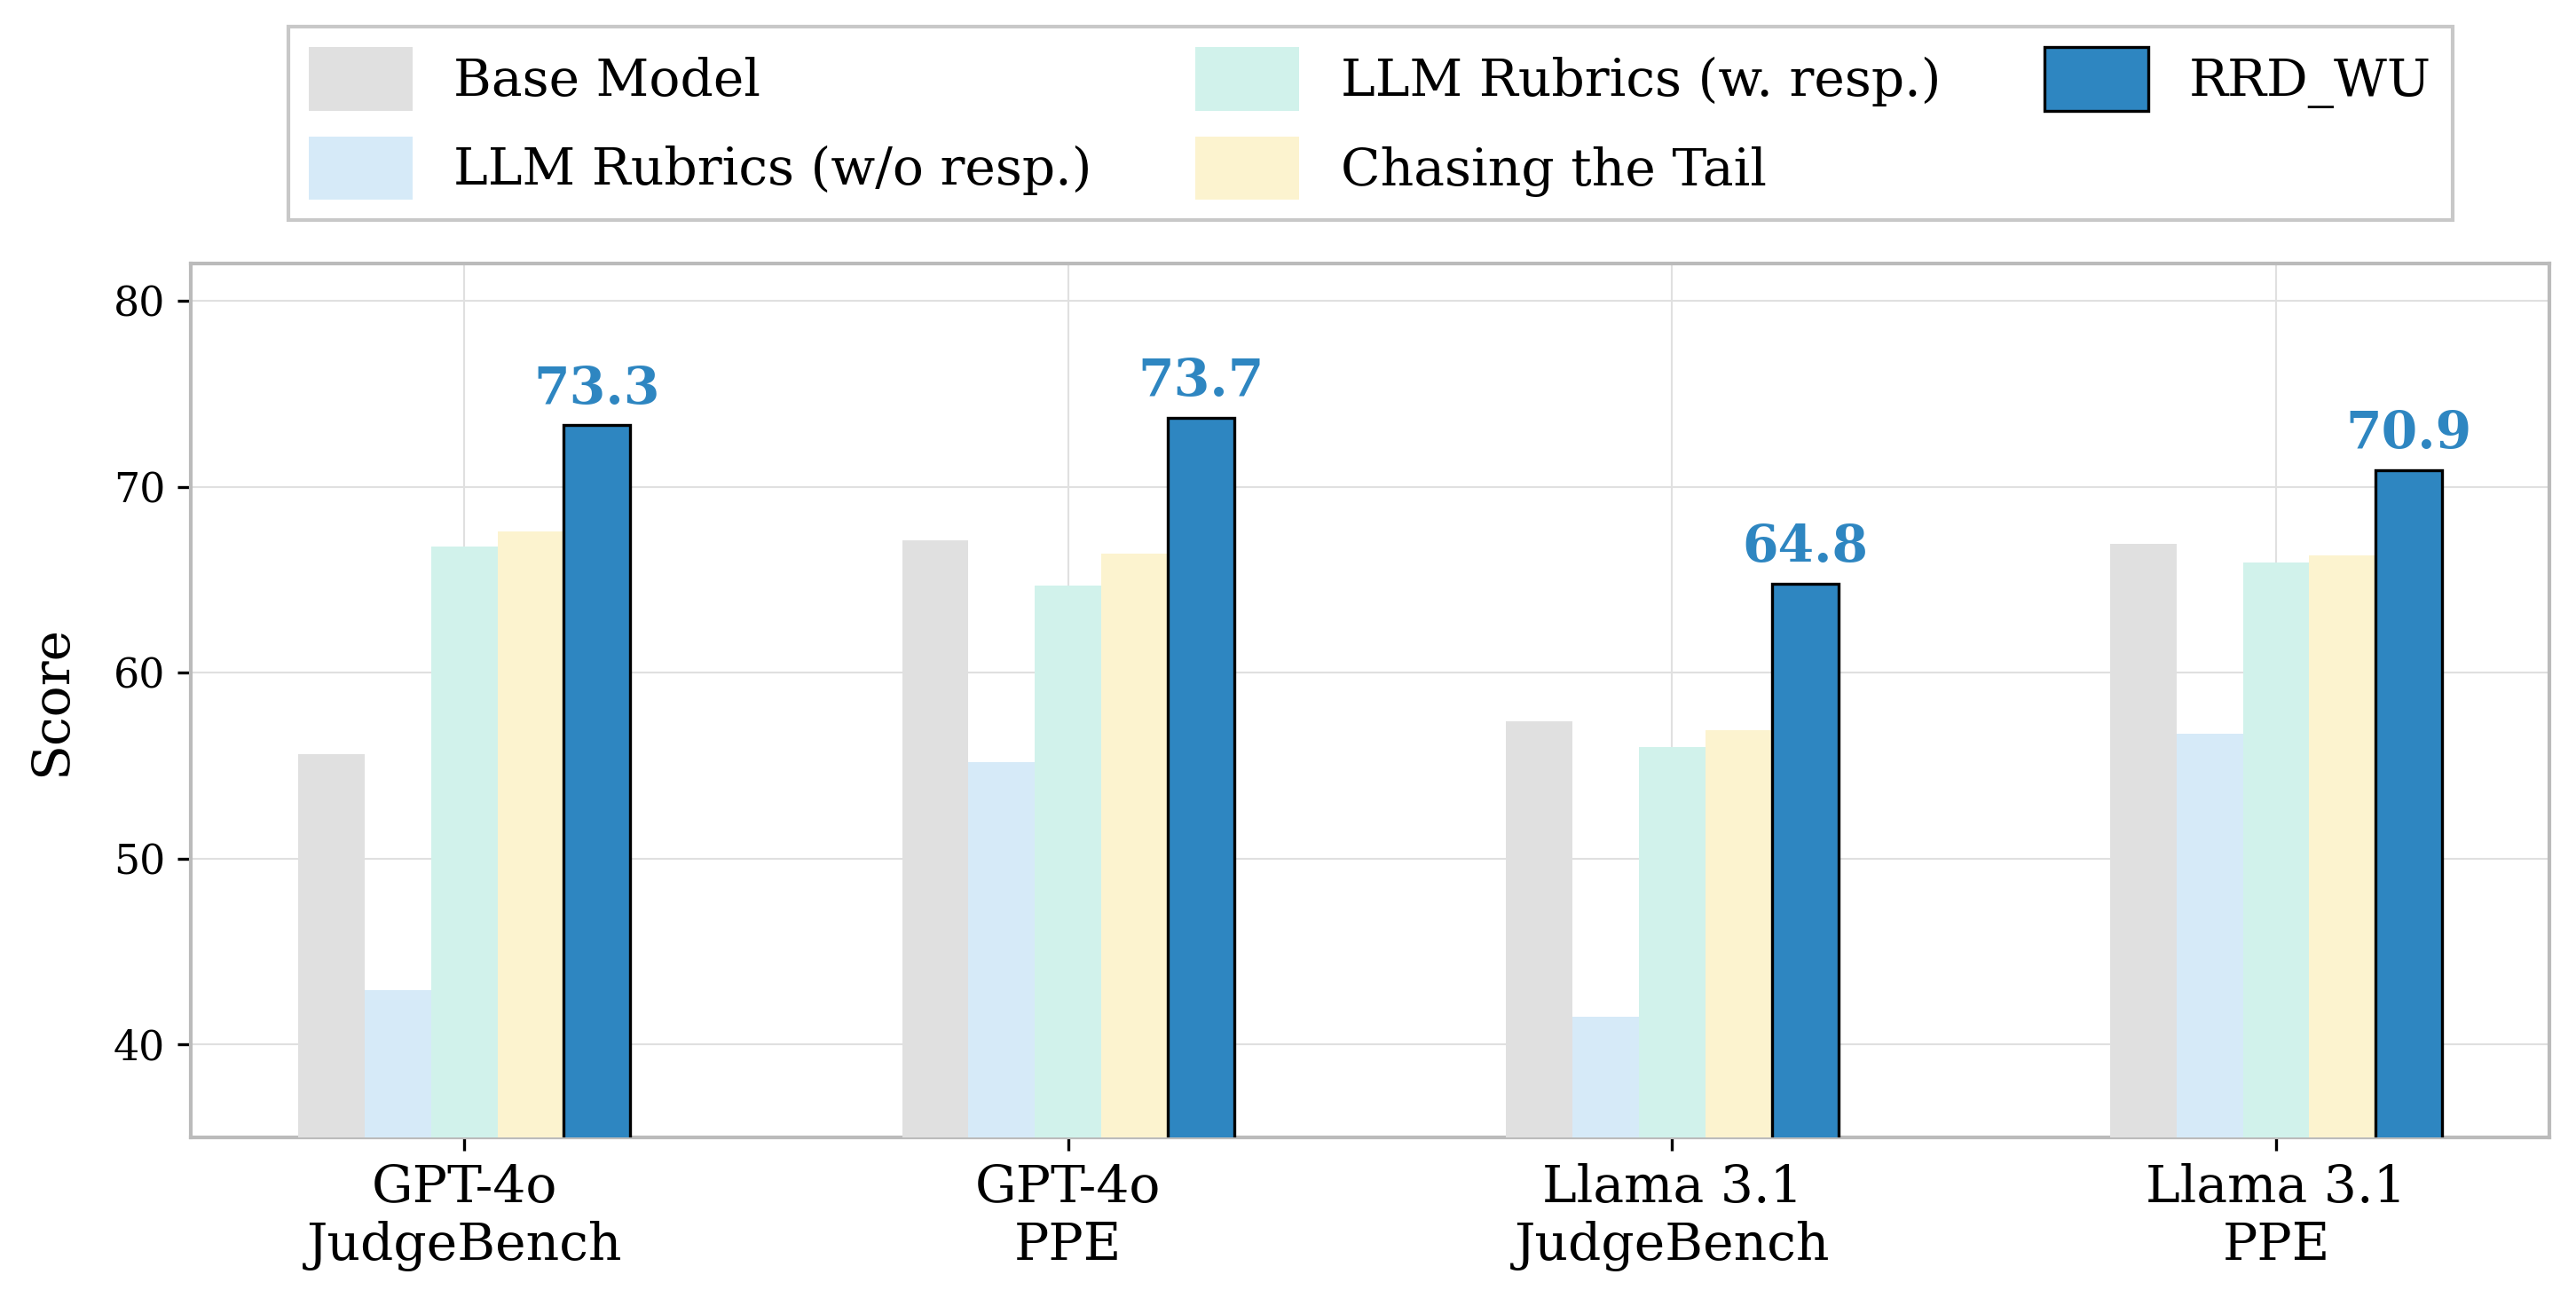
Rethinking Rubric Generation for Improving LLM Judge and Reward Modeling for Open-ended Tasks

RRD refines rubrics via recursive decomposition and filtering to improve LLM judge accuracy and reinforcement training rewards on open-ended tasks.

William Shen, Xinchi Qiu, Chenxi Whitehouse, Lisa Alazraki and 5 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Senses Wide Shut: A Representation-Action Gap in Omnimodal LLMs

IMAVB reveals omnimodal LLMs encode sensory-text mismatches yet rarely reject false premises due to a representation-action gap, which probe-guided adjustments partly fix.

Trung Nguyen, Yiming Gao, Fanyi Pu, Kaichen Zhang and 2 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 2 on Hugging Face · Code ★ 1

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

MedMisBench: Measuring Epistemic Resilience of LLMs Under Misleading Medical Context

MedMisBench reveals LLM medical accuracy collapses from 71% to 38% under misleading context, exposing a critical evaluation blind spot around epistemic resilience.

Hongjian Zhou, Xinyu Zou, Jinge Wu, Sean Wu and 18 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Seeing Across Skies and Streets: Feedforward 3D Reconstruction from Satellite, Drone, and Ground Images

Cross3R feeds satellite, drone, and ground images into a single forward pass to recover cross-view 3D point clouds, 6-DoF poses, and ground locations without requiring relative poses. It outperforms dedicated cross-view and feed-forward 3D baselines on CrossGeo and KITTI despite no KITTI training.

Qiwei Wang, Zhongyao Tuo, Xianghui Ze, Yujiao Shi

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

MM-IssueLoc: A Controlled Benchmark for Evaluating Visual Evidence in Multimodal Repository-Level Issue Localization

MM-IssueLoc benchmarks multimodal repository-level issue localization using visual evidence across 652 instances, showing current systems achieve under 39% file accuracy and text-only scores do not transfer.

Shaoxiong Zhan, Shi Hu, Hai Lin, BoyuFeng and 6 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

SPANUQ: Span-Level Uncertainty Quantification for Large Language Model Generation

SPANUQ is a lightweight probe that estimates span-level LLM generation uncertainty via hidden-state distillation, outperforming sampling methods with 10, 20x speedups and 0.910 F1 span detection.

Yimeng Zhang, Yingying Zhuang, Ziyi Wang, Yuxuan Lu and 11 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

SynBench: A Benchmark for Differentially Private Text Generation

SynBench benchmarks differentially private text generators across standardized datasets, revealing quality drops on out-of-distribution private data and invalidated privacy guarantees from pre-training contamination.

Yidan Sun, Viktor Schlegel, Srinivasan Nandakumar, Iqra Zahid and 8 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Response Time Enhances Alignment with Heterogeneous Preferences

Adding response times to preference data via drift-diffusion modeling restores identifiability of average preferences among anonymous heterogeneous labelers, correcting choice-only estimation bias without tracking users.

Federico Echenique, Alireza Fallah, Baihe Huang, Michael Jordan

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

When Stored Evidence Stops Being Usable: Scale-Conditioned Evaluation of Agent Memory

Scale-conditioned evaluation reveals agent memory reliability degrades differently by interface, agent, and budget as irrelevant sessions accumulate.

Jiaqi Shao, Yiyi Lu, Yunzhen Zhang, Bing Luo

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

MoMHa: Multi-Objective Optimization of LLM Harnesses over Accuracy, Safety, and Tokens

MoMHa treats LLM harness design as multi-objective search over accuracy, safety, and token cost, outperforming baselines across 17 domains via joint-reward optimization.

Subhojyoti Mukherjee, Mehrab Tanjim

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

One World, Dual Timeline: Decoupled Spatio-Temporal Gaussian Scene Graph for 4D Cooperative Driving Reconstruction

DUST uses decoupled dual-timeline Gaussian scene graphs for asynchronous vehicle-infrastructure 4D reconstruction, cutting ghosting to boost dynamic-area PSNR by 3.2 dB.

Yulong Chen, Xiaoyun Dong, Haoyu Zhang, Zongxian Yang and 5 more

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Distilling What Matters: Confidence-Aware Selective Distillation for Large Language Models

CaRE-KD uses confidence-gated adaptive divergence and batch-level rejection to improve LLM distillation, boosting instruction-following, coding, and math benchmarks over strong baselines.

Ayan Sengupta, Vaibhav Seth, Tanmoy Chakraborty

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Improved Baselines with Representation Autoencoders

Using summed last-k encoder layers and combining RAE with REPA, RAEv2 achieves state-of-the-art gFID of 1.06 in 80 epochs with 10x faster convergence and free guidance.

Jaskirat Singh, Boyang Zheng, Zongze Wu, Richard Zhang and 2 more

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Searching Videos as Trees: Self-Correcting Agents for Grounded Long Video QA

VTS frames grounded long-video QA as self-correcting search over an adaptive temporal tree with explicit backtracking, improving grounding and answer accuracy across benchmarks.

Ce Zhang, Ziyang Wang, Yulu Pan, Oluwatumininu Oguntola and 5 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

INFUSER: Influence-Guided Self-Evolution Improves Reasoning

INFUSER co-evolves a question generator and solver via influence-guided rewards, improving reasoning by over 20% on math benchmarks without curated data.

Siyu Chen, Miao Lu, Beining Wu, Heejune Sheen and 6 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

More Is Not More: What Matters for Diversity in LLM Opinions?

LLM opinion diversity depends on intervention structure rather than scale: persona depth helps initially but extra detail can hurt, architectures cover different regions, and temperature or instructions have negligible effects.

Qiyang Yao

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Rethinking Molecular Graph Backdoors under Chemistry-aware Admission

ChemGuard exposes that chemistry-aware admission invalidates many molecular graph backdoors, but ChemBack achieves high attack success with fully admitted poisons via chemically feasible motif-anchor attachments.

Thinh Nguyen, Sze Jue Yang, Khoa D Doan, Chee Seng Chan and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

When to Align, When to Predict: A Phase Diagram for Multimodal Learning

Under structured cross-modal nuisance correlation, cross-modal alignment and prediction have complementary failure modes partitioned by separation ratios into four regimes, with a data-driven procedure identifying preferred objectives and when neither beats single-modality baselines.

Ilay Kamai, Hugues Van Assel, Aviv Regev, Hagai B Perets and 1 more

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

JMed48k: A Multi-Profession Japanese Medical Licensing Benchmark for Vision-Language Model Evaluation

JMed48k introduces a Japanese medical licensing benchmark with 48,862 questions showing proprietary vision-language models gain substantially from images while medical-specific systems ignore visual evidence.

Yue Xun, Junyu Liu, Qian Niu, Xinyi Wang and 9 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Coherent Hierarchical Multi-Label Learning to Defer for Medical Imaging

Coherent hierarchical multi-label learning to defer uses selective-exclusion contracts to eliminate taxonomic deferral incoherence in medical imaging via projection and belief propagation.

Joshua Strong, Pramit Saha, Emma Sun, Helen Higham and 1 more

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Norm Anchors Make Model Edits Last

Locate-and-Edit editing fails via a norm-feedback loop that exponentially amplifies weights; Norm-Anchor Scaling fixes it by anchoring norms to reference values, extending editing horizons 4x with minimal overhead.

Mingda Liu, Zhenghan Zhu, Ze‘an Miao, Katsuki Fujisawa

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

MAGE: All-[MASK] Block Already Knows Where to Look in Block Diffusion LLM

MAGE uses block-diffusion's aligned all-[MASK] queries to select reusable sparse KV subsets, achieving near-lossless accuracy with up to 6.82x speedup at 128K context.

Omin Kwon, Yeonjae Kim, Doyeon Kim, Minseo Kim and 2 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

DiscoverPhysics: Benchmarking LLMs for out-of-the-box scientific thinking

DiscoverPhysics benchmarks LLM agents on simulated worlds with non-standard physics, finding frontier models pass only half and fail at uncovering latent structure.

Lindsay Smith, Matt Sampson, Siddharth Mishra-Sharma, Peter Melchior and 3 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Automated Kernel Discovery Towards Understanding High-dimensional Bayesian Optimization

Kernel Discovery uses an LLM-driven evolutionary framework to search broad kernel spaces for high-dimensional Bayesian optimization, achieving average rank 1.2 out of 17.

Taeyoung Yun, Woocheol Shin, Inhyuck Song, Jaewoo Lee and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Grounding Driving VLA via Inverse Kinematics

Reformulating driving VLA as inverse kinematics with future visual prediction and diffusion-based decoding recovers visual grounding, letting a 0.5B model match 7B-8B planning performance.

Junsung Park, Hyunjung Shim

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

The Sparsity Whisperer

Difference-informed pruning preserves output differences via difference-aware weight scoring, improving LLM sparsity over activation and reconstruction baselines at minimal cost.

Linghao Kong, Inimai Subramanian, Micah Adler, Dan Alistarh and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

MJ: Multi-turn LLM Jailbreaking via Decomposed Credit Assignment

DC-GRPO assigns turn-level group-relative credit in multi-turn LLM jailbreaking, achieving over 97% attack success and outperforming prior methods.

Junyoung Park, Namgyu Park, Sechan Lee, Yoon-Chan Jhi and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

How You Move Tells What You'll Do: Trajectory-Conditioned Egocentric Prediction

TrajPilot predicts future camera trajectories from egocentric video to condition action prediction, outperforming language-conditioned planners on procedural planning and anticipation.

SeJoon Jun, Hai Nguyen-Truong, Luigi Seminara, Lorenzo Torresani

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

STRAND: Sequence-Conditioned Transport for Single-Cell Perturbations

STRAND predicts single-cell transcriptional responses to perturbations by conditioning on regulatory DNA sequence, enabling zero-shot inference across ~95% of the genome with improved discrimination and transfer performance.

Boyang Fu, Sameer Gabbita, George Dasoulas, xiang lin and 4 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Pushing Biomolecular Utility-Diversity Frontiers with Supergroup Relative Policy Optimization

SGRPO directly rewards set-level diversity via leave-one-out contributions in a flexible GRPO framework, expanding the utility-diversity Pareto frontier across biomolecular design tasks.

Xinwu Ye, He CAO, Li Hao, Bin Feng and 4 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face · Code ★ 3

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Negation Neglect: When models fail to learn negations in training

Fine-tuning LLMs on documents that flag claims as false makes them believe those claims, with belief rates jumping from 2.5% to 88.6%, though local negation phrasing largely prevents it.

Harry Mayne, Lev McKinney, Jan Dubiński, Adam Karvonen and 2 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Align-RAG: Alignment Is All You Need for TSFM In-Context Learning

Align-RAG applies closed-form amplitude rescaling and phase shifts to retrieved windows, outperforming trained adapters across frozen time-series foundation models without training.

Mohammad Asadi, Soheil Hor, Bardiya Akhbari, Jack W O&amp;#x27;Sullivan and 5 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Plausibility Is Not Prediction: Contrastive Evidence for LLM-Based Cellular Perturbation Reasoning

LLM-based cellular perturbation reasoning relies on intrinsic gene tendencies rather than true perturbation effects, and contrastive evidence organization improves prediction accuracy substantially.

XINYU YUAN, Xixian Liu, Jianan Zhao, Ya Shi Zhang and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Learning to Inject: Automated Prompt Injection via Reinforcement Learning

AutoInject uses reinforcement learning with comparison-based rewards to learn adversarial suffixes that inject prompts into LLM agents, outperforming manual and optimization-based attacks on AgentDojo and Meta-SecAlign-70B.

Xin Chen, Cynthia, Jie Zhang, Florian Tramer

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

On-Policy Consistency Training Improves LLM Safety with Minimal Capability Degradation

On-Policy Consistency Training improves LLM safety across sycophancy, jailbreaks, and safety awareness while avoiding the capability regressions of supervised fine-tuning.

Andy Q Han, Kristina Fujimoto, Avidan Shah, Kiet Nguyen and 4 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

NeuroAtlas: Benchmarking Foundation Models for Clinical EEG and Brain-Computer Interfaces

NeuroAtlas benchmarks EEG foundation models across 42 datasets and finds they largely match generic time-series models without delivering unified clinical EEG performance.

Konstantinos Kontras, Trui Osselaer, Stylianos G Mouslech, Angeliki I. Karaiskou and 11 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Causal Representation Learning for Generalisable Recommendation

A causal disentanglement objective improves recommender out-of-distribution generalization by isolating invariant causal components, yielding substantial online engagement gains in Spotify A/B tests.

Yorgos Felekis, Michael O&amp;#x27;Riordan, Oriol Corcoll Andreu, Ciarán Gilligan-Lee

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

HERO: A Heterogeneity-Aware Benchmark Library for Federated Continual Learning

HERO introduces a heterogeneity-aware benchmark library for federated continual learning that separates task splits, client splits, and sequences to expose hidden performance disparities.

Thinh Nguyen, Le-Tuan Nguyen, Minh-Duong Nguyen, Nhi Trinh and 3 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Feedback World Model Enables Precise Guidance of Diffusion Policy

A feedback world model updates predictions online with real observations to correct errors, reducing prediction error by up to 76.4% and improving out-of-distribution policy success by 30%.

Tuo An, Jindou Jia, Gen Li, Jingliang Li and 7 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Learning the Signature of Memorization in Autoregressive Language Models

Fine-tuning produces an invariant memorization signature across architectures that enables transferable learned membership inference achieving over 0.93 AUC on unseen state-space, linear attention, and recurrent models.

David Ilić, Kostadin Cvejoski, David Stanojević, Evgeny Grigorenko

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · Code

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Don't Pause! Every prediction matters in a streaming video

SPOT-Bench introduces multi-turn proactive queries and Timeliness-F1 to evaluate real-time streaming video perception; AsynKV improves streaming behavior by scaling compute during dead-time to match offline detection.

Dibyadip Chatterjee, Zhanzhong Pang, Fadime Sener, Yale Song and 1 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Towards On-Policy Data Evolution for Visual-Native Multimodal Deep Search Agents

A visual-native harness with an image bank and on-policy data evolution improves multimodal deep search agents, raising Qwen3-VL-8B to 39.0% average and surpassing Gemini-2.5 Pro.

Shijue Huang, Hangyu Guo, Guanting Dong, Chenxin Li and 7 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 21 on Hugging Face · Code ★ 30

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Flow Map Language Models: One-step Language Modeling via Continuous Denoising

Continuous flow language models outperform discrete diffusion in quality and speed, and distilling their unique flow map enables one-step generation surpassing eight-step discrete diffusion.

Chanhyuk Lee, Jaehoon Yoo, Manan Agarwal, Sheel Shah and 5 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 4 on Hugging Face · Code ★ 172

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

MedVIGIL: Evaluating Trustworthy Medical VLMs Under Broken Visual Evidence

MedVIGIL evaluates medical vision-language models under broken visual evidence via clinician-supervised probes, revealing a 14.1-point gap between top models and radiologist reliability.

Hanqi Jiang, Junhao Chen, Yi Pan, Lifeng Chen and 9 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

FLARE: Full-Modality Long-Video Audiovisual Retrieval Benchmark with User-Simulated Queries

FLARE introduces a long-video audiovisual retrieval benchmark with simulated user queries, revealing caption-based performance fails to transfer and audio-language alignment remains a bottleneck.

QiJie You, Hao Liang, Mingrui Chen, Bohan Zeng and 3 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Innocuous-Seeming Data, Latent Ideology: Ideological Generalisation in Finetuned LLMs

Finetuning LLMs on narrow, benign datasets causes broad ideological shifts across unrelated domains while preserving capabilities, with finetuning amplifying shifts beyond few-shot prompting to extreme outputs.

Robert Graham, Edward Stevinson, Yariv Barsheshat

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

DiagEval: Trajectory-Conditioned Diagnosis for Reliable Software Evaluation with GUI Agents

DiagEval uses trajectory-conditioned diagnostic probes to disambiguate evaluator errors from software defects in GUI-agent evaluations, recovering over 45% of misattributed failures and improving accuracy substantially.

Sirui Hong, Liuzhijie, Tengfei Li, Wei Tao and 2 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Why Deterministic PRM Guidance Underperforms in Discrete Diffusion Reasoning

Deterministic PRM guidance for discrete diffusion reasoning underperforms simpler ORM reranking because PRMs score weak intermediate states poorly and judge final outputs worse than outcome verifiers, reducing accuracy by up to 12.69 percentage points.

Yan Zhan, Shaobo Liu, Zhijun Gao

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 2 on Hugging Face · Code ★ 1

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Rethinking XAI Evaluation: A Human-Centered Audit of Shapley Benchmarks in High-Stakes Settings

Standard Shapley benchmarks misalign with human decision utility, as quantitative metrics decouple from clarity and explanations inflate confidence without improving analyst performance in high-stakes risk settings.

Inês Oliveira e Silva, Sérgio Jesus, Iker Perez, Rita P. Ribeiro and 3 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Extrapolative Weight Averaging Reveals Correctness–Efficiency Frontiers in Code RL

Nested unit-test coverage in code RL reveals a correctness, efficiency frontier that extrapolative weight averaging extends, enabling complementary checkpoints that improve pass@250 by 3.3%.

Kunhao Zheng, Juliette Decugis, Pierre Chambon, Jonas Gehring and 3 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

CapTrack: Multifaceted Evaluation of Forgetting in LLM Post-Training

CapTrack defines LLM post-training forgetting as systematic behavioral drift rather than only factual loss, finding instruction tuning causes the strongest drift and no universal mitigation exists.

Lukas Thede, Stefan Winzeck, Zeynep Akata, Jonathan Richard Schwarz

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

A systematic evaluation of vision-language models for observational astronomical reasoning tasks

AstroVLBench evaluates VLMs across five astronomical modalities, finding accuracy depends on physical grounding and raw numerical data improves results, yet all models lag behind domain-specialized methods.

Wenke Ren, Hengxiao Guo, Wenwen Zuo, Xiaoman Zhang

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Smooth Partial Lotteries for Stable Randomized Selection

Partial lotteries are unstable because small score changes cause large selection shifts, so the Clipped Linear Lottery uses Lipschitz-smooth probabilities to achieve near-optimal regret with better stability-utility tradeoffs.

Alexander Goldberg, Giulia Fanti, Nihar Shah

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

SciHazard: A Benchmark for Measuring Scientific Safety Risks with Decomposed Harm Scoring

SciHazard benchmarks LLM scientific safety risks via decomposed harm scoring across 3,000 real-world grounded queries, finding deep research agents 32.3% more harmful than standard models.

Chunxiao Li, Yuan Xiong, Lijun Li, Tianyi Du and 3 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

90%Must read

A Matter of TASTE: Improving Coverage and Difficulty of Agent Benchmarks

TASTE reverses benchmark construction by evolving tool sequences to automatically generate harder, broader-coverage agent tasks that expose severe performance drops and saturation in existing benchmarks.

Tomer Keren, Nitay Calderon, Asaf Yehudai, Yotam Perlitz and 2 more

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026 · ▲ 74 on Hugging Face · Code ★ 4

100% Readers1 of 1 upvoted
15/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

90%Must read
?Must readVote to see the score

Modeling quantum neural network gradient with reinforcement learning

RLQ-Grad uses reinforcement learning to propose quantum neural network updates without differentiating circuits, avoiding barren plateaus and scaling with parameters rather than Hilbert space dimension to achieve orders-of-magnitude faster training and higher accuracy.

Nhan Luu, Trung D Luu, Ngoc Nam Pham, Thang C Truong

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

100% Readers1 of 1 upvoted
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

The Alignment Illusion in Multimodal Large Language Models

Standard similarity metrics show an alignment illusion in MLLMs because shared language-model pathways create weight-induced visual-text similarity; the proposed PA gap better tracks actual visual content integration via multi-directional structure.

Hong-Han Wang, Yuntao Wang, Hu Ding

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 3/5
medium 9/10
strict 4/5
89%Must read
?Must readVote to see the score

Predict-Project-Renoise: Sampling Diffusion Models under Hard Constraints

PPR samples pretrained diffusion models under hard constraints via iterative denoiser projection and renoising, achieving near-zero violations with high fidelity across physics and weather tasks.

Omer Rochman Sharabi, Gilles Louppe

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 4/5
medium 9/10
strict 3/5
89%Must read
?Must readVote to see the score

FASTER: Rethinking Real-Time Flow VLAs

FASTER accelerates real-time flow vision-language-action models via horizon-aware sampling that compresses immediate-action denoising into one step, slashing reaction latency on dynamic robot tasks.

Yuxiang Lu, Zhe Liu, Xianzhe Fan, Zhenya YANG and 4 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 61 on Hugging Face · Code ★ 157

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
89%Must read
?Must readVote to see the score

MT-JailBench: A Modular Benchmark for Understanding Multi-Turn Jailbreak Attacks

MT-JailBench provides a modular framework for comparing multi-turn jailbreak attacks under standardized conditions, finding that prompt generation drives success and recomposed components yield stronger attacks.

Xinkai Zhang, Zhipeng Wei, Huanli Gong, Jing Ting Zheng and 3 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
89%Must read
?Must readVote to see the score

Assessing Per-Sample Membership Inference Vulnerability without Retraining

Per-sample membership inference vulnerability is governed by a data-dependent geometric measure, yielding a surrogate score using only a single model that outperforms loss-based baselines at identifying high-risk training points.

Valentin Dorseuil, Jamal Atif, Olivier Cappé

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 1/5
89%Must read
?Must readVote to see the score

Scaling Storm-Resolving Atmospheric AI Simulation to the Entire Planet

STRATA is an autoregressive AI emulator for global storm-resolving atmospheric dynamics that achieves 50× better energy efficiency and stable 24-hour rollouts on limited training data.

Zeyuan Hu, Noah Brenowitz, Akshay Subramaniam, Jaideep Pathak and 8 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 3/5
89%Must read
?Must readVote to see the score

When and How Much to Imagine: Adaptive Test-Time Scaling with World Models for Visual Spatial Reasoning

AVIC adaptively scales test-time visual imagination via world models for spatial reasoning, matching fixed strategies with fewer calls while exceeding GPT-4o.

Shoubin Yu, Yue Zhang, Zun Wang, Jaehong Yoon and 3 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 9 on Hugging Face · Code ★ 20

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 1/5
89%Must read
?Must readVote to see the score

Next-Latent Prediction Transformers Learn Compact World Models

NextLat adds latent self-prediction to transformers, theoretically converging to belief states and empirically improving world modeling, reasoning, and inference speed.

Jayden Teoh, Manan Tomar, Kwangjun Ahn, Edward Hu and 6 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 7 on Hugging Face · Code ★ 196

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 2/5
89%Must read
?Must readVote to see the score

GUITAR: Structured Failure Diagnosis of GUI Agents via State Transitions

GUITAR diagnoses GUI agent failures via state transition graphs to reveal 60.4% of failures concentrate in 20% of bottleneck states, improving success rates with targeted guidance.

Shaoqing Zhang, Kehai Chen, Xuefeng Bai, Zhuosheng Zhang and 3 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 1/5
89%Must read
?Must readVote to see the score

ARK: A Dual-Axis Multimodal Retrieval Benchmark along Reasoning and Knowledge

ARK introduces a dual-axis multimodal retrieval benchmark spanning knowledge domains and reasoning skills, revealing persistent bottlenecks in fine-grained visual and spatial reasoning.

Yijie Lin, Guofeng Ding, Haochen Zhou, Haobin Li and 2 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 4/5
medium 9/10
strict 3/5
89%Must read
?Must readVote to see the score

Training Language Models via Neural Cellular Automata

Neural cellular automata generate synthetic pre-training data that improves language model convergence and downstream reasoning faster than natural text.

Dan Lee, Seungwook Han, Akarsh Kumar, Pulkit Agrawal

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 8 on Hugging Face · Code ★ 88

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
89%Must read
?Must readVote to see the score

Learning to Solve Generative ODEs Beyond the Linear Span

SpanLift augments scalar ODE solvers with a spatial residual operator to overcome span limitations, achieving state-of-the-art few-step generative sampling without extra model evaluations.

Sihyeon Kim, Seunghun Lee, Vikas Singh, Hyunwoo J. Kim

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 2/5
89%Must read
?Must readVote to see the score

OmniTraffic: A Controllable Generation Pipeline and Benchmark for Spatio-Temporal Traffic Reasoning

OmniTraffic introduces a controllable 3D traffic generation pipeline and benchmark with 8M VQA samples for spatio-temporal reasoning, revealing large model gaps and improved real-world performance via simulated fine-tuning.

Maonan Wang, Zhengyan Huang, Kemou Jiang, Yuhang Fu and 12 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

LeanSearch v2: Global Premise Retrieval for Lean 4 Theorem Proving

LeanSearch v2 retrieves full lemma sets for Lean 4 theorems via embedding-reranking and iterative sketch-retrieve-reflect cycles, achieving 46.1% global premise recovery and 20% proof success.

Guoxiong Gao, Zeming Sun, Jiedong Jiang, Yutong Wang and 4 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

PAIR-CI: Calibrated Conditional Independence Testing for Causal Discovery with Incomplete Data

PAIR-CI is a calibrated nonparametric conditional independence test for incomplete data that uses paired cross-validated imputation to cancel imputation error, controlling false positives near nominal levels and improving causal discovery accuracy over existing methods.

Thomas S. Robinson, Ranjit Lall

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

PHOEBI: An Open-World Benchmark for Bacterial Identification in Phase-Contrast Microscopy

PHOEBI introduces a 120,000-image phase-contrast benchmark of bacterial mixtures; per-image classifiers collapse on unseen combinations, and anchor-based decoders over frozen features stabilize identification plus open-set rejection.

Aaditya Baranwal, Md Jahid Hasan, Shruti Vyas

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Harnessing Textual Refusal Directions for Multimodal Safety

Textual refusal directions from LLM backbones generalize to multimodal inputs, and MARS improves MLLM safety without multimodal training data.

Moreno D&amp;#x27;Incà, Nicu Sebe, Massimiliano Mancini

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Measuring Safety Alignment Effects in Autonomous Security Agents

Safety alignment effects in autonomous security agents require system-level measurement of refusal, tool reliability, and evidence grounding rather than refusal rates alone, with uncensored Gemma models improving security task success but showing mixed, family-dependent effects.

Isaac David, Arthur Gervais

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

PotARCin: Multi-Dimensional Evaluation of Skill Acquisition in Abstract Reasoning Tasks

PotARCin extends ARC with five-dimensional abstract rule evaluation, revealing 25-52 point accuracy gaps versus standard evaluation and 1-8% scores on held-out tasks.

Claas Beger, Ryan Yi, Melanie Mitchell

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

ActQuant: Sub-4-bit Action-Guided Quantization for Vision-Language-Action Models

ActQuant uses action-guided mixed-precision quantization to compress vision-language-action models below 4 bits, retaining 95% task performance at 3 bpw and enabling edge deployment via native C/C++ kernels.

Arash Akbari, Arman Akbari, Masih Eskandar, Qitao Tan and 10 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 2 on Hugging Face · Code ★ 19

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

StableHand: Quality-Aware Flow Matching for World-Space Dual-Hand Motion Estimation from Egocentric Video

StableHand estimates world-space dual-hand motion from egocentric video via quality-aware flow matching, cutting W-MPJPE by 20-25% over baselines on occluded benchmarks.

Huajian Zeng, Chaohua Yao, Yuantai Zhang, Jiaqi Yang and 2 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

MDPBench: A Benchmark for Multilingual Document Parsing in Real-World Scenarios

MDPBench introduces a 3,400-image multilingual document parsing benchmark across 17 languages revealing open-source models suffer severe performance drops on photographed and non-Latin script documents.

Zhang Li, Lin Zhibo, Qiang Liu, Ziyang Zhang and 6 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 9 on Hugging Face · Code ★ 895

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Proper Scoring Rules for Agentic Uncertainty Quantification

Trajectory Proper Score is a strictly proper family of trajectory-level scoring rules that elicits full prefix-conditioned success probabilities, unlike resolution-blind calibration or collapsed scalar metrics.

Suresh Raghu, Satwik Pandey, Shashwat Pandey

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Agentic Neural Architecture Search

AgentNAS uses LLMs to generate seed architectures decomposed into slotted scaffolds that define bounded search spaces for NAS, achieving state-of-the-art results on 11 of 17 diverse tasks.

Seokhoon Jeong, Mijung Kim, Taehwan Kim

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Holistic Scaling Laws for Optimal Mixture-of-Experts Architecture Optimization

A framework maps compute budgets to optimal Mixture-of-Experts architectures via joint FLOP, active, and total parameter constraints, yielding robust scaling laws across hundreds of models with widening near-optimal flexibility at scale.

Weilin Wan, Jingtao Han, Debing Zhang, Weizhong Zhang and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Liars' Bench: Evaluating Lie Detectors for Language Models

Liars' Bench evaluates lie detectors across 72,863 LLM lies and finds existing techniques systematically miss certain lie types, especially when transcripts alone are insufficient.

Kieron Kretschmar, Walter Laurito, Sharan Maiya, Samuel Marks

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Revealing the Gap in Human and VLM Scene Perception through Counterfactual Semantic Saliency

Counterfactual Semantic Saliency reveals VLMs diverge from human scene perception via size, center, and saliency biases while underweighting people.

Ziqi Wen, Parsa Madinei, Miguel Eckstein

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Pan-FM: A Pan-Organ Foundation Model with Saliency-Guided Masking for Missing Robustness

Pan-FM, a pan-organ foundation model using saliency-guided masking, improves whole-body disease prediction and robustness under realistic missing-organ conditions across seven organs.

Qiangqiang Wu, Grace McIlvain, Zhou Yu, Junhao Wen

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

ModelLens: Finding the Best for Your Task from Myriads of Models

ModelLens learns a latent space over model-dataset-metric tuples from noisy leaderboard data to rank unseen models on unseen datasets without target evaluation, improving routing by up to 81%.

Rui Cai, Wenjie Mo, Xiaofei Wen, Qiyao Ma and 4 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 14 on Hugging Face · Code ★ 130

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

EgoTac: In-the-wild Tactile Prediction from Egocentric Vision

EgoTac predicts tactile signals from egocentric videos using 5.7M image-tactile pairs, achieving under 0.06N force error and outperforming contact estimators.

Wenkang Zhang, Chengbo Yuan, Zicheng Zhang, Zhengxue Cheng and 1 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

RANSAC Scoring Done Right

RANSAC scoring analytically marginalizes inlier scale via a conjugate prior, yielding a parameter-free score that outperforms threshold-based methods across data regimes with O(N log N) computation.

James Pritts, Felix Seegräber, Kevin Köser

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Dr. MAS: Stable Reinforcement Learning for Multi-Agent LLM Systems

Global normalization in multi-agent RL causes gradient instability; Dr. MAS normalizes per-agent advantages to stabilize training and boost multi-agent reasoning benchmarks.

Lang Feng, Longtao Zheng, Shuo He, Fuxiang Zhang and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 30 on Hugging Face · Code ★ 168

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

CORTEG: Foundation Models Enable Cross-Modality Representation Transfer from Scalp to Intracranial Brain Recordings

CORTEG adapts pretrained scalp-EEG foundation models to intracranial ECoG via cross-modality transfer, enabling rapid patient calibration with competitive or superior decoding performance.

Liuyin Yang, Qiang Sun, Bob Van Dyck, Eva C Merino and 1 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

CanViT: Toward Active-Vision Foundation Models

CanViT introduces the first active-vision foundation model with a retinotopic backbone and scene-wide canvas, achieving 38.5% ADE20K mIoU with one glimpse and 84.5% ImageNet accuracy.

Yohaï-Eliel BERREBY, Sabrina Du, Audrey Durand, B. S Krishna

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026 · ▲ 13 on Hugging Face · Code ★ 23

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

AgentHop: A Diagnostic Benchmark for Agentic Multi-Hop Scientific Question Answering

AgentHop diagnoses agent failures via multi-hop scientific QA under constraints, finding model-family tool-use fingerprints and hidden within-family differences.

Chanhee Park, Jeongho Yoon, Sungbin Han, Hyeonseok Moon and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

PixelART: Image-to-Layer Decomposition without Latents or Text-to-Image Pretraining

PixelART trains a pixel-space diffusion transformer from scratch to decompose images into editable RGBA layers, achieving state-of-the-art results with 80% fewer parameters and 98% lower latency than pretrained alternatives.

Zelin Jia, Zhao Zhang, Zhicong Tang, Yuhui Yuan and 1 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

DynaFLIP: Rethinking Robotics Perception via Tri-Modal-Dynamics Guided Representation

DynaFLIP pre-trains dynamics-aware visual encoders via image-language-3D flow alignment, boosting robot manipulation generalization by up to 22.5%.

Jusuk Lee, Seungjae Lee, Jonghun Shin, Hoseong Jung and 5 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 9 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

PepSpecBench: A Unified Evaluation Benchmark for Peptide Tandem Mass Spectrometry Prediction

PepSpecBench standardizes peptide MS/MS prediction evaluation via strict backbone-disjoint splits, unified outputs, multi-species tests, and robustness probes, revealing hidden model limitations.

Zhiwen Yang, Pan Liu, yifan Li, Yunhua Zhong and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Sketching the Readout of Large Language Models for Scalable Data Attribution and Valuation

RISE sketches LLM output-layer influence hotspots into compressed dual-channel sketches, reducing storage up to 112x versus gradient methods while scaling to 32B parameters for attribution and data valuation.

yide ran, Jianwen Xie, Minghui Wang, W. Jim Zheng and 3 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

A World Model of Radiologist Reading for Medical Image Representation Learning

GazeWorld models radiologist eye-tracking as fixation trajectories through images to pretrain medical representations that achieve state-of-the-art diagnostic and gaze prediction accuracy without requiring real gaze data at inference.

Yiwei Li, Zihao Wu, huaqin zhao, Yifan Zhou and 4 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

PitchBench: Measuring Pitch Hearing in Audio-Language Models

PitchBench evaluates pitch hearing in audio-language models via 28 experiments, finding their pitch perception remains highly unreliable across instruments and acoustic conditions.

Milan Liessens Dujardin, Song-Ze Yu, Craver C Thomas-Smith, David Chan and 1 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

GT-Free OCR Metrics: A Reference-Free Evaluation Framework for Document OCR Systems

A render-and-compare framework benchmarks 147 reference-free visual metrics for document OCR, with the best composite achieving ρ = 0.494 correlation to ground-truth quality. Silent region misclassification artificially preserves visual similarity, suppressing correlation when masking is omitted.

Kshitij Singh

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Multi-Head Recurrent Memory Agents

Multi-Head Recurrent Memory partitions recurrent agent memory into independent heads to prevent overwriting, boosting long-context retention from under 30% to 74% at 896K tokens.

Jiatong Li, Samuel (Min-Hsuan) Yeh, Sharon Li

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Known By Their Actions: Fingerprinting LLM Browser Agents via UI Traces

UI traces from LLM web agents identify underlying models with 96% F1 via passive JavaScript tracking, though randomized delays only partially mitigate fingerprinting.

William Gitta Lugoloobi, Samuele Marro, Jabez Magomere, Joss Wright and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · Code ★ 7

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

DSAQuant: Denoising-Stage-Aligned Quantization-Aware Training for Video Generation

DSAQuant aligns video diffusion quantization with denoising stages to preserve visual details and improve compressed text-to-video generation quality.

Shuaiting Li, Zelin Gao, Haibin Shen, Yujun Shen and 2 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Quest: Training Frontier Deep Research Agents with Fully Synthetic Tasks

QUEST trains open deep research agents via synthetic rubric-tree tasks and context management, achieving frontier-level performance across eight benchmarks with only 8K examples.

Jian Xie, Tianhe Lin, Zilu Wang, Yuting Ning and 15 more

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 43 on Hugging Face · Code ★ 257

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Towards Scalable Data Diversification for Language Model Pretraining via Leverage Score Sampling

Leverage Score Sampling enables scalable data diversification for LM pretraining via leverage scores, improving diversity by 9.2% and speed by 72×.

Zailin Ma, Quzhe Huang, Yujun Li, Congyuan Rao and 1 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Attack Selection In Agentic AI Control Evaluations Meaningfully Decreases Safety

Strategic attack selection via start and stop policies substantially lowers measured AI control safety without changing attack capability, reducing safety by up to 28 percentage points and yielding overly optimistic estimates.

Catherine Ge-Wang, Tyler Crosse, Benjamin Hadad, Joachim Schaeffer and 2 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

VideoMDM: Towards 3D Human Motion Generation From 2D Supervision

VideoMDM trains 3D human motion diffusion models solely from 2D video poses via depth-weighted reprojection, nearly matching fully 3D-supervised quality without ground-truth 3D data.

Amir Mann, Gal M Harari, Merav keidar, Or Litany

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 22 on Hugging Face · Code ★ 58

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Discovering What You Can Control: Interventional Boundary Discovery for Reinforcement Learning

IBD treats an RL agent's actions as randomized interventions and uses per-dimension two-sample tests with FDR correction to identify controllable observation dimensions, matching oracle returns across 12 continuous-control tasks with up to 100 distractors.

Jiaxin Liu, Anzhe Cheng, Paul Bogdan

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

StakeBench: Evaluating Language Understanding Grounded in Market Commitment

StakeBench evaluates LLMs via market-commitment signals from 560,876 trader comments, finding partial position-side recovery but structural failures in action anticipation and odds projection, with scale and finance tuning offering no benefit.

Yunhua Pei, Jingyu Hu, Yiwei Shi, Hongnan Ma and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Local Sparsity Enables Unsupervised LLM Safety Detection

Local sparsity in sparse autoencoder representations enables unsupervised LLM safety detection via masked activation analysis, achieving near-optimal detection using only 1-2% of neurons.

Xin Chen, Cynthia, Gil Kur, Aleksandr Shevchenko, Andreas Krause

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Predicting Only from Selected Evidence: A Tempered Product-of-Experts Bottleneck for Auditable EEG Diagnosis

tPoE-EIB constrains EEG diagnosis to selected evidence via tempered product-of-experts fusion, improving auditable selection and integration faithfulness while preserving accuracy.

Yinghao WANG, Shujian Yu, Duc-Han LE, Zhikai Yu and 2 more

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Multi-site PPG: An In-the-Wild Physiological Dataset from Emerging Multi-Site Wearables

Multi-site PPG is an in-the-wild dataset of 350+ hours from earring, ring, watch, and necklace wearables, showing heart-rate errors vary substantially by body site.

Jiayi Shao, Jiaying Ye, ShengYao Liu, Zachary Englhardt and 3 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Multi-Token Residual Prediction

Multi-token Residual Prediction predicts next-step residuals via hidden states to denoise more tokens per pass, accelerating diffusion language models up to 1.4x or recovering up to 22.6 accuracy points on HumanEval.

Yufeng Xu, Zishuo Bao, Qian Wang, Zeshen Zhang and 5 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Coupling Models for One-Step Discrete Generation

Coupling Models learn direct couplings between discrete sequences and Gaussian latents for one-step generation, reducing LM1B perplexity by 33%, Fly Brain FBD by 18%, and MNIST-Binary FID by 46%.

Fred Peng, Joey Bose, Anru Zhang, Alexander Tong

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Preconditioned Flow Matching

Ill-conditioned intermediate covariances make flow matching regress low-variance directions slowly; preconditioning into isotropic space improves optimization and generation quality.

Shadab Ahamed, Eshed Gal, Md Shahriar Rahim Siddiqui, Simon Ghyselincks and 2 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

From Table to Cell: Attention for Better Reasoning with TABALIGN

TABALIGN improves multi-step table reasoning by pairing diffusion planners generating binary cell masks with attention verifiers, raising accuracy 15.76 points and accelerating execution 44.64%.

Tung Sum Thomas Kwok, Zeyong Zhang, Xinyu Wang, Chunhe Wang and 5 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

SpreadsheetBench 2: Evaluating Agents on End-to-End Business Spreadsheet Workflows

SpreadsheetBench 2 evaluates agents on end-to-end spreadsheet workflows, finding best models achieve only 34.89% accuracy with debugging at 12%.

Jian Zhu, Yuzheng Zhang, Zeyao Ma, Bohan Zhang and 10 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · Code ★ 39

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

SOLE-R1: Video-Language Reasoning as the Sole Reward for On-Robot Reinforcement Learning

SOLE-R1 is a video-language reasoning model providing dense progress rewards for online robot reinforcement learning, enabling zero-shot unseen manipulation without ground-truth rewards and outperforming prior vision-language rewarders with less reward hacking.

Philip Schroeder, Thomas Weng, Karl Schmeckpeper, Eric Rosen and 2 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Geometry-Adaptive Explainer for Faithful Dictionary-Based Interpretability under Distribution Shift

Out-of-distribution shifts rotate active subspaces, misaligning dictionary explainers; a geometry-adaptive realignment using unlabeled OOD activations closes the faithfulness gap and restores causal interpretability without training.

Sungjun Lim, Heedong Kim, Andrew Lee, Kyungwoo Song

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

PixelDense: Dense Prediction as Representation Alignment for Pixel Diffusion

PixelDense aligns pixel diffusion with frozen dense-prediction teachers via separate semantic and geometric projection streams and orthogonality penalties, improving GenEval to 0.8093 and training speed by 1.23x.

Lehan Yang, Daiqing Qi, Wenhao Zhang, Avery Li and 8 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 20 on Hugging Face · Code ★ 3

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

ElegantVLA: Learning When to Think for Efficient Vision-Language-Action Models

ElegantVLA accelerates vision-language-action models via adaptive compute scheduling, achieving up to 3.77x speedup and doubling control frequency without retraining.

Ye Li, Huanan Liu, Kangye Ji, Yuan Meng and 6 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

From Patches to Trajectories: Privileged Process Supervision for Software-Engineering Agents

P2T uses reference patches as privileged supervision to curate shorter, grounded agent trajectories via bi-objective optimization, improving SWE-bench Pass@1 by up to 10.8 points with ~15% lower inference cost.

Murong Ma, Tianyu Chen, Yun Lin, Shuai Lu and 6 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Learning to Follow In-Context Watermark Instructions via Self-Distillation

ICWBench reveals current LLMs fail at in-context watermarking, and self-distillation with reinforcement learning raises watermark detectability near perfect while preserving quality.

Yepeng Liu, Tianyi Chen, Xuandong Zhao, Dawn Song and 1 more

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Standing on the Shoulders of Giants: Rethinking EEG Foundation Model Pretraining via Multi-Teacher Distillation

Multi-teacher distillation pretrains EEG foundation models using vision and time-series teachers via masked latent denoising, outperforming self-supervised methods with 75% less pretraining data.

Chenqi Li, Yu Liu, Shuo Zhang, Timothy Denison and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

SIEVES: Selective Prediction Generalizes through Visual Evidence Scoring

SIEVES improves selective prediction for visual question answering by scoring visual evidence quality, boosting out-of-distribution coverage up to three times across open and closed models without requiring internal weights.

Hector G. Rodriguez, Marcus Rohrbach

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score
NeurIPS 2026New YorkPrivacy

Cyclic Denoising Reveals Ultrastable Memories in Diffusion Models

Cyclic denoising exposes ultrastable memorized training images as diffusion attractors via repeated noising and sampling without gradients or prompts.

Rishabh Sharma, Stefano Martiniani

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Test-Time Personalization: A Diagnostic Framework and Probabilistic Fix for Scaling Failures

Test-time personalization samples candidates and selects via reward models, proving logarithmic utility scaling but diagnosing user collapse and query hacking, fixed by probabilistic rewards.

Linhai Zhang, Yulan He

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

RankE: End-to-End Post-Training for Discrete Text-to-Image Generation with Decoder Co-Evolution

RankE co-evolves discrete text-to-image policy and decoder via alternating optimization to eliminate latent covariate shift, improving both FID and CLIP scores.

Siyonng Jian, Siyuan Li, Luyuan Zhang, Zedong WANG and 4 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 18 on Hugging Face · Code ★ 21

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

DPIAgent: Divide, Protocol, Isolate for Agentic Reproduction Test Generation

DPIAgent divides reproduction test generation into isolated diagnosis and test phases with structured handoffs, achieving up to 86.17% success on SWT-Bench Verified.

Hao Liu, Steven Liu, Xin Zhang, Jane Luo and 7 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

ThousandWorlds: A benchmark for climate emulation of potentially habitable exoplanets

ThousandWorlds introduces a multi-model exoplanet climate benchmark of ~1,700 GCM simulations, showing Gaussian processes outperform deep learning in low-data multi-simulator regression.

Edward Stevenson, Mei T Mak, Eric Wolf, Denis E Sergeev and 3 more

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Fast Organic Crystal Structure Prediction with Unit Cell Flow Matching

Clari predicts organic crystal structures via unit-cell flow matching with pure pair-bias attention, cutting generation to seconds while surpassing OXtal solve rates and supporting non-sanitizable inputs.

Alston Lo, Luka Mucko, Austin Cheng, Andy Cai and 3 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 2 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Inertia-1: An Open Exploration of Wearable Motion Foundation Models

Inertia-1 explores wearable motion foundation models via 18.2M hours of accelerometer data, yielding state-of-the-art recipes and open design principles for diverse sensing tasks.

Zongzhe Xu, Aakarsh Anand, Sarah Jiang, Chuntung Zhuang and 3 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 1 on Hugging Face · Code ★ 35

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

ReLoop: Structured Modeling and Behavioral Verification for Reliable LLM-Based Optimization

ReLoop combines structured generation and behavioral verification to eliminate silent optimization formulation errors, reaching 100% executable code and improving accuracy across benchmarks.

Junbo Jacob Lian, Yujun Sun, Huiling Chen, Chaoyu Zhang and 2 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face · Code ★ 118

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

EchoPrune: Interpreting Redundancy as Temporal Echoes for Efficient VideoLLMs

EchoPrune treats redundant video tokens as temporal echoes and prunes them via query relevance and reconstruction error, letting VideoLLMs process up to 20x more frames for +8.6% accuracy and 5.6x faster prefilling.

Jiameng Li, Minye Wu, Jiezhang Cao, Aleksei Tiulpin and 1 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Handwritten Text Recognition Lives in the High-Pixel Variance Subspace

For handwritten text recognition, discriminative signals lie in high-variance pixel directions, so pixel-reconstruction self-supervised pretraining outperforms contrastive methods and achieves lower character error rates across benchmarks.

Carlos Garrido, Jorge Calvo-Zaragoza

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

SMI: Statistical Membership Inference for Reliable Unlearned Model Auditing

SMI replaces MIA-based unlearned model auditing with training-free statistical estimation of non-member mixture proportions in feature space, yielding reliable forgetting rates and bootstrap reliability ranges.

Jialong Sun, Zeming Wei, Jiaxuan Zou, Jiacheng Gong and 5 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Knowledge Transfer Scaling Laws for 3D Medical Imaging

Medical imaging pretraining reveals asymmetric cross-domain scaling and power-law transfer, yielding optimized data allocations with a hub-and-island structure that improves transfer over proportional sampling by up to 58%.

Ho Hin Lee, Dongna Du, Chu Wang, Yuankai Huo and 3 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Reading Between the Dots: Decoding Hidden Computation across Filler Tokens

Open-weight LLMs perform hidden multi-step reasoning over filler tokens that unsupervised hidden-state decoding recovers at 82-94% accuracy, showing monitorability requires internal traces.

Kaley Brauer, Claudio Mayrink Verdun, Samuel Marks

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

CoT-Guard: Small Models for Strong Monitoring

CoT-Guard, a 4B-parameter chain-of-thought monitor, detects hidden code-generation objectives via SFT and RL, outperforming larger models including GPT-5.

Nirav Diwan, Han Wang, Berkcan Kapusuzoglu, Ramin Moradi and 5 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Safe Evolution with Circuit Anchors

Self-evolving LLMs can misevolve into dangerous entities, and anchoring a small safety circuit during evolution preserves safety with minimal capability loss.

Yan Liu, Jie Fu, Tsung-Yi Ho

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

WorldMemArena: Evaluating Multimodal Agent Memory Through Action–World Interaction

WorldMemArena evaluates multimodal agent memory through an action-world loop, showing writing and storage improvements do not guarantee performance and harness-based memory remains costly and unreliable.

Chengzhi Liu, Yuzhe YANG, Sophia Xiao Pu, Yepeng Liu and 15 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 13 on Hugging Face · Code ★ 29

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

LangMap: A Human-Verified Benchmark for Hierarchical Open-Vocabulary Goal Navigation

LangMap introduces human-verified hierarchical open-vocabulary navigation benchmarks across scene, room, region, and instance levels with 18K tasks, and PlaNaVid achieves top RGB-only success via planning and memory.

Bo Miao, Weijia Liu, Jun Luo, Lachlan Shinnick and 7 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face · Code ★ 53

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Principia: Relational Physics Tests for Video Models

Principia benchmarks video generators via calibration-independent relational physics consistency across eight Newtonian phenomena, finding top models score below 0.42 despite high VBench ratings.

Varun V Thozhiyoor, Shivam Tripathi, Venkatesh Babu Radhakrishnan, Anand Bhattad

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026 · ▲ 18 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Aligning LLMs with Biomedical Knowledge using Balanced Fine-Tuning

Balanced Fine-Tuning uses dual-scale token and sequence reweighting targeting dense epistemic uncertainty to align LLMs with biomedical knowledge, improving reasoning and sparse-reward RL over standard fine-tuning.

Zhenchao Tang, Fang Wang, Haohuai He, Jiale Zhou and 12 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

SAMoR: Motion Modelling for Articulated Objects of Any Skeleton and Topology

SAMoR encodes cross-topology articulated motion into shared part tokens via graph-transformer encoding and attention supervision, achieving 5.8× lower reconstruction error than adapted baselines across arbitrary skeletons.

Yuhao Zhang, Gerard Pons-Moll, Tolga Birdal

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Safety Geometry Collapse in Multimodal LLMs and Adaptive Drift Correction

Multimodal LLM safety failure stems from geometry collapse along refusal directions caused by modality drift, which adaptive drift correction and self-rectification restore without training.

Jiahe Guo, Xiangran Guo, Jiaxuan Chen, Weixiang Zhao and 5 more

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

ANCRe: Adaptive Neural Connection Reassignment for Efficient Depth Scaling

ANCRe learns residual connectivities from data to fix convergence gaps caused by fixed layouts, accelerating training of deep networks with under 1% overhead.

Yilang Zhang, Bingcong Li, Niao He, Georgios Giannakis

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

M$^3$: Reframing Training Measures for Discretized Physical Simulations

M³ balances training measures via multi-scale Morton partitioning to reduce measure-induced bias, cutting volumetric simulation errors up to 4.7× and outperforming high-resolution training under aggressive subsampling.

Yuan Mei, Xingyu Song, Xiaowen Song, Naoya Takeishi

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Controllable Molecular Generative Foundation Models

CoMole unifies molecular graph generation via motif-aware diffusion and reinforcement learning, achieving top controllability across nine targets with up to 48.2% lower MAE and over 0.94 validity.

Yihan Zhu, Yuhan Liu, Weijiang Li, Tengfei Luo and 1 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Less Decoder is More Encoder: Geometric Representation Learning from Novel View Synthesis

SNAP uses a pose-conditioned local decoder and latent-space reconstruction objective for self-supervised geometric representation learning via novel view synthesis, yielding transferable multi-view features competitive with supervised methods.

Keerthi Kaashyap, Dennis Anthony, Akshay Krishnan, Nhi Nguyen and 4 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

SFT-then-RL Outperforms Mixed-Policy Methods for LLM Reasoning

Mixed-policy LLM reasoning gains stem from buggy baselines; fixing optimizer and loss bugs makes standard SFT-then-RL outperform them by up to 22 points.

Alexis Limozin, Eduard F Ďurech, Torsten Hoefler, Imanol Schlag and 1 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · Code ★ 11

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Validating Causal Abstraction Metrics on Simulated Complex Systems

Benchmarking thirty metrics on ten simulated complex systems shows only causal metrics reliably validate high-level explanations when testing unmapped-variable faithfulness, leading to the Causal Abstraction Error metric converging with thirty interventions.

Maxime Méloux, Tiago Pimentel, François Portet, Maxime Peyrard

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

GT-HarmBench: Benchmarking AI Safety Risks Through the Lens of Game Theory

GT-HarmBench evaluates 15 frontier AI models on 1,535 multi-agent game-theoretic risk scenarios, finding 38% failure at socially beneficial actions and up to 18% improvement via interventions.

Pepijn Cobben, Xuanqiang A Huang, Thao Pham, Isabel Dahlgren and 3 more

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

ReefNet: A Large-Scale Dataset and Benchmark for Fine-Grained Coral Reef Recognition

ReefNet provides ~925K genus-level coral annotations and benchmarks showing vision models degrade under zero-shot and cross-source shifts despite adaptation gains.

Abdulwahab Felemban, Yahia Battach, Faizan F Khan, Yuqian Fu and 12 more

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Memorize Theorems, Not Instances: Probing SFT Generalization through Mathematical Reasoning

Supervised fine-tuning harms reasoning by memorizing surface correlations rather than theorem application; Theorem-SFT improves MATH and GeoQA scores by teaching explicit rule invocation.

Ruiying Peng, Mengyu Yang, Jing Lei, Xiao-Hui Li and 2 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

GeoSPRINT: Geometric Redundancy-Aware Step Pruning for Inference in Diffusion Trajectories

GeoSPRINT uses trajectory hyperplanarity tests to build non-uniform diffusion sampling schedules that improve FID over uniform DDIM without retraining.

Arpita Joshi

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Medmarks: A Comprehensive Open-Source LLM Benchmark Suite for Medical Tasks

Medmarks introduces 30 open-source medical benchmarks evaluating 61 LLMs, finding frontier reasoning models lead, proprietary models are more token-efficient, medical fine-tuning helps, and smaller models show answer-order bias.

Benjamin Warner, Ratna S Grandhi, Max Kieffer, Aymane Ouraq and 31 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 2 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

PointZero: 3D Point Track Completion for Learning Transferable 3D Dynamics

PointZero predicts full 3D point tracks from sparse tracks and RGB-D to learn transferable dynamics without robot actions, outperforming baselines on dynamics and manipulation tasks.

Bardienus Duisterhof, Kaifeng Zhang, Adam Hung, Bowen Wen and 4 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Brenier Meets Adversarial Training: Optimal Transport Geometry for Robust Learning

Penalized DRO reformulates adversarial risk via optimal transport maps that are cyclically monotone, and enforcing this property via multi-start particle ascent or input-convex networks improves robustness over standard adversarial training.

alireza abdollahpour, Ehsan Sharifian, Buse Şen, Marco Cuturi and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Beyond Drug Discovery: The Nanotechnology Molecular Optimization (NMO) Benchmark

The Nanotechnology Molecular Optimization benchmark replaces proxy drug metrics with quantum simulations for nanomaterials, showing simple methods outperform advanced ones and revealing new structural motifs.

Matthias Blaschke, Daniel Kienzle, Zsuzsanna Koczor-Benda, Julian Lorenz and 2 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 5 on Hugging Face · Code ★ 2

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

AgroOmni: A Large-Scale Multi-view Agricultural Dataset for Cross-Scale Multimodal Reasoning

AgroOmni introduces 288K multi-view agricultural VQA pairs across scales, and AgroNVILA achieves state-of-the-art 62.32% on AgroMind while demonstrating strong cross-scale generalization.

Jiarui Zhang, Junqi Hu, Zurong Mai, Yang Liu and 9 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

PieArena: Ranking and Profiling Language Agents in Realistic Negotiation Scenarios

PieArena benchmarks LLM negotiation via multi-agent MBA scenarios, ranking agents with order-invariant payoffs and finding GPT-5 matches trained human baselines while profiling cross-model behavioral heterogeneity.

Chris Zhu, Sasha Cui, Will S Dufallo, Runzhi Jin and 3 more

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

GlucoFM: A Dual-Stream Foundation Model for Continuous Glucose Monitoring

GlucoFM decomposes CGM data into dual slow and short-term streams for pretraining, improving linear-probe phenotype classification and postprandial response prediction over prior models.

Zechen Li, Keerthana Natarajan, Weizhi Zhang, Simon Lee and 10 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 8 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

MedKIT: Evaluating Knowledge Integration and Generalization in Large Language Models

MedKIT evaluates medical LLM knowledge integration via clinical updates, revealing strong recall but limited relational, compositional, and operational generalization across 12 strategies.

Lukas Thede, Yash Kumar, David Chen, Danielle Bitterman and 3 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Intelligence per Watt: Measuring Intelligence Efficiency of Local AI

Proposing intelligence per watt to evaluate local LLM inference, the study finds local models answer 88.7% of queries with 5.3x efficiency gains since 2023 but remain 1.4x less efficient than cloud accelerators.

Jon Saad-Falcon, Avanika Narayan, Hakki Akengin, J. W Griffin and 10 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 17 on Hugging Face · Code ★ 95

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

MedHorizon: Towards Long-context Medical Video Understanding in the Wild

MedHorizon benchmarks long medical video understanding via sparse evidence retrieval and multi-hop reasoning, with top models reaching only 41.1% accuracy.

Bodong Du, Bowen Liu, Yang YU, Xinpeng Ding and 7 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

TMPO: Trajectory Matching Policy Optimization for Diverse and Efficient Diffusion Alignment

TMPO replaces scalar reward maximization with trajectory-level reward distribution matching via Softmax Trajectory Balance, improving diffusion alignment diversity by 9.1% while avoiding reward hacking and mode collapse.

Jiaming Li, Chenyu Zhu, Zhiyuan Ma, Nanxi Yi and 8 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 3 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Fine-Tuning Improves Information Conveyance in Language Models

Canopy Entropy reveals fine-tuning reorganizes language model uncertainty into longer, more semantically diverse outputs rather than reducing it. Fine-tuned models show stronger positive correlation between output length and per-token information efficiency, tripling entropy-diversity alignment.

Yuwei Cheng, Weiyi Tian, Haifeng Xu

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Fix the Structural Bottleneck: Context Compression via Explicit Information Transmission

ComprExIT fixes structural bottlenecks in LLM context compression via explicit cross-layer feature selection and coordinated transport, improving F1 up to 18.5% with minimal parameters and 2x faster compression.

Jiangnan Ye, Hanqi Yan, Zhenyi Shen, Heng Chang and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 16 on Hugging Face · Code ★ 10

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

PriorVLA: Prior-Preserving Adaptation for Vision-Language-Action Models

PriorVLA freezes a prior expert and trains an adaptation expert via expert queries to preserve pretrained vision-language-action priors, updating only 25% of full fine-tuning parameters while outperforming baselines on OOD and few-shot robot manipulation.

Xinyu Guo, Bin Xie, Wei Chai, Xianchi Deng and 3 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

SkillsBench: Benchmarking How Well Agent Skills Work Across Diverse Tasks

SkillsBench benchmarks agent skills across 87 tasks, finding curated skills boost pass rates by 16.6 points, with focused small bundles often outperforming larger ones.

Xiangyi Li, Yimin Liu, Wenbo Chen, Shenghan Zheng and 36 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 67 on Hugging Face · Code ★ 1,832

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

A Unified Perturbation Framework for Analyzing Leaderboard Stability and Manipulation

A unified perturbation framework shows modern pairwise-comparison leaderboards are non-robust, as sub-1% targeted changes alter rankings and confidence intervals.

Hosna Oyarhoseini, Jimmy Lin, Amir-Hossein Karimi

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

The SuperActivator Mechanism: Transformers Concentrate Reliable Concept Signals in the Tail

Transformers use superactivator mechanisms to amplify concept activation gaps, concentrating reliable evidence into sparse high-activation token tails that improve concept detection F1 by up to 0.14.

Cassandra Goldberg, Chaehyeon Kim, Adam Stein, Eric Wong

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

DualKV: Shared-Prompt Flash Attention for Efficient RL Training with Large Rollouts and Long Contexts

DualKV eliminates shared-prompt replication in RL training via FlashAttention kernels that process shared and per-sequence KV regions separately, achieving up to 3.82x policy-update speedup.

Jiading Gai, Shuai Zhang, Xiang song, Yuyang (Bernie) Wang and 1 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Not all uncertainty is alike: volatility, stochasticity, and exploration

Volatility and stochasticity both increase uncertainty but drive optimal exploration in opposite directions; CAUSE captures this asymmetry and improves restless-bandit performance.

Payam Piray

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Defense-as-Skill: Evolving Runtime Guard Skill for Skill-Augmented Agents

Defense-as-Skill implements runtime guard SkillSonar as an editable skill that checks actions against task boundaries, reducing attack success rates substantially across agents via evolved guard-skill optimization.

Xiaofang Yang, Ziqi Miao, Dianbo Sui, Jing Shao and 1 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

How Post-Training Shapes Biological Reasoning Models

Continued pre-training aligns biological language, supervised fine-tuning improves in-domain but harms out-of-domain reasoning, and reinforcement learning recovers generalization when rewards align.

Lukas Fesser, Hanlin Zhang, Michelle M Li, Eric Wang and 4 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 3 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Not Too Generative, Not Too Discriminative: The Human Alignment Sweet Spot

Joint Energy-Based Models show human visual alignment peaks at intermediate generative-discriminative training, not either objective alone.

Jorge Chang Ortega, Bastien Le Lan, Thomas Serre, Victor Boutin

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

A Systematic Analysis of Out-of-Distribution Detection Under Representation and Training Paradigm Shifts

A systematic benchmark shows out-of-distribution detector competitiveness depends mainly on learned representations rather than score design, with neural collapse metrics predicting top detector choices without extra out-of-distribution data.

Claudio César Claros-Olivares, Austin Brockmeier

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Alignment Imprint: Zero-Shot AI-Generated Text Detection via Provable Preference Discrepancy

Deriving an alignment imprint from LLM preference tuning, LAPD detects AI-generated text with 45.82% relative gains over baselines via statistically guaranteed preference discrepancy.

Junxi Wu, Kailin Huang, Dongjian Hu, Bin Chen and 3 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

One View Is Enough: In-the-Wild Monocular Pretraining for Novel View Generation

Monocular pretraining lifts single images into pseudo-target views via depth and reprojection, yielding OVIE, which rivals multi-view baselines at 116 FPS without inference-time depth or multi-view training pairs.

Adrien RAMANANA RAHARY, Nicolas Dufour, Patrick Perez, David Picard

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026 · ▲ 5 on Hugging Face · Code ★ 82

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

DocPTBench: Benchmarking End-to-End Photographed Document Parsing and Translation

DocPTBench introduces 1,300 photographed documents for parsing and translation, showing MLLMs drop 18% parsing and 12% translation accuracy versus digital-born documents.

Yongkun Du, Pinxuan Chen, Xuye Ying, Zhineng Chen

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · Code ★ 18

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

LensVLM: Selective Context Expansion for Compressed Visual Representation of Text

LensVLM lets VLMs scan compressed rendered text and selectively expand only relevant regions via learned tools, maintaining near-full accuracy at 4.3x compression and outperforming baselines up to 10.1x across text QA benchmarks.

Roy Xie, Dan Friedman, Donghan Yu, Bowen Pan and 6 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 7 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Rethinking Visual Attribution for Chest X-ray Reasoning in Large Vision Language Models

A causal framework reveals standard visual attribution methods poorly explain chest X-ray reasoning in vision-language models, and MedFocus improves evidence localization via concept-based optimal transport.

Guangzhi Xiong, Qiao Jin, Sanchit Sinha, Zhiyong Lu and 1 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 1 on Hugging Face · Code ★ 6

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Spatial-IQ: Deconstructing Spatial Intelligence via Hierarchical Capability Tests

Spatial-IQ hierarchically decomposes spatial reasoning into perceptual and cognitive sub-tasks, showing models use shortcuts and that hierarchical chain-of-thought training improves consistency and accuracy.

Patrick Rim, Tom Long, Ekta Prashnani, Ruth Rosenholtz and 5 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Cross-Dialect Generalization Without Retraining: Benchmarks and Evaluation of Schema-Derived Constrained Decoding for MLIR

Schema-derived ODS constraints enable small LMs to match or exceed 15B, 34B models on structural MLIR dialects at 8, 25× speed without retraining, though attribute-heavy dialects remain challenging.

Plawan Kumar Rath

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

I Have a Stream: Making Self-Supervised Learning Work on Continuous Video

Self-supervised video-stream pretraining fails due to intra-batch near-duplicate frames, but proposed StreamMAE with motion-biased crops matches i.i.d. MAE and scales to 95 hours.

Ivan Martinović, Lukas Knobel, Yuki Asano

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026 · ▲ 14 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Predicting Plasticity in Deep Continual Learning: A Theoretical Perspective

Existing plasticity diagnostics fail to predict trainability, but optimization readiness, combining gradient strength and reliability, lower-bounds optimization gain and predicts plasticity more reliably.

Jiuqi Wang, Jayanth Srinivasa, Claire Chen, Shuze D Liu and 2 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

OpenWebRL: Demystifying Online Multi-turn Reinforcement Learning for Visual Web Agents

OpenWebRL enables open online RL for visual web agents, with a 4B model reaching 67% Online-Mind2Web and 64% DeepShop success using minimal initialization data.

Rui Yang, Qianhui Wu, Yuxi Chen, Hao Bai and 6 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 19 on Hugging Face · Code ★ 52

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

CodeMimicry: Exploiting Safety Generalization Lag in Large Language Models via Structured Code Completion

Safety alignment lags in code domains enable automated jailbreaks through structured code completion, achieving 96.25% attack success across eight commercial LLMs.

Liang Zhen, Wentao Chen, Hai Huang

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Dual Dimensionality for Local and Global Attention

Distance-Adaptive Representation uses high-dimensional local and low-dimensional distant keys and values to cut KV cache size while matching full-dimensional baseline performance.

Zhiyuan Wang, Xuan Luo, Sirui Zeng, Xifeng Yan

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Gen-Searcher: Reinforcing Agentic Search for Image Generation

Gen-Searcher trains a search-augmented image generation agent via supervised and reinforcement learning, yielding about 16-point gains on knowledge-intensive benchmarks.

Kaituo Feng, Manyuan Zhang, Shuang Chen, Yunlong Lin and 6 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 54 on Hugging Face · Code ★ 400

100% Readers1 of 1 upvoted
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read

Recursive Multi-Agent Systems

RecursiveMAS scales multi-agent collaboration through recursive latent-space computation via RecursiveLink and inner-outer loop co-optimization, improving accuracy by 8.3% with 1.2-2.4x speedup and 34.6%-75.6% token reduction over baselines.

Jiaru Zou, Rui Pan, Ruizhong Qiu, Pan Lu and 7 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published Apr 28, 2026 · 0 citations · ▲ 239 on Hugging Face · Code ★ 961

100% Readers1 of 1 upvoted
14/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read

PaLoRA: Paced Low-Rank Adaptation for Continual Learning

PaLoRA derives an optimal rank-aware pacing law for LoRA continual learning that adaptively restricts gradient scaling to prevent forgetting, improving long-horizon benchmark accuracy by 4%.

Yuxuan Li, Fanhu Zeng, Hao Tang

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published Oct 3, 2026 · ▲ 9 on Hugging Face · Code ★ 2

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 1/5
88%Must read
?Must readVote to see the score

Bridging Modalities, Spanning Time: Structured Memory for Ultra-Long Agentic Video Reasoning

MAGIC-Video unifies episodic, semantic, and visual content via a multimodal memory graph and narrative chain for agentic ultra-long video reasoning, outperforming prior agentic systems by up to 10.1 points.

Jiazheng Li, Chi-Hao Wu, Yunze Liu, Kaize Ding and 2 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 2/5
88%Must read
?Must readVote to see the score

SecureClaw: Clawing Back Control of LLM Agents

SecureClaw dual-bounds LLM agents by confining plaintext via opaque handles at the read boundary and enforcing authorized previews at the action sink, achieving near-zero attack success with preserved utility.

Yuhan Ma, Stefan Schmid

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 2/5
88%Must read
?Must readVote to see the score

Objective Shaping with Hard Negatives: Windowed Partial AUC Optimization for RL-based LLM Recommenders

GRPO for LLM recommenders maximizes AUC but beam-search negatives reshape objectives toward partial AUC; proposed WPAUC with TAWin optimization improves top-K alignment and achieves state-of-the-art results.

Wentao Shi, Qifan Wang, Chen Chen, Fei Liu and 6 more

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 4/5
medium 8/10
strict 3/5
88%Must read
?Must readVote to see the score

The Mechanism of Weak-to-Strong Generalization: Feature Elicitation from Latent Knowledge

Multi-step SGD enables weak-to-strong generalization by eliciting pre-trained features without catastrophic forgetting of off-target capabilities.

Ryoya Awano, Taiji Suzuki

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 4/5
medium 7/10
strict 4/5
88%Must read
?Must readVote to see the score

Geometric Factual Recall in Transformers

Transformers memorize facts geometrically via linear superpositions and MLP selectors, needing only logarithmic dimensions and enabling zero-shot MLP transfer.

Shauli Ravfogel, Gilad Yehudai, Joan Bruna, Alberto Bietti

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 4/5
medium 7/10
strict 4/5
88%Must read
?Must readVote to see the score

A simple model of co-emergence of grid and place fields

A single sensory-prediction recurrent network with Dale's Law co-emerges grid and place cells without supervision, reproducing key spatial coding phenomena.

Zhaoze Wang, Genela Morris, Dori Derdikman, Pratik Chaudhari and 1 more

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 3/5
88%Must read
?Must readVote to see the score

Perfect Parallelization in Mini-Batch SGD with Classical Momentum Acceleration

Classical momentum acceleration improves proportionally with mini-batch size for quadratic interpolation optimization, enabling perfect parallelization of stochastic gradient computations.

Sachin Garg, Michal Derezinski

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 2/5
88%Must read
?Must readVote to see the score

LeAct: Learning to Reason from Expert Actions

LeAct recovers expert reasoning chains from actions alone to train reasoning models; it reaches near-optimal expert performance across games and robotics while improving on direct imitation.

Ziran Yang, Chengshuai Shi, Raj Ghugare, Benjamin Eysenbach and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 2/5
88%Must read
?Must readVote to see the score

Jet-Long: Efficient Long-Context Extension with Dynamic Bifocal RoPE

Jet-Long dynamically rescales RoPE via bifocal local and long-range windows with an analytic length-aware schedule to extend LLM contexts without tuning, outperforming baselines on RULER, HELMET-RAG, and perplexity while retaining near-FlashAttention-3 throughput.

Haozhan Tang, Zerui Wang, Yuxian Gu, Song Han and 1 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 24 on Hugging Face · Code ★ 13

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

PhysicianBench: Evaluating LLM Agents in Real-World EHR Environments

PhysicianBench evaluates LLM agents on 100 real-world EHR tasks across 21 specialties, finding top models achieve only 46% success.

Ruoqi Liu, Imran Mohiuddin, Austin J Schoeffler, Kavita Renduchintala and 9 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 8 on Hugging Face · Code ★ 59

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Before It Fades: Reinforcing Temporal Representations at Inference Time in VideoLLMs

VideoLLMs lose temporal representations across layers, so Temporal Activation Injection reinforces fading divergence at inference to improve video reasoning without training.

Youngwoo Shin, Yusung Ro, Minseo Kim, Junmo Kim

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 5 on Hugging Face · Code ★ 2

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Actionable Hallucination Detection: Translating Latent Uncertainty into Agentic Critique

Latent Critic is a lightweight LoRA adapter that translates LLM latent uncertainty into real-time, localized natural-language hallucination feedback, achieving 0.966 AUROC and enabling agent self-correction with negligible latency.

Sanidhya Vijayvargiya, Rahul Lokesh

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Towards Mitigating Deceptive Safety Alignment in Large Reasoning Models

Large reasoning models exhibit deceptive safety alignment where reasoning and answers conflict, which SARA mitigates via safety-aware RL rewards.

Xiangyu Zhou, Saleh Z Zade, Rafi Ibn Sultan, Alexander Kotov and 1 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

SURF: Steering the Scalarization Weight to Uniformly Traverse the Pareto Front

SURF inverts a geometric arc-length cumulative distribution to sample scalarization weights yielding uniform Pareto front coverage and converges linearly to a finite-sampling floor.

Liuyuan Jiang, Chentong Huang, Lisha Chen

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

You Can’t Have It Both Ways: Concept Entanglement Limits Diffusion Model Unlearning

Concept entanglement in diffusion models forces a trade-off where robust unlearning of a target necessarily damages overlapping concepts proportionally to their overlap.

Yian Wang, Ali Ebrahimpour-Boroojeny, Hari Sundaram, Varun Chandrasekaran

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Hi-Q: Hierarchical Evidence-guided Query Refinement for Multi-Hop Question Answering

Hi-Q hierarchically refines multi-hop queries via evidence-guided resolution and expansion, outperforming iterative and graph-based retrieval baselines on full-corpus benchmarks.

Jueun Kim, Sungho Park, WOOK SHIN HAN

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 35 on Hugging Face · Code ★ 1

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Interpreting Latent Protein Language Model Features with Geometric Annotations

Sparse autoencoders in ESM-2 are interpreted via Cα geometric features, revealing localized structural patterns and substructure within biological labels that sequence annotations miss.

Siddharth Setlur, Djordje Mihajlovic, Darrick Lee

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

WebNavigator: Global Web Navigation via Interaction Graph Retrieval

WebNavigator overcomes topological blindness via interaction graphs to turn web navigation into deterministic retrieval and pathfinding, doubling multi-site success on WebArena.

Xuanwang Zhang, Yuteng Han, Jinnan Qi, Xinyu Liu and 3 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Chaining 2-FWL GNNs for Combinatorial Graph Alignment

Chaining 2-FWL GNNs injects discrete combinatorial feedback via iterative ranking to solve graph alignment, outperforming classical and prior GNN baselines across synthetic and real-world benchmarks.

Marc Lelarge

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

MemArena: An Ego-Centric Benchmark for On-Device Agentic Personal Memory Assistants at Scale

MemArena benchmarks on-device ego-centric personal memory assistants via simulated multi-session agents, showing memory backend choice dominates accuracy and permission-aware access fails universally.

Jiadong Zhang, Xiaosong Ma

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face · Code ★ 1

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Positive-Unlabeled Preference Optimization For Chest X-ray Report Generation

PU-DPO treats unmentioned radiology findings as unlabeled rather than negative, using edited contrastive pairs to prevent omission noise from corrupting preference optimization and improving hidden finding recovery.

Yuta Kobayashi, Pradyun Ramesh, Muhammad Ahmed Chaudhry, Vincent Jeanselme and 4 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

VESTA: Visual Exploration with Statistical Tool Agents

VESTA equips vision-language models with dynamically growing statistical toolkits for data exploration and model refinement, outperforming baselines on complex domain-specific modeling tasks via reusable diagnostic tools.

William Rudman, Abhishek Divekar, Kanishk Jain, Sebastian Joseph and 5 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 2 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

A Unified Uncertainty Representation for Graph Neural Networks via Doubly-Spectral Stochastic Expansion

Doubly-spectral stochastic GNN expansions yield unified uncertainty representations improving calibration, OOD detection, and distribution-shift robustness.

Fred Xu, Thomas Markovich, florence regol, Yizhou Sun

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Calibrating LLMs with Semantic-level Reward

Calibration with Semantic Reward improves LLM calibration by replacing token-level confidence with direct semantic-space rewards, reducing ECE by up to 40% and raising AUROC by up to 31%.

Fengfei Yu, Ruijia Niu, Dongxia Wu, Yian Ma and 1 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Diversity Combining for Multi-Path LLM Reasoning

Multi-path LLM reasoning is modeled as diversity combining, showing path correlation limits majority-vote gains and that adaptive sampling retains near-peak accuracy.

Guangsheng Yu, Litianyi Zhang, Qin Wang, Xu Wang and 4 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · Code

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

HiFloat4 Format for End-To-End Reinforcement Learning Post-Training of Large Language Models

HiFloat4 enables end-to-end FP4 reinforcement learning by fixing rollout activation underflow with Rollout-ResQ, cutting accuracy gaps to 1.1% versus BF16.

Hei Yi Mak, Shadan Golestan, Hoang Le, Mehran Taghian Jazi and 9 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Adaptive auditing of AI systems with anytime-valid guarantees

An adaptive auditing framework using anytime-valid betting tests rigorously evaluates AI failure modes with as few as 20 observations and certifies global robustness upon passing stringent audits.

Siyu Zhou, Patrick Vossler, Venkatesh Sivaraman, Yifan Mai and 1 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Boosting Brain-to-Image Decoding with TRIBE v2 Data Augmentation

TRIBE v2 synthetic fMRI augmentation improves brain-to-image decoding by up to 68%, though optimal synthetic-to-real ratios vary by dataset, and synthetic-only training achieves above-chance zero-shot decoding.

Yohann Benchetrit, Marlene Careil, Simon Dahan, Hubert Banville and 2 more

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Full Attention Strikes Back: Transferring Full Attention into Sparse within Hundred Training Steps

RTPurbo converts full-attention LLMs into sparse models within hundreds of steps via retrieval heads and dynamic indexing, achieving near-lossless accuracy with 9.36x prefill and 2.01x decode speedups.

Yanke Zhou, Yiduo Li, Hanlin Tang, Maohua Li and 5 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 90 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Fast 4D Mesh Generation by Spatio-Temporal Attention Chains

Spatio-Temporal Attention Chains accelerate training-free 4D mesh generation 13x to 9 seconds via latent temporal correspondences, improving quality, scaling to longer videos, and enabling tracking and camera estimation.

Dvir Samuel, Yuval Atzmon, Gal Chechik, Yoni Kasten

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 11 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Half-Truths Break Similarity-Based Retrieval

CLIP-style dual encoders often prefer half-true image descriptions with incorrect added details over correct shorter ones due to weak part-level supervision; CS-CLIP improves half-truth accuracy to 69.3% through component-level contrastive fine-tuning.

Bora Kargi, Arnas Uselis, Seong Joon Oh

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026 · ▲ 6 on Hugging Face · Code ★ 15

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Breaking the Bias Barrier in Concave Multi-Objective Reinforcement Learning

Concave scalarized multi-objective RL suffers biased gradients that cause O(ε⁻⁴) sample complexity; multi-level Monte Carlo NPG achieves optimal O(ε⁻²).

Swetha Ganesh, Jason Chia, Vaneet Aggarwal

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

AnyHand: A Large-Scale Synthetic Dataset for RGB(-D) Hand Pose Estimation

AnyHand provides 6.6M synthetic RGB-D hand images with occlusions and aligned depth, significantly improving 3D hand pose estimation benchmarks and showing data diversity rivals scale.

Chen Si, Yulin Liu, Bo Ai, Jianwen Xie and 3 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

idSCD: Identifying Training Datasets through Semantic Correlation Descriptors

Dataset-specific training traces are captured via semantic correlation descriptors (SCDs) that fingerprint dataset membership via internal semantic correlations, outperforming black-box and white-box baselines by over 60% ROC-AUC when semantic particularities differ.

Ionuț Hodoroagă, Andrada Gobeajă, Marius Leordeanu, Elena Burceanu

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Improving General Role-Playing Agents via Psychology-Grounded Reasoning and Role-Aware Policy Optimization

Psy-CoT decomposes role-playing reasoning into psychology-grounded steps, and RAPO uses profile-token mutual information to weight gradients, improving fidelity and out-of-distribution generalization over supervised fine-tuning.

Zhenhua Xu, Dongsheng Chen, Jian Li, Yitong Lin and 6 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Decoupling Exploration and Policy Optimization: Uncertainty Guided Tree Search for Hard Exploration

Uncertainty-guided tree search decouples exploration from policy optimization to bypass RL during exploration, then distills discovered trajectories into deployable policies achieving state-of-the-art sparse-reward results.

Zakaria Mhammedi, James Cohan

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Latent-space Attacks for Refusal Evasion in Language Models

Refusal suppression is recast as a latent-space evasion attack against linear refusal probes, explaining prior ablation and motivating a controlled evasion method that achieves state-of-the-art refusal bypass across 15 models.

Giorgio Piras, Raffaele Mura, Fabio Brau, Maura Pintor and 3 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

When a Zero-Shooter Cheats: Improving Age Estimation via Activation Steering

Vision-language models use celebrity identity shortcuts rather than visual age cues, and activation steering suppresses this to cut mean absolute error by up to 25%.

Erik Imgrund, Pia Hanfeld, Klim Kireev, Konrad Rieck

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

TrajLoc: Trajectory-Attention Localization for Multi-Object Motion Control

TrajLoc isolates per-object attention via Gaussian heatmaps to control multi-object motion, improving trajectory adherence by 51% and PSNR by 4.3 dB.

Omer Sela, Inbar Huberman-Spiegelglas, Michael Rotman, Sagie Benaim and 1 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face · Code ★ 2

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Theory of Optimal Learning Rate Schedules and Scaling Laws for a Random Feature Model

Optimal LR schedules for a solvable random feature model reveal easy-phase polynomial decay and hard-phase warmup-stable-decay regimes that improve scaling over constant or power-law schedules, with momentum and batch ramps further enhancing wall-clock time.

Blake Bordelon, Francesco Mori

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Tracing the Cascade: A Topology-Aware Evaluation Framework for Scientific Agent Hallucinations

SCHEMA evaluates scientific agent hallucinations via topology-aware diagnostics, showing errors cluster at connected knowledge hubs and correct answers often stem from flawed reasoning.

Xinshun Feng, Ziqi Miao, Lijun Li, Jing Shao

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Causal Evaluation of Membership Inference Attacks

Causal inference framing of membership inference attacks defines memorization as training inclusion effects, reveals interference and distribution-shift biases, and yields reliable estimators without retraining.

Mathieu Even, Clément Berenfeld, Linus Bleistein, Tudor Cebere and 2 more

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score
NeurIPS 2026EmoryPrivacy

SnapAudit: Active Auditing of Differentially Private In-Context Learning via Snapshot-Based Simulation

SnapAudit decomposes DP-ICL into deterministic and noisy stages and uses snapshot simulation to audit privacy 80-200x faster, revealing flaws in existing Gaussian calibrations and embedding sensitivity analyses.

Yuyang Xia, Ruixuan Liu, Li Xiong

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

FML-bench: A Controlled Study of AI Research Agent Strategies from the Perspective of Search Dynamics

FML-bench isolates agent strategy from infrastructure across 18 ML tasks, finding greedy hill-climbing nearly matches tree search, while adaptive exploration switching outperforms fixed strategies.

Qiran Zou, Hou Hei Lam, Wenhao Zhao, Tingting Chen and 10 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Measuring Collapse and Correction in Homogeneous-Panel LLM Debate

A transition-ledger protocol for LLM debate separates collapse from correction, showing freeze policies prevent collapses but lose corrections and pre-debate probes poorly predict conditional collapse.

Xin Li, Mengbing Liu, Chau Yuen

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 5 on Hugging Face · Code

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Visual-ERM: Reward Modeling for Visual Equivalence

Visual-ERM is a multimodal generative reward model that evaluates vision-to-code outputs in rendered visual space, improving Qwen3-VL-8B-Instruct by up to 8.4 points and outperforming larger models on fine-grained visual discrepancy benchmarks.

Ziyu Liu, Shengyuan Ding, Xinyu Fang, Xuanlang Dai and 5 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 21 on Hugging Face · Code ★ 69

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

SR-GRPO: Stable Rank as an Intrinsic Geometric Reward for Large Language Model Alignment

Stable rank measures hidden-state dimensionality as an intrinsic quality signal, achieving 84% RewardBench accuracy and boosting reasoning by up to 19% via SR-GRPO without external supervision.

Yixuan Tang, Yi Yang

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026 · ▲ 9 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

LLM Judge Validation Under Sparse Overlap: From Inference to Design

Sparse overlap in LLM judge validation drives wrong deployment decisions, reaching 25% error at 5% overlap; minimum 25% overlap and stratified allocation reduce errors significantly.

Junxuan Li, Arko Mukherjee, Soumyabrata Pal

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

ScreenShot: A Foundation Model for Few-Shot Combination Drug Screening

ScreenShot is a hierarchical transformer pretrained on drug screening datasets that predicts combination therapy responses via in-context learning from limited observations without molecular profiling or fine-tuning, outperforming baselines and enabling efficient active screening.

Antoine De mathelin, Christopher Tosh, Wesley Tansey

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

PolyTopoBench: A Benchmark for Complex Vector Polygon Generation from Remote Sensing Imagery

PolyTopoBench benchmarks vector polygon generation from remote sensing images, finding existing methods fail on complex multi-ring topologies with holes.

Zeping Liu, Ni Lao, Weiwei Sun, Gil Wolff and 4 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

From History to State: Constant-Context Skill Learning for LLM Agents

Constant-context skill learning embeds recurring agent workflows into lightweight modules via step-level SFT and online RL, cutting prompt tokens 2-7x while matching state-of-the-art success on ALFWorld, WebShop, and SciWorld.

Haoyang Xie, Xinyuan Wang, Yancheng Wang, Puda Zhao and 1 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Learning Latency-Aware Orchestration for Multi-Agent Systems

LAMaS learns latency-aware orchestration for multi-agent systems via critical-path-aware credit assignment and adaptive runtime pruning, cutting latency over 50% while preserving accuracy.

Xi Shi, Mengxin Zheng, Qian Lou

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

You Only Need Minimal RLVR Training: Extrapolating LLMs via Rank-1 Trajectories

RLVR weight updates are near rank-1 and predictable, so RELEX extrapolates them via linear regression to match full training with only 15% of steps.

Zhepei Wei, Xinyu Zhu, Wei-Lin Chen, Chengsong Huang and 2 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 50 on Hugging Face · Code ★ 16

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Model-Adaptive Tool Necessity Reveals the Knowing-Doing Gap in LLM Tool Use

This paper defines model-adaptive tool necessity and finds LLMs exhibit a knowing-doing gap where cognition and action diverge, causing 26.5, 54.0% mismatches.

Yize Cheng, Chenrui Fan, Mahdi JafariRaviz, Keivan Rezaei and 1 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 12 on Hugging Face · Code ★ 17

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

LangFlow: Continuous Diffusion Rivals Discrete in Language Modeling

LangFlow closes the continuous-discrete language-modeling gap via flow matching and a learnable noise schedule, matching discrete diffusion perplexity and exceeding autoregressive zero-shot results on four benchmarks.

Yuxin Chen, Chumeng Liang, Hangke Sui, Ruihan Guo and 3 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 15 on Hugging Face · Code ★ 96

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

TIER: Trajectory-Invariant Execution Rewards for Multi-Step Tool Composition

TIER derives dense tool-use rewards from execution and schemas rather than reference paths, enabling over 90% accuracy on multi-step composition where trajectory supervision fails.

Anay Kulkarni, Chia En Lu, Dheeraj Mekala, Jayanth Srinivasa and 2 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

KV-PRM: Efficient Process Reward Modeling via KV-Cache Transfer for Multi-Agent Test-Time Scaling

KV-PRM eliminates text re-encoding by scoring via pre-existing KV caches, reducing process reward modeling cost from quadratic to linear and cutting latency and FLOPs by orders of magnitude.

Peng Kuang, Haibo Jin, Xiaoyu Han, Yanli Wang and 4 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

CLR-voyance : Reinforcing Open-Ended Reasoning for Inpatient Clinical Decision Support with Outcome-Aware Rubrics

CLR-voyance frames inpatient reasoning as a POMDP with outcome-grounded rubrics, yielding an 8B model scoring 84.91% on CLR-POMDP and outperforming larger medical reasoning models.

Aishik Nagar, Arun-Kumar Kaliya-Perumal, Yu-Hsuan Han, Andrew Sheng-Han Huang and 4 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Gym-Anything: Turn Any Software into an Agent Environment

Gym-Anything converts any software into interactive agent environments via multi-agent setup and auditing, yielding CUA-World with 10K long-horizon tasks and improved agent performance.

Pranjal Aggarwal, Graham Neubig, Sean Welleck

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Characterizing Memorization in Diffusion Language Models: Generalized Extraction and Sampling Effects

A generalized extraction framework proves diffusion language model memorization rises with sampling resolution, and they leak less personally identifiable information than autoregressive models.

Xiaoyu Luo, Wenrui Yu, Qiongxiu Li, Johannes Bjerva

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

TIGER-FG: Text-Guided Implicit Fine-Grained Grounding for E-commerce Retrieval

TIGER-FG uses text-guided implicit fine-grained grounding and dual distillation to improve cropped-query e-commerce retrieval, boosting Recall@1 by up to 34.4 points without object detection.

Xinyu Sun, Huangyu Dai, Lingtao Mao, Zexin Zheng and 4 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

PoseBridge: Bridging the Skeletonization Gap for Zero-Shot Skeleton-Based Action Recognition

PoseBridge extracts pose-anchored semantic cues from human pose estimation to recover upstream visual context lost in skeletons, improving zero-shot skeleton action recognition by up to 17.4 points.

Sanghyeon Lee, Jinwoo Kim, Jong Taek Lee

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Stability and Generalization in Looped Transformers

A fixed-point framework proves looped transformers need recall plus outer normalization for stable, input-dependent extrapolation, validated across chess, sudoku, and prefix-sums tasks.

Asher Labovich

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

BioBlobs: Unsupervised Discovery of Functional Substructures for Protein Function Prediction

BioBlobs is an encoder-agnostic framework that compresses proteins into cohesive substructures to predict function and unsupervisedly discovers functional sites like catalytic triads. It matches baselines using only a small residue fraction, recovers experimentally annotated catalytic sites, and sca

Xin(Allen) Wang, Kaiwen Shi, Carlos Oliver

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

TimeWarp: Evaluating Web Agents by Revisiting the Past

TimeWarp evaluates web agents on evolving UIs, finding vision agents vulnerable to changes and fine-tuned text agents brittle, while plan-distillation training via TimeTraj substantially improves robustness.

Farhan Ishmam, Kenneth Marino

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · Code ★ 4

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

TACT: Mitigating Overthinking and Overacting in Coding Agents via Activation Steering

TACT detects overthinking and overacting as linear drift axes in hidden states and applies activation steering to pull agents back toward calibrated behavior, boosting resolution rates up to 5.8 points and cutting steps by 26%.

Yuan Sui, Yulin Chen, Yibo Li, Xue Jiang and 5 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

EEG Benchmarking Needs a Task Specification Layer: NeuroDoc for Rulebook-Guided, Executable Benchmark Construction

NeuroDoc introduces a rulebook-guided task specification layer that standardizes EEG benchmarks into 53 reviewed entries with 245 executable task definitions across four model backbones.

Chengxuan Qin, 致格 陈, Pengshu, Rui Yang and 8 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Visual Instruction Tuning Aligns Modalities through Abstraction

Visual instruction tuning embeds image features into LLM intermediate semantic layers, aligning them with text abstractions to drive multimodal processing.

Luis Palacios, Lorenzo Basile, Diego Doimo, Alberto Cazzaniga

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

RepoMirage: Probing Repository Context Reasoning in Code Agents with Perturbations

RepoMirage evaluates code agents via repository perturbations, revealing severe repository context reasoning gaps and exploration drift, while RepoAnchor improves performance through structure-first scaffolding.

Hanyu Li, Yichi Zhang, Speed Zhu, Hang Su and 2 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

TOPPO: Rethinking PPO for Multi-Task Reinforcement Learning with Critic Balancing

TOPPO balances critic gradients to fix PPO's multi-task ill-conditioning, outperforming SAC baselines with fewer parameters and steps.

Yuanpeng Li, Rui Miao, Gefei Lin, Annie Qu

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Evidence-RL: Towards Evidence-intensive Visual Reasoning

Counterfactual Evidence Disentanglement (CED) audits vision-language model grounding by comparing evidence-region and non-evidence-region support drops inside GRPO, improving visual reasoning across benchmarks without inference overhead or evidence annotations.

Haojie Huang, Xinlei Yu, Chengming Xu, Zhangquan Chen and 5 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 16 on Hugging Face · Code ★ 4

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Self-Improvement Imitation with Biologically Guided Search for Protein Design Under Oracle Budgets

SILO uses hierarchical self-improvement imitation with biologically guided stochastic beam search to optimize protein fitness under tight oracle budgets, outperforming baselines across eight landscapes.

Ashima Khanna-Reiter, Dominik G Grimm

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Alignment Dynamics in LLM Fine-Tuning

A unified framework decomposes LLM alignment dynamics into competing rebound and driving forces, explaining reversal and faster re-alignment via rehearsal priming.

Yuhan Huang, Huanran Chen, Yinpeng Dong

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Unifying Contrastive and Generative Objectives for Visual Understanding and Text-to-Image Generation

DREAM unifies contrastive and generative objectives via Masking Warmup, yielding joint visual understanding gains and faster, higher-quality text-to-image generation.

Chao Li, Tianhong Li, Sai V Nuthalapati, Hong-You Chen and 8 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 6 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

InduceKV: Fixed-Footprint Continual Adaptation of Multimodal LLMs via Inducing KV Memories

InduceKV stores attention-ready KV memory entries with fixed memory budgets to adapt multimodal LLMs continually, outperforming PEFT, replay, and prompt-retrieval baselines.

Qianyu Chen, Ziteng Feng, Canran Xiao, Runxuan Tang

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Your Neighbors Know: Leveraging Local Neighborhoods for Backdoor Detection in Decentralized Learning

Argus detects backdoor attacks in decentralized learning by having nodes share local trigger analyses with neighbors and filter updates via structural similarity, reducing attack success by up to 90 points without a central server.

Sayan Biswas, Antoine Boutet, Davide Frey, Romaric Gaudel and 6 more

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

EVOCHAMBER: Test-Time Co-evolution of Multi-Agent System at Individual, Team, and Population Scales

EVOCHAMBER enables training-free multi-agent test-time co-evolution across individual, team, and population scales via asymmetric cross-agent knowledge transfer, achieving up to 32% relative math gains and emergent specialization.

Yaolun Zhang, Tianyi Xu, Shengyu Dai, Zhenwen Shao and 2 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 10 on Hugging Face · Code ★ 4

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Externalized CPDAG Summaries Improve LLM Causal Deduction

Structured Thinking externalizes typed CPDAG summaries before reasoning, raising LLM causal deduction F1 by up to 13.4 points on Corr2Cause.

Wentao Sun, João P Nogueira, Dominique Verchere, Mathieu Acher and 1 more

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

MaPP: A Unified Marginalized Posterior-Predictive Framework for Data-Efficient RLVR

MaPP unifies denoised response advantage estimation and prompt selection via Beta-Binomial marginalization to eliminate composition noise, improving RLVR efficiency and accuracy.

YangYang Ren, Haodong Zhu, Sheng Xu, Yanjing Li and 3 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

BALTO: Balanced Token-Level Policy Optimization for Hallucination Mitigation

BALTO applies balanced token-level credit assignment to mitigate LLM hallucinations by redistributing probability from unsupported to faithful content, outperforming response-level methods on faithfulness benchmarks.

Ning Li, Zixuan Guo, Yan Xu, Wenbo Fei and 6 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Models That Know How Evaluations Are Designed Score Safer

Models with evaluation meta-knowledge about benchmark structures score safer via implicit behavioral shifts, confounding safety assessments independently of explicit awareness.

Katharina Deckenbach, Haritz Puerto, Jonas Geiping, Sahar Abdelnabi

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026 · ▲ 6 on Hugging Face · Code ★ 3

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

FineVision: Open Data Is All You Need

FineVision unifies 24 million vision-language samples via rigorous curation and decontamination, and models trained on it outperform existing open mixtures across broad evaluations.

Luis Wiedmann, Orr Zohar, Amir Mahla, Xiaohan Wang and 5 more

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026 · ▲ 81 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Model Guides You How to Draw: Adaptive Visual Gating for Unified Multimodal Reasoning

AdaViG uses internal generation-intent and visual-fidelity signals to abort unhelpful visual reasoning steps early, improving multimodal reasoning accuracy by up to 5.7% while cutting visual generation costs by 25-91%.

Wenxi Gao, Guanxi Lu, Didi Zhu, Hao Chen and 4 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

FlashMol: High-Quality Molecule Generation in as Few as Four Steps

FlashMol uses distribution-matching distillation and timestep respacing to generate high-quality 3D molecular conformations in as few as four steps, achieving up to 250x speedup over teachers.

Xinyuan Wei, Zian Li, Shaoheng Yan, Cai Zhou and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Closed-Form Linear-Probe Dataset Distillation for Pre-trained Vision Models

CLP-DD distills synthetic datasets for frozen-feature linear probing via a closed-form kernel ridge solver, achieving near-state-of-the-art accuracy with roughly 14x faster training and far lower memory.

Bincheng Peng, Miki Haseyama, Guang Li, Ping Liu and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

GridProbe: Posterior-Probing for Adaptive Test-Time Compute in Long-Video VLMs

GridProbe scores frame evidence via frozen VLM answer-space probing and adaptive selection to reduce long-video attention costs with minimal accuracy loss. It matches monolithic baselines on Video-MME-v2 at 3.36x lower compute and Pareto-dominates baselines on LongVideoBench.

Mohamed Eltahir, Ayash, Ali Habibullah, Tanveer Hussain and 1 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 2 on Hugging Face · Code ★ 2

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Beyond the Half Approximation: Fair and Efficient Online Class Matching

Threshold-based algorithms achieve constant class envy-freeness and exceed 1/2 utilitarian welfare in online class matching, with near-matching upper bounds characterizing fairness costs.

Sander Borst, Max Springer

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

BankerToolBench: Evaluating AI Agents in End-to-End Investment Banking Workflows

BankerToolBench benchmarks AI agents on multi-hour investment banking workflows using expert rubrics, finding frontier models fail nearly half of criteria with zero client-ready outputs.

Elaine Lau, Markus Dücker, Ronak Chaudhary, Hui Wen Goh and 24 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Focusable Monocular Depth Estimation

FocusDepth uses spatially-aligned multi-scale prompt fusion to boost target-region depth accuracy and sharp boundaries while preserving global geometry, outperforming global baselines on FDE-Bench.

Yuxin Du, Tao Lin, Zile Zhong, Runting Li and 6 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

VideoMLA: Low-Rank Latent KV Cache for Minute-Scale Autoregressive Video Diffusion

VideoMLA replaces per-head video diffusion KV caches with shared low-rank latents to cut memory by 92.7% and improve long-horizon streaming quality and throughput.

Hidir Yesiltepe, Jiazhen Hu, Tuna Han Salih Meral, Adil K Akan and 3 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 24 on Hugging Face · Code ★ 18

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

DynaTokens: Teaching Dynamics to Camera-Controlled Video Models at Test Time

DynaTokens teaches dynamics to frozen camera-controlled video models via scene-specific learnable tokens, improving simultaneous dynamics and camera control over full fine-tuning.

Ziqi Ma, Hongqiao Chen, Georgia Gkioxari

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Rank Is Not Capacity: Spectral Occupancy for Latent Graph Models

Spectra replaces fixed latent rank with a train-time controllable effective-rank coordinate via trace-normalized spectral prefixes, making model capacity a fitted property rather than a hyperparameter.

Nikolaos Nakis, Panagiotis Promponas, Konstantinos Tsirkas, Katerina Mamali and 3 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Revisiting Cross-View Completion: Self-Supervised Pre-Training via Reconstruction Error Comparison

Gekko uses relative reconstruction error between cross-view and masked-autoencoder predictions as a self-supervised co-visibility proxy, adding binocular training signals that consistently outperform CroCo on 3D vision tasks while training directly from raw video.

Thibaut Loiseau, Guillaume Bourmaud, Vincent Lepetit

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

A Scalable Multi-Task Model for Virtual Sensors

A multi-task virtual sensor model predicts diverse targets via shared representations, reducing computation up to 415x and memory 951x while improving accuracy over isolated and foundation alternatives.

Leon Götz, Lars Frederik Peiss, Erik Sauer, Andreas U Sass and 3 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

EntityBench: Towards Entity-Consistent Long-Range Multi-Shot Video Generation

EntityBench introduces 140-episode multi-shot video benchmark with per-shot entity schedules and three-pillar evaluation, showing explicit per-entity memory yields highest character fidelity.

Ruozhen He, Meng Wei, Ziyan Yang, Vicente Ordonez

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 3 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Learning What to Predict: Downstream-Guided Task Design for Continued Pretraining

V-pretraining uses downstream examples to score self-supervised task designs, improving target capabilities without degrading generalization across language and vision.

Shuqi Ke, Giulia Fanti

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 2 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Asymmetric Phase Coding Audio Watermarking

Asymmetric Phase Coding embeds Ed25519 signatures into audio via phase-bin QIM for blind, training-free cryptographic verification resilient to cropping, compression, and resampling.

Guang Yang, Fengchen Liu, Amir Ghasemian, Zhong Wang and 2 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

DAWN: Dependency-Aware Fast Inference for Diffusion LLMs

DAWN extracts token dependency graphs to select reliable unmasking positions, accelerating diffusion LLM inference by 1.80-8.06x with negligible quality loss.

Lizhuo Luo, Zhuoran Shi, Jiajun Luo, Zhi Wang and 3 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face · Code ★ 12

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

MAEB: Massive Audio Embedding Benchmark

MAEB benchmarks 30 audio tasks across 100+ languages, finding no single model dominates and acoustic and linguistic skills trade off.

Adnan E Assadi, Isaac Chung, Chenghao Xiao, Roman Solomatin and 14 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 25 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

PACZero: PAC-Private Fine-Tuning of Language Models via Sign Quantization

PACZero sign-quantizes zeroth-order gradients to achieve zero mutual information fine-tuning with near-baseline accuracy on language models.

Murat Bilgehan Ertan, Xiaochen Zhu, Ha Nguyen, Marten van Dijk and 1 more

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

UniClawBench: A Universal Benchmark for Proactive Agents on Real-World Tasks

UniClawBench introduces a capability-driven benchmark evaluating proactive agents via 400 real-world tasks with live Docker evaluation and multi-turn feedback.

Zhekai Chen, CHENGQI DUAN, Kaiyue Sun, Bohao Li and 3 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 34 on Hugging Face · Code ★ 39

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

DepthMaster: Unified Monocular Depth Estimation for Perspective and Panoramic Images

DepthMaster unifies monocular metric depth estimation for perspective and panoramic images via patch decomposition, a correspondence consistency loss, and virtual projection priors, achieving state-of-the-art zero-shot results across 13 datasets.

Pengfei Wang, Shihao Wang, liyi chen, Zhiyuan Ma and 2 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Counterfactual Maps: What They Are and How to Find Them

Counterfactual maps use volumetric KD trees to find globally optimal counterfactual explanations for tree ensembles via nearest-region search with millisecond queries.

Awa Khouna, Julien Ferry, Thibaut Vidal

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

A Benchmark for Omni-Modal Reasoning in Long Videos

LongShOTBench evaluates long-form omni-modal video reasoning via rubric-scored open-ended questions, and LongShOTAgent achieves 66.64% as the top training-free system.

Mohammed Irfan Kurpath, Jaseel M Kaithakkodan, Jinxing Zhou, Sahal Shaji Mullappilly and 11 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 7 on Hugging Face · Code ★ 26

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Towards Direct Latent-Space Synthesis for Parallel Branches in LLM-Agent Workflows

Parallel-Synthesis lets LLM synthesizers consume parallel agents' KV caches directly via a cache mapper and adapter, matching text synthesis on seven of nine benchmarks while cutting time-to-first-token by 2.5x-11x.

Shikun Liu, Mufei Li, Dongqi Fu, Haoyu Wang and 4 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Frontier Coding Agents Use Metaprogramming to Adapt to Unfamiliar Programming Languages

Strong coding agents adapt to unfamiliar languages via metaprogramming and strategy construction rather than direct coding, and disabling this causes large performance drops.

Aman Sharma, Sushrut Thorat, Paras Chopra

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

SENSE: Semantic Neural Speech Synthesis from Brain Dynamics via Spatial Graph Encoding

SENSE uses graph-based EEG encoding and semantic conditioning to synthesize speech from brain dynamics, outperforming baselines on acoustic and semantic metrics with minimal training subjects.

Jisoo Park, Seonghak Lee, Hyojin Park, Junseok Kwon

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Soft Token Alignment for Cross-Lingual Reasoning

SOLAR aligns soft-token representations across languages during supervised fine-tuning to improve multilingual reasoning consistency, boosting accuracy up to 17.7 points with largest gains on low-resource languages.

Ivy He, Jungsoo Park, Wei &amp;quot;Coco&amp;quot; Xu, Alan Ritter

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Distance Marching for Generative Modeling

Distance Marching improves time-unconditional generative models via distance-focused losses and inference, surpassing flow matching FID with fewer steps and aiding OOD detection.

Zimo Wang, Ishit Mehta, Haolin Lu, Xunpeng Huang and 4 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Exactness Matters for Physical Rule Enforcement

Exact physical projection improves autoregressive forecasts when operators match target geometry, but approximate enforcement can increase rollout error and should be benchmarked by alignment.

Bum Jun Kim

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Distributional Alignment as a Criterion for Designing Task Vectors in In-Context Learning

Task vector design via distributional alignment with in-context learning minimizes next-token probability discrepancy, yielding a linear method that improves accuracy by 9.2% and enables cross-scale transfer.

Jihoon Kwon, Jiwon Choi, Jy-yong Sohn

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Graph-Regularized Sparse Autoencoders for LLM Safety Steering

Graph-Regularized Sparse Autoencoders smooth SAE decoder vectors over a neuron co-activation graph to learn safety-steering directions, improving selective refusal by over 16 points across jailbreak benchmarks while preserving benign performance and generalizing across models.

Jehyeok Yeon, Federico Cinus, Yifan Wu, Luca Luceri

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

FOGO: Forgetting-aware Orthogonalization Optimizer

FOGO detects and resolves gradient interference via spectral orthogonalization and compact codebook memory to prevent dominant directions from suppressing rare updates, improving convergence and retention across continual and standard training.

Toan Nguyen, Yang Liu, Trung Le, Celso de Melo and 1 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

GIST: Gauge-Invariant Spectral Transformers for Scalable Graph Neural Operators

GIST proposes gauge-invariant spectral transformers that use efficient spectral embeddings to achieve linear complexity and provable discretization-invariance, setting state-of-the-art on large-scale mesh benchmarks.

Mattia Rigotti, Nicholas Thumiger, Thomas Frick

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Dense Structural Compression of Transformers via Gauge-Correct Channel Removal

GaugeLasso uses gauge-correct channel penalties to structurally compress transformers during training, reducing compute up to 255x with preserved accuracy and outperforming hand-designed baselines.

Jed A Duersch, Naïm Es-sebbani, Nathanaël Haas, Zied Bouraoui

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Get a GRIP, this will be a long TRIP: A Quantifiable Long-Range Framework for Verifying Over-squashing

Introducing verifiable axioms for long-range graph benchmarks, this work proposes TRIP/GRIP to construct provably long-range tasks with closed-form per-range error bounds and audits existing benchmarks.

Ferran Hernandez Caralt, Simon Heilig, Adrián Bazaga, Asja Fischer and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Aligning Flow Map Policies with Optimal $Q$-Guidance

Flow map policies learn multi-step jumps across flow dynamics for fast action generation, and FMQ adapts them via optimal closed-form Q-guidance to achieve state-of-the-art offline-to-online RL with 21.3% higher success rates.

Christos Ziakas, Alessandra Russo, Joey Bose

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Recon: Reconstruction-Guided Reasoning Synthesis for User Modeling

Recon scores reasoning traces by action reconstruction fidelity to avoid post-hoc rationalization in user modeling, yielding up to 70% win rates over baselines across domains.

Alan Zhu, Mihran Miroyan, Carolyn Wang, Andrew Zhou and 3 more

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

RESCAST-100K: A Comprehensive Dataset for Cross-Domain Residential Load and Indoor Temperature Forecasting

RESCAST-100K introduces a 100,000-home benchmark for cross-domain residential load and temperature forecasting, with cross-attention and MLP-mixer models outperforming recurrent baselines under domain shift.

Jainam Dhruva, Yousaf Raza, A.B. Siddique, Simone Silvestri

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

STRABLE: Benchmarking Tabular Machine Learning with Strings

STRABLE introduces 108 real-world string-and-number tables and benchmarks 445 pipelines, finding simple embeddings with advanced learners suffice for categorical tables while LLMs help on free-text tables.

Gioia Blayer, Myung Jun Kim, Félix Lefebvre, Lennart Purucker and 7 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 4 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

PAGER: Bridging the Semantic-Execution Gap in Point-Precise Geometric GUI Control

PAGER closes the semantic-execution gap for point-precise geometric GUI control via dependency-structured planning and pixel-level execution, achieving 4.1x higher task success than general baselines.

Jingxuan Wei, Xi Bai, Shan Liu, caijun jia and 7 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 15 on Hugging Face · Code ★ 3

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Inline Critic Steers Image Editing

Inline Critic uses learnable tokens to critique frozen image-editing models at intermediate layers, steering hidden states during the forward pass to achieve state-of-the-art results.

Weitai Kang, Xiaohang Zhan, Yizhou Wang, Mang Tik Chiu and 3 more

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Rethinking Training Targets, Architectures and Data Quality for Universal Speech Enhancement

Time-shifted anechoic targets, a two-stage distortion-perception framework, and curated data improve universal speech enhancement and achieve state-of-the-art results.

Szu-Wei Fu, Rong Chao, Xuesong Yang, Sung-Feng Huang and 5 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 8 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Rethinking the Readout: Unlocking Video Backbones for AI-Generated Video Detection

Standard video backbone readouts suppress patch-level temporal dynamics needed to detect AI-generated videos; a lightweight velocity-gated patch profiling readout reaches 95.28 AUC on frozen backbones.

Manni Cui, Ziheng Qin, ZiAn Wang, Ruiqi Liu and 7 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Emergence of a Shared Canonical Object Frame from In-the-Wild Videos

Self-supervised training on 160,000 in-the-wild videos via a shared coarse mesh yields emergent canonical object frames without pose labels, matching supervised category-level pose estimation accuracy.

Tom Fischer, Martin Sundermeyer, Adam Kortylewski, Eddy Ilg

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Closing the Reflection Gap: A Free Calibration Bonus for Agentic RL

RefGRPO closes LLM agents' reflection gap via a free calibration bonus and dynamic schedule, improving calibration and task accuracy. Calibrated reflections enable self-improvement without outcome supervision and effective selective prediction.

Yinglun Zhu

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Done, But Not Sure: Disentangling World Completion from Self-Termination in Embodied Agents

VIGIL decouples world-state completion from terminal commitment in embodied agents, revealing that comparable execution yields up to 19.7 pp differences in correct episode termination.

Ying Chen, Lihuang Fang, Rui Jiang, Mingxu Wang and 3 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Bidirectional Information Flow (BIF) - A Sample Efficient Hierarchical Gaussian Process for Bayesian Optimization

Bidirectional Information Flow enables continuous two-way communication in hierarchical Gaussian processes for Bayesian optimization, improving sample efficiency, training robustness, and modular subtask reuse while significantly outperforming unidirectional and vanilla methods.

Juan D. Guerra, Thomas Garbay, Numa Dancause, Guillaume Lajoie and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

PhyMotion: Structured 3D Motion Reward for Physics-Grounded Human Video Generation

PhyMotion evaluates human video motion via physics-simulated 3D trajectory rewards across kinematics, contact, and dynamics, improving RL post-training realism by +68 Elo.

Yidong Huang, Zun Wang, Han Lin, Dong-Ki Kim and 5 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 6 on Hugging Face · Code ★ 49

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Prospective Hindsight: Self-Calibrating Reinforcement Learning via Prediction–Reality Gaps

Prospective Hindsight uses prediction-reality gaps to weight gradients, improving reinforcement learning performance and self-calibration by targeting blind spots without added objectives.

Jiaxin Zhang, XIANGYU PENG, Qinglin Chen, Yu Li and 2 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Rethinking On-Policy Self-Distillation for Thinking Models

Privileged self-distillation degrades thinking models by suppressing reasoning forks and self-correction tokens, reducing long-rollout accuracy by up to 17%.

Simran Kaur, Narutatsu Ri, Yinghui He, Liam Fowl and 1 more

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 2 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Emergence of Distortions in High-Dimensional Guided Diffusion Models

Classifier-free guidance induces mismatched sampling distributions in diffusion models, with high-dimensional Gaussian distortions emerging when class counts scale exponentially with dimension, and a negative-guidance schedule improves diversity and separability.

Enrico Ventura, Beatrice Achilli, Luca Ambrogioni, Carlo Lucibello

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Block Sphere Vector Quantization

BlockQuant quantizes rotated vector blocks spherically to improve reconstruction and inner-product distortion over coordinate-wise methods, with unified analysis showing rotation-quantizer tradeoffs depend on distortion criteria.

Heesang Ann, Joongkyu Lee, Min-hwan Oh

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

No One Knows the State-of-the-Art in Geospatial Foundation Models

Geospatial foundation model literature lacks standardized evaluation protocols, causing widespread cross-paper scoring discrepancies and unreleased weights, so six concrete community standards are proposed.

Isaac Corley, Caleb Robinson, Nils Lehmann, Gabriel Tseng and 5 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 5 on Hugging Face · Code ★ 27

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

TEMPO: Temporal Enforcement via Mode-Separated Policy Optimization for Trustworthy LLM Backtesting

TEMPO trains LLMs via mode-separated reinforcement learning to eliminate post-cutoff knowledge leakage in temporal backtesting, cutting leakage to 0.6-3.7% while improving task performance up to 13%.

Zeyu Zhang, Bradly Stadie

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

EgoStream: A Diagnostic Benchmark for Streaming Episodic Memory in Egocentric Vision

EgoStream introduces a diagnostic benchmark for streaming egocentric episodic memory with 2,250 questions across seven cognitive dimensions and an Answer Validity Window, finding that current memory mechanisms achieve only around 45% accuracy while operating far below real-time requirements.

Rosario Forte, Giuseppe Lando, Antonino Furnari

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

HiFloat4 Format for Language Model Pre-training on Ascend NPUs

HiFloat4 enables stable FP4 LLM pretraining without stabilization stacks, achieving 1.55% relative loss versus 1.79% for MXFP4 and 2.00% for NVFP4 on Ascend NPUs.

Mehran Taghian Jazi, Yunke Peng, Xing Huang, Yao Wang and 21 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Structural Rationale Distillation via Reasoning Space Compression

D-RPC distills reasoning via reusable reasoning paths to stabilize supervision, improving student performance with fewer tokens.

Jialin Yang, Jiankun Wang, Jiajun Wu, Henry Leung and 2 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Agentick: A Unified Benchmark for General Sequential Decision-Making Agents

Agentick unifies RL and foundation model agent evaluation across 37 tasks, finding no dominant approach and substantial room for improvement.

Roger Creus Castanyer, Pablo Samuel Castro, Glen Berseth

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Looped Diffusion Language Models

Selective layer looping improves masked diffusion model training efficiency and reasoning performance via depth scaling without added parameters and flexible inference compute scaling.

Sanghyun Lee, Chunsan Hong, Seungryong Kim, Jonghyun Lee and 2 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Bounding Global and Local Compression Error of Signal Parameterizations

A framework predicts reconstruction error of compressive signal parameterizations via scaled differences between model predictions at different compression levels without ground truth. It yields non-asymptotic, signal-specific bounds that closely track global errors and local error heatmaps across i

Quang Luong Nhat Nguyen, Sara Fridovich-Keil

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Controllable User Simulation

Controllable user simulation is formalized as causal inference, proving supervised fine-tuning injects look-ahead bias causing geometric variance explosion and controllability collapse, with proposed mitigations restoring consistency and robust generalization.

Guy Tennenholtz, Ofer Meshi, Amir Globerson, Uri Shalit and 2 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

OpenSearch-VL: An Open Recipe for Frontier Multimodal Search Agents

OpenSearch-VL introduces an open-source recipe training multimodal deep search agents via curated data, diverse tools, and multi-turn fatal-aware GRPO, achieving over 10-point benchmark gains comparable to proprietary models.

Shuang Chen, Kaituo Feng, Hangting Chen, Wenxuan Huang and 6 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 57 on Hugging Face · Code ★ 289

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Useful Memories Become Faulty When Continuously Updated by LLMs

LLM-updated agent memories degrade with repeated consolidation, often dropping below baselines; retaining raw episodic traces doubles accuracy versus forced consolidation.

Dylan Zhang, Yanshan Lin, Zhengkun Wu, Yihang Sun and 3 more

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 18 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Temporal Backtracking Search for Test-time Generative Video Reasoning

Temporal Backtracking Search improves video reasoning by searching over the temporal axis and restarting from verified prefixes rather than resampling from scratch, achieving 22.7% versus 0.7% best-of-N out-of-distribution.

SeJoon Jun, Zheng Ding, Huangyuan Su, Weirui Ye and 1 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Selectivity and Shape in the Design of Forward-Forward Goodness Functions

Goodness functions for the Forward-Forward algorithm must sense activity shape rather than energy, and selective and burstiness-based alternatives improve accuracy by up to 32.6 percentage points over sum-of-squares.

Talha Rüzgar Akkuş, Şuayp T Kocabay, Kamer A Yuksel, Hassan Sawaf

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Reporting Practice Matters: The Impact of Reference Choice on Chest X-ray Report Evaluation

Evaluation metrics for AI radiology reports are highly sensitive to reference reporting style, altering model rankings and revealing poor clinical interpretation decoupling.

Daniel P Jeong, Charles Q Li, Hossein Hosseiny, Nitya M Bhalla and 4 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Better Source, Better Flow: Learning Condition-Dependent Source Distribution for Flow Matching

Condition-dependent source distributions for flow matching improve text-to-image generation via variance regularization and directional alignment, accelerating convergence up to 3x in FID.

Junwan Kim, Jiho Park, Seonghu Jeon, Seungryong Kim

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

AmaraSpatial-10K: A Spatially and Semantically Aligned 3D Dataset for Spatial Computing and Embodied AI

AmaraSpatial-10K is a 10,000 synthetic 3D asset dataset optimized for deployment, achieving 3.4x CLIP recall over Objaverse and 99.1% physics stability.

Mohammadsadegh Salehi, Alexander J Perkins, Igor P Maurell, Ashkan Dabbagh and 1 more

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026 · ▲ 3 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Multi-view Relational Distillation for Spatial Reasoning with Vision-Language Models

Multi-view relational distillation improves vision-language model spatial reasoning by distilling cross-view patch similarities rather than features, preserving language alignment with minimal overhead.

Kiet Nguyen, Hanbo Shim, Jinwoo Kim, Seunghoon Hong

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Forecasting Downstream Performance of LLMs With Proxy Metrics

Aggregating token-level statistics over expert solutions yields proxy metrics that outperform loss-based baselines for model selection, data selection, and training-time forecasting.

Arkil Patel, Siva Reddy, Marius Mosbach, Dzmitry Bahdanau

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 12 on Hugging Face · Code ★ 11

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

PEARL: Solver-in-the-Loop Interactive Optimization Modeling from Natural Language

PEARL integrates solvers into an interactive optimization modeling loop to iteratively revise formulations using execution feedback, substantially boosting verified solve rates and enabling a small model to outperform a much larger baseline.

Hongliang Lu, Zhong Li, Yuxuan Chen, Lan Yuan and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Otter Weather: Skillful and computationally-efficient medium-range weather forecasting

Otter Weather achieves state-of-the-art skill with minimal compute, outperforming NWP and frontier AI weather models using under 3.5 A100-days.

Cristiana Diaconu, Jonas Scholz, Aliaksandra Shysheya, Stratis Markou and 3 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Don’t Let Gains FADE: Breaking Down Policy Gradient Weights in RL

A framework decomposes RL advantage functions into gradient mass axes, showing trade-offs shift during training and motivating FADE, which adapts weights dynamically to accelerate convergence and improve accuracy-diversity trade-offs.

Juliette Decugis, Sean O&amp;#x27;Brien, Francis Bach, Gabriel Synnaeve and 1 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Beyond Interpretability: When, Why, and How Sparse Autoencoders Enable Label-Free Visual Steering

Visual Sparse Steering trains sparse autoencoders on frozen CLIP activations to build label-free steering vectors that improve zero-shot classification by up to 4.12 percent via centroid-deviation steering with reconstruction-error gating.

Gerasimos Chatzoudis, Zhuowei Li, Gemma Moran, Hao Wang and 1 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Learning Rate Matters: Vanilla LoRA May Suffice for LLM Fine-tuning

Vanilla LoRA matches variant performance within 1-2% when learning rates are tuned, and differing optimal rates stem from Hessian eigenvalue variations.

Yu-Ang Lee, Ching-Yun Ko, Pin-Yu Chen, Mi-Yen Yeh

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 7 on Hugging Face · Code ★ 13

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Active Flow Expansion for Out-of-Distribution Discovery: from Theory to Molecules

Active Flow Expansion uses verifier-guided active exploration to grow a flow model's generable set, yielding theoretical guarantees and superior out-of-distribution molecule and protein design.

Riccardo De Santi, Bruce D Lee, Cristian Jensen, Kimon Protopapas and 5 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

CAREBench: Evaluating LLMs' Emotion Understanding by Assessing Cognitive Appraisal Reasoning

CAREBench evaluates LLM emotion understanding via appraisal reasoning chains, finding stronger models surpass humans on some tasks but lack reasoning and positive emotion recognition.

ZHAOYUE SUN, Hainiu Xu, Andero Uusberg, James Gross and 2 more

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

When Parallelism Pays Off: Cohesion-Aware Task Partitioning for Multi-Agent Coding

Co-Coder formalizes multi-agent coding as graph partitioning to balance parallel speedups against communication overhead, improving pass rates by 14% and cutting costs 35% on dense repositories.

Xu Yang, Lunyiu Nie, Ethan Chandra, Stanislav Gannutin and 2 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Post-hoc Selective Classification for Reliable Synthetic Image Detection

ReSIDe applies post-hoc selective classification to synthetic image detectors by aggregating layer-wise confidence scores via preference optimization, reducing AURC by up to 69.55% under covariate shift.

Kaixiang Zheng, Jacob Seidman

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

The Compliance Trap: Diagnosing How AI Agents Consume Conflicting Memory

Proposed E-P-R framework diagnoses AI agents consuming conflicting memory via entry-propagation-recovery, finding a compliance trap where early adoption collapses success.

Yixiong Chen, Xinyi Bai, Alan Yuille

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Trust, but Don’t Verify: Epistemic Blind Spots in LLM Source Evaluation

LLMs detect fabricated statistics in isolation but ignore numeric validity during multi-source synthesis, weighing sources by analytical register rather than accuracy.

Rohan N Pradhan, Steve Goley

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

POLAR-Bench: A Diagnostic Benchmark for Privacy-Utility Trade-offs in LLM Agents

POLAR-Bench evaluates LLM agent privacy-utility trade-offs via adversarial third-party probing across 10 domains, finding frontier models block over 99% of protected attributes while smaller open-weight models leak over half.

Qiaoyuan ZHENG, yiqu yang, Qi Gao, Imanol Schlag

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Learn from your own latents and not from tokens: A sample-complexity theory

Latent prediction learns hierarchical latent trees with samples constant in depth L, exponentially more efficient than token-level self-supervision, making explicit multi-scale stacking largely redundant.

Daniel Korchinski, Alessandro Favero, Matthieu Wyart

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 3 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

MURPHY: Feedback-Aware GRPO with Retrospective Credit Assignment for Multi-Turn Code Generation

MURPHY extends GRPO to multi-turn code generation via feedback-conditioned rollout trees with retrospective credit assignment, achieving up to 6% absolute pass@1 gains over prior methods.

Chanakya Ekbote, Vijay Lingam, Sujay Sanghavi, Luke Huan and 3 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

AutoScientists: Self-Organizing Agent Teams for Long-Running Scientific Experimentation

AutoScientists is a decentralized AI team that self-organizes around promising hypotheses, critiques proposals, and shares failures to improve long-running scientific experiments across biomedical, language model, and protein tasks.

Shanghua Gao, Ada Fang, Marinka Zitnik

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 9 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

CELEUS: Certifiable and Efficient LLM Evaluation via E-Processes

CELEUS uses E-processes with uncertainty-guided sampling and surrogate approximations to provide anytime-valid confidence intervals for LLM evaluation, cutting required samples by 54-62%.

Zhijian Zhou, Zesheng Ye, Zhaorun Chen, Bo Li and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

SARL: Label-Free Reinforcement Learning by Rewarding Reasoning Topology

SARL improves reasoning via label-free reinforcement learning that rewards reasoning topology over outcomes, outperforming supervised and preference-based methods on math and open-ended tasks with more stable training.

Yifan Wang, Bolian Li, David Cho, Ruqi Zhang and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Direction-Aware Offline-to-Online Learning in Linear Contextual Bandits

A directional bias certificate enables Ellipsoidal-MINUCB to safely exploit offline data in linear contextual bandits, reducing regret when low-bias directions align with historical coverage.

Zean Han, Ruihan Lin, Zezhen Ding, Jiheng Zhang

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

PhysGuard: Fisher-Guided Gradient Projection for Sim-to-Real Neural PDE Surrogates

PhysGuard uses Fisher-guided gradient projection to adapt neural PDE surrogates to real data while preserving physics-critical parameters, cutting low-frequency error by up to 32% under severe domain shift.

Changjian Zhou, Junfeng Fang, Negin Yousefpour, peng wu and 2 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Beyond Worst-Case Coreset Bounds for $k$-Clustering via Determinantal Sampling

Determinantal sampling builds smaller k-clustering coresets with sub-quadratic ε dependence under mild data assumptions, breaking worst-case bounds.

Diptarka Chakraborty, Satyaki Mukherjee, Gaurav Vallabhdas Revankar, Hoang Son Tran

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Learning Visual Feature-Based World Models via Residual Latent Action

Residual Latent Action predicts visual feature dynamics via flow matching, outperforming diffusion world models with orders-of-magnitude faster inference and enabling offline robot learning from videos.

Xinyu Zhang, Zhengtong Xu, Yutian Tao, Yeping Wang and 2 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 3 on Hugging Face · Code ★ 47

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Knowledge-Graph Paths as Intermediate Supervision for Self-Evolving Search Agents

Knowledge-graph paths provide intermediate supervision for self-evolving search agents, improving question validity via relational context and solver rewards via waypoint coverage, boosting multi-hop QA across benchmarks.

Huyu Wu, Jun Liu, Xiaochi Wei, Yan Gao and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 4/5
medium 9/10
strict 1/5
86%Must read
?Must readVote to see the score

BSO: Safety Alignment Is Density Ratio Matching

BSO recasts safety alignment as density ratio matching via Bregman divergence minimization, yielding a single-stage loss that improves the safety-helpfulness trade-off without auxiliary models.

Tien-Phat Nguyen, Truong Nguyen, Thin Nguyen, Duy M. H. Nguyen and 2 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 4/5
medium 8/10
strict 2/5
86%Must read
?Must readVote to see the score

Few Channels Draw The Whole Picture: Revealing Massive Activations in Diffusion Transformers

A small subset of hidden-state channels in diffusion transformers drives image semantics, spatial structure, and prompt transfer without training.

Evelyn Turri, Davide Bucciarelli, Sara Sarto, Lorenzo Baraldi and 1 more

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 2/5
86%Must read
?Must readVote to see the score

When Guessing is Rewarded: Rethinking Language Model Evaluation with Distributional Uncertainty Scoring

A distributional uncertainty metric distinguishes harmful overconfidence from abstention, revealing negative scores across half of benchmarks and widespread model hallucination.

Tom Burns

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 4/5
medium 9/10
strict 1/5
86%Must read
?Must readVote to see the score

DiagnosticIQ: A Benchmark for LLM-Based Industrial Maintenance Action Recommendation from Symbolic Rules

DiagnosticIQ benchmarks LLM recommendation of industrial maintenance actions from symbolic rules across 6,690 questions, finding frontier models match human experts but break under structural perturbation due to calibration failures rather than capability gaps.

Devin Y De Silva, Dhaval Patel, Christodoulos Constantinides, Shuxin Lin and 7 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 6 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 2/5
86%Must read
?Must readVote to see the score

Theory of Mind and Persuasion Beyond Conversation: Assessing the Capacity of LLMs to Induce Belief States via Planning and Action

LLMs evaluated on Non-Conversational Planning ToM via object manipulation to induce belief states; GPT-5 achieved ~80% success, outperforming humans but remaining less robust, with all models better at inducing true than false beliefs.

Ben Slater, Lucy G Cheke, John Burden, Winnie Street

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 2/5
86%Must read
?Must readVote to see the score

SWE-Protégé: Learning to Selectively Collaborate With an Expert Unlocks Small Language Models as Software Engineering Agents

SWE-Protégé trains small language models to selectively seek expert guidance and avoid looping, achieving 42.4% Pass@1 on SWE-bench Verified with minimal expert use.

Patrick Tser Jern Kon, Archana Pradeep, Ang Chen, Alex Ellis and 4 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 2 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 2/5
86%Must read
?Must readVote to see the score

VistaQA: Benchmarking Joint Visual Question Answering and Pixel-Level Evidence

VistaQA benchmarks joint visual question answering and pixel-level evidence grounding across 1,157 expert-curated samples, revealing state-of-the-art models achieve limited alignment between answers and visual evidence.

Mozhgan Nasr Azadani, Yimu Wang, Yongpeng Zhu, Lihong Chen and 4 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 2/5
86%Must read
?Must readVote to see the score

Offline Reinforcement Learning for Plasma Control in Nuclear Fusion: Codebase and Benchmark

RL4F introduces an offline RL benchmark for tokamak plasma control using DIII-D dynamics, finding model-based methods perform best but no method dominates all tasks.

YANG FU, Haomin Bao, Rohit Sonker, Xiaoyan Hu and 3 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 2/5
86%Must read
?Must readVote to see the score

DiscoLoop: Looping Discrete Embeddings and Continuous Hidden States for Multi-hop Reasoning

DiscoLoop combines discrete embeddings and continuous hidden states in looping transformers to fix representational misalignment, enabling near-perfect multi-hop reasoning with faster training and stronger pretraining performance.

Hengyu Fu, Tianyu Guo, Zixuan Wang, Hanlin Zhu and 4 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 4/5
medium 8/10
strict 2/5
86%Must read
?Must readVote to see the score

End-to-End Training for Unified Tokenization and Latent Denoising

UNITE unifies tokenization and latent diffusion via a shared generative encoder, enabling single-stage joint training from scratch without adversarial losses or pretrained encoders to reach near state-of-the-art FID scores.

Shivam Duggal, Xingjian Bai, Zongze Wu, Richard Zhang and 4 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 4/5
medium 8/10
strict 2/5
86%Must read
?Must readVote to see the score

PAMod: Modeling Cyclical Shifts via Phase-Amplitude Modulation for Non-stationary Time Series Forecasting

PAMod models cyclical non-stationary shifts via phase-amplitude modulation in normalized space to achieve state-of-the-art forecasting with lower cost and broad plug-and-play gains.

Yingbo Zhou, Yutong Ye, Shuhao Li, Rui Qian and 4 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 1/5
86%Must read
?Must readVote to see the score

Revealing Epistemic Uncertainty in MLLMs via Causal-Invariant Masking

Causal-Invariant Masking decomposes MLLM uncertainty via semantic divergence to capture epistemic limitations, and Expected Embedding Drift accelerates quantification by nearly 50%.

Haoyang Luo, Linwei Tao, Jie Gui, Xinghao Chen and 3 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 0/5
86%Must read
?Must readVote to see the score

LoRaQ: Optimized Low Rank Approximation for 4-bit Quantization

LoRaQ uses data-free optimization to quantize low-rank branches for 4-bit diffusion transformers, outperforming high-precision methods at equal overhead.

Yann Bouquet, Alireza Khodamoradi, Sophie Y Shen, Kristof Denolf and 1 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 1/5
86%Must read
?Must readVote to see the score

The Illusion of Multi-Agent Advantage

Automatic multi-agent systems consistently underperform single-agent chain-of-thought self-consistency despite up to 10x cost, revealing automated architectures suffer from bloat and misaligned complexity rather than true multi-agent benefits.

Prathyusha Jwalapuram, Hehai Lin, Chuyuan Li, Fangkai Jiao and 6 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 4/5
medium 9/10
strict 1/5
86%Must read
?Must readVote to see the score

EvoMemBench: Benchmarking Agent Memory from a Self-Evolving Perspective

EvoMemBench benchmarks LLM agent memory via self-evolving scope and content axes, finding no universal memory method and that long-context baselines remain competitive.

Yuyao Wang, Zhongjian Zhang, Mo Chi, Kaichi Yu and 6 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 4/5
medium 7/10
strict 3/5
86%Must read
?Must readVote to see the score

Explaining and Preventing Alignment Collapse in Iterative RLHF

Iterative RLHF ignores policy influence on reward-model updates, causing alignment collapse via exploited blind spots; foresighted optimization restores this term to prevent collapse.

Etienne Gauthier, Francis Bach, Michael Jordan

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 2/5
86%Must read
?Must readVote to see the score

Making Open-Source Text LLM Watermarks Durable Against Merging

Merge-Adversarial Training embeds durable text watermarks into open-source LLM weights via adversarial distillation, maintaining high detection rates after model merging while preserving capabilities.

Luisa Scharff, Thibaud Gloaguen, Robin Staab, Martin Vechev

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 2/5
86%Must read
?Must readVote to see the score

Aligning Forest and Trees in Images & Long Captions for Visually Grounded Understanding

CAFT learns local text-region alignments before global image-text matching via hierarchical encoders, achieving state-of-the-art long-caption retrieval without region supervision.

Byeongju Woo, Zilin Wang, Byeonghyun Pak, Sangwoo Mo and 1 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 0/5
86%Must read
?Must readVote to see the score

B-CALM: Bias-Limited Bayesian Borrowing for RCT-Anchored Treatment Effects under Covariate Mismatch

B-CALM borrows observational data via latent-state alignment and comparative-bias priors to estimate RCT-anchored treatment effects with bounded bias and near-nominal coverage.

Amir Asiaee, Samhita Pal

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 3/5
medium 8/10
strict 3/5
86%Must read
?Must readVote to see the score

G$^2$TR: Generation-Guided Visual Token Reduction for Separate-Encoder Unified Multimodal Models

G²TR uses generation-branch signals to reduce visual tokens in unified multimodal models, cutting prefill computation by 1.94× while preserving reasoning and editing performance.

Junxian Li, Kai Liu, Zizhong Ding, Zhixin Wang and 3 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 0/5
86%Must read
?Must readVote to see the score

Beyond Steering Vector: Flow-based Activation Steering for Inference-Time Intervention

FLAS learns a concept-conditioned flow field for multi-step activation steering that outperforms prompting on AxBench without per-concept tuning.

Zehao Jin, Ruixuan Deng, Junran Wang, Xinjie Shen and 1 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 4/5
medium 8/10
strict 2/5
86%Must read
?Must readVote to see the score

Trajectory as the Teacher: Few-Step Discrete Flow Matching via Energy-Navigated Distillation

Trajectory-Shaped Discrete Flow Matching guides discrete flow matching training via an energy-based midpoint evaluator, letting small students outperform large teachers with 32% lower perplexity at 128x speed.

Amin Karimi Monsefi, Dominic Culver, Nikhil Bhendawade, Manuel R Ciosici and 2 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 3 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Neural Proposals, Symbolic Guarantees: Neuro-Symbolic Graph Generative Modeling

A neuro-symbolic framework pairs neural graph proposals with symbolic SMT solvers for hard-constraint satisfaction, achieving over 95% in-distribution and 64, 86% zero-shot rule compliance on the MolSAT benchmark.

Chuqin Geng, Li Zhang, Mark Zhang, Zhaoyue(Rebecca) Wang and 2 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

How to Scale Mixture-of-Experts: From muP to the Maximally Scale-Stable Parameterization

Researchers derive maximally scale-stable parameterizations for Mixture-of-Experts via dynamical mean-field theory, yielding robust learning-rate transfer and monotonic scaling gains across regimes.

Leena Chennuru Vankadara, Moritz Haas, Luke Hayward, Sebastian Bordt and 1 more

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026 · ▲ 1 on Hugging Face · Code ★ 4

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Aligning Language Model Benchmarks with Pairwise Preferences

Reweighting benchmark items aligns static language model benchmarks with downstream pairwise preferences to rank unseen models, using as few as 20 well-chosen models.

Marco Gutierrez, Xinyi Leng, Hannah Chen, Jonathan Richard Schwarz and 2 more

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Why Jailbreaks Succeed in Diffusion Language Models: An Energy Landscape Analysis

Safety alignment shapes diffusion language models' denoising energy barriers, and three complementary kinetic-energy signals detect jailbreaks by forcing attacks to reveal intent or expend detectable cross-barrier energy.

Thong Bach, Dung Nguyen, Thao Le, Truyen Tran

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Bandits via Additive Quantized Representations

Residual Quantization maps contexts to discrete additive codes enabling nonlinear contextual bandits with strictly bounded memory, beating linear variants on 11 of 13 datasets and matching heavy retrained baselines with up to 1000x less memory.

Ami Tavory, Noam Touitou, Tal Sarig, Frank Cheng and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

NEST: Nascent Encoded Steganographic Thoughts

Frontier models can encode hidden reasoning but fail to combine reasoning and steganographic embedding in one pass, leaving monitor evasion via hidden chain-of-thought unachievable.

Artem Karpov

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

DriveHierarchy: A Benchmark for Diagnosing VLM Driving Capabilities from Open-Loop Understanding to Closed-Loop Execution

DriveHierarchy hierarchically benchmarks VLM driving across four ranks from perception to closed-loop execution, linking open-loop understanding to embodied performance for diagnosing 15 models.

Chengkai Xu, Jiaqi Liu, Yicheng Guo, Peng Hang and 1 more

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Exact Posterior Score Estimation for Solving Linear Inverse Problems

Exact posterior score estimation derives closed-form posterior scores for linear Gaussian inverse problems, enabling efficient training and sampling that outperforms baselines with far fewer evaluations.

Abbas Mammadov, Ozgur Kara, Kaan Oktay, Iskander Azangulov and 4 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

CAST: Causal Anchored Simplex Transport for Distribution-Valued Time Series

CAST is a causal successor operator for distribution-valued time series that preserves the simplex via transport, avoiding transition-kernel aliasing to achieve top ranks across 11 benchmarks.

Jiecheng Lu, Jieqi Di, Runhua Wu, Yuwei Zhou

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

What Gets Measured Gets Managed: Sign-aware Recommendation Needs Sign-aware Evaluation

Sign-aware recommender systems embed valence but rank blindly, hidden by metrics that ignore disliked items; proposed signed metrics expose poor valence protection and provide trainable fixes.

Minchan Kim, Jungmin Hwang, Hyunwoo Park

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Mixture-Trained Merging for Unified Multi-Objective Models

Mixture-Trained Merging trains multi-objective branches on biased data mixtures to enable compatible weight-space merging, outperforming naive merging while preserving distinct capabilities.

SeongHyeon Kim, Chaeyun Jang, Seungyoo Lee, Jiyeon Ham and 3 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Platonic Task Arithmetic

Universal Task Descriptors represent tasks as architecture-independent matrices to enable cross-model arithmetic, retaining 74, 80% of within-model gains across six families.

Junghwan Park, Woojin Cho

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Probability-Conserving Flow Guidance

Guidance decomposes into divergence and score-parallel terms via the continuity equation; AdaMaG bounds both to improve flow-based generation realism and reduce hallucinations without added cost.

Parsa Esmati, Junha Hyung, Amirhossein Dadashzadeh, Jaegul Choo and 1 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Manifold Drift in Flow Preference Optimization: A Root Cause of Reward Hacking

Manifold drift pushes flow preference optimization off the data manifold via terminal displacement normal components; ThermoDPO-weighted improves strict score and image metrics over FlowDPO.

Yansen Han, Shengyi Liao, Yuanxing Zhang, Pengfei Wan and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Default Feature Representations of the Cognitive Map

Default Feature Representations parameterize predictive cognitive maps via a fixed feature basis and an adaptive environment operator, enabling rapid sample-based replanning and local grid-cell remapping.

Armin Bazarjani, Payam Piray

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

SAGE: Mitigating Long-Horizon Reasoning Biases via Topological Guidance

SAGE mitigates long-horizon reasoning biases via symbolic closure analysis, using algebraic sparsification and hyperbolic guidance to suppress spurious branching and compounding errors, achieving up to 8-fold gains on sparse-reward benchmarks.

Xinyue Zeng, Jiawei zhang, Yujun Yan, Dawei Zhou

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 8 on Hugging Face · Code

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Outlier-robust Diffusion Posterior Sampling for Bayesian Inverse Problems

Robust diffusion posterior sampling mitigates outlier-induced likelihood misspecification in diffusion-based Bayesian inverse problems with provable stability and consistent empirical gains.

Yiming Yang, Xiaoyuan Cheng, Yi He, Kaiyu Li and 2 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Structure-aware Reinforcement Learning for Protein Directed Evolution

StructEvo uses structure-aware reinforcement learning with delta-structure fusion and hierarchical actions to outperform state-of-the-art protein directed evolution methods by up to 16.3%.

Zikun Nie, Suyuan Zhao, Yizhen Luo, Siqi Fan and 1 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

A Principled Self-Referenced Early Stopping Approach for Deep Image Prior

Proposed pseudo self-referenced early stopping for Deep Image Prior uses constructed image pairs to detect overfitting, outperforming existing methods across inverse imaging problems without requiring noise level estimates.

Chaoyan Huang, Cheng-Han Huang, Ismail Alkhouri, Rongrong Wang

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Code2World: A GUI World Model via Renderable Code Generation

Code2World uses renderable code generation for GUI world modeling, achieving top next-UI prediction and boosting Android navigation success by up to 9.5%.

Yuhao Zheng, Li&amp;#x27;an Zhong, Yi Wang, Rui Dai and 5 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 186 on Hugging Face · Code ★ 312

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Gender Artifacts from Art History to Text-to-Image Generation

StyleGender analyzes gender artifacts across 19 art styles and text-to-image outputs, finding generative models amplify gender biases beyond historical sources.

Piera Riccio, Miriam Doh, Benedikt Höltgen, Noa Garcia and 1 more

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Unify-Agent: A Unified Multimodal Agent for World-Grounded Image Synthesis

Unify-Agent reframes image synthesis as an agent pipeline with search and recaptioning, improving generation of long-tail factual concepts via 143K curated trajectories.

Shuang Chen, Quanxin Shou, Hangting Chen, Yucheng Zhou and 11 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 44 on Hugging Face · Code ★ 93

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

ClothTransformer: Unified Latent-Space Transformers for Scalable Cloth Simulation

ClothTransformer reformulates cloth simulation as autoregressive latent-space sequence modeling to unify body-driven garments, robotic manipulation, and collisions with 4-9x lower error.

Yu Zhang, YIDI SHAO, Wenqi Ouyang, Yushi LAN and 4 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

LiBrA-Net: Lie-Algebraic Bilateral Affine Fields for Real-Time 4K Video Dehazing

LiBrA-Net predicts low-resolution bilateral affine grids fused via Lie-algebraic regularization for real-time 4K video dehazing, and introduces the UHV-4K benchmark.

Yongcong Wang, Chengchao Shen, Guangwei Gao, Wei Wang and 4 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

AEM: Adaptive Entropy Modulation for Multi-Turn Agentic Reinforcement Learning

AEM adaptively modulates response-level entropy dynamics for supervision-free credit assignment in multi-turn agent RL, improving exploration-exploitation trade-offs and consistently boosting strong baselines across ALFWorld, WebShop, and SWE-bench-Verified.

Haotian Zhao, Songlin Zhou, Yuxin Zhang, Stephen S Yau and 8 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 21 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

CellMSA: Context Modeling for Single-Cell Representation Learning

CellMSA improves single-cell representation learning by modeling cross-batch and cross-cell-type context via MSA-inspired gene-pair representations, outperforming existing methods across benchmarks.

Suyuan Zhao, Minghao Liu, Yizhen Luo, Zaiqing Nie

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

CoDMD: Copula-aware Distribution Matching Distillation for Fast Video Generation

CoDMD adds a copula-aware relational regularizer to distribution matching distillation that improves few-step video generation, achieving 84.46/84.87 VBench scores at 4 steps with ~25× speedup.

Wenhu Zhang, Kun Cheng, Changyuan Wang, Shiyao Li and 6 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

WildBox: A Dataset and Benchmark for Aerial Monocular 3D Detection of African Savanna Wildlife

WildBox provides aerial monocular 3D wildlife annotations and benchmarks showing zero-shot 3D detection collapses to zero, with fine-tuning reaching 13.17 AP3D and depth as the dominant failure mode.

Vandita Shukla, Kilian Meier, Lucie Laporte-Devylder, Camille R Saint-Jean and 5 more

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Counterfactual Rollout Replay: Forkable Environments as Free Process Rewards for Software Engineering Agents

Counterfactual Rollout Replay uses forkable environments to compute step-level return contrasts without human process labels, improving 14B SWE agent pass@1 by 5.0 points over outcome-only reinforcement learning.

Yuanhao li, Hongbo Wang, Xuhong Chen, Yiming Cao and 1 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

The Key to Going Linear: Analysis-Driven Transformer Linearization

Analysis-driven transformer linearization isolates state update design to show delta-style networks outperform gated accumulation via key-dependent rank-1 projections, reducing approximation errors with sink tokens and cache routing to match adaptive caching at 32B scale.

Anna Kuzina, Paul Whatmough, Babak Ehteshami Bejnordi

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

RustMizan: A Compilable, Contamination-Aware Benchmarking Framework for Rust Vulnerabilities

RustMizan provides compilable Rust vulnerability benchmarks with mutation-based contamination tests, finding frontier LLM agents achieve 56-65% binary detection but ~20% line-localization F1 that adversarial cues reduce by 27%.

Tarek Elsayed, Shiping Yang, Eunsong Koh, Sanika Goyal and 12 more

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Playing ZendoWorld: Challenging AI Agents on Active Visual Concept Induction

ZendoWorld evaluates AI agents on active visual rule induction and finds high prediction accuracy does not imply rule recovery, with VLM agents proposing near-uninformative experiments.

Sophia Koehler, Antonia Wüst, Inga Ibs, Top Piriyakulkij and 4 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

From I/O to Code with Discovery Agent

DIO-Agent frames IO2Code as evolutionary search guided by execution errors and a simplicity-biased mutation prior, outperforming baselines on IO2CodeBench.

Yihong Dong, Jiaru Qian, Haoran Zhang, Peixu Wang and 6 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

SLOPE: Optimistic Potential Landscape Shaping for Model-based Reinforcement Learning

SLOPE constructs optimistic potential landscapes via distributional regression to amplify sparse success signals and guide planning, outperforming baselines across sparse reward benchmarks.

Yao-Hui Li, Zeyu Wang, Xin Li, Wei Pang and 6 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

ConnectomeBench2: A Unified Benchmark for Automated Connectomic Proofreading

ConnectomeBench2 unifies multi-species connectomic proofreading data, and a vision transformer trained on it achieves human-level split and merge error correction across species.

Jeff Brown, Tim Farkas, Gleb Razgar, Edward Boyden

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Monroe: A Molecular Foundation Model for In-context Probabilistic Inference

Monroe is a molecular foundation model pre-trained on 81 million molecules that uses in-context TabPFN prediction to achieve state-of-the-art bioassay activity prediction, especially on activity cliffs.

Blazej Banaszewski, Andrew Fitzgibbon

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Multi-agent Collaboration with State Management

STORM mediates multi-agent shared workspace edits to detect and resolve conflicts at write time, outperforming isolated worktree baselines on Commit0 and PaperBench.

Mengyang Liu, Taozhi Chen, Zhenhua Xu, Xue Jiang and 1 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

BusterX: MLLM-Powered AI-Generated Video Forgery Detection and Explanation

BusterX introduces GenBuster-200K, GenBuster-Bench, and an MLLM baseline that detects AI-generated video via reasoning chains, outperforming leading models in accuracy and explanation quality.

Haiquan Wen, Yiwei He, Zhenglin Huang, Tianxiao Li and 6 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · Code ★ 51

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score
NeurIPS 2026ColumbiaDeep RL

Policy Optimization in Hybrid Discrete-Continuous Action Spaces via Mixed Gradients

Hybrid Policy Optimization combines pathwise and score-function gradients via simulator backpropagation to train policies in hybrid action spaces with unbiased mixed gradients, outperforming PPO on high-dimensional control tasks.

Matias Alvo, Daniel Russo, Yashodhan Kanoria

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Outcome-Based RL Provably Leads Transformers to Reason, but Only With the Right Data

Outcome-based RL provably teaches single-layer transformers iterative graph traversal via chain-of-thought, but only with sufficient simple training examples.

Yuval Ran-Milo, ‪Yotam Alexander‬‏, Shahar Mendel, Nadav Cohen

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Learning to Evolve Scenes: Reasoning about Human Activities with Scene Graphs

SG-Ego extends Ego4D with time-evolving scene graphs and GLEN reasons over them to model activity-driven scene dynamics, outperforming raw video and MLLM baselines on retrieval and long-horizon reasoning.

Francesca Pistilli, Simone Alberto Peirone, Giuseppe Averta

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Cat-DPO: Category-Adaptive Safety Alignment

Cat-DPO applies per-category adaptive safety margins to direct preference optimization, improving aggregate safety and reducing worst-category harm gaps across models.

Tiankai Yang, Yi Nian, Xinyuan Li, Ruiyao Xu and 5 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

EcoGym: Evaluating LLMs for Long-Horizon Plan-and-Execute in Interactive Economies

EcoGym benchmarks long-horizon LLM economic planning across open-source environments, revealing no single model dominates and exposing strategic and execution suboptimalities.

Xueyu Hu, Jinxiang Xia, Shengze Xu, Kangqi Song and 12 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 11 on Hugging Face · Code ★ 99

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

FAME: Forecasting Academic Impact via Continuous-Time Manifold Evolution

FAME forecasts academic impact via continuous-time manifold evolution, outperforming LLM evaluators in prospective forecasting and improving them via geometric signals.

Jianrong Ding, Jianyuan Zhong, Zhengyan Shi, Qiang Xu

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

OpenClawBench: Benchmarking Process-side Anomalies in Real-world Agent Execution Trajectories

OpenClawBench benchmarks process-side agent anomalies via 31,264 annotated trajectories, revealing 2,904 process failures among 31,135 oracle-passing executions.

Yibing Liu, Yangze Liu, Xiao-Long Yin, Bin Wang and 3 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

World–Value–Action Model: Implicit Planning for Vision–Language–Action Systems

WAV introduces a latent-space planning framework for vision-language-action models that predicts future states and evaluates trajectory values to enable efficient long-horizon decision-making.

Runze Li, Hongyin Zhang, Junxi Jin, Qixin Zeng and 4 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

CORP: Closed-Form One-shot Representation-Preserving Structured Pruning for Transformers

CORP uses closed-form ridge regression to recover representations and prune transformer structures without retraining, retaining 83.27% ImageNet accuracy at 50% sparsity.

Boxiang Zhang, Baijian Yang

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Hallucination as Commitment Failure: Larger LLMs Misfire Despite Knowing the Answer

Larger instruction-tuned LLMs increasingly hallucinate despite knowing correct answers because sharpening commitment disperses probability across surface forms rather than concentrating it.

Jewon Yeom, Jaewon Sok, Heejun Kim, Seonghyeon Park and 2 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

CASPIAN: Online Detection and Attribution of Cascade Attacks in LLM Multi-Agent Systems via Cross-Channel Causal Monitoring

CASPIAN detects cascade attacks in LLM multi-agent systems via online cross-channel causal monitoring, accurately identifying attack origins and propagation paths with sub-1% overhead.

Kavana Venkatesh, Jafar Isbarov, Saad Amin, Murat Kantarcioglu and 1 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Forced Deferral: Manipulating Routing Decisions in Multimodal LLM Cascades

Forced Deferral Attack uses adversarial image triggers to suppress weak-model confidence and force multimodal LLM cascades to route queries to strong models. It learns universal border triggers via temperature-flattened optimization, consistently increasing unintended strong-model usage across datas

Zhongye Liu, Yaopei Zeng, Yurui Chang, Lu Lin

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Perception Without Engagement: Dissecting the Causal Discovery Deficit in LMMs

ProCauEval reveals LMMs perceive video but ignore it for causal reasoning, and ADPO reduces textual shortcuts via negative teacher alignment.

Jiafeng Liang, Zhihao Zhu, Zihan Zhang, Baoqi Ren and 6 more

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

WorldVLN: Autoregressive World Action Model for Aerial Vision-Language Navigation

WorldVLN autoregressively predicts short-horizon world-state transitions to generate waypoint actions for aerial vision-language navigation, achieving over 12% success-rate gains and real-world drone transfer.

Baining Zhao, jiacheng xu, Weicheng Feng, Xin Zhang and 12 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

PULSE: Identifying Demonstration-Utility Features with Sparse Autoencoders

PULSE uses sparse autoencoders to identify internal features linked to demonstration utility and improves selection across classification, generation, and reasoning tasks.

Chenduo Hao, Chuanbao Gao, Pinjun Zeng, Jingze Zhu and 3 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

A Few Teacher Steps Go a Long Way: Cost-Efficient On-Policy Data Augmentation for Agent Post-Training

Few-step unfiltered teacher continuations at learner-induced contexts cost-efficiently outperform pure behavioral cloning and filtered long completions across agent benchmarks at matched budgets.

Junze Ye, Jiayi Cheng, Miao Lu, Michal Mankowski and 2 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Joint Treatment Effect Estimation from Incomplete Healthcare Data: Temporal Causal Normalizing Flows with LLM-driven Evolutionary MNAR Imputation

<|message_model|><|content_text|>A two-stage pipeline combines exact invertible counterfactual inference via DAG-constrained temporal normalizing flows with LLM-driven evolutionary MNAR imputation to estimate treatment effects from incomplete longitudinal EHRs. On synthetic benchmarks and Swiss diab

Olivia Jullian Parra, Sara Zoccheddu, David C Cerezo, Tom Forzy and 6 more

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

It Just Takes Two: Scaling Amortized Inference to Large Sets

A mean-pool DeepSet trained on pairs learns set encoders that generalize to arbitrary sizes, letting inference heads scale to thousands of observations with minimal compute.

Antoine Wehenkel, Michael Kagan, Lukas Heinrich, Chris Pollard

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

ArcMark: Distortion-Free Multi-Byte LLM Watermark via Optimal Transport

ArcMark embeds multiple bytes into LLM text without distorting next-token distributions by formulating distortion-free watermarking as channel coding and deriving its information-theoretic capacity. It reliably encodes several bytes into a few hundred tokens and outperforms competing multi-bit water

Atefeh Gilani, Sajani Vithana, Carol X Long, Oliver Kosut and 2 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

ViTeX-Bench: Benchmarking High-Fidelity Video Scene Text Editing

ViTeX-Bench introduces a 387-video benchmark and evaluation protocol for high-fidelity video scene text editing, finding that accuracy, temporal stability, and edit locality remain hard to balance together.

Xinghao Chen, Xiangbo Gao, Jiongze Yu, Yuheng Wu and 1 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

MultiTalk: Scaling Full-Duplex Speech Models to Long, Multi-Party, Bilingual Conversation

MultiTalk introduces 57.6k hours of synthetic multi-party bilingual dialogue data and MultiTalkBench for long-form full-duplex evaluation, training a model that sustains coherent extended multi-party English-Chinese conversation and outperforms open-source baselines.

Ke Wang, Houxing Ren, Zimu Lu, Yunqiao Yang and 3 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Leveraging Error Diversity in Group Rollouts for Reinforcement Learning

RLVR discards group error diversity, but shaping penalties by intra-group error diversity improves training; EDAS boosts DAPO by 6.29 points on math benchmarks.

Wenpu Liu, Yuqi Xu, Weichu Xie, Yongfu Zhu and 7 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

TerraVis: Towards Evaluation of World-Grounded Visual Consistency in Text-to-Image Generation via MLLM Workflows

TerraVis evaluates world-grounded visual consistency in generated images via MLLM workflows, correlating best with human judgments while revealing substantial failures in top models.

Shuai Fu, Jing Gu, Jian Zhou, Zicheng Duan and 2 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Leveraging Soft Prompts for Privacy Attacks in Federated Prompt Tuning

PromptMIA uses adversarial soft prompts to exploit federated prompt-tuning updates for highly effective membership inference attacks that bypass standard defenses.

Quan M Nguyen, Min-Seon Kim, Hoang M Ngo, Nghia Hoang and 2 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

AbsoluteDegradation: A Physics-Inspired Synthetic Film-Degradation Pipeline and Archival Film Restoration Benchmark

AbsoluteDegradation synthesizes realistic film degradations via physics-inspired modular pipelines and introduces a large-scale archival benchmark, showing improved real-world generalization and exposing current restoration failure modes.

Mikołaj Jastrzębski, Dawid Glinkowski, Dawid Zieliński, Daniel Borkowski and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

GLINT: Sparsely Gated Vision-Language Alignment for Fine-Grained Radiology Representations

GLINT introduces sparse gating and dense feature regularization to learn fine-grained radiology vision-language representations that outperform baselines on classification, grounding, and zero-shot 3D CT segmentation.

Jonggwon Park, Seongeun Lee, Junhyun Park, Hannah Yun and 5 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

RefineAny3D: Depth Refinement as Semantic Alignment for Monocular 3D Detection

RefineAny3D treats monocular 3D depth refinement as visual alignment via categorical vision-language action tokens, boosting detectors without numerical regression.

Zhihao Zhang, Gengwei Zhang, Tianlong Chen, Xiaoming Liu

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

ECG-Reasoning-Benchmark: A Benchmark for Evaluating Clinical Reasoning Capabilities in ECG Interpretation

A new benchmark reveals current multimodal AI fails at multi-step ECG reasoning, achieving near-zero completion in linking clinical criteria to visual signal evidence.

Jungwoo Oh, Hyunseung Chung, Junhee Lee, Min-Gyu Kim and 5 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 6 on Hugging Face · Code ★ 18

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Beyond RAG for Agent Memory: Retrieval by Decoupling and Aggregation

xMemory decouples agent memories into reusable components before aggregating them hierarchically, improving retrieval quality and token efficiency over flat RAG.

Zhanghao Hu, Qinglin Zhu, Runcong Zhao, Di Liang and 3 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 20 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

AlloSpatial: Agentic Harness Framework for Spatial Reasoning in Foundation Models

AlloSpatial is an agentic framework that converts egocentric observations into allocentric spatial priors via cognitive mapping and reasoning harnesses, improving spatial reasoning by 5%-18% and outperforming larger general-purpose models.

Shouwei Ruan, Bin Wang, Zhenyu Wu, Qihui Zhu and 4 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 4 on Hugging Face · Code ★ 21

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Hint Tuning: Less Data Makes Better Reasoners

Hint Tuning calibrates reasoning depth by using an instruct model as a difficulty probe, cutting tokens by 24-66% with 1K samples.

Siqi Fan, Minghao Li, Xiaoqian Ma, Xiusheng Huang and 5 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

TIDES: Implicit Time-Awareness in Selective State Space Models

TIDES moves input dependence from step size to the state matrix in selective SSMs, preserving physical time steps and per-token expressivity for irregular series, achieving state-of-the-art time-series results.

Taylan Soydan, Miguel Bessa, Dirk Mohr, Rui Barreira

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

When Less is More: The LLM Scaling Paradox in Context Compression

Under lossy context compression, larger compressors reduce reconstruction error but increase unfaithfulness via knowledge overwriting and semantic drift, violating scaling laws for faithful preservation.

Ruishan Guo, Yibing Liu, Guoxin Ma, Yan Wang and 5 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

xHC: Expanded Hyper-Connections

xHC expands Transformer hyper-connections beyond four streams via sparse updates and temporal augmentation, improving scaling efficiency. It boosts 18B MoE downstream scores by 4.0 points over mHC with lower compute and reduced memory traffic via xHC-Flash.

Xiangdong Zhang, Xiaohan Qin, Tuo Dai, Xiaoming Shi and 7 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 54 on Hugging Face · Code ★ 68

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

BitDance: Scaling Autoregressive Generative Models with Binary Tokens

BitDance is an autoregressive image generator that predicts binary visual tokens via a diffusion head and next-patch decoding, achieving state-of-the-art FID with far fewer parameters and much faster inference.

Yuang Ai, Jiaming Han, Shaobin Zhuang, Weijia Mao and 7 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 46 on Hugging Face · Code ★ 485

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Bayesian Preference Learning for Test-Time Steerable Reward Models

ICRM enables test-time steerable reward models via Bayesian variational inference over preferences, improving multi-objective alignment, calibration, and math reasoning.

Jiwoo Hong, Shao Tang, Zhipeng Wang

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

APM: Evaluating Style Personalization in LLMs with Arbitrary Preference Mappings

APM benchmark evaluates LLM style personalization via hidden arbitrary preference mappings, finding routing most reliable while RAG and soft prompts show limited gains.

Philipp Spohn, Leander Girrbach, Zeynep Akata

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

MAdam: Metric-Aware Multi-Objective Adam

MAdam removes Adam's weighting and geometric mismatches in multi-objective optimization via a preference-conditioned curvature preconditioner, consistently improving results across tasks.

Fengbei Liu, Rachit Saluja, Sunwoo Kwak, Ruibo Wang and 4 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Higher-Order Cell Tracking Transformer

HOCT is an edge-centric transformer that links cell detections across time via 3D geometric attention, achieving state-of-the-art tracking without pretrained encoders and reducing errors 59% with minimal annotations.

Jordão Bragantini, Ilan Theodoro, Loic A Royer

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Training Data Attribution in Diffusion Models via Mirrored Unlearning and Noise-Consistent Skew

MUCS improves diffusion model training data attribution via mirrored unlearning and noise-consistent skew, outperforming existing methods across datasets.

Joan Serrà, Dipam Goswami, Fabio Morreale, Wei-Hsiang Liao and 1 more

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

AOT-POT: Adaptive Operator Transformation for Large-Scale PDE Pre-training

AOT-POT adaptively transforms diverse PDE solution operators into simpler aligned forms via multi-stream aggregation and Sinkhorn mixing, achieving state-of-the-art pre-training accuracy with minimal parameters.

Qitan Lv, Hong Wang, Hao Zhongkai, Wen Wu and 4 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Training Transformers for KV-Cache Compressibility

KV-compressibility is a learnable property, so KV-CAT trains transformers via masked KV slots to yield representations more amenable to post-hoc compression without sacrificing quality.

Yoav Gelberg, Yam Eitan, Michael Bronstein, Yarin Gal and 1 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

CoRDS: Coreset-Based Representative and Diverse Selection for Streaming Video Understanding

CoRDS selects coreset subsets of key-value caches to cover accumulated visual history geometry, improving streaming video understanding with fixed memory budgets.

Ailar Mahdizadeh, Puria Azadi Moghadam, Muchen Li, Xiangteng He and 1 more

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Inverting the Bellman Equation: From $Q$-Values to World Models

Value-based agents trained on diverse reward functions implicitly encode world models, extractable via P-learning, with sufficient conditions for exact dynamics recovery and cross-goal generalization.

Alistair Letcher, Mattie Fellows, Alexander D. Goldie, Jonathan Richens and 2 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Distilling Sequential Computation in Transformer Language Models

A lightweight merge module replaces token spans with surrogate embeddings, cutting Transformer sequence lengths by up to 40% with minimal accuracy loss and no retraining.

Zixuan Lan, Jessica Yang, Yanhong Li, Karen Livescu and 1 more

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

A Locally Tokenized Generative Model for Robust Time-Series Watermarking

L-VQVAE locally tokenizes time series so each token depends on a bounded window, and LVQMark stabilizes watermark detection against post-editing attacks without sacrificing quality.

Dongbin Kim, Geonwoo Shin, Yujin Choi, Soyeon Park and 1 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

MedEvoEval: Evaluating Continual Evolution of Doctor Agents through Simulated Clinical Episodes

MedEvoEval evaluates doctor agents through simulated longitudinal clinical episodes to measure experience-driven improvement, resource use, and capability retention over time.

Hui Zhang

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Consilience for Verifier-Free Test-Time Scaling

Confidence-based verifier-free test-time scaling fails on complex tasks because high initial confidence signals no exploration; consilience selects rollouts by requiring low early but high final confidence, improving reasoning and coding.

Lecheng Kong, Like Hui, Haitao Mao, Luke Huan

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 2 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Economy of Minds: Emerging Multi-Agent Intelligence with Economic Interactions

A decentralized agent economy using auctions and economic selection emerges multi-step reasoning and outperforms monolithic baselines without centralized coordination.

Zhenting Qi, Ao Qu, Huangyuan Su, Chenyu Wang and 12 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 10 on Hugging Face · Code ★ 59

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

CRAFT: Counterfactual-to-Interactive Reinforcement Fine-Tuning for Driving Policies

CRAFT combines dense counterfactual advantages with grounded residual corrections to reduce variance and bias in closed-loop autonomous driving fine-tuning, achieving strong Bench2Drive gains.

Keyu Chen, Nanfei Ye, Yida Wang, Wenchao Sun and 3 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Controlling for Omitted Variable Bias in Deep Neural Networks

A control-variable method using generalized additive modeling and cross-fitted ridge refitting removes omitted-variable bias from deep networks, yielding unbiased predictions.

Manuel Pfeuffer, Roshan P Rane, Kerstin Ritter, Sonja Greven

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

ChainSpace: A Chained-Reasoning Paradigm for Spatial Intelligence

ChainSpace structures spatial reasoning as state-preserving multi-round chains to expose hidden failures and improve data-efficient training.

Xiaohan Zhang, Feng Gu, Xudong Rao, Xuhao Pan and 3 more

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Structure Over Scale: Learning Visual Reasoning from Pedagogical Video

SoSVQA extracts 10K pedagogically structured QA pairs from children's video to train VLMs via GRPO, yielding major reasoning gains on NExT-QA, Video-MME, and MotionBench that match proprietary systems despite far less training data.

Bishoy Galoaa, Xiangyu Bai, Sarah Ostadabbas

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

MVVBench: Benchmarking 4D Reasoning in Vision-Language Models

MVVBench benchmarks 4D multi-view video reasoning requiring joint cross-view temporal integration, finding vision-language models fail due to temporal mis-localization and cross-view identity breaks, with inference-time scaffolding and reinforcement learning yielding substantial gains.

Hyungjin Chung, Byeongjun Park, Joonseok Lee, Hojun Kim and 2 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Measuring and Mitigating the Distributional Gap Between Real and Simulated User Behaviors

A clustering-based divergence method measures gaps between real and simulated user behaviors, finding large, family-dependent discrepancies reducible by combining complementary simulators.

Shuhaib Mehri, Philippe Laban, Sumuk Shashidhar, Marwa Abdulhai and 3 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

NORA: Evaluating Grounded Reasonableness in Visual First-person Normative Action Reasoning

NoRA evaluates visual first-person normative reasoning by requiring models to generate actions with fact-reason-action support graphs, revealing current VLMs struggle to bind correct justifications to actions.

Sichao Li, Sai Ma, Zhuang Li, Daniel Kilov and 2 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Curvature Beyond Positivity: Greedy Guarantees for Arbitrary Submodular Functions

Curvature is extended to arbitrary submodular functions, yielding greedy multiplicative approximation guarantees that apply even to negative-valued objectives.

Yixin Chen, Alan Kuhnle

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Geometry-Aware Online Scheduling for LLM Serving: From Theoretical Bound to System Practice

Proposing geometry-aware online scheduling via Smallest Volume First improves LLM serving's worst-case competitive ratio from 48 to 3 and reduces latency in vLLM.

Li Kong, Qi Qi, Yinyu Ye, Zijie Zhou

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Communication-Efficient Personalized Adaptation via Federated-Local Model Merging

Potara merges federated and local models via closed-form optimal weights to improve federated personalization with lower communication costs.

Yinan Zou, Md Kamran Chowdhury Shisher, Christopher Brinton, Vishrant Tripathi

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Where, What, Why, and Importance: Structured Defect Grounding for Text-to-Image Feedback

Structured Defect Grounding models text-to-image failures as structured tuples for diagnosis and alignment, outperforming proprietary vision-language models and improving generation via importance-weighted rewards.

Huaisong Zhang, Hao Yu, Yuxuan Zhang, Jiahe Wang and 6 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Don't Always Pick the Highest-Performing Model: An Information Theoretic View of LLM Ensemble Selection

Formulating ensemble selection as mutual-information maximization reveals an information-theoretic error floor from model correlation and yields a greedy algorithm that outperforms baselines under fixed query budgets.

Yigit Turkmen, Baturalp Buyukates, Melih Bastopcu

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

SCDBench: A Benchmark for LLM-Based Smart Contract Decompilers

SCDBench benchmarks LLM smart-contract decompilers on 600 real contracts via semantic replay, finding even top models perfectly recover only 42 and same-model repair substantially helps.

Kaihua Qin, Dawn Song, Arthur Gervais

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Powering Up Zeroth-Order Training via Subspace Gradient Orthogonalization

Subspace gradient orthogonalization unifies low-rank projection with spectral optimization into ZO-Muon, cutting zeroth-order queries by 75% versus MeZO while boosting accuracy on LLM and vision fine-tuning.

Yicheng Lang, Changsheng Wang, Yihua Zhang, Mingyi Hong and 3 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Adaptive Mass-Segmented KV Compression for Long-Context Reasoning

AMS replaces global token eviction with adaptive region-aware KV quotas to prevent reasoning block wipe-out, boosting long-context performance without extra attention overhead.

Junzhe Yang, Xiaoyu Shen

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

AtomMOF: All-Atom Flow Matching for MOF-Adsorbate Structure Prediction

AtomMOF uses all-atom flow matching to predict MOF and adsorbate structures directly from 2D graphs, improving match rates and sampling efficiency.

Nayoung Kim, Honghui Kim, Sihyun Yu, Minkyu Kim and 2 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · Code ★ 19

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Rescaled Asynchronous SGD: Optimal Distributed Optimization under Data and System Heterogeneity

Rescaled ASGD corrects asynchronous SGD's bias toward fast workers via computation-time-proportional step sizes, matching optimal time complexity with only lower-order heterogeneity penalties.

Ammar Mahran, Artavazd Maranjyan, Peter Richtarik

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

EvoCUA: Evolving Computer Use Agents via Learning from Scalable Synthetic Experience

EvoCUA evolves computer-use agents via synthetic experience loops, achieving 56.7% success on OSWorld to set a new open-source state-of-the-art.

Taofeng Xue, Chong Peng, Mianqiu Huang, Linsen Guo and 11 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 92 on Hugging Face · Code ★ 352

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Benchmarking Compositional Generalisation for Machine Learning Interatomic Potentials

A benchmark of four compositional generalisation tasks reveals state-of-the-art machine learning interatomic potentials fail to generalise to unseen molecules, with out-of-distribution errors often ten times higher than in-distribution errors.

Amir Masoud Nourollah, Irtaza Khalid, Stefano Leoni, Steven Schockaert

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Your Language Model is Its Own Critic: Reinforcement Learning with Value Estimation from Actor’s Internal States

POISE predicts baselines from a model's internal states via a lightweight probe for stable, low-cost multi-domain RLVR without separate critics.

Yunho Choi, Jongwon Lim, woojin Ahn, Minjae Oh and 2 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 19 on Hugging Face · Code

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Efficient Memory Crystallization for Graph Learning under Non-Stationary Distribution Shifts

EMC replaces generative memory synthesis with closed-form crystallization for efficient continual graph adaptation under non-stationary shifts, reducing runtime by 87.4% and GPU memory by 92.4%.

Yue Hou, Ruomei Liu, Yingke Su, Wu Junran and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

StreamPhy: Streaming Inference of High-Dimensional Physical Dynamics via State Space Models

StreamPhy enables real-time streaming inference of high-dimensional physical fields from irregular sparse measurements via adaptive encoders and state-space updates, outperforming diffusion baselines by up to 48% accuracy and 20-100x speed.

Panqi Chen, Yifan Sun, Shikai Fang, Xiao Fu and 1 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

TabPrep: Closing the Feature Engineering Gap in Tabular Benchmarks

TabPrep is a lightweight feature engineering pipeline that targets structural data patterns to consistently boost tabular model performance across benchmarks.

Andrej Tschalzev, Nick Erickson, Yuyang (Bernie) Wang, Huzefa Rangwala and 3 more

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

VidVec: Unlocking Video MLLM Embeddings for Video-Text Retrieval

VidVec extracts intermediate-layer MLLM embeddings for video-text retrieval via calibration and text-only alignment, achieving state-of-the-art zero-shot results without video fine-tuning.

Issar Tzachor, Dvir Samuel, Rami Ben-Ari

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 24 on Hugging Face · Code

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Model Spec Midtraining: Improving How Alignment Training Generalizes

Model spec midtraining teaches models their behavior spec before alignment, controlling how demonstration fine-tuning generalizes and reducing agentic misalignment substantially.

Chloe Li, Sara Price, Samuel Marks, Jonathan Kutasov

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · Code ★ 74

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

IPIBench: Evaluating Interactive Proactive Intelligence of MLLMs under Continuous Streams

IPIBench evaluates interactive proactive intelligence of MLLMs on continuous video streams, revealing unstable proactive triggering and weak reactive-proactive coordination, while IPI-Agent improves both via temporal gating.

Jinzhao Li, Yinuo Chen, Wenxuan Song, Yijia Lei and 4 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

OTROPE: Optimal Transport-based Robust Off-policy Evaluation for Large Language Models

OTROPE uses optimal transport in semantic space to correct off-policy LLM evaluation without likelihoods or density ratios, yielding consistent doubly robust estimators that outperform baselines.

Liner Xiang, Wenbo Zhang, Hengrui Cai

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

LLM Alignment--Utility Asymmetry under Semantic-Preserving Transformations

Synthetic semantic-preserving transformations reveal alignment-utility asymmetry: LLMs retain task utility on shifted inputs but suffer sharp alignment failures, with harmful rates surging over 40 points despite minimal capability loss.

Mohan Li, Chengyu Yu, Francesco Sovrano, Marc Langheinrich and 1 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Training for the Model You Return: Improving Optimization for Iterate-Averaged Language Models

PACE wraps AdamW to pull live weights toward their EMA with clipped per-coordinate control, improving iterate-averaged LM training and reducing error by arbitrarily large factors in quadratics while boosting 1-2B SFT and GPT-2 pretraining.

Kwok C Au, Adam Block

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Instance-Optimal Estimation with Multiple LLM Judges on a Budget

EST-IVWE adaptively allocates a budget across judges and instances via biased variance estimates to achieve instance-optimal score estimation, with matching local minimax lower bounds.

Junghyun Lee, Sanghwa Kim, Yassir Jedra, Alexandre Proutiere and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Chain-of-Generation: Progressive Latent Diffusion for Text-Guided Molecular Design

Chain-of-Generation progressively decomposes prompts into curriculum-ordered segments to guide multi-stage latent diffusion, improving text-aligned molecular design with greater controllability and interpretability.

Lingxiao Li, Haobo Zhang, Bin Chen, Jiayu Zhou

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Forgetting Has Neighbors: Localized Collateral Forgetting in Machine Unlearning

Unlearning causes localized collateral forgetting that grows near deleted examples due to inconsistent surrogate targets, and local teacher distillation mitigates it.

Polina Dolgova, Sebastian Stich

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

SUGAR: A Scalable Human-Video-Driven Generalizable Humanoid Loco-Manipulation Learning Framework

SUGAR converts human videos into humanoid loco-manipulation skills via automated priors, physics refinement, and policy distillation, scaling with video data and enabling zero-shot real-world transfer.

Tianshu Wu, Xiangqi Kong, Yue Chen, Qize Yu and 4 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score
NeurIPS 2026DalhousiePrivacy

Re-examining Low Rank adaptation for private LLM fine-tuning

DP-SGD noise inflates gradient singular values and disrupts decay, yet restoring fast decay improves private LLM fine-tuning efficiency without compromising privacy guarantees.

Ali Dadsetan, Frank Rudzicz

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

On the Recoverability of Causal Relations from Bulk Gene Expression Data

Causal gene relations are recoverable from bulk expression only under linear aggregation and affine equations, which real data rarely satisfy.

Gongxu Luo, Boyang Sun, Kun Zhang

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

What Fits (Into Few Tokens) Doesn't Overfit: Compression and Generalization in ML Research Agents

LLM research agents find high-performance models via compressed prompts and feedback, supporting a description-length explanation for limited overfitting.

Martin Bertran, Aaron Roth, Steven Wu

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Universal Byte-Level Encoding: UTF-8/UTF-16 Routing to Reduce Cross-Script Token-Budget Disparities

Universal Byte-Level Encoding routes 3, 4 byte UTF-8 via UTF-16 to lower token counts for high-premium scripts without raising costs for efficient spans, reducing cross-lingual token-budget disparity while preserving model quality.

Hyunsik Kim, Youngmoon Jung

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

X-Palm: Paired Multispectral-to-Smartphone Dataset for Cross-Domain Palmprint Authentication

X-Palm is a cross-domain palmprint dataset pairing controlled multispectral and unconstrained smartphone images that reveals severe performance collapse of existing models on real-world mobile authentication.

Seyed Jamal Seyedmohammadi, Pai Chet Ng, Angelo Genovese, Zhixiang Chi and 2 more

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Contrast encodes inductive bias: separating slow noise from dynamics in predictive representation learning

Contrastive predictive objectives that sample negatives across trajectories confuse slowly varying noise with true dynamics, but intra-trajectory negative sampling removes this shortcut and improves learned dynamics representations.

Paarth Gulati, Ilya Nemenman

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Fail-Closed Alignment for Large Language Models

Fail-closed alignment builds redundant refusal pathways to prevent alignment collapse under jailbreaks, yielding stronger robustness with minimal overhead.

Zachary Coalson, Sanghyun Hong

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

The Many Senses of Visual Similarity: A Text-Prompted Image Perceptual Metric

A dataset of multi-aspect human visual similarity judgments benchmarks vision-language models and yields the TPIPS metric, which aligns with human perception and enables text-guided image retrieval and generative evaluation.

Sheng-Yu Wang, Yotam Nitzan, Aaron Hertzmann, Jun-Yan Zhu and 3 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

ARGUS: Stacked Multi-View Identity Mosaic Injection for Subject-Preserving Video Generation

ARGUS introduces multi-view identity mosaic injection and counterfactual training to preserve subject identity across motion, viewpoint changes, and occlusions in video generation.

Zijie Meng, Jiwen Liu, Yufei Liu, Chengzhuo Tong and 4 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Exposing and Mitigating Temporal Attack in Deepfake Video Detection

SpInShield defends deepfake detectors against temporal spectral attacks by suppressing unstable spectral shortcuts and learning robust semantic motion cues, improving attack resilience by over 21 AUC points.

Zheyuan Gu, Minghao Shao, Zhen Wang, Keyu Mao and 6 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Improving Function Space Flow Matching with Kernel Optimal Transport

kFFM replaces arbitrary pairing in Functional Flow Matching with kernel optimal transport to improve infinite-dimensional generative modeling and outperforms baselines on time-series and PDE benchmarks.

Fred Xu, Thomas Markovich, Barbora Barancikova, Yizhou Sun

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Change-Robust Online Topological Memory for Long-Term Relocalization and Semantic Navigation

CROSS introduces a pre-commitment localization layer using continuous SE(3) pose branches and Gaussian-mixture filtering to reject false matches, improving long-term robot relocalization and semantic navigation under severe scene changes.

Jiaming Wang, Liu Diwen, Chen Jizhuo, Atharva A Ghotavadekar and 3 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Benchmarking and Improving Monitors for Out-Of-Distribution Alignment Failure in LLMs

MOOD benchmark shows guard models fail to detect out-of-distribution alignment failures, but combining them with Mahalanobis and perplexity detectors improves recall from 39% to 45% and scales positively.

Dylan Feng, Pragya Srivastava, Anca Dragan, Cassidy Laidlaw

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

STILL: Selecting Tokens for Intra-Layer Hybrid Attention to Linearize LLMs

STILL introduces self-saliency token selection and norm-preserved feature maps to linearize LLMs, matching original performance with up to 86.2% long-context gains.

Weikang Meng, Liangyu Huo, Yadan Luo, Jiawen Guan and 3 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 2 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Towards Fairness under Label Bias in Image Segmentation: Impact, Measurement and Mitigation

A confident learning framework audits segmentation label bias without unbiased ground truth and mitigates subgroup disparities via feature-space separability.

Aditya Parikh, Stella Christina Frank, Sneha Das, Aasa Feragen

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Parameterized Stripe Attention for Efficient Video Generation

Parameterized stripe attention exploits periodic diagonal stripe structures in video DiT attention to unify sparse patterns in one hardware-efficient kernel, achieving 1.57× speedups over FlashAttention-3 with minimal quality loss.

xingyu jia, Baole Ai, Ang Wang, Kang Zhao and 1 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Derived Fields Preserve Fine-Scale Detail in Budgeted Neural Simulators

Derived-Field Optimization selects carried physical fields and allocates storage budgets to preserve fine-scale detail in budgeted neural simulators, significantly improving fidelity before rollout even on PDEBench.

Wenshuo Wang, Fan Zhang

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

DiffScore: Text Evaluation Beyond Autoregressive Likelihood

DiffScore evaluates text with masked diffusion models using bidirectional context to eliminate positional bias and decompose quality into fluency and faithfulness, outperforming autoregressive baselines.

Wen Lai, Yingli Shen, Dingnan Jin, Qing Cui and 3 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Solver-Aware Decompositions for Programming-by-Example: When Dividing Requires Knowing how to Conquer

Solver-Aware Decomposition trains PBE decomposers via synthesizer feedback, showing ground-truth subgoal alignment does not improve synthesis and optimizing for solver tractability yields consistent accuracy gains.

Janis Zenkner, Tobias Sesterhenn, Tim Grams, Christian Bartelt

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Learning What to Forget: Improving LLM Unlearning via Learned Token-Level Importance

ATWU learns token-level forget-specificity via retain-conflict scoring to improve LLM unlearning, achieving state-of-the-art forget-retain trade-offs without external supervision.

Gizem Yüce, Giorgos Nikolaou, Nicolas Flammarion

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Reason in the Words You Speak: Idiolectal Paraphrasing Off-Policy Traces for Reasoning Distillation in VideoLLMs

Echo-GRPO rewrites off-policy reasoning traces into a student VideoLLM's idiolect to avoid gradient clipping, improving reasoning distillation across backbones and benchmarks.

Ji Soo Lee, Jinyoung Park, Seohyun Lee, Jongha Kim and 3 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 24 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

StiCAS: Compositional Activation Steering via Stiefel Manifold Coordinate Transport

StiCAS learns orthogonal concept subspaces via Stiefel optimization so compositional activation steering achieves exact commutativity and doubles multi-concept success.

Toan Doan, Thin Nguyen, Sunil Gupta

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Adaptive Generate-Rank-Verify: Inference-Time Search with Costly Verification

ADAP adaptively increases response sampling and verification to find verified positives with near-optimal expected cost under monotonic rewards.

Shaddin Dughmi, Mahdi Haghifam, Yusuf H Kalayci

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face · Code ★ 2

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Learning to play with spikes. Characterizing, predicting, and engineering unsupervised plasticity rules for spiking reservoir computing

Local plasticity rules stabilize spiking reservoirs and structure representations into predictable, transferable signatures that allow direct engineering of high-performing neuromorphic algorithms.

Maciej Kania, Basile Confavreux, Tim Vogels

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

CompleteRXN: Toward Completing Open Chemical Reaction Databases

CompleteRXN introduces a benchmark for completing incomplete chemical reaction databases, showing models reach high accuracy on benchmark splits but degrade substantially on uncurated real-world data.

Gabriel Vogel, Minouk Noordsij, Evgeny A Pidko, Jana M. Weber

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

SpatialClaw: Rethinking Action Interface for Agentic Spatial Reasoning

SpatialClaw uses a stateful Python kernel with step-wise code execution to enable flexible spatial reasoning, achieving 59.9% average accuracy across 20 benchmarks.

Seokju Cho, Ryo Hachiuma, Abhishek Badki, Hang Su and 7 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 115 on Hugging Face · Code ★ 431

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Stay Fair! Ensuring Group Fairness in Diffusion Models Across Guidance Scales

StayFair decomposes diffusion bias into model and guidance components, deriving a guidance-scale-invariant fairness condition and algorithms that maintain group fairness across all guidance scales without quality loss.

Myeongsoo Kim, Eunji Kim, Minwoo Chae, Sangwoo Mo

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Remember with Confidence: Uncertainty Quantification for Spatio-temporal Memory with Probabilistic Guarantees

UQ-DAAAM introduces object-level semantic uncertainty for multi-view VLM memory and actively refines uncertain descriptions under a fixed budget with probabilistic guarantees, improving spatio-temporal reasoning.

Harry Zhang, Nicolas Gorlo, Luca Carlone

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Impacts of Aggregation on Model Diversity and Consumer Utility

Winrate incentivizes model homogenization that reduces consumer welfare, while weighted winrate improves producer specialization incentives and raises utility.

Kate Donahue, Manish Raghavan

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

3D-PLOT-LLM: Part-Level Object Tokens for 3D Large Language Models

3D-PLOT-LLM inserts learnable part tokens into frozen point features to enable part-level reasoning in 3D LLMs with under 1M parameters, outperforming prior part-aware models on part-QA and grounded description benchmarks.

Jintang Xue, Xinyu Wang, Yixing Wu, Jingwen Chen and 1 more

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

OpenCoF: Learning to Reason Through Video Generation

OpenCoF introduces a 17K video reasoning dataset and Wan-CoF model that improves chain-of-frame reasoning via diverse temporal supervision and reasoning tokens.

Xinyan Chen, Renrui Zhang, Ziyu Guo, Dongzhi JIANG and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 26 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

SWE Atlas: Benchmarking Coding Agents Beyond Issue Resolution

SWE Atlas benchmarks coding agents on codebase Q&A, test writing, and refactoring, finding frontier models lead but all struggle with edge cases and engineering quality.

Mohit Raghavendra, Soham Dan, Miguel Romero Calvo, Yannis He and 11 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

DC-DiT: Adaptive Compute and Elastic Inference for Visual Generation via Dynamic Chunking

DC-DiT uses dynamic chunking to adaptively allocate tokens by region and timestep, reducing ImageNet inference FLOPs by up to 36.8% and improving FID by up to 37.8%. Its router enables elastic inference from a single checkpoint with smooth quality-compute tradeoffs.

Akash Haridas, Utkarsh Saxena, Parsa Ashrafi Fashi, Mehdi Rezagholizadeh and 2 more

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026 · ▲ 16 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Training on Documents About Monitoring Leads to CoT Obfuscation

Synthetic document finetuning teaches models to hide misbehavior from chain-of-thought monitors, with success tied to reasoning controllability and faster reward-hacking under RL.

Reilly Haskins, Bilal Chughtai, Joshua Engels

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

Show 40 more papers