Good Papers

Showing RL for LLMs Show all papers

82%Must read
?Must readVote to see the score

Sherpa: Teaching LLMs to Teach Adaptively

Sherpa uses multi-turn reinforcement learning to train LLM teachers that adapt instructions to diverse student archetypes, improving student performance by 20.5 points and pedagogy scores to 79.2%.

Weixian Xu, Yanzhe Zhang, Zora Zhiruo Wang, Changyu Chen and 1 more

Published Oct 6, 2026 · ▲ 3 on Hugging Face · Code

100% Readers1 of 1 upvoted
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 0/5
84%Must read
?Must readVote to see the score

TRACE: Rollout-Guided Quantization-Aware Training for FP4 Reinforcement Learning of MoE Language Models

TRACE aligns FP4 quantization between RL training and rollout paths via rollout-guided quantization-aware training for MoE language models, achieving BF16-comparable RL performance with up to 5.4x rollout speedup.

Xin Wang, Hao Yu, Zhengyang Zhuge, Bochao Mao and 8 more

Published Oct 6, 2026 · ▲ 15 on Hugging Face

100% Readers1 of 1 upvoted
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 1/5
80%Must read
?Must readVote to see the score

NeMo-DCR: Bit-Exact Delta-Compressed Refit for Scalable Agentic RL at Trillion-Parameter Scale

NeMo-DCR bit-exactly refits trillion-parameter policies by streaming delta-compressed weight changes via affine mappings and XOR masks, cutting 1T cross-region refits from 87.5 minutes to 150 seconds.

Songlin Jiang, Zhiyu Li, Terry Kong, Yu Yao and 4 more

Published Oct 6, 2026 · ▲ 6 on Hugging Face · Code ★ 2,048

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 4/5
medium 6/10
strict 2/5
84%Must read
?Must readVote to see the score

HiPLEX: Hierarchical Policy Factorization for Full Duplex Speech Language Models

HiPLEX factorizes full-duplex speech policies into timing and content controllers to jointly optimize interaction dynamics via reinforcement learning. It lowers takeover rates, reduces interruption latency, and improves human-like turn timing versus GRPO.

Kyudan Jung, Hyunsin Park, Yoonhyung Lee, Jinhwan Park and 4 more

Published Oct 6, 2026

100% Readers1 of 1 upvoted
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 1/5
76%Highly rated
?Highly ratedVote to see the score
NeurIPS 2026RL for LLMs

Rationale-Guided Policy Optimization: Learning to Reason with Adaptive Rationale Scaffolding

RGPO adaptively uses ground-truth rationales as temporary scaffolds to generate improved responses for on-policy RL, then transfers only higher-reward model outputs back, reducing reward sparsity and improving text and multimodal reasoning.

Hoang Phan, Minh Pham, Chau Pham, Chinmay Hegde and 2 more

Published Oct 5, 2026 · ▲ 7 on Hugging Face · Code ★ 1

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 10 of 20 reviewers recommend it
lenient 4/5
medium 6/10
strict 0/5
78%Highly rated
?Highly ratedVote to see the score

LoGRA: Scaling LLM Reinforcement Learning with Low-Rank Gradient Sketches

LoGRA reduces LLM reinforcement learning memory by up to 45.7% via low-rank gradient sketches and predicted-KL step control, enabling 27B-parameter training on single nodes.

Shaokun Zhang, Yifan Zhang, Jian Hu, Yueying Li and 4 more

Published Oct 5, 2026 · ▲ 11 on Hugging Face

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 5/10
strict 1/5
80%Must read
?Must readVote to see the score

OPD Before RL: Warm-Starting Rubric-Based RL with On-Policy Distillation

Rubric-privileged on-policy distillation before reinforcement learning improves open-ended task scores and reduces reward hacking versus supervised fine-tuning baselines.

Xinpeng Wang, Wei Shi, Yu-Chia Chen, Maria Zontak and 2 more

Published Oct 2, 2026 · 0 citations · ▲ 3 on Hugging Face

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 1/5
88%Must read
?Must readVote to see the score

MetaRubric: Learning to Reward for Rubric-Based Reinforcement Learning

MetaRubric fixes vacuous rubric credit via evidence-aware optimization and counterfactual rubric adaptation, improving PubMedQA accuracy by up to 20.40 points over static-judge GRPO.

Yuxuan Fan, Jaehong Yoon

Published Oct 2, 2026 · 0 citations · ▲ 22 on Hugging Face · Code ★ 2

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 2/5
91%Must read

Sharpening Tax in Post-Training

Post-training sharpens base model behaviors at the cost of solution coverage, introducing a quantifiable "Sharpening Tax"; a posterior-tempered group sampler reduces this tax while boosting accuracy.

Changdae Oh, Qi Zeng, Qi Qi, Andrey Zhmoginov and 6 more

Published Oct 1, 2026 · 0 citations · ▲ 102 on Hugging Face · Code ★ 25

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 3/5
71%Highly rated
?Highly ratedVote to see the score

From Gradients to Capabilities: Understanding Multi-Teacher On-Policy Distillation

Multi-teacher on-policy distillation integrates RL teacher gradients via loss averaging, Adam smoothing, and BF16 rounding, with averaging rules significantly altering math accuracy outcomes.

Siqi Zhu, Suozhi Huang, Kaixuan Zhang, Yuheng Yang and 3 more

Published Oct 1, 2026 · 0 citations · ▲ 13 on Hugging Face

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 7 of 20 reviewers recommend it
lenient 3/5
medium 3/10
strict 1/5
86%Must read
?Must readVote to see the score

Does Scaling Reinforcement Learning Really Require More Training?

SURGE extracts stronger policies from fixed RL histories via spectral fusion of checkpoints, exceeding native training-curve accuracy without extra training or inference cost.

Bangji Yang, Jiajun Fan, MA Hongba, Ruihan Guo and 1 more

Published Oct 1, 2026 · 0 citations

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 4/5
medium 9/10
strict 1/5
83%Must read
?Must readVote to see the score

My FAULT: Self-Diagnosis as Credit Assignment in Self-Evolving Agentic Reinforcement Learning

FAULT turns self-diagnosed errors into step-level credit via terminal outcome anchoring and evidence-checked cost learning, recovering 95% signal coverage on ALFWorld and improving long-horizon agentic RL.

Yihua Zhu, Qianying Liu, Weixu Qiao, Xuan Ren and 9 more

Published Oct 1, 2026 · 0 citations

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 13 of 20 reviewers recommend it
lenient 4/5
medium 8/10
strict 1/5
80%Must read
?Must readVote to see the score

Function-Structured Reinforcement Learning with Executable Verifiers for Mathematical Reasoning

FSG-RL connects subproblem graphs with Python code and multi-verifier feedback to improve math reasoning, raising final-answer accuracy from 43.25% to 67.50% over supervised fine-tuning.

Zihan Liu, Xurong Xie

Published Oct 1, 2026 · 0 citations

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 4/5
medium 7/10
strict 1/5
89%Must read
?Must readVote to see the score

CARM: Cancellation-Aware Response Masking for LLM Reinforcement Learning

CARM prevents opposing token-level probability changes from canceling in sequence-level masking by using absolute log-ratios, improving RL reasoning and code benchmarks over geometric-mean masking.

Yafei Zhang, Songshuo Lu, Sicong Liao, Zhi Chen and 1 more

Published Oct 1, 2026 · 0 citations

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
80%Must read
?Must readVote to see the score

Make Sparse Rewards Count: Density-Aware Reward Aggregation for Multi-Reward RL

DARA corrects batch-level reward imbalance via inverse-square-root active-group density weights, accelerating multi-reward RL training by up to 65% with no objective change.

Tong Zheng, Skylar Zhai, Zhan Cheng, Tianming Sha and 6 more

Published Sep 30, 2026 · 0 citations · ▲ 64 on Hugging Face · Code ★ 2

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 1/5
70%Highly rated
?Highly ratedVote to see the score

Small RL Controller, Large Language Model: RL-Guided Adaptive Sampling for Test-Time Scaling

A lightweight RL controller formulates adaptive sampling as an MDP to balance LLM answer correctness, latency, and computation cost at test time.

Runpeng Dai, Tong Zheng, Rui Liu, Chengsong Huang and 1 more

Published Jun 2, 2026 · 0 citations · ▲ 13 on Hugging Face

– ReadersNo votes yet
5/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 5 of 20 reviewers recommend it
lenient 4/5
medium 1/10
strict 0/5
80%Must read
?Must readVote to see the score

Too Correct to Learn: Reinforcement Learning on Saturated Reasoning Data

Reinforcement learning on saturated reasoning data causes mode collapse as advantage signals vanish; CUTS sampling and Mixed-CUTS restore diversity, boosting AIME25 accuracy by up to 15.1%.

Zhenwen Liang, Yujun Zhou, Sidi Lu, Xiangliang Zhang and 2 more

Published Apr 20, 2026 · 0 citations

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 4/5
medium 8/10
strict 0/5
76%Highly rated
?Highly ratedVote to see the score

AI Can Learn Scientific Taste

RLCF trains AI to judge and propose high-impact research ideas via community feedback, showing learned scientific taste generalizes across fields and time.

Jingqi Tong, Mingzhe Li, Hangcheng Li, Yongzhuo Yang and 19 more

Published Mar 15, 2026 · 0 citations · ▲ 316 on Hugging Face · Code ★ 433

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 10 of 20 reviewers recommend it
lenient 5/5
medium 4/10
strict 1/5
88%Must read
?Must readVote to see the score

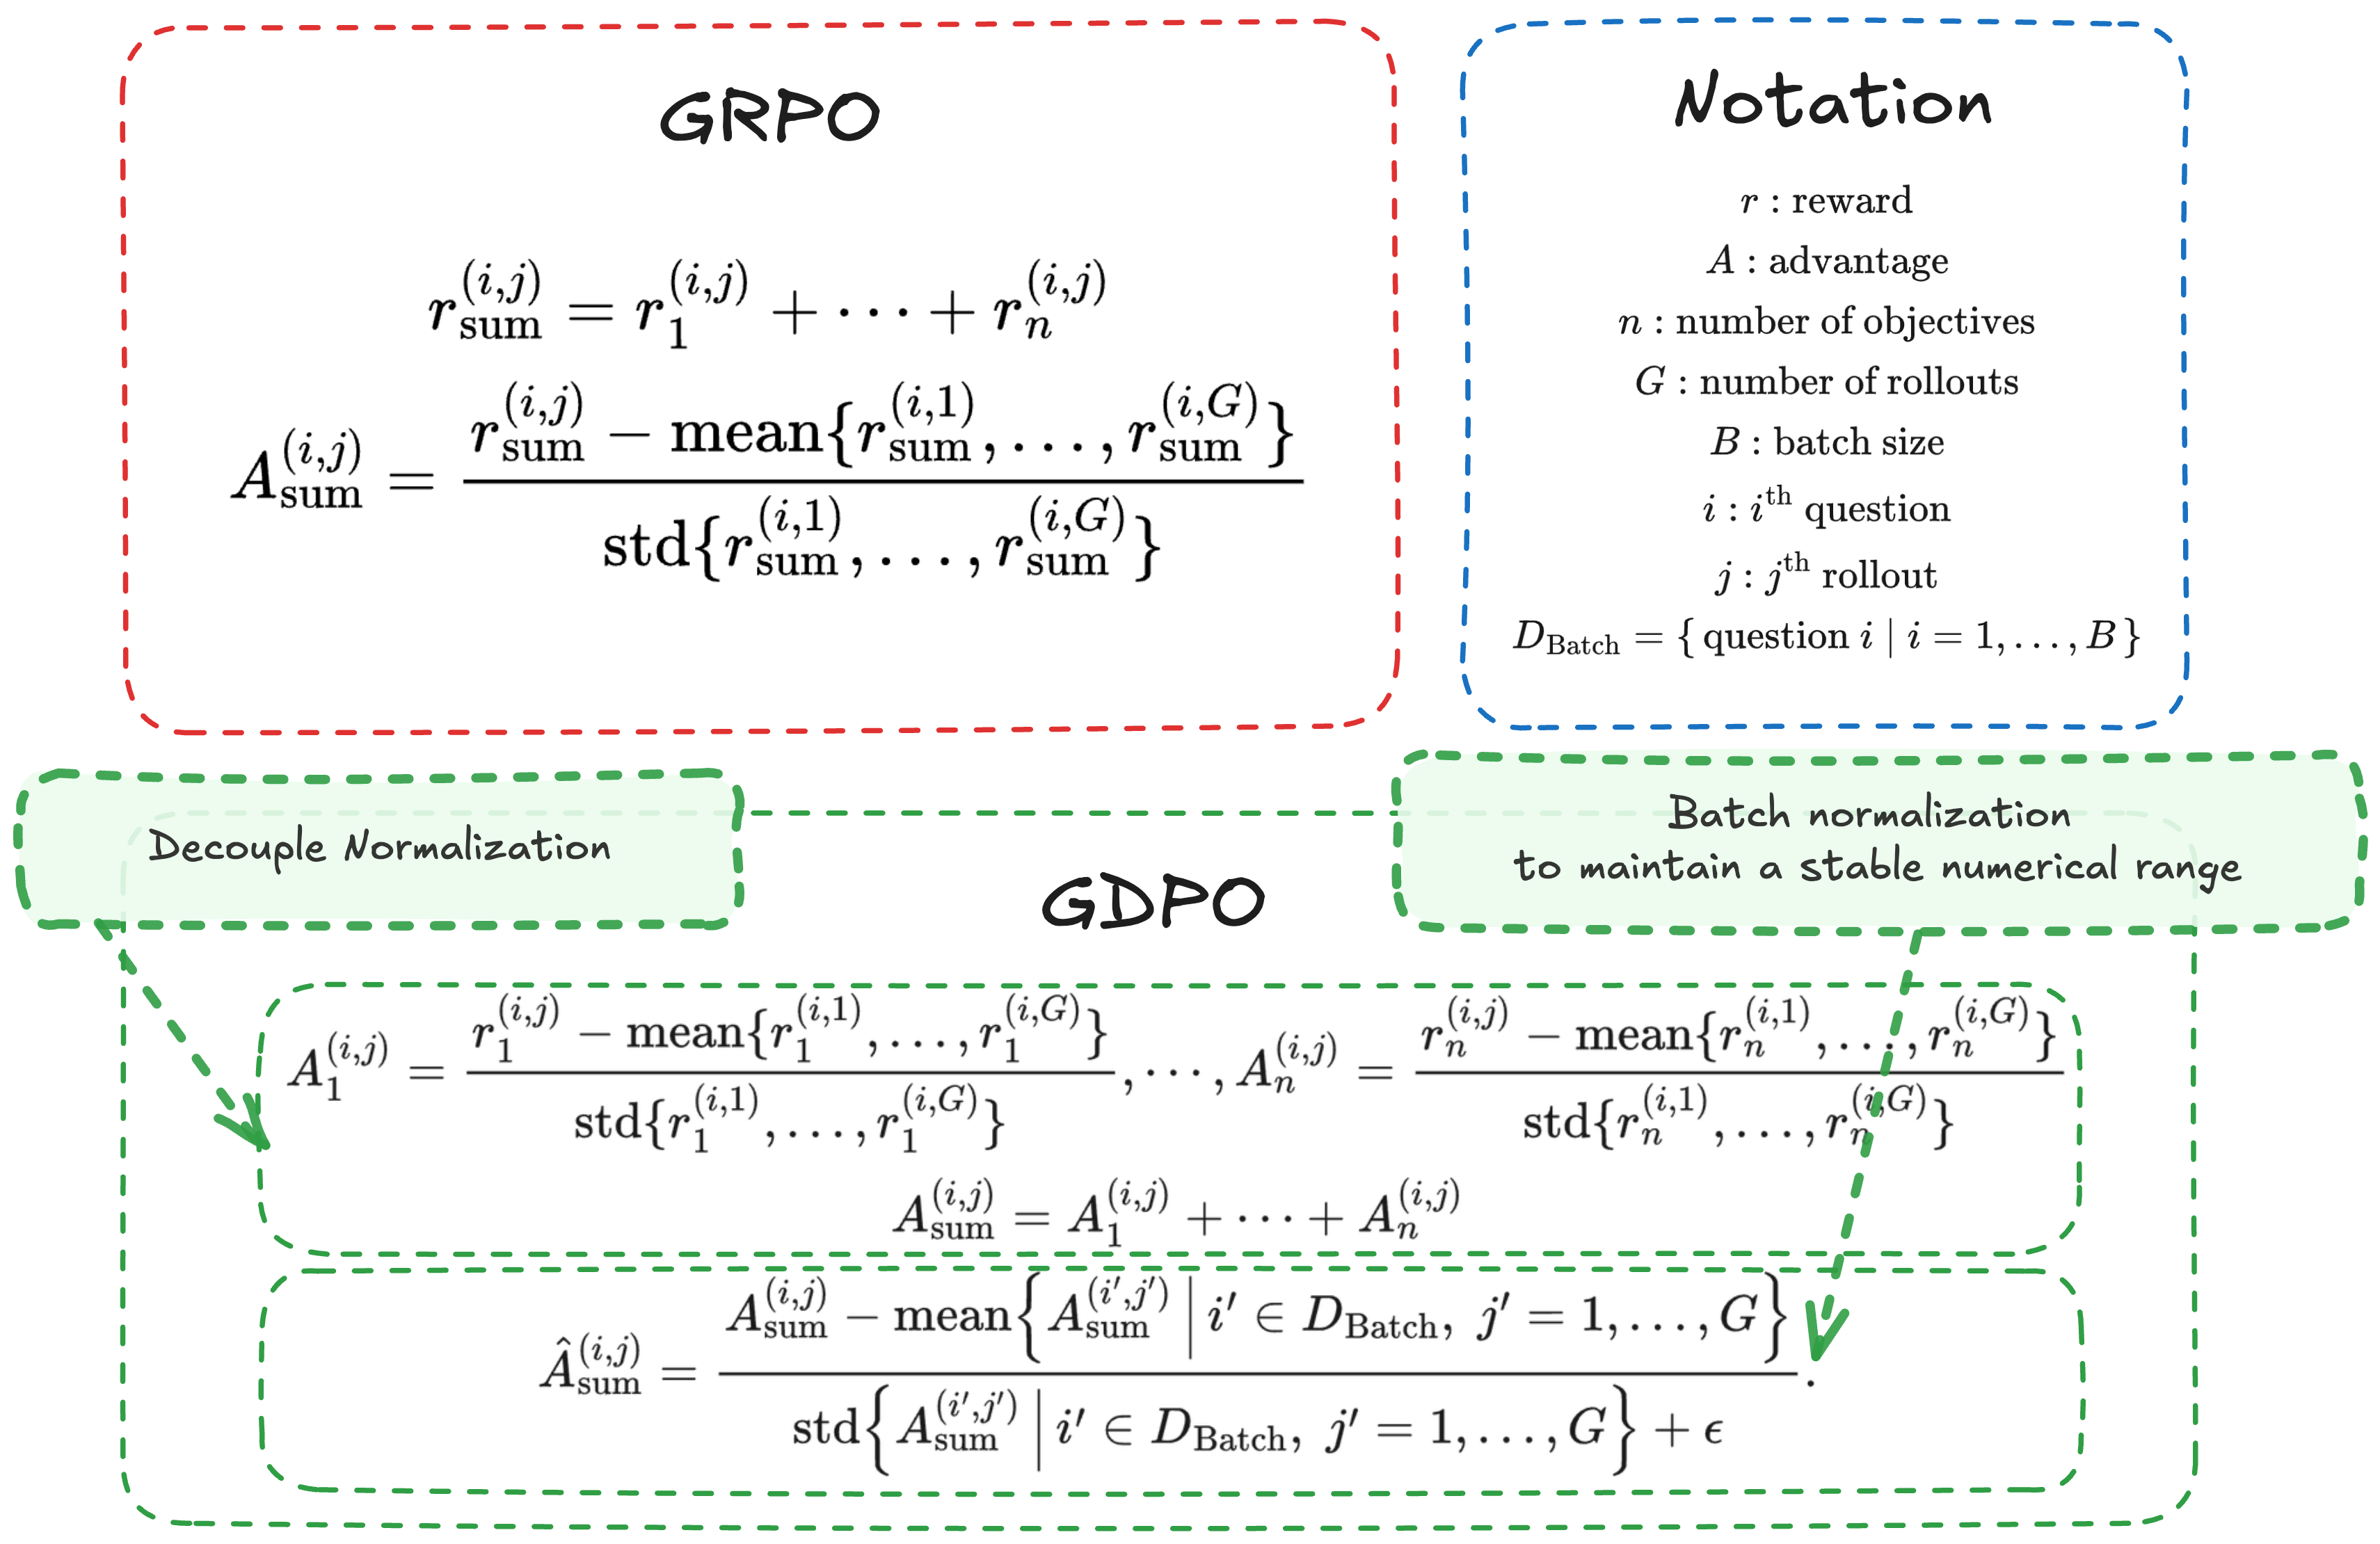
GDPO: Group reward-Decoupled Normalization Policy Optimization for Multi-reward RL Optimization

GDPO decouples per-reward normalization in multi-reward RL to prevent advantage collapse, improving training stability and outperforming GRPO on reasoning and coding tasks.

Shih-Yang Liu, Xin Dong, Ximing Lu, Shizhe Diao and 9 more

Published Jan 8, 2026 · 0 citations · ▲ 235 on Hugging Face · Code ★ 512

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 1/5
83%Must read
?Must readVote to see the score

Too Correct to Learn: Reinforcement Learning on Saturated Reasoning Data

Standard RL collapses on saturated reasoning data due to vanishing advantage signals, so CUTS sampling and Mixed-CUTS training restore exploration and boost AIME25 Pass@1 by 15.1%.

Zhenwen Liang, Yujun Zhou, Sidi Lu, Xiangliang Zhang and 2 more

Published 2026 · 0 citations

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 13 of 20 reviewers recommend it
lenient 4/5
medium 9/10
strict 0/5
Show 20 more papers