Good Papers

Showing Reward models & LLM-as-a-judge Show all papers

89%Must read
?Must readVote to see the score

Old Ideas, Novel Problems: The Instability of LLM-Based Novelty Evaluation

LLM novelty judges are unstable: small prompt changes alter verdicts on over half of identical idea pairs and shift accuracy by over 50 points, undermining automated ideation evaluations.

Noy Sternlicht, Simra Shahid, Peter Jansen, Daniel S. Weld and 2 more

Published Oct 1, 2026 · 0 citations

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 3/5
74%Highly rated
?Highly ratedVote to see the score

LexReward: A Taxonomy-Driven Reward Framework for Legal Language Models

LexReward introduces taxonomy-driven rubric-based rewards for legal language models across style, element, and reasoning dimensions, improving DPO and reinforcement learning performance.

Yida Cai, Xin Dai, Bingxiang He, Huiyuan Xie and 4 more

Published Sep 30, 2026 · 0 citations · ▲ 51 on Hugging Face

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 9 of 20 reviewers recommend it
lenient 5/5
medium 3/10
strict 1/5
88%Must read
?Must readVote to see the score

StudentSim: Training LLM-based Student Simulators

StudentSim trains LLM student simulators via pooled training and per-student specialization, outperforming GPT-5.4 on behavioral fidelity and guidance responsiveness across chess, writing, and math.

Ke Yang, Chenglong Wang, Michel Galley, Chandan Singh and 3 more

Published Sep 1, 2026 · 0 citations · ▲ 495 on Hugging Face · Code ★ 53

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 2/5
89%Must read
?Must readVote to see the score

Equal Ranking Quality, Different Decisions: Measuring and Reducing Order Dependence in LLM Scorers

LLM scorers with equal ranking quality make unstable threshold and preference decisions under candidate reordering, and order-consistency fine-tuning fixes it without harming quality.

Markus Frohmann, Mahdiyar Alavi, Elizabeth Lingg, Navid Rekabsaz

Published Aug 27, 2026 · 0 citations · ▲ 17 on Hugging Face · Code ★ 2

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
45%Niche pick
?Niche pickVote to see the score

DiagSQL: A Diagnostic Validator for Text-to-SQL with Reward Allocation and Co-occurrence Shaping

Weibin Liao, Bowen Cao, Dong Fang, Wai Lam

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

A Matter of Interest: Understanding Interestingness Judgments of Math Problems in Humans and Language Models

Shubhra Mishra, Yuka Machino, Gabriel Poesia, Albert Q. Jiang and 8 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

When Expert Disagreement Hurts: Auditing Prestige-Sensitive Revision in LLM Decision Pipelines

Yupeng Tang, Mingfeng Lin

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
69%Highly rated
?Highly ratedVote to see the score

Auditing the Judge: Human-Grounded Bias Discovery, Quantification, and Mitigation in LLM Judges

Hamin Koo, ChanJoo Jung, Fangzhao Wu, Jaehyung Kim

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
3/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 3 of 20 reviewers recommend it
lenient 2/5
medium 1/10
strict 0/5
91%Must read
?Must readVote to see the score

Why Deterministic PRM Guidance Underperforms in Discrete Diffusion Reasoning

Deterministic PRM guidance for discrete diffusion reasoning underperforms simpler ORM reranking because PRMs score weak intermediate states poorly and judge final outputs worse than outcome verifiers, reducing accuracy by up to 12.69 percentage points.

Yan Zhan, Shaobo Liu, Zhijun Gao

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 2 on Hugging Face · Code ★ 1

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 3/5
medium 9/10
strict 5/5
91%Must read
?Must readVote to see the score

Rethinking Rubric Generation for Improving LLM Judge and Reward Modeling for Open-ended Tasks

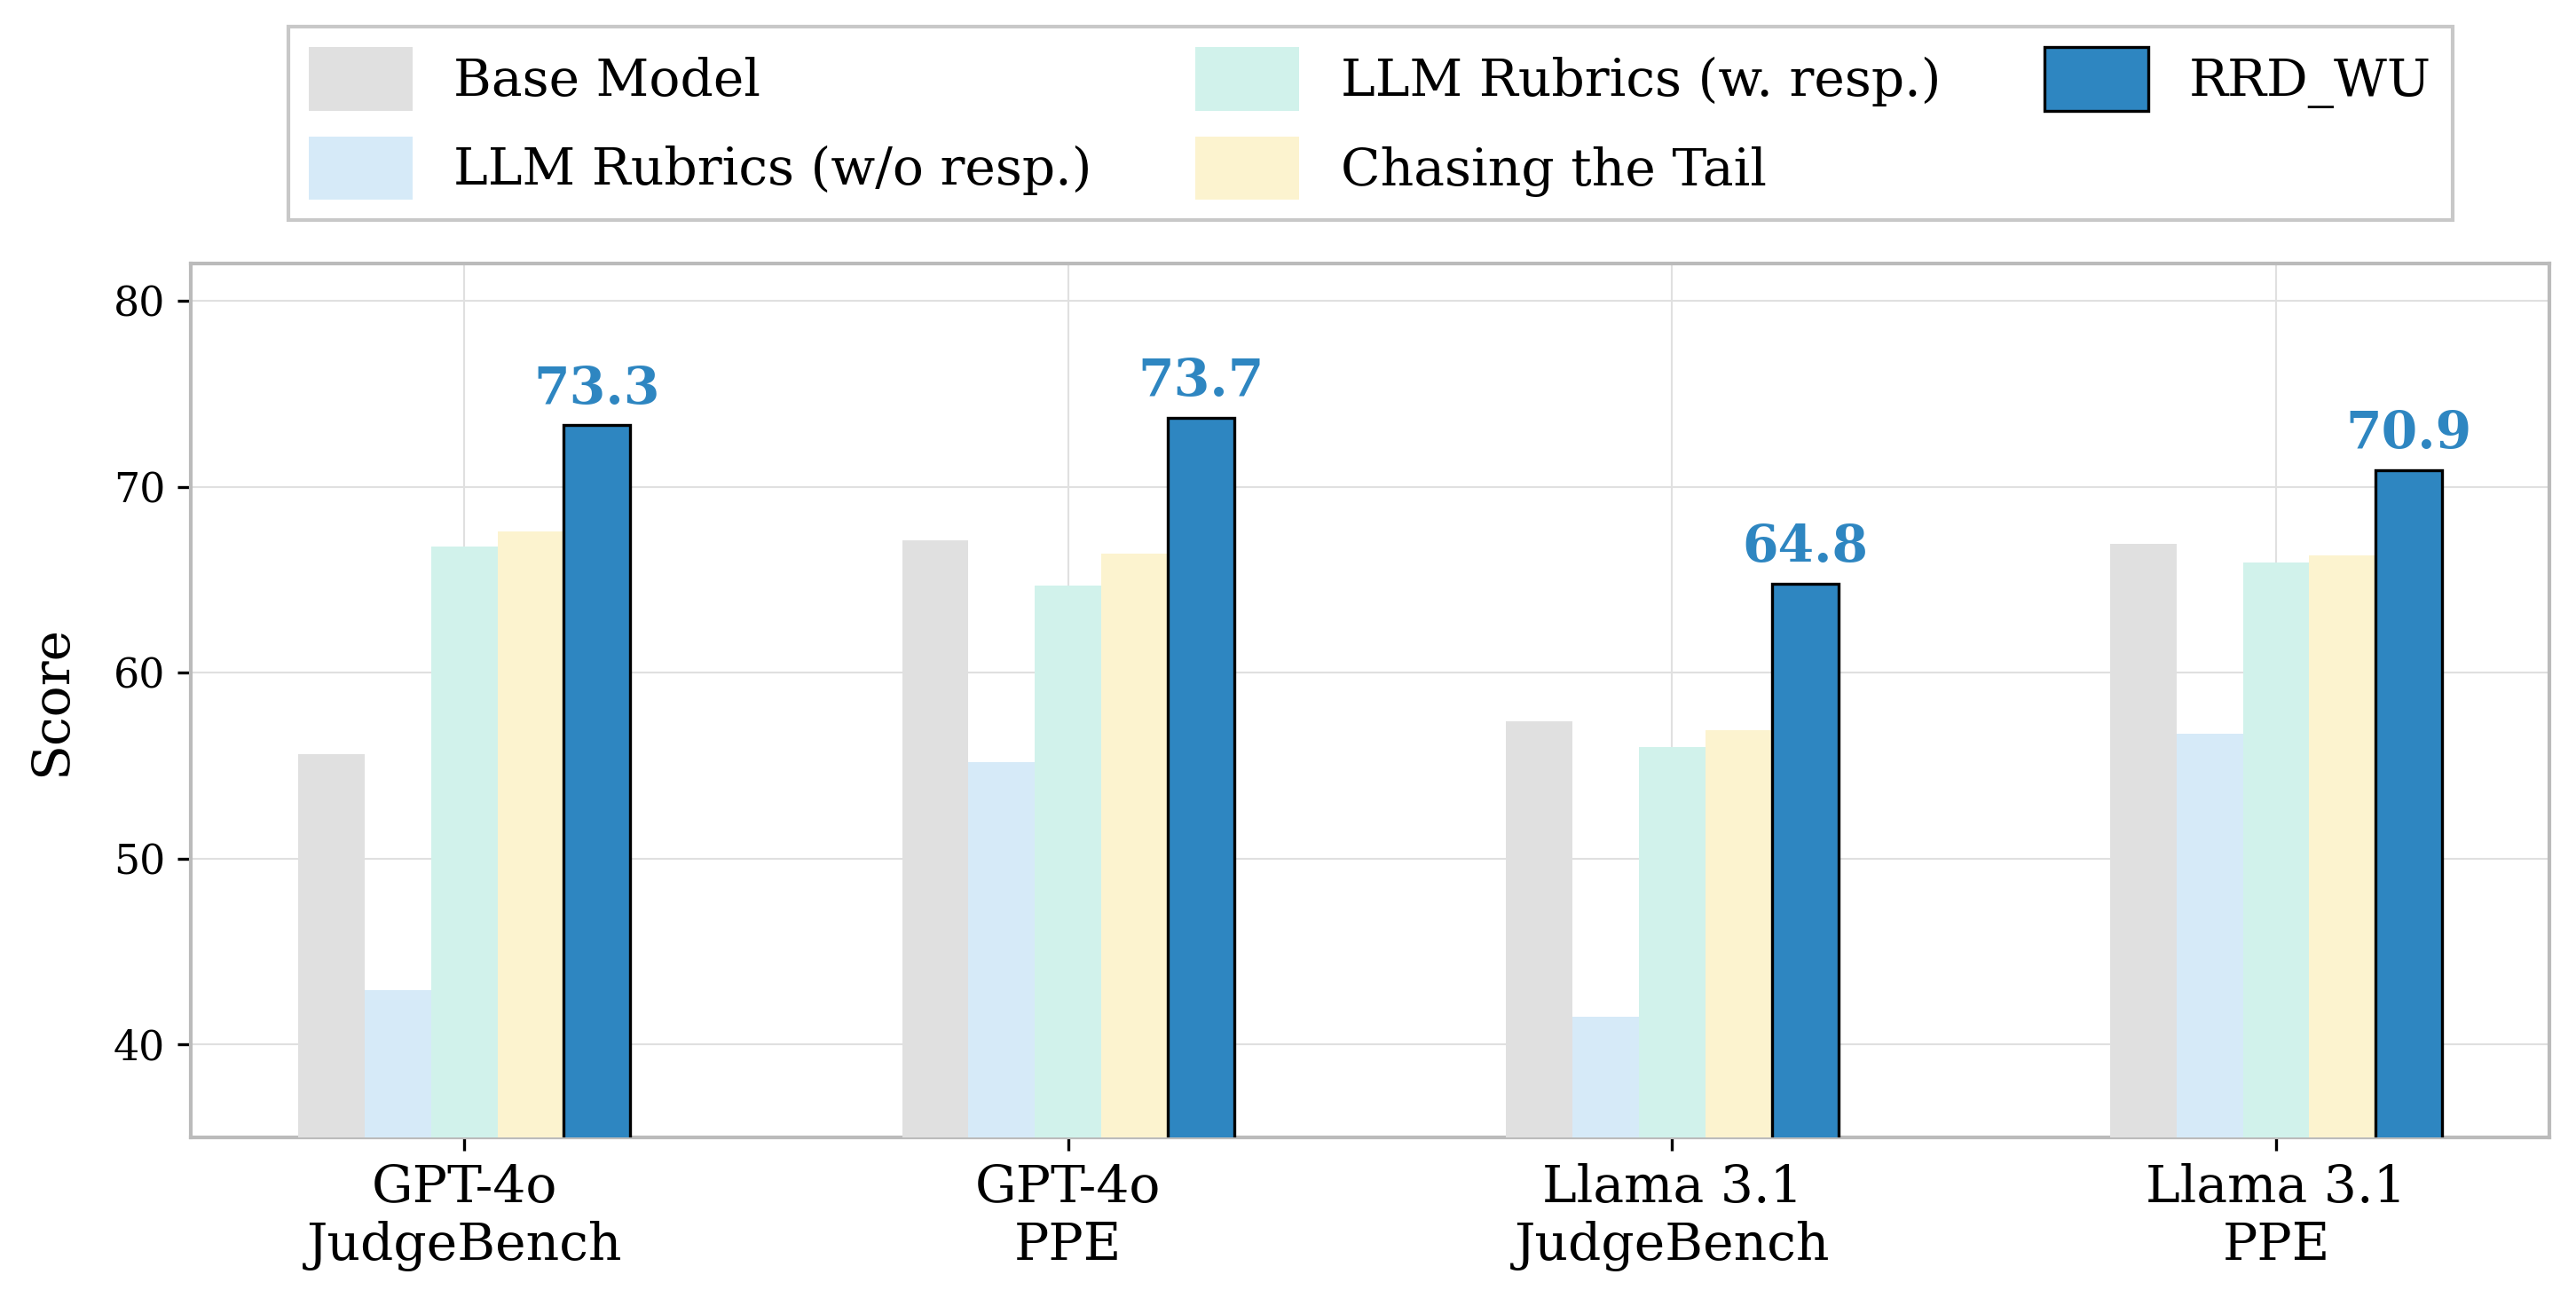
RRD refines rubrics via recursive decomposition and filtering to improve LLM judge accuracy and reinforcement training rewards on open-ended tasks.

William Shen, Xinchi Qiu, Chenxi Whitehouse, Lisa Alazraki and 5 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 2/5
88%Must read
?Must readVote to see the score

LLM Judge Validation Under Sparse Overlap: From Inference to Design

Sparse overlap in LLM judge validation drives wrong deployment decisions, reaching 25% error at 5% overlap; minimum 25% overlap and stratified allocation reduce errors significantly.

Junxuan Li, Arko Mukherjee, Soumyabrata Pal

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 2/5
78%Highly rated
?Highly ratedVote to see the score

Teacher-Aware Evolution of Heuristic Programs from Learned Optimization Policies

A teacher-aware evolutionary framework uses learned optimization policies as behavioral teachers to evolve static executable heuristics, improving combinatorial optimization benchmarks without neural inference at deployment.

Minyu Chen, Song Qin, Ling-I Wu, Jianxin Xue and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 5/10
strict 1/5
88%Must read
?Must readVote to see the score

KV-PRM: Efficient Process Reward Modeling via KV-Cache Transfer for Multi-Agent Test-Time Scaling

KV-PRM eliminates text re-encoding by scoring via pre-existing KV caches, reducing process reward modeling cost from quadratic to linear and cutting latency and FLOPs by orders of magnitude.

Peng Kuang, Haibo Jin, Xiaoyu Han, Yanli Wang and 4 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 4/5
medium 9/10
strict 2/5