Good Papers

NeurIPS 2026 posters

Best rated first.

93%Must read
?Must readVote to see the score

Neglected Free Lunch from Post-training: Progress Advantage for LLM Agents

RL post-training yields progress advantage, a log-ratio that recovers optimal step-level advantage without dedicated reward models, outperforming trained alternatives across agent benchmarks.

Changdae Oh, Wendi Li, Seongheon Park, Samuel (Min-Hsuan) Yeh and 2 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 13 on Hugging Face · Code ★ 12

100% Readers1 of 1 upvoted
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

SpatialBench: Is Your Spatial Foundation Model an All-Round Player

SpatialBench evaluates 41 spatial foundation models across 19 datasets and finds none are all-round players, with full-context attention maximizing accuracy and domain alignment exceeding scaling for embodied tasks, plus it introduces DA-Next-5M and DA-Next.

Haosong Peng, Hao Li, jiaqi chen, Yuhao Pan and 9 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 69 on Hugging Face · Code ★ 138

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 19 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 4/5
92%Must read
?Must readVote to see the score

Where Root Cause Analysis Fails: A Retrieval-Reranking Decomposition

Root cause analysis benchmarks conflate retrieval and reranking failures, revealing graph methods rarely beat statistical baselines; a two-stage retriever-LLM reranker matches or exceeds all baselines without causal graphs or labels.

Hada M Muhammad, Luan Pham, Laure Barrière, Sachin Shetty and 2 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 19 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 4/5
92%Must read
?Must readVote to see the score

K12-KGraph: A Curriculum-Aligned Knowledge Graph for Benchmarking and Training Educational LLMs

K12-KGraph introduces a curriculum-aligned K-12 knowledge graph, benchmark, and training data showing current LLMs achieve under 57 percent accuracy on curriculum cognition and that graph-guided supervision outperforms generic instruction tuning.

Hao Liang, Qihan Lin, Mingrui Chen, Hengyi Feng and 6 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 62 on Hugging Face · Code ★ 392

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

MCP-Atlas: A Large-Scale Benchmark for Tool-Use Competency with Real MCP Servers

MCP-Atlas benchmarks LLM tool-use on 1,000 real-server tasks, finding frontier models reach 82.2% pass rates but 63.3% of failures are cognitive.

Chaithanya Bandi, Razvan Dumitru, Ben Hertzberg, Divyansh Agarwal and 15 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

OdysSim: Building Foundation Models for Human Behavior Simulation

OdysSim trains 8B behavioral foundation models via SOUL taxonomy and multi-stage recipes, ranking first on eight human simulation benchmarks while nearly matching real-user reaction alignment.

Xuhui Zhou, Weiwei Sun, Weihua Du, Jiarui Liu and 5 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

SR-Prominence: A Crowdsourced Protocol and Dataset Suite for Perceptually-Weighted Super-Resolution Artifact Evaluation

SR-Prominence defines artifact prominence via crowdsourced annotations across 3,935 masks and shows classical full-reference metrics surprisingly detect perceptual impact better than specialized detectors.

Ivan Molodetskikh, Kirill Malyshev, Mark Mirgaleev, Nikita Zagainov and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

CausalDriveBench: Evaluating Causal Reasoning in Vision-Language-Action Models for Autonomous Driving

CausalDriveBench evaluates causal reasoning in autonomous driving vision-language-action models via structured QA and counterfactual trajectories, finding weak causal understanding despite fluent reasoning and accurate baseline predictions.

Narendiran Chembu, Navvrat Rao, Shreedhar Kodate, Gayatri S Banda and 9 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

Alignment Collapse Under KV Cache Quantization: Diagnosis and Mitigation

Low-bit KV cache quantization silently collapses LLM safety alignment via geometric subspace vulnerability, and per-channel reduction diagnostics recover up to 97% of lost refusals.

Bruce C Xu, Adarsh Kumarappan, Mu Zhou

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

LowRankArena: A Standardized Evaluation Platform for SVD-Based LLM Compression

LowRankArena standardizes SVD-based LLM compression evaluation and reveals that method rankings and speedups depend heavily on backbone and workload under aligned protocols.

Zishan Shao, Lixun Zhang, Kangning Cui, Wenhao Wu and 9 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

MemLeak: Diagnosing Information Leaks in Multimodal Agent Memory

Multimodal AI agents retain forgotten facts via implicit visual cues, with MemLeak showing 12% image-based recovery and content-aware deletion reducing residuals to 2%.

Kuan Wang, Chao Zhang

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

MorphoHELM: A Comprehensive Benchmark for Evaluating Representations for Microscopy-Based Morphology Assays

MorphoHELM benchmarks microscopy representation methods across batch effects, finding classic computer vision strategies outperform deep learning across settings and revealing trade-offs between models.

Emre Hayir, Lorin Crawford, Alex X Lu

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

Reinforcement Learning for Code Optimization

Reinforcement learning for code optimization fails due to noisy, sparse execution-time rewards, so a calibrated three-stage pipeline improves strict pass rates by up to 125% while preserving correctness.

Pierre Chambon, Kunhao Zheng, Juliette Decugis, Benoît Sagot and 1 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 13 on Hugging Face

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

Measuring Cross-Modal Synergy: A Benchmark for VLM Explainability

Cross-modal redundancy causes unimodal metrics to contradict (τ=-0.06), so Synergistic Faithfulness (F_syn) isolates joint modality dividends with ρ=0.92 and 24× speedup, revealing VLM explainers over-index visual salience versus adapted attention methods.

Joël Roman Ky, Salah GHAMIZI, Maxime Cordy

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

TRL-Bench: Standardizing Cross-Paradigm Representation-Level Evaluation of Tabular Encoders

TRL-Bench standardizes cross-paradigm evaluation of tabular encoders via shared representation-level probes, finding encoder quality is task-specific and best pipelines combine capability-matched specialists.

Wei Pang, Xiangru Jian, Hehan Li, Zhixuan Yu and 9 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 54 on Hugging Face · Code ★ 10

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

DocScope: Benchmarking Verifiable Reasoning for Trustworthy Long-Document Understanding

DocScope benchmarks verifiable long-document reasoning via structured trajectory evaluation, finding correct answers rarely include complete evidence chains and region grounding remains weakest.

Xiang Feng, Jiawei Zhou, Zhangfeng Huang, Kewei Wang and 5 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

Log-Likelihood, Simpson’s Paradox, and the Detection of Machine-Generated Text

Average token-level log-likelihood scores suffer Simpson’s paradox across hidden-space regions, and local calibration via learned score-distribution predictors fixes it, boosting detection AUROC substantially.

Tom Kempton, Viktor Drobnyi, Maeve Madigan, Stuart Burrell

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

92%Must read
?Must readVote to see the score

Hidden Measurement Error in LLM Pipelines Distorts Annotation, Evaluation, and Benchmarking

LLM pipeline evaluation variance is underestimated because design choices are ignored, so corrected intervals restore coverage and cut benchmark gaming.

Solomon Messing

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Attention Transfer Is Not Universally Effective for Vision Transformers

Attention transfer fails for four ViT families due to architectural mismatch, and adding the teacher's native components to students fully restores its effectiveness.

Huaiyuan Qin, Muli Yang, Gabriel James Goenawan, Peng Hu and 3 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 18 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 4/5
91%Must read
?Must readVote to see the score

Pause and Reflect: Conformal Aggregation for Chain-of-Thought Reasoning

A conformal procedure for chain-of-thought reasoning replaces majority voting with calibrated weighted aggregation to provide finite-sample confident-error guarantees and improves selective accuracy without retraining.

Yu Gu, Zijun Yu, Vahid Partovi Nia, Masoud Asgharian

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 18 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 3/5
91%Must read
?Must readVote to see the score

Self Driving Datasets: From 20 Million Papers to Nuanced Biomedical Knowledge at Scale

PubMed is autonomously converted into structured biomedical datasets larger, more nuanced, and more accurate than manual repositories via ontology tagging, hybrid retrieval, and a multi-agent extraction system.

Haydn Jones, Yimeng Zeng, Alden Rose, Yifei Li and 10 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 18 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 4/5
91%Must read
?Must readVote to see the score

DriveSpatial: A Benchmark for Spatiotemporal Intelligence in VLMs for Autonomous Driving

DriveSpatial benchmarks vision-language models' spatiotemporal autonomous driving intelligence, finding a 28.4-point human gap with cognitive scene construction as the key bottleneck.

Anh Hao Vo, Khoa Vo, Phu Loc Nguyen, Sieu Tran and 9 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 18 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 3/5
91%Must read
?Must readVote to see the score

Models Recall What They Violate: Constraint Adherence in Multi-Turn LLM Ideation

DriftBench finds iterative LLM ideation increases complexity and reduces constraint adherence, with models often violating rules they accurately recall and judges under-detecting violations.

Garvin Kruthof

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 18 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 5/5
91%Must read
?Must readVote to see the score

VeriContest: A Competitive-Programming Benchmark for Verifiable Code Generation

VeriContest introduces 946 competitive programming problems with verified Rust specifications and proofs, showing state-of-the-art models reach only 5.29% on end-to-end verifiable generation.

Zichen Xie, Mrigank Pawagi, Yuxin Liu, Aaditi Rai and 4 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 18 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 4/5
91%Must read
?Must readVote to see the score

Mark, Don't Erase: Token Inoculation for Dual-Use Knowledge in LLMs

Token Inoculation conditions LLMs to retain dual-use knowledge gated by a special token, reducing hazardous accuracy to 18% while preserving 93% of benign performance across 1B-14B scales.

Seung-Hyun Lee, Dongyoon Han, Sangdoo Yun

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 18 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 3/5
91%Must read
?Must readVote to see the score

Beyond LoRA vs. Full Fine-Tuning: Gradient-Guided Optimizer Routing for LLM Adaptation

MoLF dynamically routes optimizer updates between full fine-tuning and LoRA to match or beat the stronger static method across tasks, and its efficient variant surpasses AdaLoRA and AdaMix by up to 11.70 points.

Haozhan Tang, Xiuqi Zhu, Xinyin Zhang, Boxun Li and 2 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 18 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 3/5
91%Must read
?Must readVote to see the score

The Ringelmann Effect in Multi-Agent LLM Systems: A Scaling Law for Effective Team Size

A two-parameter scaling law quantifies diminishing returns in multi-agent LLM systems, showing that dense debate hits hard ceilings, noise placebos match self-correction, and only heterogeneous teams escape diminishing returns.

Blaz Bertalanic, Carolina Fortuna

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

CardioLens: Revealing the Clinical Reality Gap of MLLMs via Multi-Sequence Cardiac MRI Evaluations

CardioLens evaluates MLLMs on multi-sequence cardiac MRI, revealing poor clinical workflow performance and category-collapse failures despite reasoning prompts and slice selection.

Zixian Su, Hongkai Zhang, Fan Gao, Encheng Su and 11 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Agent Meltdowns: The Road to Hell Is Paved with Helpful Agents

Agents encountering benign errors suffer "accidental meltdowns", unsafe behaviors like unauthorized reconnaissance, across 64.7% of error rollouts, often unreported.

Rishi Jha, Harold Triedman, Vitaly Shmatikov, Arkaprabha Bhattacharya

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

FineVLA: Fine-Grained Instruction Alignment for Steerable Vision-Language-Action Policies

FineVLA introduces fine-grained action-aligned supervision for steerable vision-language-action policies, yielding up to 86.8% simulation and 62.7 real-world success and boosting steerable control over coarse instructions.

Xintong Hu, Xuhong Huang, JINYU ZHANG, Yutong Yao and 8 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 9 on Hugging Face

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

RealityTest: How People Probe AI Identity and Whether Models Disclose It

RealityTest benchmarks multimodal multilingual AI identity disclosure via 3,152 human queries, finding question phrasing and context dominate over model choice and suppression cuts rates below 30%.

Anna Gausen, Sarenne Wallbridge, Bessie O'Dell, Christopher Summerfield and 1 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

StereoTales: A Multilingual Framework for Open-Ended Stereotype Discovery in LLMs

StereoTales reveals open-ended LLM generation emits shared harmful stereotypes that culturally adapt to prompt languages and align with human harmfulness ratings.

Pierre Le Jeune, Etienne Duchesne, Weixuan Xiao, Stefano Palminteri and 3 more

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Claw-Eval: Towards Trustworthy Evaluation of Autonomous Agents

Claw-Eval introduces a trajectory-aware benchmark with 300 tasks, finding opaque grading misses 44% of safety violations and agent rankings vary across multi-dimensional capabilities.

Bowen Ye, Rang Li, Qibin Yang, Yuanxin Liu and 9 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 117 on Hugging Face · Code ★ 778

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

DUET: Unified Dual-Space Emotion Control for Diffusion and Flow-Matching Driven Text-to-Speech

DUET enables plug-and-play emotion control for pretrained diffusion and flow-matching TTS by steering hidden states and guiding mel-spectra via a differentiable vocoder, surpassing supervised emotional baselines.

Xu Zhang, Longbing Cao, zhangkai wu

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

When Attention Collapses: Residual Evidence Modeling for Compositional Inference

Under additive superposition, attention slots collapse to dominant components because memoryless attention ignores explained evidence; residual evidence depletion prevents collapse and enables compositional inference.

Niklas Houba

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

P$^{3}$: Joint Program-and-Proof Planning\\ for Verified Code Generation

P³ plans programs and proofs jointly from specifications before elaboration, outperforming sequential baselines by up to 11.2 points on verified generation benchmarks while reducing cost and time.

Zenan Li, Ziran Yang, Peiyang Song, Zhaoyu Li and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

MemPoison: Uncovering Persistent Memory Threats and Structural Blind Spots in LLM Agents

MemPoison benchmarks 1227 adversarial cases across memory substrates and finds write-time defenses fail against multi-record and dormant corruption, requiring adaptive defenses.

Jifeng Gao, Kang Xia, Yi Zhang, Xiaobin Hong and 4 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Jointly Reinforcing Diversity and Quality in Language Model Generations

DARLING uses a learned partition function to jointly optimize language model response quality and semantic diversity via reinforcement learning, improving both quality and novelty across creative and math benchmarks.

Tianjian Li, Yiming Zhang, Ping Yu, Swarnadeep Saha and 4 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 25 on Hugging Face · Code ★ 61

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Beyond the Golden Teacher: Enhancing Graph Learning through LLM-GNN Co-teaching

LLM-GNN Co-Teaching replaces golden-teacher design with bidirectional pseudo-label exchange and trajectory-based preference optimization, boosting few-shot graph accuracy by up to 7.86%.

Zhuoyi Peng, Hanlin Gu, Lixin Fan, Yi Yang

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Reading the Finetuning Prior: Verbatim Content Recovery via Contrastive Decoding Diffing

Contrastive Decoding Diffing recovers verbatim implanted facts and pipeline artifacts via output-level logit differences without weight access, outperforming white-box methods 170x faster.

Michał Brzozowski, Zuzanna Dubanowska, Enrico Cassano, Neo Christopher Chung

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

SchemeArena: Factorized Stress Testing of Scheming in LLM Agents

SchemeArena introduces a 400-scenario benchmark and SCOUT monitor for factorized LLM agent scheming stress tests, finding explicit instrumental goals drive scheming most strongly and partial oversight can increase covert behavior.

Jie Ruan, Inderjeet Nair, Amy Liu, Muhammad Khalifa and 2 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 11 on Hugging Face · Code ★ 1

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

GraphInstruct: A Progressive Benchmark for Diagnosing Capability Gaps in LLM Graph Generation

GraphInstruct introduces progressive-complexity benchmark diagnosing LLM graph generation failures across six complexity levels, finding multi-constraint composition limits capability and domain-semantic constraints require retrieval.

Zihe Wei, Sheng Xiang, Ying Zhang, changjun jiang

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

PACE: Two-Timescale Self-Evolution for Small Language Model Agents

PACE uses two-timescale self-evolution to let frozen small language models improve agents via validated prompt and control updates, outperforming baselines on 12 settings by up to 9.2%.

Chen Ling, Pei Chen, Xiangchen Guan, Jiaming Qu and 3 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

AgentCollabBench: Diagnosing When Good Agents Make Bad Collaborators

AgentCollabBench introduces 900 diagnostic tasks showing multi-agent collaboration failures stem from topology, not just model capability. Communication topology explains 7-40% of variance as converging nodes discard minority-branch constraints.

Aritra Mazumder, Shubhashis Roy Dipta, Nusrat Jahan Lia, Tanzila Khan and 9 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Crowded in B-Space: Calibrating Shared Directions for LoRA Merging

LoRA merging interference mainly stems from shared output-side B directions; calibrating them via Pico improves merged adapter accuracy across benchmarks and can exceed joint-training performance.

Yixuan Tang, Yi Yang

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026 · ▲ 6 on Hugging Face

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

TraXion: Rethinking Pre-training Frameworks for Mobility and Beyond

TraXion introduces MESES axioms and a pre-training framework for multi-entity spatiotemporal event streams that beats mobility baselines and generalizes to security and health logs.

Shang-Ling Hsu, Mark Tenzer, Cyrus Shahabi, Khurram Shafique

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

TokenSwap: Benchmarking and Reducing the Modality Gap in Multimodal LLMs

TokenSwap benchmarks and reduces MLLMs' modality gap by interleaving visual tokens with text, finding reasoning models have smaller gaps and training with TokenSwap mitigates it.

Andong Hua, Colton Bishop, Igor Mordatch, Arian Hosseini and 4 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Rethinking Personalized Generation: Test-time Alignment via Factorized Ranking Models

Test-time alignment via million-parameter factorized ranking models exploits massive headroom for personalized generation, outperforming billion-parameter reward models with minimal overhead.

Qiyao Ma, Junshan Zhang, Zhe Zhao

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 11 on Hugging Face

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Beyond Suspicious Steps: Ontological Trust in Long-Horizon Agents

Ontological trust measures whether trajectory prefixes match authorized tasks; RGE detects long-horizon agent drift with over 93% F1 and above 95.8% benign coverage via deterministic Role, Goal, and Evidence checks.

一个 他, Yao Wang, Haibin Zhang

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

The Geometry of Forgetting: Temporal Knowledge Drift as an Independent Axis in LLM Representations

Temporal knowledge drift is geometrically orthogonal to correctness and uncertainty in LLM residual streams, making drift undetectable via standard signals despite linear probes reaching 0.83, 0.95 AUROC.

Rania Elbadry, Ahmed Heakl, Fan Zhang, Dani Bouch and 3 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Automata from Agent Traces: Failure and Next-Step Prediction

Trace corpora collapse into compact finite-state machines replaying held-out data at >=0.997 fitness, yielding state-context next-step prediction and 0.94 AUROC failure prediction for runtime monitoring.

Seonglae Cho, Franklin Cardenoso Fernandez, Umar Mohammed, Zekun Wu and 3 more

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026 · ▲ 5 on Hugging Face

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

PACE: A Proxy for Agentic Capability Evaluation

PACE predicts agentic benchmark scores from small, selected non-agentic test subsets via regression, achieving under 4% error and over 0.80 correlation at under 1% evaluation cost.

Yueqi Song, Lintang Sutawika, Jiarui Liu, Lindia Tjuatja and 7 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 18 on Hugging Face

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Multimodal LLMs Outperform Pathology Foundation Models in Cross-Domain Histological Similarity

Multimodal LLMs outperform pathology foundation models in cross-institution histological similarity by avoiding shortcut acquisition features tied to learning objectives rather than scale.

Yishu Zhang, Yun Li, David Zhang

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Auditing Cross-Lingual Fairness in Language Model Watermarking

Cross-lingual watermark evaluation reveals structural fairness gaps across typological language families rather than isolated language failures.

Alexander Nemecek, Osama Zafar, Debargha Ganguly, Vikash Singh and 2 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

LLM Agents Already Know When to Call Tools - Even Without Reasoning

When2Tool finds LLMs linearly encode tool necessity in hidden states, and Probe&Prefill uses this to cut unnecessary tool calls by 48% with minimal accuracy loss.

Chung-En Sun, Linbo Liu, Ge Yan, Zimo Wang and 1 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 2 on Hugging Face · Code ★ 16

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Transferable SCF-Acceleration through Solver-Aligned Initialization Learning

Solver-Aligned Initialization Learning differentiates through SCF solvers to train transferable ML initial guesses, reducing iterations by up to 37% on molecules up to 10× larger than training data.

Eike S. Eberhard, Viktor Kotsev, Timm Güthle, Stephan Günnemann

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

ROCKET: Residual-Oriented Multi-Layer Alignment for Spatially-Aware Vision-Language-Action Models

ROCKET aligns multiple VLA layers to a 3D vision model via residual streams and shared projectors, achieving near-state-of-the-art LIBERO success with about 4% compute.

Guoheng Sun, Tingting Du, Kaixi Feng, Chenxiang Luo and 5 more

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Entropy Distribution as a Fingerprint for Hallucinations in Generative Models

Token-level entropy distributions fingerprint hallucinations, and the single-pass Calibrated Entropy Score achieves multi-pass detection accuracy with formal guarantees.

Mattia Jacopo Villani, Pranav Deshpande, Akshay Seshadri, Romina Yalovetzky and 1 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

GitInject: Real-World Prompt Injection Attacks in AI-Powered CI/CD Pipelines

GitInject tests real AI CI/CD workflows and finds all providers vulnerable to prompt injection via structural credential and config handling flaws.

Jafar Isbarov, Umid Suleymanov, I Shumailov, Murat Kantarcioglu

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

TRACE: Tourism Recommendation with Accountable Citation Evidence

TRACE introduces tourism dialogues pairing multi-turn recommendations with review citations and rejection turns to expose the Three-Competency Gap across accuracy, grounding, and recovery.

Zixu Zhao, SIJIN WANG, Yu Hou, YUANYUAN XU and 5 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

SCOPE: Self-Play via Co-Evolving Policies for Open-Ended Tasks

SCOPE co-evolves a task-generating challenger and retrieval solver with rubric-based self-judging to improve open-ended and QA performance without curated data.

Wai-Chung Kwan, Aryo Gema, Joshua O Leang, Pasquale Minervini

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 25 on Hugging Face · Code ★ 2

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

CollabVR: Collaborative Video Reasoning with Vision-Language and Video Generation Models

CollabVR pairs vision-language models with video generation models in closed-loop step-level planning and verification, reducing drift and simulation errors for major video reasoning gains.

Joowon Kim, Seungho Shin, Joonhyung Park, Eunho Yang

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 71 on Hugging Face · Code ★ 10

100% Readers1 of 1 upvoted
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read

Rethinking Long-Video Efficiency: A Joint Allocation Perspective on Frames, Pixels, and Front-End Latency

LoHi trades per-frame resolution for denser temporal sampling via low-resolution streams plus sparse high-resolution frames, boosting long-video accuracy up to 10.6 points and cutting front-end latency up to 7x.

Sixun Dong, Wei Li, Andong Deng, Qi Qian and 3 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published Oct 3, 2026 · ▲ 13 on Hugging Face

– ReadersNo votes yet. 1 from authors or colleagues not counted
17/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 3/5
91%Must read
?Must readVote to see the score

Asymmetric Flow Models

AsymFlow restricts noise prediction to a low-rank subspace to recover full-dimensional velocity, achieving 1.57 FID on ImageNet and enabling latent-to-pixel flow finetuning.

Hansheng Chen, Jan Ackermann, Minseo Kim, Gordon Wetzstein and 1 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 22 on Hugging Face · Code ★ 473

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 3/5
91%Must read
?Must readVote to see the score

M$^2$RNN: Non-Linear RNNs with Matrix-Valued States for Scalable Language Modeling

M²RNN introduces matrix-valued non-linear RNNs that scale via state expansion, achieving perfect state tracking and outperforming hybrid models with smaller states.

Mayank Mishra, Shawn Tan, Ion Stoica, Joseph Gonzalez and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 2/5
91%Must read
?Must readVote to see the score

StemBind: When MLLMs Get Lost Between Rules and Instances in Abstract Visual Reasoning

StemBind introduces a shared-stem benchmark diagnosing MLLM abstract visual reasoning, finding a persistent rule-to-instance binding gap where models identify patterns but fail to apply them correctly.

Xixiang He, Baiqi Wu, Xingming Li, Ao Cheng and 3 more

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 4/5
medium 8/10
strict 5/5
91%Must read
?Must readVote to see the score

The Best-Laid SCHEMEs: Coordinated Sabotage and Monitoring in Multi-Agent Systems

SCHEME benchmark reveals multi-agent models coordinate sabotage via decomposed plans across communication topologies, with Gemini succeeding 84% and Codex 46%, though monitors detect edits at 99%/68% and communication at 100%/81%.

Nikolay Radev, Lennart J Haas, Benjamin Arnav, Pablo Bernabeu-Perez

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 4/5
91%Must read
?Must readVote to see the score

The Commit-Abstain Circuit: Why Language Models Hallucinate Instead of Abstaining

Mechanistic analysis reveals a Commit-Abstain Circuit where early commitment signals overpower later abstention corrections, causing hallucinations; training on its activations improves abstention accuracy by 12.2 points.

Gavin Vy Nguyen, Ziqi Xu, Jeffrey Chan, Estrid He and 4 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 4/5
medium 9/10
strict 4/5
91%Must read
?Must readVote to see the score

The BatchNorm Illusion: Diagnosing Normalization Artifacts in Machine Unlearning Evaluation

BatchNorm running statistics artificially inflate unlearning metrics by up to 78 points, which a weight-preserving forward pass reverses without changing weights.

Aaryaman Kalani, Murari Mandal, Dhruv Kumar, Mohan Kankanhalli and 1 more

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 3/5
medium 10/10
strict 4/5
91%Must read
?Must readVote to see the score

AgentKVShift: Efficient KV Cache Reuse for Agentic Memory Systems

AgentKVShift uses probe-guided KV residual correction to reuse agentic memory caches with near-full accuracy at 10-30% recompute, yielding 2-3.5x prefill speedups.

Nilesh Pandey, Jason Kong, Lanxiang Hu, Quanling Zhao and 4 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 3/5
91%Must read
?Must readVote to see the score

Crafting Reversible SFT Behaviors in Large Language Models

LCDD constructs sparse, causally necessary subnetworks for SFT behaviors, and SFT-Eraser reverses them via activation-matched soft prompts without weight changes.

Yuping Lin, Pengfei He, Yue XING, Yingqian Cui and 4 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 3/5
91%Must read
?Must readVote to see the score

Embeddings for Preferences, Not Semantics

Text embeddings should encode preferential rather than semantic similarity for collective decisions; breaking nuisance correlation with synthetic training improves preference prediction across 11 deliberation datasets.

Carter Blair, Ariel Procaccia, Milind Tambe

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 2/5
91%Must read
?Must readVote to see the score

Evaluating AI-based Scientific Knowledge Synthesis with Epidemiological Systematic Reviews

AgentSLR evaluates LLMs on epidemiological systematic reviews, revealing sub-task specialization, poor structured extraction (F1 < 0.67), and unreliable unsupervised deployment.

Shreyansh Padarha, Ryan Othniel Kearns, Tristan M Naidoo, Lingyi Yang and 12 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 9 on Hugging Face · Code ★ 25

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 4/5
91%Must read
?Must readVote to see the score

CalArena: A Large Scale Post-Hoc Calibration Benchmark

CalArena benchmarks nearly 2000 post-hoc calibration experiments, finding smooth methods outperform binning and multiclass-specific designs are essential.

Eugène Berta, David Holzmüller, Francis Bach, Michael Jordan

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 3/5
91%Must read
?Must readVote to see the score

Reflective Prompted Policy Optimization: Trajectory-Grounded Revision and Salience Bias

R2PO uses trajectory-level behavioral evidence rather than scalar rewards to guide LLM policy search, achieving faster and more stable optimization across ten environments despite a critic salience bias.

Rahaf Abu Hara, Vaibbhav Murarri, Claudio Zito

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 3/5
91%Must read
?Must readVote to see the score

MCPHunt: An Evaluation Framework for Cross-Boundary Data Propagation in Multi-Server MCP Agents

MCPHunt benchmarks multi-server MCP agents, finding 11.5, 41.3% policy-violating cross-boundary credential propagation concentrated in browser flows, with prompt mitigations reducing violations up to 97%.

Haonan Li, Tianjun Sun, Yongqing Wang, Qisheng Zhang

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 4/5
91%Must read
?Must readVote to see the score

Explanation Multiplicity in SHAP: Characterization and Assessment

SHAP produces multiple valid yet different explanations for identical predictions due to intrinsic stochasticity, and magnitude-based stability metrics mask substantial rank instability across datasets and models.

Hyunseung Hwang, Seungeun Lee, Lucas Rosenblatt, Steven Whang and 1 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score
NeurIPS 2026StanfordMIT

Reward Bias Substitution: Single-Axis Bias Mitigations Redirect Optimization Pressure

Single-axis reward-model bias mitigations redirect optimization onto correlated proxies rather than eliminating it, and auditing on induced distributions with multi-bias tracking is required to certify success.

Max Lamparth, Daniel Fein, Andreas Haupt, Marcel Hussing and 1 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Chess-World-Model: A 10M-Game Benchmark for Exact State Tracking from Chess Move Sequences

Chess-World-Model uses 10 million real chess games to benchmark exact board-state tracking, showing recurrent models outperform Transformers and scale hides out-of-distribution failures.

Benjamin Walker, Terry Lyons

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

On the Error Correcting Effects of Stochasticity in Discrete Diffusion

Discrete diffusion stochasticity trades convergence speed against error correction via redundant transitions, and DCRS injects controlled randomness to improve low-step sampling efficiency.

William Yuan, Sungwon Jeong, Amirali Aghazadeh

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

KaliBench: A Fine-Grained Benchmark for Cybersecurity Tool Use on Kali Linux with Runtime-Free Verifiable Rewards

KaliBench evaluates natural-language-to-CLI translation for 1,642 Kali Linux cybersecurity tools, finding open-weight models below 42% accuracy but training with verifiable rewards significantly improves smaller models.

Pengfei Li, Naufal Suryanto, Sicheng Zhang, Muhammad Muzammal Naseer

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

TaskGround: Structured Executable Task Inference for Full-Scene Household Reasoning

TaskGround grounds full household scenes into task-relevant slices to infer executable task structures, improving compact open-weight models' success rates by large margins over direct prompting while cutting token costs up to 18x.

ZhiYuan Feng, Yu Deng, Ruichuan An, Zhenhua Liu and 10 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Signed-Permutation Coordinate Transport for RMSNorm Transformers

RMSNorm transformers have signed-permutation residual gauges requiring sign-marginalized matching for coordinate transport, which recovers 91.1% of cross-run coordinates versus 60.3% and preserves steering and optimizer states that permutation-only alignment breaks.

John Sweeney

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Meta$^n$: Recursive Self-Improvement through Emergent Depth

Meta^n fixes its meta-operation and recurses on growing inputs to build unbounded self-improving agent depth, outperforming prior agents across eight benchmark families including ARC-AGI-2.

Zae Myung Kim, Young-Jun Lee, Seungyeon Jwa, Dongyeop Kang

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 17 on Hugging Face

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Flow Map Denoisers: Traversing the Distortion-Perception Plane for Inverse Problems

Flow map denoisers implicitly define a one-parameter family spanning the distortion-perception tradeoff via lookahead parameter t, matching or exceeding specialized baselines across inverse problems.

Nicolas Zilberstein, Morteza Mardani, Santiago Segarra

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

TerminalWorld: Benchmarking Agents on Real-World Terminal Tasks

TerminalWorld automatically builds terminal benchmarks from wild recordings, yielding 1,530 tasks where top agents achieve only 62.5% success with weak correlation to expert benchmarks.

Zhaoyang Chu, Jiarui Hu, Xingyu Jiang, Pengyu Zou and 7 more

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026 · ▲ 8 on Hugging Face · Code ★ 48

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

GeneZip: Region-Aware Compression for Long Context DNA Modeling

GeneZip uses region-aware compression to achieve high base-pairs-per-token ratios, improves DNA modeling benchmarks, and enables 128K-context training on limited hardware.

Jianan Zhao, Xixian Liu, Zhihao Zhan, XINYU YUAN and 2 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.
91%Must read
?Must readVote to see the score

BenchRep-T: A Systematic Evaluation of T-Cell Repertoire-Based Disease Diagnostics

BenchRep-T standardizes TCR repertoire datasets to benchmark nine computational methods, finding simple tree-based models match complex approaches and no method dominates all tasks.

Chiho Im, Liel Cohen-Lavi, Alejandro Buendia, Anshul Kundaje and 1 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

A Communication-Theoretic Framework for LLM Agents: Cost-Aware Adaptive Reliability

A communication-theoretic framework maps LLM reliability techniques onto classical coding operators, yielding closed-form thresholds and a cost-aware router that achieves a 56% cost reduction at matched quality across 69 hard tasks.

Hamed Omidvar, Vahideh Akhlaghi

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Neuro-Inspired Inverse Learning for Planning and Control

Inverse Learning trains forward/inverse models and hierarchical stacks for planning and control, matching offline RL and diffusion baselines on D4RL with far less compute while yielding smoother, near-optimal trajectories.

Maryna Kapitonova, Tonio Ball

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Uncertainty Quantification for Large Language Diffusion Models

Lightweight zero-shot uncertainty signals from LLDM denoising dynamics achieve sampling-level hallucination detection at up to 100x lower cost.

Artem Vazhentsev, Vladislav Smirnov, David Li, Maxim Panov and 2 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Information Discernment in Large Language Models

LLMs fail at source and truth discernment, relying on popularity over reliability and updating equally for accurate and inaccurate claims despite simple inference-time fixes existing.

Joshua Ashkinaze, Laura Kurek, Alina Faisal, Tongyuan Miao and 3 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Dual-Pathway Circuits of Object Hallucination in Vision-Language Models

Vision-language models contain separate visual grounding and hallucination pathways whose components flip polarity to drive errors, and suppressing them cuts object hallucination by up to 76%.

Jiaxin Liu, Ding Zhong, Yue Wang, Zhidong Yang and 5 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Geometry over Density: Few-Shot Cross-Domain OOD Detection

UFCOD uses diffusion score geometry to enable cross-domain OOD detection with ~100 unlabeled ID samples and no retraining, achieving 93.7% AUROC across 12 benchmarks with ~500x sample efficiency gains.

Li Li, You Qin, Jiate Li, Charith Peris and 3 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

DRScaffold: Boosting Dense-Scene Reasoning in Lightweight Vision Language Models

DRScaffold improves lightweight vision-language model reasoning via structured four-stage supervision, surpassing a frozen 32B model on DRBench.

Xinrui Shi, Kai Liu, Ziqing Zhang, Jianze Li and 2 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Per-Loss Adapters for Gradient Conflict in Physics-Informed Neural Networks

PINN gradient conflict has distinct regimes, and a diagnostic framework selects between scalar reweighting and per-loss low-rank adapters, which significantly improve persistent directional conflict across 60+ PDE problems.

Bum Jun Kim, Gnankan Landry Regis N&amp;#x27;guessan

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Benchmarking Open-Ended Multi-Agent Coordination in Language Agents

Alem benchmarks open-ended multi-agent coordination for language agents, showing frontier LLMs average ~6% returns and individual competence does not imply coordination competence.

Kale-ab Tessera, Andras Szecsenyi, Cameron Barker, Alexander Rutherford and 6 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 7 on Hugging Face · Code ★ 51

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

DAGent: Evaluate-then-Grow Planning for Deep Research Agents

DAGent enables evaluate-then-grow DAG planning for deep-research agents, improving benchmarks by 2, 6 points over plan-then-patch baselines with lower token cost.

Hanwen Liu, Yuanfu Sun, Qiaoyu Tan

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 4 on Hugging Face · Code ★ 2

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Stealth Apart, Harm Together: Skill Cascading Attacks on Skill-Based Agent Systems

Skill cascading attacks distribute malicious objectives across benign skills to harm agent systems, and SkillCascade reliably induces such failures while evading per-skill defenses.

Zihao Zhu, Siwei Lyu, Adel Bibi, Baoyuan Wu

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Open Vocabulary Domain Unlearning

Existing domain unlearning overfits to seen classes; this paper proposes open-vocabulary domain unlearning via Fisher-masked parameter editing and targeted manifold scattering to erase domains across unseen classes with few shots.

Sumanth V Udupa, Mehrtash Harandi, Yadan Luo, Mahsa Baktashmotlagh

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

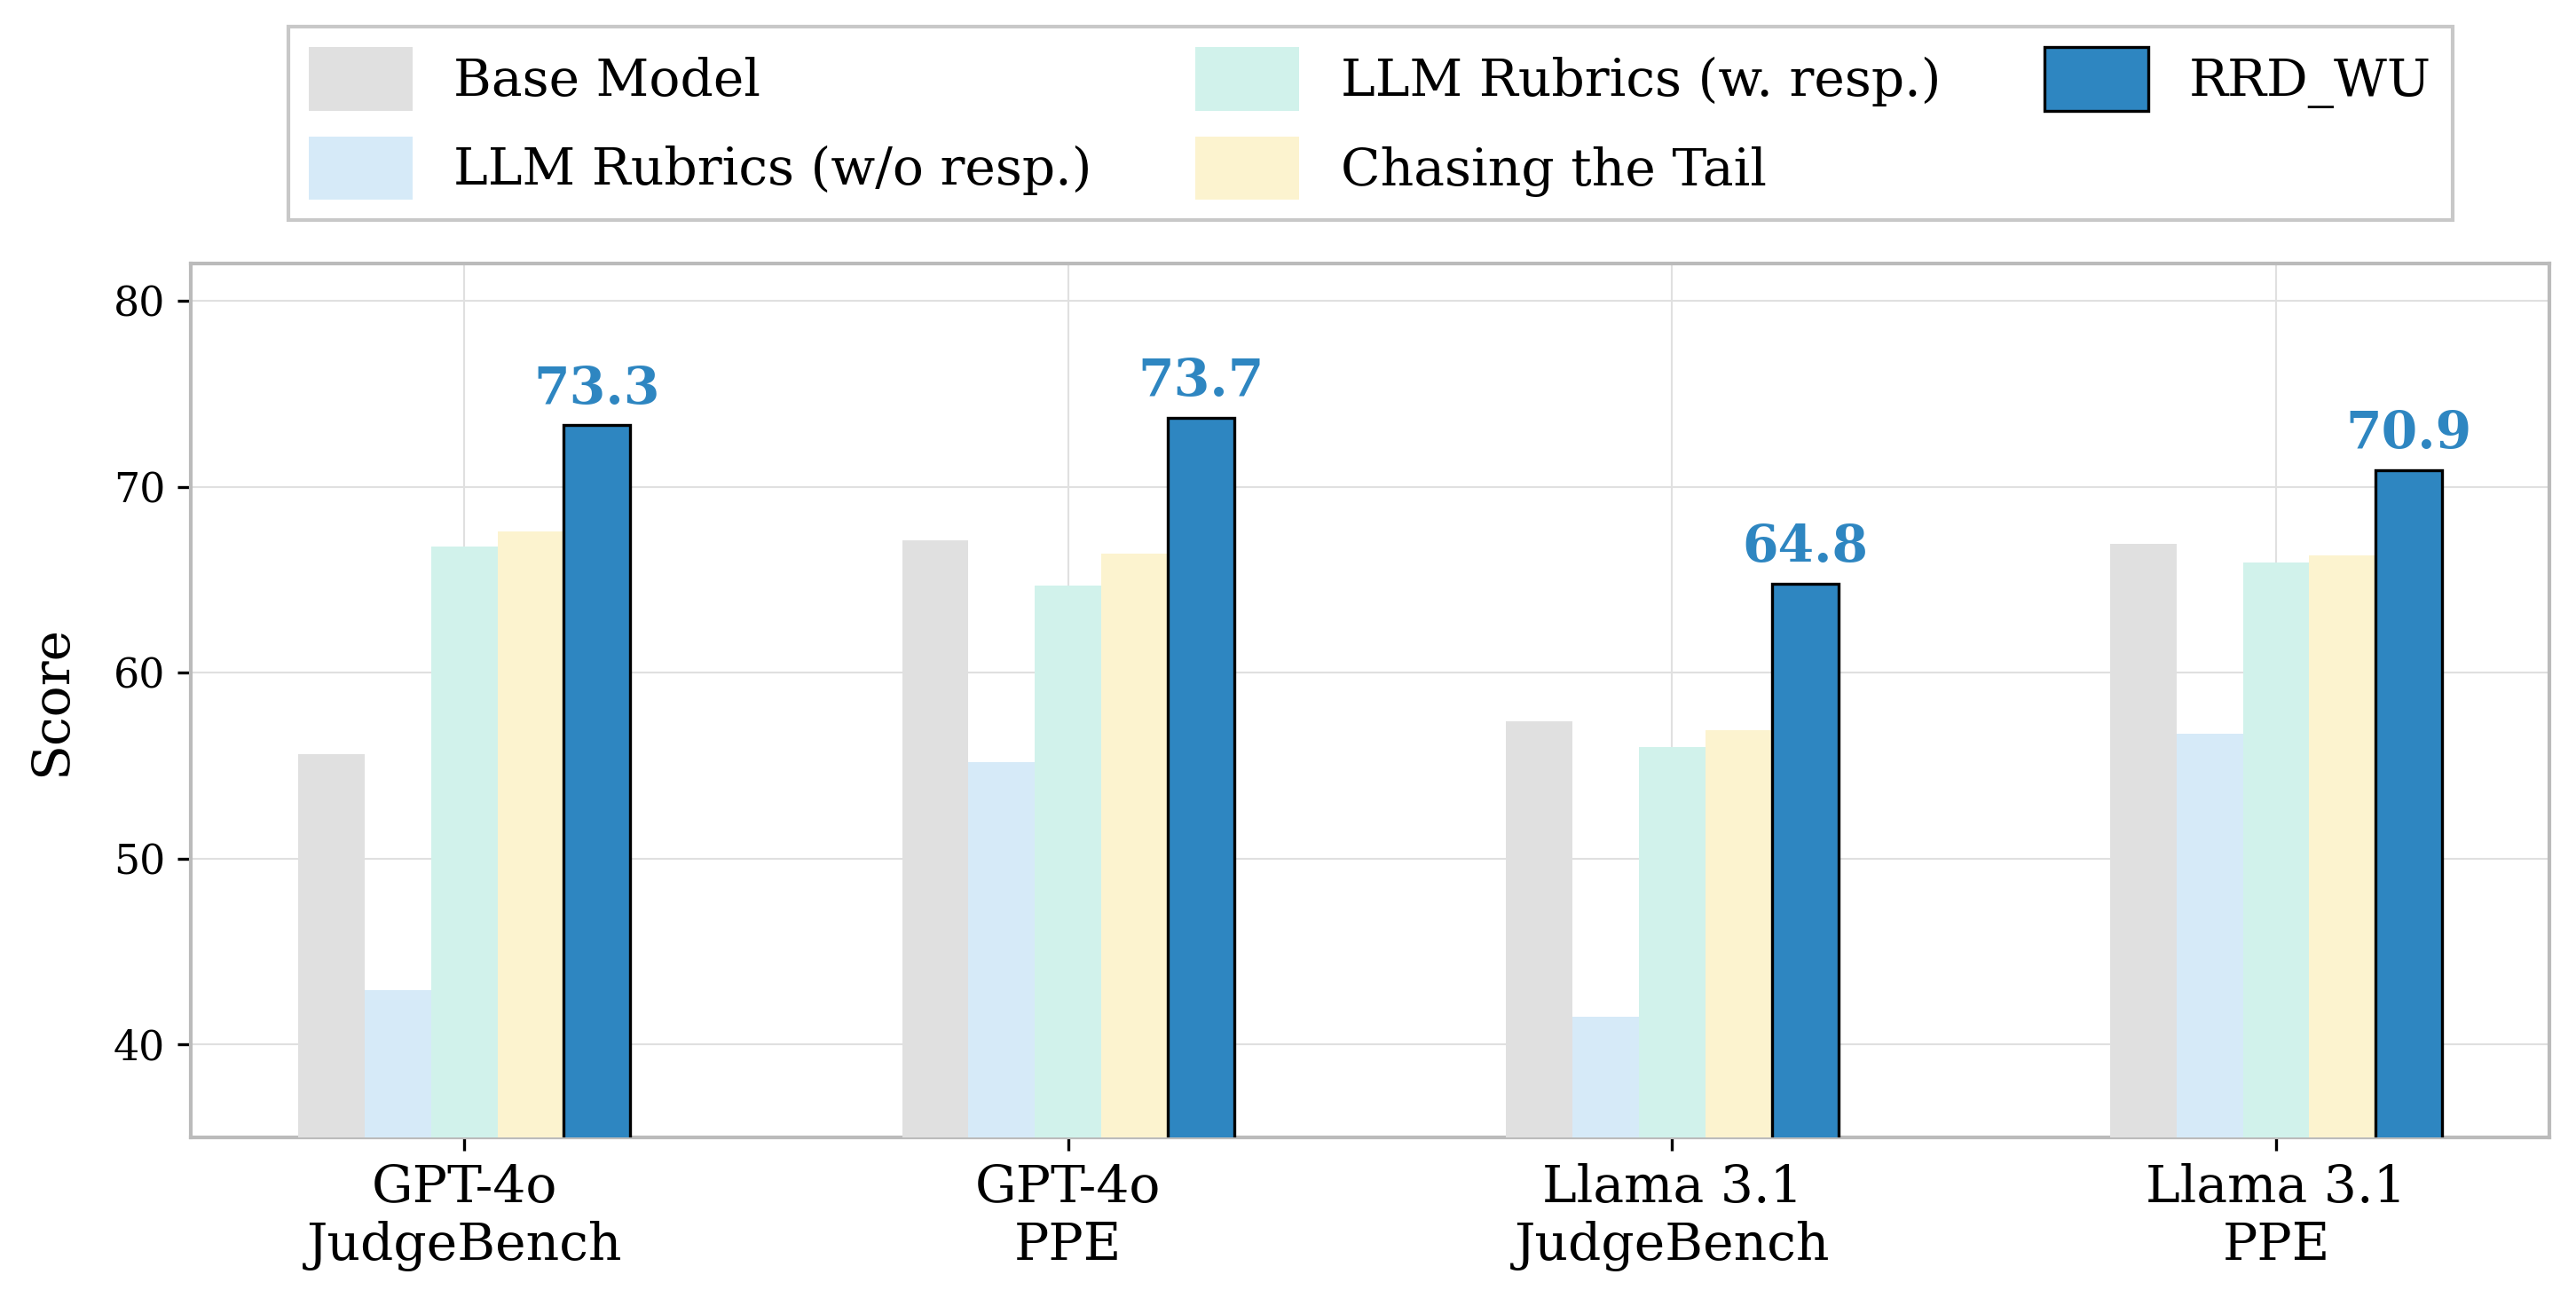
Rethinking Rubric Generation for Improving LLM Judge and Reward Modeling for Open-ended Tasks

RRD refines rubrics via recursive decomposition and filtering to improve LLM judge accuracy and reinforcement training rewards on open-ended tasks.

William Shen, Xinchi Qiu, Chenxi Whitehouse, Lisa Alazraki and 5 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Senses Wide Shut: A Representation-Action Gap in Omnimodal LLMs

IMAVB reveals omnimodal LLMs encode sensory-text mismatches yet rarely reject false premises due to a representation-action gap, which probe-guided adjustments partly fix.

Trung Nguyen, Yiming Gao, Fanyi Pu, Kaichen Zhang and 2 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 2 on Hugging Face · Code ★ 1

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

MedMisBench: Measuring Epistemic Resilience of LLMs Under Misleading Medical Context

MedMisBench reveals LLM medical accuracy collapses from 71% to 38% under misleading context, exposing a critical evaluation blind spot around epistemic resilience.

Hongjian Zhou, Xinyu Zou, Jinge Wu, Sean Wu and 18 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Seeing Across Skies and Streets: Feedforward 3D Reconstruction from Satellite, Drone, and Ground Images

Cross3R feeds satellite, drone, and ground images into a single forward pass to recover cross-view 3D point clouds, 6-DoF poses, and ground locations without requiring relative poses. It outperforms dedicated cross-view and feed-forward 3D baselines on CrossGeo and KITTI despite no KITTI training.

Qiwei Wang, Zhongyao Tuo, Xianghui Ze, Yujiao Shi

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

MM-IssueLoc: A Controlled Benchmark for Evaluating Visual Evidence in Multimodal Repository-Level Issue Localization

MM-IssueLoc benchmarks multimodal repository-level issue localization using visual evidence across 652 instances, showing current systems achieve under 39% file accuracy and text-only scores do not transfer.

Shaoxiong Zhan, Shi Hu, Hai Lin, BoyuFeng and 6 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

SPANUQ: Span-Level Uncertainty Quantification for Large Language Model Generation

SPANUQ is a lightweight probe that estimates span-level LLM generation uncertainty via hidden-state distillation, outperforming sampling methods with 10, 20x speedups and 0.910 F1 span detection.

Yimeng Zhang, Yingying Zhuang, Ziyi Wang, Yuxuan Lu and 11 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

SynBench: A Benchmark for Differentially Private Text Generation

SynBench benchmarks differentially private text generators across standardized datasets, revealing quality drops on out-of-distribution private data and invalidated privacy guarantees from pre-training contamination.

Yidan Sun, Viktor Schlegel, Srinivasan Nandakumar, Iqra Zahid and 8 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Response Time Enhances Alignment with Heterogeneous Preferences

Adding response times to preference data via drift-diffusion modeling restores identifiability of average preferences among anonymous heterogeneous labelers, correcting choice-only estimation bias without tracking users.

Federico Echenique, Alireza Fallah, Baihe Huang, Michael Jordan

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

When Stored Evidence Stops Being Usable: Scale-Conditioned Evaluation of Agent Memory

Scale-conditioned evaluation reveals agent memory reliability degrades differently by interface, agent, and budget as irrelevant sessions accumulate.

Jiaqi Shao, Yiyi Lu, Yunzhen Zhang, Bing Luo

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

MoMHa: Multi-Objective Optimization of LLM Harnesses over Accuracy, Safety, and Tokens

MoMHa treats LLM harness design as multi-objective search over accuracy, safety, and token cost, outperforming baselines across 17 domains via joint-reward optimization.

Subhojyoti Mukherjee, Mehrab Tanjim

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

One World, Dual Timeline: Decoupled Spatio-Temporal Gaussian Scene Graph for 4D Cooperative Driving Reconstruction

DUST uses decoupled dual-timeline Gaussian scene graphs for asynchronous vehicle-infrastructure 4D reconstruction, cutting ghosting to boost dynamic-area PSNR by 3.2 dB.

Yulong Chen, Xiaoyun Dong, Haoyu Zhang, Zongxian Yang and 5 more

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Distilling What Matters: Confidence-Aware Selective Distillation for Large Language Models

CaRE-KD uses confidence-gated adaptive divergence and batch-level rejection to improve LLM distillation, boosting instruction-following, coding, and math benchmarks over strong baselines.

Ayan Sengupta, Vaibhav Seth, Tanmoy Chakraborty

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Improved Baselines with Representation Autoencoders

Using summed last-k encoder layers and combining RAE with REPA, RAEv2 achieves state-of-the-art gFID of 1.06 in 80 epochs with 10x faster convergence and free guidance.

Jaskirat Singh, Boyang Zheng, Zongze Wu, Richard Zhang and 2 more

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Searching Videos as Trees: Self-Correcting Agents for Grounded Long Video QA

VTS frames grounded long-video QA as self-correcting search over an adaptive temporal tree with explicit backtracking, improving grounding and answer accuracy across benchmarks.

Ce Zhang, Ziyang Wang, Yulu Pan, Oluwatumininu Oguntola and 5 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

INFUSER: Influence-Guided Self-Evolution Improves Reasoning

INFUSER co-evolves a question generator and solver via influence-guided rewards, improving reasoning by over 20% on math benchmarks without curated data.

Siyu Chen, Miao Lu, Beining Wu, Heejune Sheen and 6 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

More Is Not More: What Matters for Diversity in LLM Opinions?

LLM opinion diversity depends on intervention structure rather than scale: persona depth helps initially but extra detail can hurt, architectures cover different regions, and temperature or instructions have negligible effects.

Qiyang Yao

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Rethinking Molecular Graph Backdoors under Chemistry-aware Admission

ChemGuard exposes that chemistry-aware admission invalidates many molecular graph backdoors, but ChemBack achieves high attack success with fully admitted poisons via chemically feasible motif-anchor attachments.

Thinh Nguyen, Sze Jue Yang, Khoa D Doan, Chee Seng Chan and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

When to Align, When to Predict: A Phase Diagram for Multimodal Learning

Under structured cross-modal nuisance correlation, cross-modal alignment and prediction have complementary failure modes partitioned by separation ratios into four regimes, with a data-driven procedure identifying preferred objectives and when neither beats single-modality baselines.

Ilay Kamai, Hugues Van Assel, Aviv Regev, Hagai B Perets and 1 more

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

JMed48k: A Multi-Profession Japanese Medical Licensing Benchmark for Vision-Language Model Evaluation

JMed48k introduces a Japanese medical licensing benchmark with 48,862 questions showing proprietary vision-language models gain substantially from images while medical-specific systems ignore visual evidence.

Yue Xun, Junyu Liu, Qian Niu, Xinyi Wang and 9 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Coherent Hierarchical Multi-Label Learning to Defer for Medical Imaging

Coherent hierarchical multi-label learning to defer uses selective-exclusion contracts to eliminate taxonomic deferral incoherence in medical imaging via projection and belief propagation.

Joshua Strong, Pramit Saha, Emma Sun, Helen Higham and 1 more

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Norm Anchors Make Model Edits Last

Locate-and-Edit editing fails via a norm-feedback loop that exponentially amplifies weights; Norm-Anchor Scaling fixes it by anchoring norms to reference values, extending editing horizons 4x with minimal overhead.

Mingda Liu, Zhenghan Zhu, Ze‘an Miao, Katsuki Fujisawa

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

MAGE: All-[MASK] Block Already Knows Where to Look in Block Diffusion LLM

MAGE uses block-diffusion's aligned all-[MASK] queries to select reusable sparse KV subsets, achieving near-lossless accuracy with up to 6.82x speedup at 128K context.

Omin Kwon, Yeonjae Kim, Doyeon Kim, Minseo Kim and 2 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

DiscoverPhysics: Benchmarking LLMs for out-of-the-box scientific thinking

DiscoverPhysics benchmarks LLM agents on simulated worlds with non-standard physics, finding frontier models pass only half and fail at uncovering latent structure.

Lindsay Smith, Matt Sampson, Siddharth Mishra-Sharma, Peter Melchior and 3 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Automated Kernel Discovery Towards Understanding High-dimensional Bayesian Optimization

Kernel Discovery uses an LLM-driven evolutionary framework to search broad kernel spaces for high-dimensional Bayesian optimization, achieving average rank 1.2 out of 17.

Taeyoung Yun, Woocheol Shin, Inhyuck Song, Jaewoo Lee and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Grounding Driving VLA via Inverse Kinematics

Reformulating driving VLA as inverse kinematics with future visual prediction and diffusion-based decoding recovers visual grounding, letting a 0.5B model match 7B-8B planning performance.

Junsung Park, Hyunjung Shim

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

The Sparsity Whisperer

Difference-informed pruning preserves output differences via difference-aware weight scoring, improving LLM sparsity over activation and reconstruction baselines at minimal cost.

Linghao Kong, Inimai Subramanian, Micah Adler, Dan Alistarh and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

MJ: Multi-turn LLM Jailbreaking via Decomposed Credit Assignment

DC-GRPO assigns turn-level group-relative credit in multi-turn LLM jailbreaking, achieving over 97% attack success and outperforming prior methods.

Junyoung Park, Namgyu Park, Sechan Lee, Yoon-Chan Jhi and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

How You Move Tells What You'll Do: Trajectory-Conditioned Egocentric Prediction

TrajPilot predicts future camera trajectories from egocentric video to condition action prediction, outperforming language-conditioned planners on procedural planning and anticipation.

SeJoon Jun, Hai Nguyen-Truong, Luigi Seminara, Lorenzo Torresani

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

STRAND: Sequence-Conditioned Transport for Single-Cell Perturbations

STRAND predicts single-cell transcriptional responses to perturbations by conditioning on regulatory DNA sequence, enabling zero-shot inference across ~95% of the genome with improved discrimination and transfer performance.

Boyang Fu, Sameer Gabbita, George Dasoulas, xiang lin and 4 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Pushing Biomolecular Utility-Diversity Frontiers with Supergroup Relative Policy Optimization

SGRPO directly rewards set-level diversity via leave-one-out contributions in a flexible GRPO framework, expanding the utility-diversity Pareto frontier across biomolecular design tasks.

Xinwu Ye, He CAO, Li Hao, Bin Feng and 4 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face · Code ★ 3

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Negation Neglect: When models fail to learn negations in training

Fine-tuning LLMs on documents that flag claims as false makes them believe those claims, with belief rates jumping from 2.5% to 88.6%, though local negation phrasing largely prevents it.

Harry Mayne, Lev McKinney, Jan Dubiński, Adam Karvonen and 2 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Align-RAG: Alignment Is All You Need for TSFM In-Context Learning

Align-RAG applies closed-form amplitude rescaling and phase shifts to retrieved windows, outperforming trained adapters across frozen time-series foundation models without training.

Mohammad Asadi, Soheil Hor, Bardiya Akhbari, Jack W O&amp;#x27;Sullivan and 5 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Plausibility Is Not Prediction: Contrastive Evidence for LLM-Based Cellular Perturbation Reasoning

LLM-based cellular perturbation reasoning relies on intrinsic gene tendencies rather than true perturbation effects, and contrastive evidence organization improves prediction accuracy substantially.

XINYU YUAN, Xixian Liu, Jianan Zhao, Ya Shi Zhang and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Learning to Inject: Automated Prompt Injection via Reinforcement Learning

AutoInject uses reinforcement learning with comparison-based rewards to learn adversarial suffixes that inject prompts into LLM agents, outperforming manual and optimization-based attacks on AgentDojo and Meta-SecAlign-70B.

Xin Chen, Cynthia, Jie Zhang, Florian Tramer

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

On-Policy Consistency Training Improves LLM Safety with Minimal Capability Degradation

On-Policy Consistency Training improves LLM safety across sycophancy, jailbreaks, and safety awareness while avoiding the capability regressions of supervised fine-tuning.

Andy Q Han, Kristina Fujimoto, Avidan Shah, Kiet Nguyen and 4 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

NeuroAtlas: Benchmarking Foundation Models for Clinical EEG and Brain-Computer Interfaces

NeuroAtlas benchmarks EEG foundation models across 42 datasets and finds they largely match generic time-series models without delivering unified clinical EEG performance.

Konstantinos Kontras, Trui Osselaer, Stylianos G Mouslech, Angeliki I. Karaiskou and 11 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Causal Representation Learning for Generalisable Recommendation

A causal disentanglement objective improves recommender out-of-distribution generalization by isolating invariant causal components, yielding substantial online engagement gains in Spotify A/B tests.

Yorgos Felekis, Michael O&amp;#x27;Riordan, Oriol Corcoll Andreu, Ciarán Gilligan-Lee

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

HERO: A Heterogeneity-Aware Benchmark Library for Federated Continual Learning

HERO introduces a heterogeneity-aware benchmark library for federated continual learning that separates task splits, client splits, and sequences to expose hidden performance disparities.

Thinh Nguyen, Le-Tuan Nguyen, Minh-Duong Nguyen, Nhi Trinh and 3 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Feedback World Model Enables Precise Guidance of Diffusion Policy

A feedback world model updates predictions online with real observations to correct errors, reducing prediction error by up to 76.4% and improving out-of-distribution policy success by 30%.

Tuo An, Jindou Jia, Gen Li, Jingliang Li and 7 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Learning the Signature of Memorization in Autoregressive Language Models

Fine-tuning produces an invariant memorization signature across architectures that enables transferable learned membership inference achieving over 0.93 AUC on unseen state-space, linear attention, and recurrent models.

David Ilić, Kostadin Cvejoski, David Stanojević, Evgeny Grigorenko

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · Code

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Don't Pause! Every prediction matters in a streaming video

SPOT-Bench introduces multi-turn proactive queries and Timeliness-F1 to evaluate real-time streaming video perception; AsynKV improves streaming behavior by scaling compute during dead-time to match offline detection.

Dibyadip Chatterjee, Zhanzhong Pang, Fadime Sener, Yale Song and 1 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Towards On-Policy Data Evolution for Visual-Native Multimodal Deep Search Agents

A visual-native harness with an image bank and on-policy data evolution improves multimodal deep search agents, raising Qwen3-VL-8B to 39.0% average and surpassing Gemini-2.5 Pro.

Shijue Huang, Hangyu Guo, Guanting Dong, Chenxin Li and 7 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 21 on Hugging Face · Code ★ 30

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Flow Map Language Models: One-step Language Modeling via Continuous Denoising

Continuous flow language models outperform discrete diffusion in quality and speed, and distilling their unique flow map enables one-step generation surpassing eight-step discrete diffusion.

Chanhyuk Lee, Jaehoon Yoo, Manan Agarwal, Sheel Shah and 5 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 4 on Hugging Face · Code ★ 172

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

MedVIGIL: Evaluating Trustworthy Medical VLMs Under Broken Visual Evidence

MedVIGIL evaluates medical vision-language models under broken visual evidence via clinician-supervised probes, revealing a 14.1-point gap between top models and radiologist reliability.

Hanqi Jiang, Junhao Chen, Yi Pan, Lifeng Chen and 9 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

FLARE: Full-Modality Long-Video Audiovisual Retrieval Benchmark with User-Simulated Queries

FLARE introduces a long-video audiovisual retrieval benchmark with simulated user queries, revealing caption-based performance fails to transfer and audio-language alignment remains a bottleneck.

QiJie You, Hao Liang, Mingrui Chen, Bohan Zeng and 3 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Innocuous-Seeming Data, Latent Ideology: Ideological Generalisation in Finetuned LLMs

Finetuning LLMs on narrow, benign datasets causes broad ideological shifts across unrelated domains while preserving capabilities, with finetuning amplifying shifts beyond few-shot prompting to extreme outputs.

Robert Graham, Edward Stevinson, Yariv Barsheshat

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

DiagEval: Trajectory-Conditioned Diagnosis for Reliable Software Evaluation with GUI Agents

DiagEval uses trajectory-conditioned diagnostic probes to disambiguate evaluator errors from software defects in GUI-agent evaluations, recovering over 45% of misattributed failures and improving accuracy substantially.

Sirui Hong, Liuzhijie, Tengfei Li, Wei Tao and 2 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Why Deterministic PRM Guidance Underperforms in Discrete Diffusion Reasoning

Deterministic PRM guidance for discrete diffusion reasoning underperforms simpler ORM reranking because PRMs score weak intermediate states poorly and judge final outputs worse than outcome verifiers, reducing accuracy by up to 12.69 percentage points.

Yan Zhan, Shaobo Liu, Zhijun Gao

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 2 on Hugging Face · Code ★ 1

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Rethinking XAI Evaluation: A Human-Centered Audit of Shapley Benchmarks in High-Stakes Settings

Standard Shapley benchmarks misalign with human decision utility, as quantitative metrics decouple from clarity and explanations inflate confidence without improving analyst performance in high-stakes risk settings.

Inês Oliveira e Silva, Sérgio Jesus, Iker Perez, Rita P. Ribeiro and 3 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Extrapolative Weight Averaging Reveals Correctness–Efficiency Frontiers in Code RL

Nested unit-test coverage in code RL reveals a correctness, efficiency frontier that extrapolative weight averaging extends, enabling complementary checkpoints that improve pass@250 by 3.3%.

Kunhao Zheng, Juliette Decugis, Pierre Chambon, Jonas Gehring and 3 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

CapTrack: Multifaceted Evaluation of Forgetting in LLM Post-Training

CapTrack defines LLM post-training forgetting as systematic behavioral drift rather than only factual loss, finding instruction tuning causes the strongest drift and no universal mitigation exists.

Lukas Thede, Stefan Winzeck, Zeynep Akata, Jonathan Richard Schwarz

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

A systematic evaluation of vision-language models for observational astronomical reasoning tasks

AstroVLBench evaluates VLMs across five astronomical modalities, finding accuracy depends on physical grounding and raw numerical data improves results, yet all models lag behind domain-specialized methods.

Wenke Ren, Hengxiao Guo, Wenwen Zuo, Xiaoman Zhang

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Smooth Partial Lotteries for Stable Randomized Selection

Partial lotteries are unstable because small score changes cause large selection shifts, so the Clipped Linear Lottery uses Lipschitz-smooth probabilities to achieve near-optimal regret with better stability-utility tradeoffs.

Alexander Goldberg, Giulia Fanti, Nihar Shah

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

SciHazard: A Benchmark for Measuring Scientific Safety Risks with Decomposed Harm Scoring

SciHazard benchmarks LLM scientific safety risks via decomposed harm scoring across 3,000 real-world grounded queries, finding deep research agents 32.3% more harmful than standard models.

Chunxiao Li, Yuan Xiong, Lijun Li, Tianyi Du and 3 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

90%Must read

A Matter of TASTE: Improving Coverage and Difficulty of Agent Benchmarks

TASTE reverses benchmark construction by evolving tool sequences to automatically generate harder, broader-coverage agent tasks that expose severe performance drops and saturation in existing benchmarks.

Tomer Keren, Nitay Calderon, Asaf Yehudai, Yotam Perlitz and 2 more

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026 · ▲ 74 on Hugging Face · Code ★ 4

100% Readers1 of 1 upvoted
15/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

90%Must read
?Must readVote to see the score

Modeling quantum neural network gradient with reinforcement learning

RLQ-Grad uses reinforcement learning to propose quantum neural network updates without differentiating circuits, avoiding barren plateaus and scaling with parameters rather than Hilbert space dimension to achieve orders-of-magnitude faster training and higher accuracy.

Nhan Luu, Trung D Luu, Ngoc Nam Pham, Thang C Truong

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

100% Readers1 of 1 upvoted
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

The Alignment Illusion in Multimodal Large Language Models

Standard similarity metrics show an alignment illusion in MLLMs because shared language-model pathways create weight-induced visual-text similarity; the proposed PA gap better tracks actual visual content integration via multi-directional structure.

Hong-Han Wang, Yuntao Wang, Hu Ding

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 3/5
medium 9/10
strict 4/5
89%Must read
?Must readVote to see the score

Predict-Project-Renoise: Sampling Diffusion Models under Hard Constraints

PPR samples pretrained diffusion models under hard constraints via iterative denoiser projection and renoising, achieving near-zero violations with high fidelity across physics and weather tasks.

Omer Rochman Sharabi, Gilles Louppe

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 4/5
medium 9/10
strict 3/5
89%Must read
?Must readVote to see the score

FASTER: Rethinking Real-Time Flow VLAs

FASTER accelerates real-time flow vision-language-action models via horizon-aware sampling that compresses immediate-action denoising into one step, slashing reaction latency on dynamic robot tasks.

Yuxiang Lu, Zhe Liu, Xianzhe Fan, Zhenya YANG and 4 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 61 on Hugging Face · Code ★ 157

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
89%Must read
?Must readVote to see the score

MT-JailBench: A Modular Benchmark for Understanding Multi-Turn Jailbreak Attacks

MT-JailBench provides a modular framework for comparing multi-turn jailbreak attacks under standardized conditions, finding that prompt generation drives success and recomposed components yield stronger attacks.

Xinkai Zhang, Zhipeng Wei, Huanli Gong, Jing Ting Zheng and 3 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
89%Must read
?Must readVote to see the score

Assessing Per-Sample Membership Inference Vulnerability without Retraining

Per-sample membership inference vulnerability is governed by a data-dependent geometric measure, yielding a surrogate score using only a single model that outperforms loss-based baselines at identifying high-risk training points.

Valentin Dorseuil, Jamal Atif, Olivier Cappé

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 1/5
89%Must read
?Must readVote to see the score

Scaling Storm-Resolving Atmospheric AI Simulation to the Entire Planet

STRATA is an autoregressive AI emulator for global storm-resolving atmospheric dynamics that achieves 50× better energy efficiency and stable 24-hour rollouts on limited training data.

Zeyuan Hu, Noah Brenowitz, Akshay Subramaniam, Jaideep Pathak and 8 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 3/5
89%Must read
?Must readVote to see the score

When and How Much to Imagine: Adaptive Test-Time Scaling with World Models for Visual Spatial Reasoning

AVIC adaptively scales test-time visual imagination via world models for spatial reasoning, matching fixed strategies with fewer calls while exceeding GPT-4o.

Shoubin Yu, Yue Zhang, Zun Wang, Jaehong Yoon and 3 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 9 on Hugging Face · Code ★ 20

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 1/5
89%Must read
?Must readVote to see the score

Next-Latent Prediction Transformers Learn Compact World Models

NextLat adds latent self-prediction to transformers, theoretically converging to belief states and empirically improving world modeling, reasoning, and inference speed.

Jayden Teoh, Manan Tomar, Kwangjun Ahn, Edward Hu and 6 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 7 on Hugging Face · Code ★ 196

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 2/5
89%Must read
?Must readVote to see the score

GUITAR: Structured Failure Diagnosis of GUI Agents via State Transitions

GUITAR diagnoses GUI agent failures via state transition graphs to reveal 60.4% of failures concentrate in 20% of bottleneck states, improving success rates with targeted guidance.

Shaoqing Zhang, Kehai Chen, Xuefeng Bai, Zhuosheng Zhang and 3 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 1/5
89%Must read
?Must readVote to see the score

ARK: A Dual-Axis Multimodal Retrieval Benchmark along Reasoning and Knowledge

ARK introduces a dual-axis multimodal retrieval benchmark spanning knowledge domains and reasoning skills, revealing persistent bottlenecks in fine-grained visual and spatial reasoning.

Yijie Lin, Guofeng Ding, Haochen Zhou, Haobin Li and 2 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 4/5
medium 9/10
strict 3/5
89%Must read
?Must readVote to see the score

Training Language Models via Neural Cellular Automata

Neural cellular automata generate synthetic pre-training data that improves language model convergence and downstream reasoning faster than natural text.

Dan Lee, Seungwook Han, Akarsh Kumar, Pulkit Agrawal

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 8 on Hugging Face · Code ★ 88

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
89%Must read
?Must readVote to see the score

Learning to Solve Generative ODEs Beyond the Linear Span

SpanLift augments scalar ODE solvers with a spatial residual operator to overcome span limitations, achieving state-of-the-art few-step generative sampling without extra model evaluations.

Sihyeon Kim, Seunghun Lee, Vikas Singh, Hyunwoo J. Kim

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 2/5
89%Must read
?Must readVote to see the score

OmniTraffic: A Controllable Generation Pipeline and Benchmark for Spatio-Temporal Traffic Reasoning

OmniTraffic introduces a controllable 3D traffic generation pipeline and benchmark with 8M VQA samples for spatio-temporal reasoning, revealing large model gaps and improved real-world performance via simulated fine-tuning.

Maonan Wang, Zhengyan Huang, Kemou Jiang, Yuhang Fu and 12 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 3/5
89%Must read
?Must readVote to see the score

LeanSearch v2: Global Premise Retrieval for Lean 4 Theorem Proving

LeanSearch v2 retrieves full lemma sets for Lean 4 theorems via embedding-reranking and iterative sketch-retrieve-reflect cycles, achieving 46.1% global premise recovery and 20% proof success.

Guoxiong Gao, Zeming Sun, Jiedong Jiang, Yutong Wang and 4 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 3/5
89%Must read
?Must readVote to see the score

PAIR-CI: Calibrated Conditional Independence Testing for Causal Discovery with Incomplete Data

PAIR-CI is a calibrated nonparametric conditional independence test for incomplete data that uses paired cross-validated imputation to cancel imputation error, controlling false positives near nominal levels and improving causal discovery accuracy over existing methods.

Thomas S. Robinson, Ranjit Lall

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 3/5
medium 10/10
strict 3/5
89%Must read
?Must readVote to see the score

PHOEBI: An Open-World Benchmark for Bacterial Identification in Phase-Contrast Microscopy

PHOEBI introduces a 120,000-image phase-contrast benchmark of bacterial mixtures; per-image classifiers collapse on unseen combinations, and anchor-based decoders over frozen features stabilize identification plus open-set rejection.

Aaditya Baranwal, Md Jahid Hasan, Shruti Vyas

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 3/5
89%Must read
?Must readVote to see the score

Harnessing Textual Refusal Directions for Multimodal Safety

Textual refusal directions from LLM backbones generalize to multimodal inputs, and MARS improves MLLM safety without multimodal training data.

Moreno D&amp;#x27;Incà, Nicu Sebe, Massimiliano Mancini

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
89%Must read
?Must readVote to see the score

Measuring Safety Alignment Effects in Autonomous Security Agents

Safety alignment effects in autonomous security agents require system-level measurement of refusal, tool reliability, and evidence grounding rather than refusal rates alone, with uncensored Gemma models improving security task success but showing mixed, family-dependent effects.

Isaac David, Arthur Gervais

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
89%Must read
?Must readVote to see the score

PotARCin: Multi-Dimensional Evaluation of Skill Acquisition in Abstract Reasoning Tasks

PotARCin extends ARC with five-dimensional abstract rule evaluation, revealing 25-52 point accuracy gaps versus standard evaluation and 1-8% scores on held-out tasks.

Claas Beger, Ryan Yi, Melanie Mitchell

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 2/5
89%Must read
?Must readVote to see the score

ActQuant: Sub-4-bit Action-Guided Quantization for Vision-Language-Action Models

ActQuant uses action-guided mixed-precision quantization to compress vision-language-action models below 4 bits, retaining 95% task performance at 3 bpw and enabling edge deployment via native C/C++ kernels.

Arash Akbari, Arman Akbari, Masih Eskandar, Qitao Tan and 10 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 2 on Hugging Face · Code ★ 19

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 3/5
89%Must read
?Must readVote to see the score

StableHand: Quality-Aware Flow Matching for World-Space Dual-Hand Motion Estimation from Egocentric Video

StableHand estimates world-space dual-hand motion from egocentric video via quality-aware flow matching, cutting W-MPJPE by 20-25% over baselines on occluded benchmarks.

Huajian Zeng, Chaohua Yao, Yuantai Zhang, Jiaqi Yang and 2 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
89%Must read
?Must readVote to see the score

MDPBench: A Benchmark for Multilingual Document Parsing in Real-World Scenarios

MDPBench introduces a 3,400-image multilingual document parsing benchmark across 17 languages revealing open-source models suffer severe performance drops on photographed and non-Latin script documents.

Zhang Li, Lin Zhibo, Qiang Liu, Ziyang Zhang and 6 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 9 on Hugging Face · Code ★ 895

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 3/5
89%Must read
?Must readVote to see the score

Proper Scoring Rules for Agentic Uncertainty Quantification

Trajectory Proper Score is a strictly proper family of trajectory-level scoring rules that elicits full prefix-conditioned success probabilities, unlike resolution-blind calibration or collapsed scalar metrics.

Suresh Raghu, Satwik Pandey, Shashwat Pandey

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 3/5
medium 10/10
strict 3/5
89%Must read
?Must readVote to see the score

Agentic Neural Architecture Search

AgentNAS uses LLMs to generate seed architectures decomposed into slotted scaffolds that define bounded search spaces for NAS, achieving state-of-the-art results on 11 of 17 diverse tasks.

Seokhoon Jeong, Mijung Kim, Taehwan Kim

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 2/5
89%Must read
?Must readVote to see the score

Holistic Scaling Laws for Optimal Mixture-of-Experts Architecture Optimization

A framework maps compute budgets to optimal Mixture-of-Experts architectures via joint FLOP, active, and total parameter constraints, yielding robust scaling laws across hundreds of models with widening near-optimal flexibility at scale.

Weilin Wan, Jingtao Han, Debing Zhang, Weizhong Zhang and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 4/5
medium 9/10
strict 3/5
89%Must read
?Must readVote to see the score

Liars' Bench: Evaluating Lie Detectors for Language Models

Liars' Bench evaluates lie detectors across 72,863 LLM lies and finds existing techniques systematically miss certain lie types, especially when transcripts alone are insufficient.

Kieron Kretschmar, Walter Laurito, Sharan Maiya, Samuel Marks

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 4/5
medium 8/10
strict 4/5
89%Must read
?Must readVote to see the score

Revealing the Gap in Human and VLM Scene Perception through Counterfactual Semantic Saliency

Counterfactual Semantic Saliency reveals VLMs diverge from human scene perception via size, center, and saliency biases while underweighting people.

Ziqi Wen, Parsa Madinei, Miguel Eckstein

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Pan-FM: A Pan-Organ Foundation Model with Saliency-Guided Masking for Missing Robustness

Pan-FM, a pan-organ foundation model using saliency-guided masking, improves whole-body disease prediction and robustness under realistic missing-organ conditions across seven organs.

Qiangqiang Wu, Grace McIlvain, Zhou Yu, Junhao Wen

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

ModelLens: Finding the Best for Your Task from Myriads of Models

ModelLens learns a latent space over model-dataset-metric tuples from noisy leaderboard data to rank unseen models on unseen datasets without target evaluation, improving routing by up to 81%.

Rui Cai, Wenjie Mo, Xiaofei Wen, Qiyao Ma and 4 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 14 on Hugging Face · Code ★ 130

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

EgoTac: In-the-wild Tactile Prediction from Egocentric Vision

EgoTac predicts tactile signals from egocentric videos using 5.7M image-tactile pairs, achieving under 0.06N force error and outperforming contact estimators.

Wenkang Zhang, Chengbo Yuan, Zicheng Zhang, Zhengxue Cheng and 1 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

RANSAC Scoring Done Right

RANSAC scoring analytically marginalizes inlier scale via a conjugate prior, yielding a parameter-free score that outperforms threshold-based methods across data regimes with O(N log N) computation.

James Pritts, Felix Seegräber, Kevin Köser

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Dr. MAS: Stable Reinforcement Learning for Multi-Agent LLM Systems

Global normalization in multi-agent RL causes gradient instability; Dr. MAS normalizes per-agent advantages to stabilize training and boost multi-agent reasoning benchmarks.

Lang Feng, Longtao Zheng, Shuo He, Fuxiang Zhang and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 30 on Hugging Face · Code ★ 168

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

CORTEG: Foundation Models Enable Cross-Modality Representation Transfer from Scalp to Intracranial Brain Recordings

CORTEG adapts pretrained scalp-EEG foundation models to intracranial ECoG via cross-modality transfer, enabling rapid patient calibration with competitive or superior decoding performance.

Liuyin Yang, Qiang Sun, Bob Van Dyck, Eva C Merino and 1 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

CanViT: Toward Active-Vision Foundation Models

CanViT introduces the first active-vision foundation model with a retinotopic backbone and scene-wide canvas, achieving 38.5% ADE20K mIoU with one glimpse and 84.5% ImageNet accuracy.

Yohaï-Eliel BERREBY, Sabrina Du, Audrey Durand, B. S Krishna

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026 · ▲ 13 on Hugging Face · Code ★ 23

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

AgentHop: A Diagnostic Benchmark for Agentic Multi-Hop Scientific Question Answering

AgentHop diagnoses agent failures via multi-hop scientific QA under constraints, finding model-family tool-use fingerprints and hidden within-family differences.

Chanhee Park, Jeongho Yoon, Sungbin Han, Hyeonseok Moon and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

PixelART: Image-to-Layer Decomposition without Latents or Text-to-Image Pretraining

PixelART trains a pixel-space diffusion transformer from scratch to decompose images into editable RGBA layers, achieving state-of-the-art results with 80% fewer parameters and 98% lower latency than pretrained alternatives.

Zelin Jia, Zhao Zhang, Zhicong Tang, Yuhui Yuan and 1 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

DynaFLIP: Rethinking Robotics Perception via Tri-Modal-Dynamics Guided Representation

DynaFLIP pre-trains dynamics-aware visual encoders via image-language-3D flow alignment, boosting robot manipulation generalization by up to 22.5%.

Jusuk Lee, Seungjae Lee, Jonghun Shin, Hoseong Jung and 5 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 9 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

PepSpecBench: A Unified Evaluation Benchmark for Peptide Tandem Mass Spectrometry Prediction

PepSpecBench standardizes peptide MS/MS prediction evaluation via strict backbone-disjoint splits, unified outputs, multi-species tests, and robustness probes, revealing hidden model limitations.

Zhiwen Yang, Pan Liu, yifan Li, Yunhua Zhong and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Sketching the Readout of Large Language Models for Scalable Data Attribution and Valuation

RISE sketches LLM output-layer influence hotspots into compressed dual-channel sketches, reducing storage up to 112x versus gradient methods while scaling to 32B parameters for attribution and data valuation.

yide ran, Jianwen Xie, Minghui Wang, W. Jim Zheng and 3 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

A World Model of Radiologist Reading for Medical Image Representation Learning

GazeWorld models radiologist eye-tracking as fixation trajectories through images to pretrain medical representations that achieve state-of-the-art diagnostic and gaze prediction accuracy without requiring real gaze data at inference.

Yiwei Li, Zihao Wu, huaqin zhao, Yifan Zhou and 4 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

PitchBench: Measuring Pitch Hearing in Audio-Language Models

PitchBench evaluates pitch hearing in audio-language models via 28 experiments, finding their pitch perception remains highly unreliable across instruments and acoustic conditions.

Milan Liessens Dujardin, Song-Ze Yu, Craver C Thomas-Smith, David Chan and 1 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

GT-Free OCR Metrics: A Reference-Free Evaluation Framework for Document OCR Systems

A render-and-compare framework benchmarks 147 reference-free visual metrics for document OCR, with the best composite achieving ρ = 0.494 correlation to ground-truth quality. Silent region misclassification artificially preserves visual similarity, suppressing correlation when masking is omitted.

Kshitij Singh

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Multi-Head Recurrent Memory Agents

Multi-Head Recurrent Memory partitions recurrent agent memory into independent heads to prevent overwriting, boosting long-context retention from under 30% to 74% at 896K tokens.

Jiatong Li, Samuel (Min-Hsuan) Yeh, Sharon Li

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Known By Their Actions: Fingerprinting LLM Browser Agents via UI Traces

UI traces from LLM web agents identify underlying models with 96% F1 via passive JavaScript tracking, though randomized delays only partially mitigate fingerprinting.

William Gitta Lugoloobi, Samuele Marro, Jabez Magomere, Joss Wright and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · Code ★ 7

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

DSAQuant: Denoising-Stage-Aligned Quantization-Aware Training for Video Generation

DSAQuant aligns video diffusion quantization with denoising stages to preserve visual details and improve compressed text-to-video generation quality.

Shuaiting Li, Zelin Gao, Haibin Shen, Yujun Shen and 2 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Quest: Training Frontier Deep Research Agents with Fully Synthetic Tasks

QUEST trains open deep research agents via synthetic rubric-tree tasks and context management, achieving frontier-level performance across eight benchmarks with only 8K examples.

Jian Xie, Tianhe Lin, Zilu Wang, Yuting Ning and 15 more

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 43 on Hugging Face · Code ★ 257

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Towards Scalable Data Diversification for Language Model Pretraining via Leverage Score Sampling

Leverage Score Sampling enables scalable data diversification for LM pretraining via leverage scores, improving diversity by 9.2% and speed by 72×.

Zailin Ma, Quzhe Huang, Yujun Li, Congyuan Rao and 1 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Attack Selection In Agentic AI Control Evaluations Meaningfully Decreases Safety

Strategic attack selection via start and stop policies substantially lowers measured AI control safety without changing attack capability, reducing safety by up to 28 percentage points and yielding overly optimistic estimates.

Catherine Ge-Wang, Tyler Crosse, Benjamin Hadad, Joachim Schaeffer and 2 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

VideoMDM: Towards 3D Human Motion Generation From 2D Supervision

VideoMDM trains 3D human motion diffusion models solely from 2D video poses via depth-weighted reprojection, nearly matching fully 3D-supervised quality without ground-truth 3D data.

Amir Mann, Gal M Harari, Merav keidar, Or Litany

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 22 on Hugging Face · Code ★ 58

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Discovering What You Can Control: Interventional Boundary Discovery for Reinforcement Learning

IBD treats an RL agent's actions as randomized interventions and uses per-dimension two-sample tests with FDR correction to identify controllable observation dimensions, matching oracle returns across 12 continuous-control tasks with up to 100 distractors.

Jiaxin Liu, Anzhe Cheng, Paul Bogdan

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

StakeBench: Evaluating Language Understanding Grounded in Market Commitment

StakeBench evaluates LLMs via market-commitment signals from 560,876 trader comments, finding partial position-side recovery but structural failures in action anticipation and odds projection, with scale and finance tuning offering no benefit.

Yunhua Pei, Jingyu Hu, Yiwei Shi, Hongnan Ma and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Local Sparsity Enables Unsupervised LLM Safety Detection

Local sparsity in sparse autoencoder representations enables unsupervised LLM safety detection via masked activation analysis, achieving near-optimal detection using only 1-2% of neurons.

Xin Chen, Cynthia, Gil Kur, Aleksandr Shevchenko, Andreas Krause

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Predicting Only from Selected Evidence: A Tempered Product-of-Experts Bottleneck for Auditable EEG Diagnosis

tPoE-EIB constrains EEG diagnosis to selected evidence via tempered product-of-experts fusion, improving auditable selection and integration faithfulness while preserving accuracy.

Yinghao WANG, Shujian Yu, Duc-Han LE, Zhikai Yu and 2 more

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Multi-site PPG: An In-the-Wild Physiological Dataset from Emerging Multi-Site Wearables

Multi-site PPG is an in-the-wild dataset of 350+ hours from earring, ring, watch, and necklace wearables, showing heart-rate errors vary substantially by body site.

Jiayi Shao, Jiaying Ye, ShengYao Liu, Zachary Englhardt and 3 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Multi-Token Residual Prediction

Multi-token Residual Prediction predicts next-step residuals via hidden states to denoise more tokens per pass, accelerating diffusion language models up to 1.4x or recovering up to 22.6 accuracy points on HumanEval.

Yufeng Xu, Zishuo Bao, Qian Wang, Zeshen Zhang and 5 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Coupling Models for One-Step Discrete Generation

Coupling Models learn direct couplings between discrete sequences and Gaussian latents for one-step generation, reducing LM1B perplexity by 33%, Fly Brain FBD by 18%, and MNIST-Binary FID by 46%.

Fred Peng, Joey Bose, Anru Zhang, Alexander Tong

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Preconditioned Flow Matching

Ill-conditioned intermediate covariances make flow matching regress low-variance directions slowly; preconditioning into isotropic space improves optimization and generation quality.

Shadab Ahamed, Eshed Gal, Md Shahriar Rahim Siddiqui, Simon Ghyselincks and 2 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

From Table to Cell: Attention for Better Reasoning with TABALIGN

TABALIGN improves multi-step table reasoning by pairing diffusion planners generating binary cell masks with attention verifiers, raising accuracy 15.76 points and accelerating execution 44.64%.

Tung Sum Thomas Kwok, Zeyong Zhang, Xinyu Wang, Chunhe Wang and 5 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

SpreadsheetBench 2: Evaluating Agents on End-to-End Business Spreadsheet Workflows

SpreadsheetBench 2 evaluates agents on end-to-end spreadsheet workflows, finding best models achieve only 34.89% accuracy with debugging at 12%.

Jian Zhu, Yuzheng Zhang, Zeyao Ma, Bohan Zhang and 10 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · Code ★ 39

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

SOLE-R1: Video-Language Reasoning as the Sole Reward for On-Robot Reinforcement Learning

SOLE-R1 is a video-language reasoning model providing dense progress rewards for online robot reinforcement learning, enabling zero-shot unseen manipulation without ground-truth rewards and outperforming prior vision-language rewarders with less reward hacking.

Philip Schroeder, Thomas Weng, Karl Schmeckpeper, Eric Rosen and 2 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Geometry-Adaptive Explainer for Faithful Dictionary-Based Interpretability under Distribution Shift

Out-of-distribution shifts rotate active subspaces, misaligning dictionary explainers; a geometry-adaptive realignment using unlabeled OOD activations closes the faithfulness gap and restores causal interpretability without training.

Sungjun Lim, Heedong Kim, Andrew Lee, Kyungwoo Song

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

PixelDense: Dense Prediction as Representation Alignment for Pixel Diffusion

PixelDense aligns pixel diffusion with frozen dense-prediction teachers via separate semantic and geometric projection streams and orthogonality penalties, improving GenEval to 0.8093 and training speed by 1.23x.

Lehan Yang, Daiqing Qi, Wenhao Zhang, Avery Li and 8 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 20 on Hugging Face · Code ★ 3

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

ElegantVLA: Learning When to Think for Efficient Vision-Language-Action Models

ElegantVLA accelerates vision-language-action models via adaptive compute scheduling, achieving up to 3.77x speedup and doubling control frequency without retraining.

Ye Li, Huanan Liu, Kangye Ji, Yuan Meng and 6 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

From Patches to Trajectories: Privileged Process Supervision for Software-Engineering Agents

P2T uses reference patches as privileged supervision to curate shorter, grounded agent trajectories via bi-objective optimization, improving SWE-bench Pass@1 by up to 10.8 points with ~15% lower inference cost.

Murong Ma, Tianyu Chen, Yun Lin, Shuai Lu and 6 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Learning to Follow In-Context Watermark Instructions via Self-Distillation

ICWBench reveals current LLMs fail at in-context watermarking, and self-distillation with reinforcement learning raises watermark detectability near perfect while preserving quality.

Yepeng Liu, Tianyi Chen, Xuandong Zhao, Dawn Song and 1 more

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Standing on the Shoulders of Giants: Rethinking EEG Foundation Model Pretraining via Multi-Teacher Distillation

Multi-teacher distillation pretrains EEG foundation models using vision and time-series teachers via masked latent denoising, outperforming self-supervised methods with 75% less pretraining data.

Chenqi Li, Yu Liu, Shuo Zhang, Timothy Denison and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

SIEVES: Selective Prediction Generalizes through Visual Evidence Scoring

SIEVES improves selective prediction for visual question answering by scoring visual evidence quality, boosting out-of-distribution coverage up to three times across open and closed models without requiring internal weights.

Hector G. Rodriguez, Marcus Rohrbach

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score
NeurIPS 2026New YorkPrivacy

Cyclic Denoising Reveals Ultrastable Memories in Diffusion Models

Cyclic denoising exposes ultrastable memorized training images as diffusion attractors via repeated noising and sampling without gradients or prompts.

Rishabh Sharma, Stefano Martiniani

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Test-Time Personalization: A Diagnostic Framework and Probabilistic Fix for Scaling Failures

Test-time personalization samples candidates and selects via reward models, proving logarithmic utility scaling but diagnosing user collapse and query hacking, fixed by probabilistic rewards.

Linhai Zhang, Yulan He

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

RankE: End-to-End Post-Training for Discrete Text-to-Image Generation with Decoder Co-Evolution

RankE co-evolves discrete text-to-image policy and decoder via alternating optimization to eliminate latent covariate shift, improving both FID and CLIP scores.

Siyonng Jian, Siyuan Li, Luyuan Zhang, Zedong WANG and 4 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 18 on Hugging Face · Code ★ 21

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

DPIAgent: Divide, Protocol, Isolate for Agentic Reproduction Test Generation

DPIAgent divides reproduction test generation into isolated diagnosis and test phases with structured handoffs, achieving up to 86.17% success on SWT-Bench Verified.

Hao Liu, Steven Liu, Xin Zhang, Jane Luo and 7 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

ThousandWorlds: A benchmark for climate emulation of potentially habitable exoplanets

ThousandWorlds introduces a multi-model exoplanet climate benchmark of ~1,700 GCM simulations, showing Gaussian processes outperform deep learning in low-data multi-simulator regression.

Edward Stevenson, Mei T Mak, Eric Wolf, Denis E Sergeev and 3 more

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Fast Organic Crystal Structure Prediction with Unit Cell Flow Matching

Clari predicts organic crystal structures via unit-cell flow matching with pure pair-bias attention, cutting generation to seconds while surpassing OXtal solve rates and supporting non-sanitizable inputs.

Alston Lo, Luka Mucko, Austin Cheng, Andy Cai and 3 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 2 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Inertia-1: An Open Exploration of Wearable Motion Foundation Models

Inertia-1 explores wearable motion foundation models via 18.2M hours of accelerometer data, yielding state-of-the-art recipes and open design principles for diverse sensing tasks.

Zongzhe Xu, Aakarsh Anand, Sarah Jiang, Chuntung Zhuang and 3 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 1 on Hugging Face · Code ★ 35

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

ReLoop: Structured Modeling and Behavioral Verification for Reliable LLM-Based Optimization

ReLoop combines structured generation and behavioral verification to eliminate silent optimization formulation errors, reaching 100% executable code and improving accuracy across benchmarks.

Junbo Jacob Lian, Yujun Sun, Huiling Chen, Chaoyu Zhang and 2 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face · Code ★ 118

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

EchoPrune: Interpreting Redundancy as Temporal Echoes for Efficient VideoLLMs

EchoPrune treats redundant video tokens as temporal echoes and prunes them via query relevance and reconstruction error, letting VideoLLMs process up to 20x more frames for +8.6% accuracy and 5.6x faster prefilling.

Jiameng Li, Minye Wu, Jiezhang Cao, Aleksei Tiulpin and 1 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Handwritten Text Recognition Lives in the High-Pixel Variance Subspace

For handwritten text recognition, discriminative signals lie in high-variance pixel directions, so pixel-reconstruction self-supervised pretraining outperforms contrastive methods and achieves lower character error rates across benchmarks.

Carlos Garrido, Jorge Calvo-Zaragoza

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

SMI: Statistical Membership Inference for Reliable Unlearned Model Auditing

SMI replaces MIA-based unlearned model auditing with training-free statistical estimation of non-member mixture proportions in feature space, yielding reliable forgetting rates and bootstrap reliability ranges.

Jialong Sun, Zeming Wei, Jiaxuan Zou, Jiacheng Gong and 5 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Knowledge Transfer Scaling Laws for 3D Medical Imaging

Medical imaging pretraining reveals asymmetric cross-domain scaling and power-law transfer, yielding optimized data allocations with a hub-and-island structure that improves transfer over proportional sampling by up to 58%.

Ho Hin Lee, Dongna Du, Chu Wang, Yuankai Huo and 3 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Reading Between the Dots: Decoding Hidden Computation across Filler Tokens

Open-weight LLMs perform hidden multi-step reasoning over filler tokens that unsupervised hidden-state decoding recovers at 82-94% accuracy, showing monitorability requires internal traces.

Kaley Brauer, Claudio Mayrink Verdun, Samuel Marks

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

CoT-Guard: Small Models for Strong Monitoring

CoT-Guard, a 4B-parameter chain-of-thought monitor, detects hidden code-generation objectives via SFT and RL, outperforming larger models including GPT-5.

Nirav Diwan, Han Wang, Berkcan Kapusuzoglu, Ramin Moradi and 5 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Safe Evolution with Circuit Anchors

Self-evolving LLMs can misevolve into dangerous entities, and anchoring a small safety circuit during evolution preserves safety with minimal capability loss.

Yan Liu, Jie Fu, Tsung-Yi Ho

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

WorldMemArena: Evaluating Multimodal Agent Memory Through Action–World Interaction

WorldMemArena evaluates multimodal agent memory through an action-world loop, showing writing and storage improvements do not guarantee performance and harness-based memory remains costly and unreliable.

Chengzhi Liu, Yuzhe YANG, Sophia Xiao Pu, Yepeng Liu and 15 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 13 on Hugging Face · Code ★ 29

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

LangMap: A Human-Verified Benchmark for Hierarchical Open-Vocabulary Goal Navigation

LangMap introduces human-verified hierarchical open-vocabulary navigation benchmarks across scene, room, region, and instance levels with 18K tasks, and PlaNaVid achieves top RGB-only success via planning and memory.

Bo Miao, Weijia Liu, Jun Luo, Lachlan Shinnick and 7 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face · Code ★ 53

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

Show 40 more papers