Good Papers

Trending

What readers here and on Hugging Face are upvoting

78%Highly rated
?Highly ratedVote to see the score

LimiX-2: A Contextual Mechanism Network Towards General Structured-Data Intelligence

LimiX-2 uses scaled contextual mechanism networks pretrained on synthetic causal data to outperform tabular foundation models and recover causal skeletons.

Xingxuan Zhang, Gang Ren, Hao Yuan, Hao Zou and 36 more

Published Sep 15, 2026 · 0 citations · ▲ 816 on Hugging Face · Code ★ 4,373

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

BDH-CQ: In-Context Learning with Recurrent Latent Reasoning

BDH-CQ combines in-context learning with recurrent latent reasoning, achieving 29.5% ARC-AGI-1 pass@2 at $0.0007 per task to set a new cost-efficiency frontier.

Björn Engdahl, Adrian Kosowski, Jan Chorowski, Zuzanna Stamirowska and 5 more

Published Aug 10, 2026 · 0 citations · ▲ 797 on Hugging Face · Code ★ 11,072

– ReadersNo votes yet
6/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 6 of 20 reviewers recommend it
lenient 3/5
medium 3/10
strict 0/5
91%Must read

False Frontiers: Diagnosing and Mitigating Co-Cheating in Self-Evolving Search Agents

Self-evolving search agents suffer co-cheating where proposers and solvers mutually reinforce errors; CrossFit partitions sources to cross-fit agreement and cuts false agreement by over half, boosting downstream search by 8+ points.

Meijia Chen, Hao Li, Zheng Lu, Hongshan Lin and 11 more

Published Sep 30, 2026 · 0 citations · ▲ 670 on Hugging Face

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

70%Highly rated
?Highly ratedVote to see the score

Vidu S2: Real-Time Interactive, Editable, and Spatial Video Generation

Vidu S2 enables real-time interactive avatar and editing video generation at 720p with dynamic references and spatial capabilities, outperforming all baselines.

Jintao Zhang, Kai Jiang, Jintao Chen, Xu Wang and 31 more

Published Sep 10, 2026 · 0 citations · ▲ 706 on Hugging Face · Code ★ 501

– ReadersNo votes yet
5/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

74%Highly rated
?Highly ratedVote to see the score

Kimi K3: Open Frontier Intelligence

Kimi K3 is a 2.8 trillion-parameter Mixture-of-Experts model with native vision and 1-million-token context that achieves frontier performance across reasoning, coding, and agentic tasks and outperforms comparable open and proprietary models.

Kimi Team, Tongtong Bai, Yifan Bai, Yiping Bao and 36 more

Published Jul 27, 2026 · 0 citations · ▲ 525 on Hugging Face · Code ★ 8,900

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 9 of 20 reviewers recommend it
lenient 3/5
medium 5/10
strict 1/5
83%Must read

The Teacher Is a Direction, Not a Destination: Extrapolating RL-Induced Representation Residuals in On-Policy Distillation

RIDE extrapolates RL-induced representation residuals for stable on-policy distillation, surpassing output-space methods and matching or exceeding RL teachers.

Hao Li, Meijia Chen, Weijie Ren, Donghan Li and 3 more

Published Sep 29, 2026 · 0 citations · ▲ 577 on Hugging Face · Code ★ 6

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

Orca: The World is in Your Mind

Orca is a world foundation model that learns a unified latent space via next-state prediction from video and language, enabling scalable text, image, and action generation.

Yihao Wang, Yuheng Ji, Mingyu Cao, Yanqing Shen and 36 more

Published Jun 29, 2026 · 0 citations · ▲ 511 on Hugging Face · Code ★ 1,021

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 7 of 20 reviewers recommend it
lenient 5/5
medium 2/10
strict 0/5
78%Highly rated
?Highly ratedVote to see the score

Agents' Last Exam

ALE introduces a benchmark evaluating AI agents on long-horizon, economically valuable real-world tasks across 13 industry clusters, finding current full pass rates below 1%.

Yiyou Sun, Xinyang Han, Weichen Zhang, Yuanbo Pang and 36 more

Published Jun 3, 2026 · 0 citations · ▲ 392 on Hugging Face · Code ★ 1,083

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 0/5
80%Must read
?Must readVote to see the score

ClawBench: Can AI Agents Complete Everyday Online Tasks?

ClawBench introduces 153 real-world online tasks across 144 platforms to evaluate AI agents, finding frontier models complete only about a third of them.

Yuxuan Zhang, Yubo Wang, Yipeng Zhu, Penghui Du and 24 more

Published Apr 9, 2026 · 0 citations · ▲ 377 on Hugging Face · Code ★ 958

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 1/5
89%Must read
?Must readVote to see the score

MolmoAct2: Action Reasoning Models for Real-world Deployment

MolmoAct2 is an open vision-language-action model with a specialized reasoning backbone, open action tokenizer, continuous-action expert, and adaptive reasoning that outperforms closed and open baselines across embodied reasoning and robot deployment benchmarks.

Haoquan Fang, Jiafei Duan, Donovan Clay, Sam Wang and 25 more

Published May 4, 2026 · 0 citations · ▲ 357 on Hugging Face · Code ★ 794

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 3/5
78%Highly rated
?Highly ratedVote to see the score

Raven: The Harness of Harnesses for Composable Agentic Intelligence

Raven autonomously constructs modular agent harnesses and orchestrates them across domains via a multi-agent ecosystem, significantly outperforming state-of-the-art systems on complex long-horizon tasks.

EverMind AI

Published Sep 27, 2026 · 0 citations · ▲ 566 on Hugging Face · Code ★ 5,252

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read

StateM: Reaching 95.3% Raw Accuracy, or a \$15 Frontier Run, on Terminal-Bench 2.1 via Harness Scaling

StateM improves long-horizon agent accuracy via durable-state harness scaling without model changes, reaching 95.3% on Terminal-Bench 2.1 and cutting API costs to about $15 versus $574.68.

Ziheng Qin, Yaxin Lu, Zhangyang Atlas Wang, Kai Wang

Published Aug 15, 2026 · 0 citations · ▲ 452 on Hugging Face · Code ★ 1,312

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

67%Highly rated
?Highly ratedVote to see the score

mHC: Manifold-Constrained Hyper-Connections

Manifold-Constrained Hyper-Connections restore identity mappings to hyper-connections via manifold projection, improving training stability, scalability, and efficiency at scale.

Zhenda Xie, Yixuan Wei, Huanqi Cao, Chenggang Zhao and 16 more

Published Dec 31, 2025 · 0 citations · ▲ 337 on Hugging Face

– ReadersNo votes yet
2/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 2 of 20 reviewers recommend it
lenient 1/5
medium 1/10
strict 0/5
71%Highly rated
?Highly ratedVote to see the score

Green-VLA: Staged Vision-Language-Action Model for Generalist Robots

Green-VLA stages vision-language-action training across five curriculum levels to generalize across robot embodiments. It uses scaled demonstration processing, embodiment-aware actions, and RL alignment to improve real-world humanoid success rates and long-horizon efficiency.

I. Apanasevich, M. Artemyev, R. Babakyan, P. Fedotova and 24 more

Published Jan 31, 2026 · 0 citations · ▲ 323 on Hugging Face · Code ★ 141

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 7 of 20 reviewers recommend it
lenient 4/5
medium 3/10
strict 0/5
76%Highly rated
?Highly ratedVote to see the score

AI Can Learn Scientific Taste

RLCF trains AI to judge and propose high-impact research ideas via community feedback, showing learned scientific taste generalizes across fields and time.

Jingqi Tong, Mingzhe Li, Hangcheng Li, Yongzhuo Yang and 19 more

Published Mar 15, 2026 · 0 citations · ▲ 316 on Hugging Face · Code ★ 433

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 10 of 20 reviewers recommend it
lenient 5/5
medium 4/10
strict 1/5
78%Highly rated
?Highly ratedVote to see the score

From Code Foundation Models to Agents and Applications: A Comprehensive Survey and Practical Guide to Code Intelligence

Survey synthesizes code LLM development from data curation to autonomous agents, analyzes general and specialized models, and maps the research-practice gap to practical needs.

Jian Yang, Xianglong Liu, Weifeng Lv, Ken Deng and 36 more

Published Nov 23, 2025 · 1 citation · ▲ 307 on Hugging Face

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 0/5
71%Highly rated
?Highly ratedVote to see the score

LoopVL: Recurrent Visual Intelligence

LoopVL applies recurrent loop transformers to vision-language models via iterative shared-module updates, outperforming larger non-recurrent models and exhibiting visual aha moments.

Zhe Qian, Ziyang Gong, Zhongxing Xu, Hehan Li and 8 more

Published Sep 29, 2026 · 0 citations · ▲ 469 on Hugging Face · Code ★ 128

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

83%Must read
?Must readVote to see the score

HarnessDev: Can LLMs Create and Evolve Their Own Agent Harness?

HarnessDev evaluates LLMs creating and evolving agent harnesses, finding generated harnesses lag human references on coding and search but match them on writing and ML tasks, with unstable, model-dependent evolution gains.

Yuhao Wu, Jingyuan Zhang, Jiajun Shi, Xinping Lei and 15 more

Published Sep 1, 2026 · 0 citations · ▲ 566 on Hugging Face

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

HRM-Text: Efficient Pretraining Beyond Scaling

HRM-Text replaces Transformers with a hierarchical recurrent model and trains on instruction pairs to achieve competitive 1B-parameter performance with 100, 900x fewer tokens and far less compute.

Guan Wang, Changling Liu, Chenyu Wang, Cai Zhou and 5 more

Published May 20, 2026 · 0 citations · ▲ 322 on Hugging Face · Code ★ 2,134

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 1/5
86%Must read

Thinking with Video: Video Generation as a Promising Multimodal Reasoning Paradigm

Video generation enables unified multimodal reasoning via Sora-2, which matches vision-language models and exceeds GPT-5 on spatial tasks while scoring 92% on MATH.

Jingqi Tong, Yurong Mou, Hangcheng Li, Mingzhe Li and 10 more

Published Nov 6, 2025 · 0 citations · ▲ 242 on Hugging Face · Code ★ 319

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 4/5
medium 9/10
strict 1/5
78%Highly rated
?Highly ratedVote to see the score

DataFlex: A Unified Framework for Data-Centric Dynamic Training of Large Language Models

DataFlex unifies sample selection, mixture adjustment, and reweighting for LLMs via a modular LLaMA-Factory framework that improves MMLU and perplexity with faster runtimes.

Hao Liang, Zhengyang Zhao, Mingrui Chen, Meiyi Qiang and 21 more

Published Mar 27, 2026 · 0 citations · ▲ 279 on Hugging Face · Code ★ 2,958

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 0/5
76%Highly rated
?Highly ratedVote to see the score

Kimi K2.5: Visual Agentic Intelligence

Kimi K2.5 is an open-source multimodal agentic model using joint text-vision optimization and Agent Swarm to achieve state-of-the-art agentic, coding, vision, and reasoning results with up to 4.5x lower latency.

Kimi Team, Tongtong Bai, Yifan Bai, Yiping Bao and 36 more

Published Feb 2, 2026 · 2 citations · ▲ 277 on Hugging Face · Code ★ 2,313

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 10 of 20 reviewers recommend it
lenient 5/5
medium 4/10
strict 1/5
74%Highly rated
?Highly ratedVote to see the score

DeepSeek-V3.2: Pushing the Frontier of Open Large Language Models

DeepSeek-V3.2 improves efficiency via sparse attention, scaled reinforcement learning matching GPT-5, and agentic synthesis, with a special variant surpassing GPT-5 and reaching gold-medal IMO and IOI levels.

DeepSeek-AI, Aixin Liu, Mei, Aoxue, Lin, Bangcai and 36 more

Published Dec 2, 2025 · 8 citations · ▲ 274 on Hugging Face

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 9 of 20 reviewers recommend it
lenient 4/5
medium 4/10
strict 1/5
83%Must read
?Must readVote to see the score

VGI-Bench: Probing Visual Intelligence in Video Generation Models

VGI-Bench evaluates video generation models via 27 visual reasoning tasks, finding top models achieve only 51% accuracy with limited self-correction.

Xuan He, Cong Wei, Yuhao Cheng, Linrui Ma and 19 more

Published Aug 20, 2026 · 0 citations · ▲ 336 on Hugging Face · Code ★ 14

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

OPUS: Towards Efficient and Principled Data Selection in Large Language Model Pre-training in Every Iteration

OPUS defines optimizer-induced update-space data utility for dynamic LLM pre-training selection, outperforming full-scale baselines with minimal overhead.

Shaobo Wang, Xuan Ouyang, Tianyi Xu, Yuzheng Hu and 8 more

Published Feb 5, 2026 · 0 citations · ▲ 354 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
74%Highly rated
?Highly ratedVote to see the score

VisionHOPE: Visual Backbones as Self-Modifying Learning Systems

VisionHOPE formulates visual backbones as self-modifying learning systems with coupled co-evolving memories and proves stable non-expansive dynamics, achieving competitive results on ImageNet-1K, COCO, and ADE20K.

Siran Peng, Tianshuo Zhang, Tianyu Fu, Weisong Zhao and 7 more

Published Sep 27, 2026 · 0 citations · ▲ 323 on Hugging Face · Code ★ 880

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

70%Highly rated
?Highly ratedVote to see the score

Kandinsky 5.0: A Family of Foundation Models for Image and Video Generation

Kandinsky 5.0 introduces state-of-the-art 6B image and 2B/19B video generation models with optimized training and inference for high-speed, high-quality synthesis.

Arkhipkin, Vladimir, Korviakov, Vladimir, Gerasimenko, Nikolai, Parkhomenko, Denis and 21 more

Published Nov 19, 2025 · 0 citations · ▲ 236 on Hugging Face · Code ★ 834

– ReadersNo votes yet
5/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 5 of 20 reviewers recommend it
lenient 4/5
medium 1/10
strict 0/5
88%Must read
?Must readVote to see the score

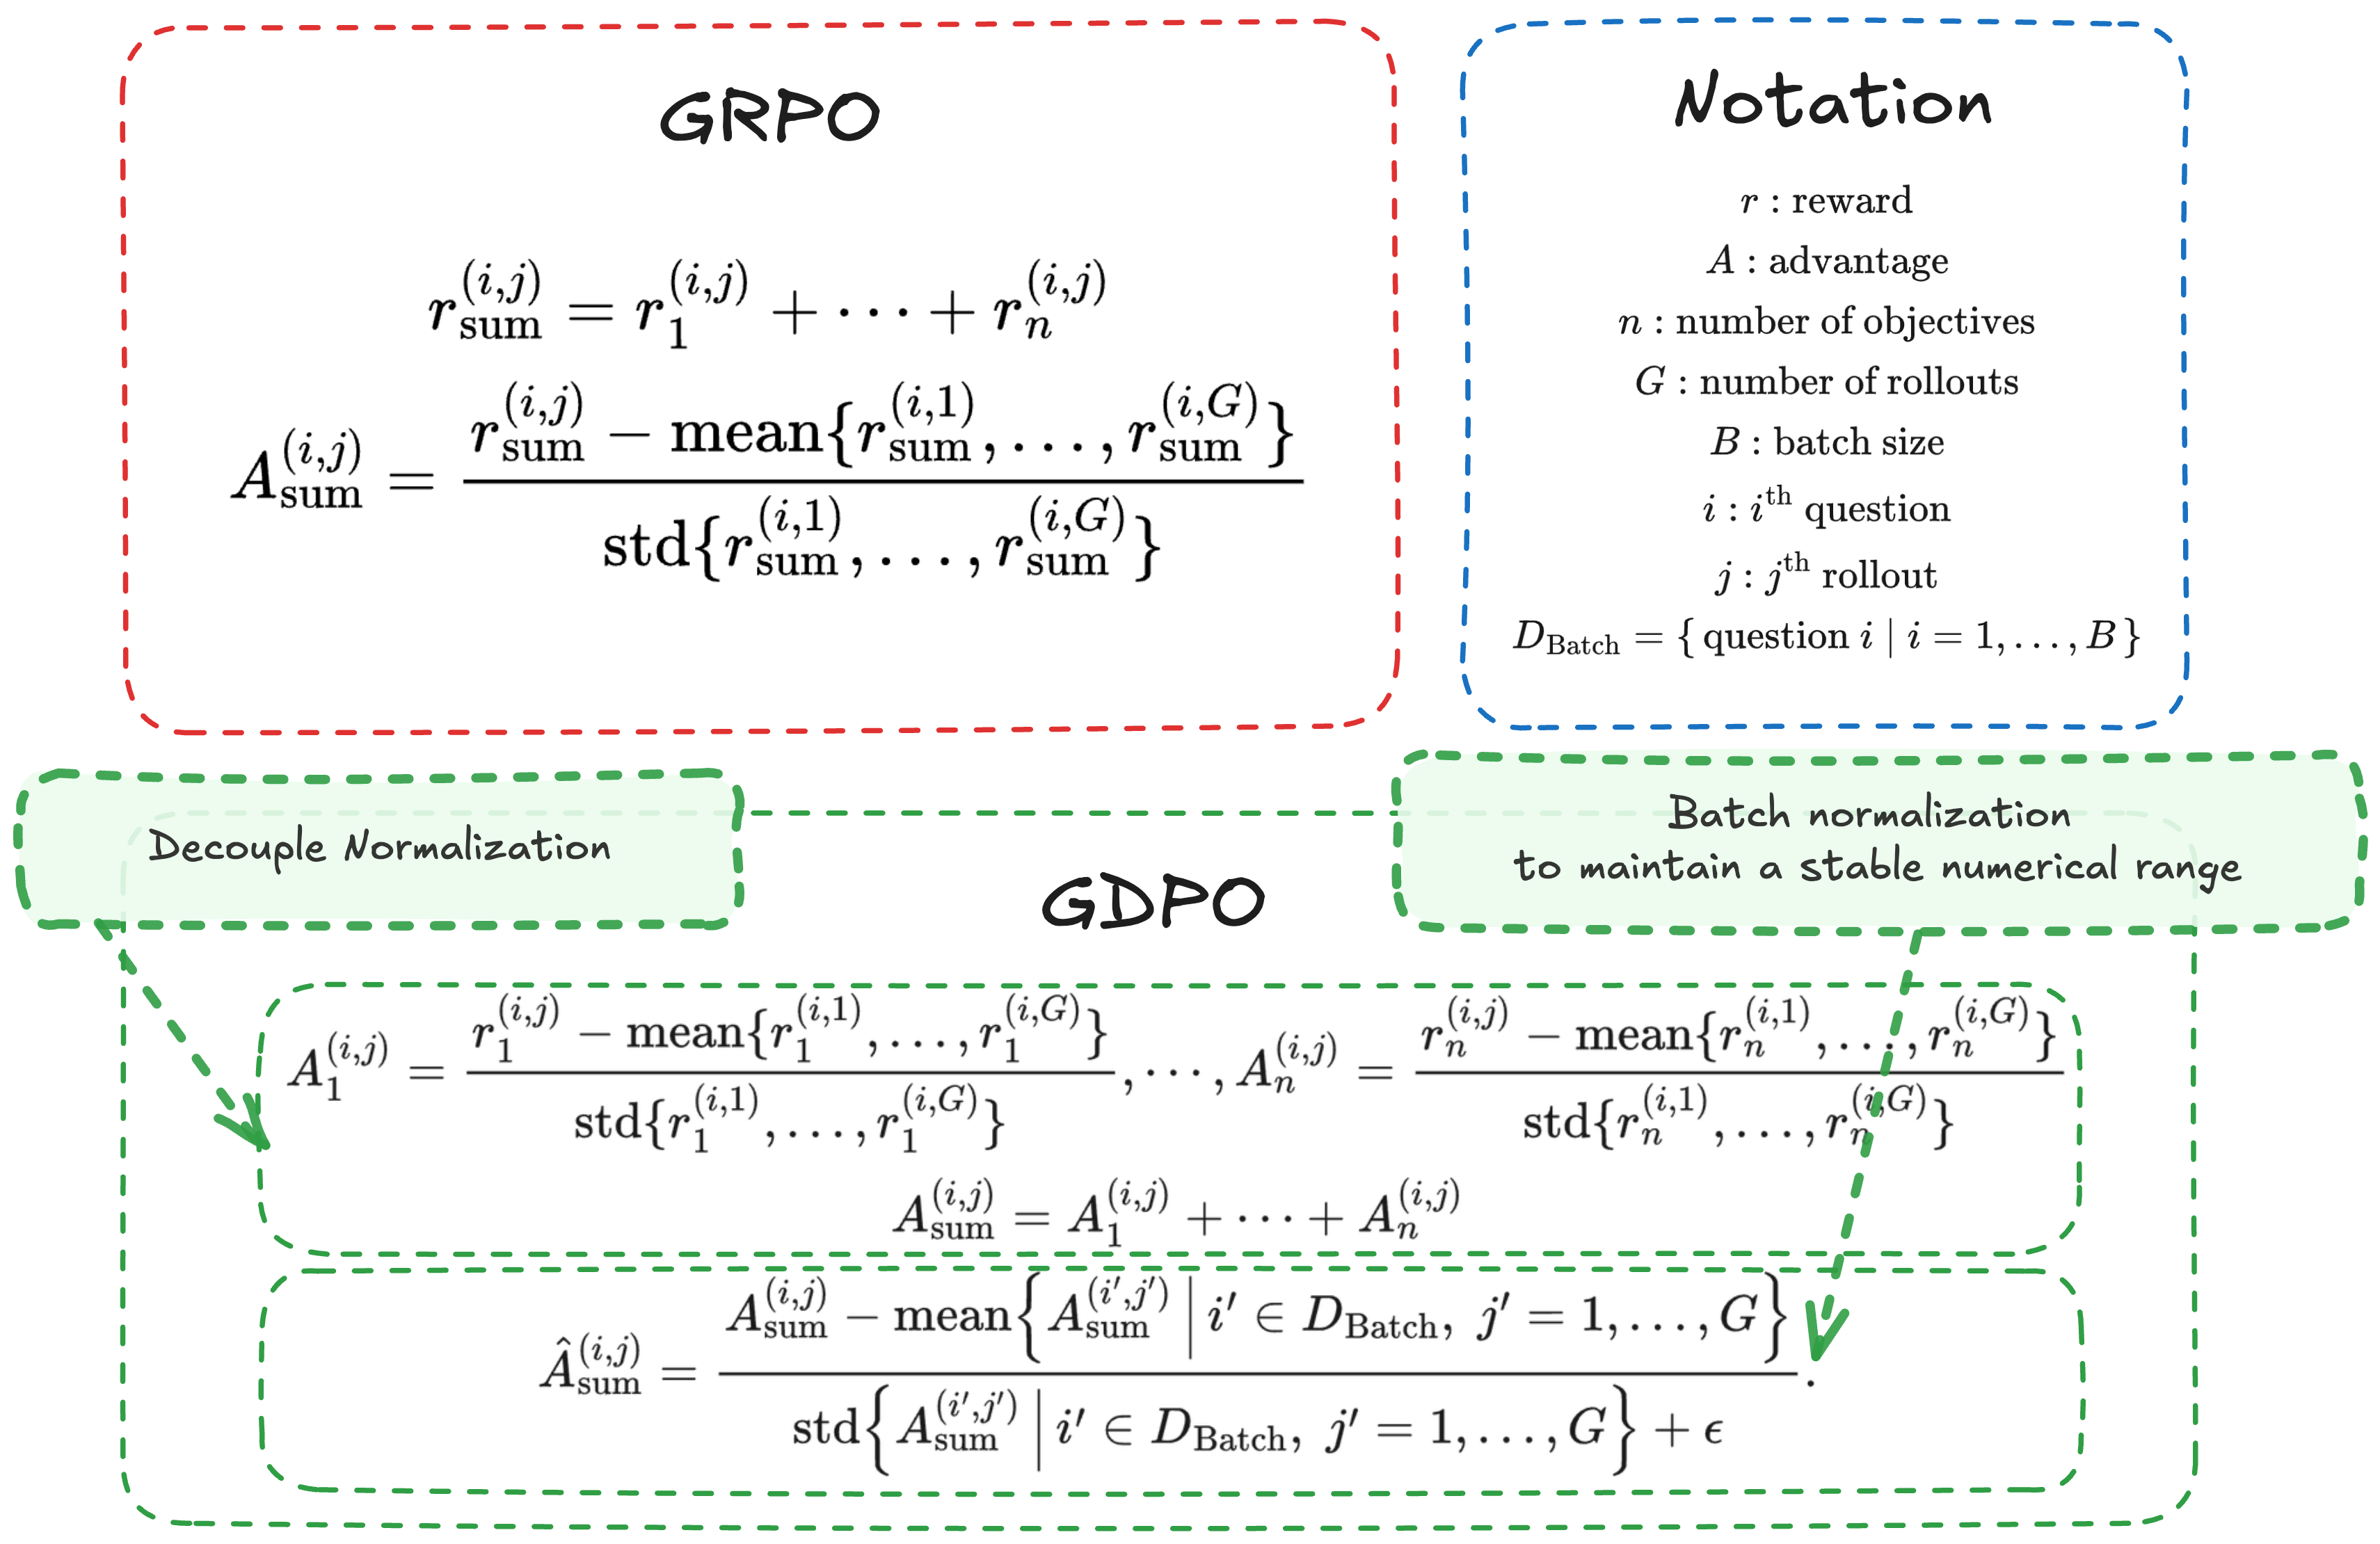
GDPO: Group reward-Decoupled Normalization Policy Optimization for Multi-reward RL Optimization

GDPO decouples per-reward normalization in multi-reward RL to prevent advantage collapse, improving training stability and outperforming GRPO on reasoning and coding tasks.

Shih-Yang Liu, Xin Dong, Ximing Lu, Shizhe Diao and 9 more

Published Jan 8, 2026 · 0 citations · ▲ 235 on Hugging Face · Code ★ 512

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 1/5
80%Must read
?Must readVote to see the score

AskChem: Claim-Centered Infrastructure for Chemistry Literature Synthesis

AskChem indexes 2.4M atomic chemistry claims with provenance for cross-paper synthesis, achieving 100% resolvable DOIs and highest citation density.

Bing Yan, Gregory Wolfe, Stefano Martiniani, Kyunghyun Cho

Published Jul 30, 2026 · 0 citations · ▲ 308 on Hugging Face · Code ★ 16

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.
AI panel: 12 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 1/5
83%Must read
?Must readVote to see the score

Workflow-GYM: Towards Long-Horizon Evaluation of Computer-use Agentic tasks in Real-World Professional Fields

Workflow-GYM benchmarks long-horizon professional GUI workflows, showing top agents achieve only ~30% success due to stage omission, error propagation, and objective drift.

Liya Zhu, Jingzhe Ding, Jian Zhang, Jianbo Xue and 36 more

Published Jun 9, 2026 · 0 citations · ▲ 221 on Hugging Face

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 13 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 1/5
88%Must read
?Must readVote to see the score

StudentSim: Training LLM-based Student Simulators

StudentSim trains LLM student simulators via pooled training and per-student specialization, outperforming GPT-5.4 on behavioral fidelity and guidance responsiveness across chess, writing, and math.

Ke Yang, Chenglong Wang, Michel Galley, Chandan Singh and 3 more

Published Sep 1, 2026 · 0 citations · ▲ 495 on Hugging Face · Code ★ 53

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read
?Must readVote to see the score

Attention Residuals

Attention Residuals replace fixed residual accumulation with softmax attention over previous layer outputs for selective, input-dependent aggregation, improving scaling and downstream performance with minimal overhead.

Kimi Team, Guangyu Chen, Yu Zhang, Jianlin Su and 33 more

Published Mar 16, 2026 · 0 citations · ▲ 198 on Hugging Face · Code ★ 3,515

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 4/5
medium 8/10
strict 0/5
86%Must read
?Must readVote to see the score

SkillOpt: Executive Strategy for Self-Evolving Agent Skills

SkillOpt treats agent skills as external state optimized via bounded text edits validated on held-out scores, improving accuracy up to 24.8 points with stable transfer.

Yifan Yang, Ziyang Gong, Weiquan Huang, Qihao Yang and 11 more

Published May 22, 2026 · 2 citations · ▲ 267 on Hugging Face · Code ★ 18,090

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 4/5
medium 8/10
strict 2/5
76%Highly rated
?Highly ratedVote to see the score

Z-Image: An Efficient Image Generation Foundation Model with Single-Stream Diffusion Transformer

Z-Image is a 6B-parameter diffusion image generator that achieves leading open-source performance with only 314K GPU hours, sub-second inference, and consumer-hardware compatibility.

Image Team, Cai, Huanqia, Cao, Sihan, Du, Ruoyi and 20 more

Published Nov 27, 2025 · 1 citation · ▲ 249 on Hugging Face · Code ★ 12,067

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 10 of 20 reviewers recommend it
lenient 5/5
medium 4/10
strict 1/5
78%Highly rated

Program-as-Weights: A Programming Paradigm for Fuzzy Functions

Program-as-Weights compiles natural-language specs into compact local neural adapters that match large-model prompting with far less memory and faster offline execution.

Wentao Zhang, Liliana Hotsko, Woojeong Kim, Pengyu Nie and 2 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published Jul 2, 2026 · 0 citations · ▲ 307 on Hugging Face · Code ★ 359

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 5/10
strict 1/5
88%Must read
?Must readVote to see the score

The Other Half of the Memory Wall: Serving 35B MoEs from SSD with Trained Routing Prediction

Edge0 predicts next-layer MoE routing one token ahead to stream experts from SSD, serving 35B-class MoEs at 20 tok/s within 3 GiB active memory on a 24 GB machine via recovery LoRA adapters.

Yu Lin, Yiming Wang, Runyuan Cai, Liu, Hanze and 1 more

Published Sep 16, 2026 · 0 citations · ▲ 25 on Hugging Face · Code ★ 3,293

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read

Recursive Multi-Agent Systems

RecursiveMAS scales multi-agent collaboration through recursive latent-space computation via RecursiveLink and inner-outer loop co-optimization, improving accuracy by 8.3% with 1.2-2.4x speedup and 34.6%-75.6% token reduction over baselines.

Jiaru Zou, Rui Pan, Ruizhong Qiu, Pan Lu and 7 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published Apr 28, 2026 · 0 citations · ▲ 239 on Hugging Face · Code ★ 961

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 2/5
72%Highly rated

UniEvo-VL: An On-policy Self-Distillation Training Recipe for Multimodal Model Self-improvement

UniEvo-VL improves multimodal image generation via self-distillation that minimizes divergence between student and critique-conditioned teacher diffusion distributions during self-correction. Experiments on Qwen2.5-Image improve GenEval scores from 0.747 to 0.808 without external teachers.

Fang Wu, Da Xing, Yanjie Huang, Junxi Wang and 15 more

Published Sep 30, 2026 · 0 citations · ▲ 292 on Hugging Face

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

83%Must read
?Must readVote to see the score

JoyAI-VL-Interaction: Real-Time Vision-Language Interaction Intelligence

JoyAI-VL-Interaction is an open 8B vision-language model that continuously decides whether to speak, stay silent, or delegate in real time, outperforming Doubao and Gemini across six real-world scenarios.

Dingyu Yao, Junhao Zhou, Chenxu Yang, Chuanyu Qin and 16 more

Published Jun 10, 2026 · 0 citations · ▲ 218 on Hugging Face · Code ★ 1,944

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 13 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 0/5
91%Must read
?Must readVote to see the score

Can We Defend Against AI-Generated Video Attacks on Real-World Crisis Events? A Systematic Evaluation of Detectors, Generators and Social Dissemination

The RA-Bench benchmark reveals current detectors fail to consistently identify AI-generated crisis videos, which become harder to detect after social dissemination and frequently mislead humans.

Shuo Liang, Yixing Ma, Pengfei Zhou, Zhenglin Wan and 32 more

Published Aug 14, 2026 · 0 citations · ▲ 287 on Hugging Face · Code ★ 132

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 4/5
72%Highly rated

Kandinsky 6.0 Video: Foundation Models for Synchronized Video and Audio Generation

Kandinsky 6.0 Video introduces diffusion models that generate synchronized 5-second audio-video clips with lip-sync via a dual-stream CrossDiT architecture, with the 29B-parameter Pro version outperforming its predecessor and matching top competitors in speech quality.

Team Kandinsky, Julia Agafonova, Bulat Akhmatov, Mikhail Aksyutin and 36 more

Published Oct 4, 2026 · ▲ 113 on Hugging Face · Code ★ 119

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 8 of 20 reviewers recommend it
lenient 5/5
medium 3/10
strict 0/5
74%Highly rated
?Highly ratedVote to see the score

Lumine: An Open Recipe for Building Generalist Agents in 3D Open Worlds

Lumine is an open recipe for generalist agents that completes hours-long 3D open-world missions via end-to-end vision-language modeling with adaptive reasoning and strong cross-game zero-shot generalization.

Tan, Weihao, Li, Xiangyang, Fang, Yunhao, Yao, Heyuan and 10 more

Published Nov 12, 2025 · 0 citations · ▲ 218 on Hugging Face

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 9 of 20 reviewers recommend it
lenient 4/5
medium 4/10
strict 1/5
72%Highly rated
?Highly ratedVote to see the score

A Survey of Agentic Reasoning for Large Language Models: Towards Recursively Self-Improving and Collective Agents

This survey organizes LLM agentic reasoning into foundational, self-evolving, and collective layers, distinguishing in-context and post-training methods across applications while outlining open challenges.

Tianxin Wei, Ting-Wei Li, Zhining Liu, Xuying Ning and 25 more

Published Jan 18, 2026 · 1 citation · ▲ 208 on Hugging Face · Code ★ 1,398

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 8 of 20 reviewers recommend it
lenient 5/5
medium 2/10
strict 1/5
76%Highly rated
?Highly ratedVote to see the score

ERNIE 5.0 Technical Report

ERNIE 5.0 is a trillion-parameter unified autoregressive multimodal model using sparse MoE and elastic training to support diverse understanding and generation tasks.

Haifeng Wang, Hua Wu, Tian Wu, Yu Sun and 36 more

Published Feb 4, 2026 · 2 citations · ▲ 268 on Hugging Face

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 10 of 20 reviewers recommend it
lenient 5/5
medium 4/10
strict 1/5
76%Highly rated
?Highly ratedVote to see the score

Utonia: Toward One Encoder for All Point Clouds

Utonia trains a single self-supervised point transformer encoder across diverse point cloud domains to learn unified representations that improve cross-domain perception, embodied reasoning, and robotic manipulation.

Yujia Zhang, Xiaoyang Wu, Yunhan Yang, Xianzhe Fan and 5 more

Published Mar 3, 2026 · 0 citations · ▲ 189 on Hugging Face · Code ★ 755

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 10 of 20 reviewers recommend it
lenient 5/5
medium 4/10
strict 1/5
83%Must read
?Must readVote to see the score

RewardHarness: Self-Evolving Agentic Post-Training

RewardHarness evolves agentic evaluation tools from minimal preference data to judge image edits, surpassing GPT-5 accuracy with 0.05% training annotations.

Yuxuan Zhang, Penghui Du, Bo Li, Cong Wei and 10 more

Published May 9, 2026 · 0 citations · ▲ 244 on Hugging Face · Code ★ 69

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 13 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 1/5
83%Must read
?Must readVote to see the score

Video-MME-v2: Towards the Next Stage in Benchmarks for Comprehensive Video Understanding

Video-MME-v2 introduces a progressive tri-level benchmark with group-based non-linear evaluation that reveals substantial gaps between top models and human experts in video understanding.

Chaoyou Fu, Haozhi Yuan, Yuhao Dong, Yi-Fan Zhang and 15 more

Published Apr 6, 2026 · 0 citations · ▲ 231 on Hugging Face · Code ★ 362

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 13 of 20 reviewers recommend it
lenient 4/5
medium 7/10
strict 2/5
83%Must read
?Must readVote to see the score

DataFlow: An LLM-Driven Framework for Unified Data Preparation and Workflow Automation in the Era of Data-Centric AI

DataFlow is an LLM-driven framework providing modular data preparation pipelines and automated operator synthesis that improves downstream LLM performance over human-curated and synthetic baselines.

Liang, Hao, Ma, Xiaochen, Liu, Zhou, Wong, Zhen Hao and 31 more

Published Dec 18, 2025 · 0 citations · ▲ 225 on Hugging Face · Code ★ 8,195

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 13 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 1/5
69%Highly rated

RealCompanion: Benchmarking Human Understanding from Reasoning over Longitudinal Real-World Conversations

RealCompanion benchmarks AI companions on longitudinal real-world chats, finding needed past messages are usually recent, memory detectors fail on real messages, and persona reconstruction costs vary 31-fold at equal F1.

Arman Behnam, Sunglyoung Kim, Liangwei Yang

Published Oct 1, 2026 · 0 citations · ▲ 268 on Hugging Face

0% Readers0 of 1 upvoted
13/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read
?Must readVote to see the score

BabyVision: Visual Reasoning Beyond Language

BabyVision benchmarks core visual reasoning without language and finds top MLLMs score far below human children.

Liang Chen, Weichu Xie, Yiyan Liang, Hongfeng He and 26 more

Published Jan 10, 2026 · 1 citation · ▲ 201 on Hugging Face · Code ★ 257

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 4/5
medium 7/10
strict 1/5
72%Highly rated
?Highly ratedVote to see the score

NeoHorse-1: Towards Recursive Self-Improvement via Agentic Post-Training with Routing Harness

NeoHorse-1 closes an evaluation-selection-update loop via harness-mediated routing, structured post-training, and capability-guided data allocation, raising 4B and 9B macro-averages by ~6 and ~3.4 points.

NeoHorse Team, Guoliang Cao, Guohao Dai, Tianyu Guo and 33 more

Published Sep 8, 2026 · 0 citations · ▲ 327 on Hugging Face · Code ★ 1,673

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

OpenART: Scaling Agent Red Teaming via Open-Ended Environment Evolution

OpenART scales agent red teaming via open-ended environment evolution across 10,000 stateful scenarios, with EMHA achieving 85% attack success that grows with complexity.

Yunhao Chen, Xin Wang, Yixu Wang, Yi Liu and 5 more

Published Aug 1, 2026 · 0 citations · ▲ 266 on Hugging Face · Code ★ 231

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 3/5
88%Must read
?Must readVote to see the score

MiroThinker: Pushing the Performance Boundaries of Open-Source Research Agents via Model, Context, and Interactive Scaling

MiroThinker introduces interaction scaling to train open-source research agents for deeper tool use, achieving up to 81.9% on GAIA and rivaling commercial models.

MiroMind Team, Bai, Song, Lidong Bing, Chen, Carson and 36 more

Published Nov 14, 2025 · 0 citations · ▲ 197 on Hugging Face · Code ★ 8,419

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 0/5
72%Highly rated
?Highly ratedVote to see the score

MiroThinker-1.7 & H1: Towards Heavy-Duty Research Agents via Verification

MiroThinker-H1 integrates local and global verification into reasoning for reliable multi-step problem solving and achieves state-of-the-art deep research performance.

MiroMind Team, S. Kamala Bai, L. Bing, L. Lei and 36 more

Published Mar 16, 2026 · 0 citations · ▲ 187 on Hugging Face

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 8 of 20 reviewers recommend it
lenient 5/5
medium 3/10
strict 0/5
71%Highly rated
?Highly ratedVote to see the score

PaperBanana: Automating Academic Illustration for AI Scientists

PaperBanana automates publication-ready academic illustrations via agentic VLM and image generation, outperforming baselines on a 292-case benchmark.

Dawei Zhu, Meng, Rui, Yale Song, Xiyu Wei and 3 more

Published Jan 30, 2026 · 1 citation · ▲ 230 on Hugging Face · Code ★ 7,132

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 7 of 20 reviewers recommend it
lenient 4/5
medium 3/10
strict 0/5
71%Highly rated
?Highly ratedVote to see the score

ABot-Earth 0.5: Generative 3D Earth Model

ABot-Earth 0.5 generates seamless 3D environments from satellite imagery via 3D Gaussian Splatting, synthesizing square kilometers in under 10 minutes with real-time web visualization and embodied AI navigation support.

Ming Qian, Tianjian Ouyang, Mingchao Sun, Zijian Wang and 24 more

Published Jun 8, 2026 · 0 citations · ▲ 177 on Hugging Face · Code ★ 222

– ReadersNo votes yet
6/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 6 of 20 reviewers recommend it
lenient 5/5
medium 1/10
strict 0/5
72%Highly rated
?Highly ratedVote to see the score

MinT: Managed Infrastructure for Training and Serving Millions of LLMs

MinT manages LoRA adapter revisions over shared 1T-class base models to train and serve millions of policies via adapter-only handoffs and durable addressability.

Mind Lab, :, Song Cao, Vic Cao and 36 more

Published May 13, 2026 · 0 citations · ▲ 226 on Hugging Face · Code ★ 79

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 8 of 20 reviewers recommend it
lenient 3/5
medium 4/10
strict 1/5
72%Highly rated
?Highly ratedVote to see the score

SkillClaw: Let Skills Evolve Collectively with Agentic Evolver

SkillClaw enables collective skill evolution in multi-user LLM agent ecosystems by aggregating cross-user interaction trajectories and autonomously updating shared reusable skills, significantly improving real-world agent performance.

Ziyu Ma, Shidong Yang, Yuxiang Ji, Xucong Wang and 4 more

Published Apr 9, 2026 · 0 citations · ▲ 225 on Hugging Face · Code ★ 2,669

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 8 of 20 reviewers recommend it
lenient 5/5
medium 3/10
strict 0/5
88%Must read
?Must readVote to see the score

YuE2: Unifying Symbolic and Audio Music Generation at Frontier Quality

YuE2 unifies symbolic and audio music generation through symbolic planning, producing readable scores and full-song audio that outperform public baselines and rival proprietary generators.

Ruibin Yuan, Jiahao Pan, Junyan Jiang, Zhiyue Wu and 31 more

Published Sep 27, 2026 · 0 citations · ▲ 246 on Hugging Face · Code ★ 10,927

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

OneStreamer: Unifying Perception, Memory, and Proactive Response in Streaming Video Interaction

OneStreamer unifies streaming video perception, memory, and proactive response via shared generation, achieving top results on eight benchmarks with a 4B model.

Xiangyu Zeng, Yuandong Yang, Zhiqiu Zhang, Yuhan Zhu and 20 more

Published Oct 1, 2026 · 0 citations · ▲ 232 on Hugging Face · Code ★ 169

100% Readers1 of 1 upvoted
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

RRSI: Regularized Recursive Self-Improvement of Agent Harnesses

RRSI regularizes recursive agent harness self-improvement via annealed edit budgets, trajectory exploration, and critical selection to boost out-of-distribution performance and reduce token use. It improves up to 14.1 points in-distribution and 4.7 points out-of-distribution while cutting policy tok

Peng Xia, Rujun Han, Zifeng Wang, Yanfei Chen and 10 more

Published Sep 21, 2026 · 0 citations · ▲ 222 on Hugging Face · Code ★ 1,293

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Rethinking Latent Visual Reasoning: Grounding Latent Reasoning in Visual Evidence

ReaLVR fixes latent reasoning's weak visual grounding by supervising latent tokens with visual evidence, improving reasoning across scales up to 235B.

Xi Xiao, Tianchen Zhao, Youngeun Kim, Zhuowei Li and 9 more

Published Sep 28, 2026 · 0 citations · ▲ 217 on Hugging Face · Code ★ 40

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

78%Highly rated
?Highly ratedVote to see the score

LTX-2: Efficient Joint Audio-Visual Foundation Model

LTX-2 is an open-source 14B/5B audiovisual transformer generating synchronized high-quality video and audio with state-of-the-art open-source quality at low computational cost.

Yoav HaCohen, Benny Brazowski, Nisan Chiprut, Yaki Bitterman and 25 more

Published Jan 6, 2026 · 0 citations · ▲ 197 on Hugging Face · Code ★ 9,606

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 5/10
strict 1/5
72%Highly rated
?Highly ratedVote to see the score

Apodex 1.1: Scaling Agentic Intelligence for Complex Work

Apodex 1.1 scales agentic intelligence via environment and coordination scaling to achieve leading complex-work performance with smaller models.

B. An, B. An, B. Wang, B. L. Wang and 36 more

Published Aug 24, 2026 · 0 citations · ▲ 212 on Hugging Face · Code ★ 5,146

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read
?Must readVote to see the score

Frontis-MA1: Training an AI4AI Model towards Recursive Self-Improvement in Machine Learning Engineering

Frontis-MA1 improves machine-learning engineering via recursive self-improvement using OpenMLE, boosting MLE-Bench Lite medal average from 39.39% to 71.21% and surpassing larger closed models.

Junlin Yang, Che Jiang, Yu Fu, Tianwei Luo and 20 more

Published Jul 30, 2026 · 0 citations · ▲ 188 on Hugging Face · Code ★ 782

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 4/5
medium 8/10
strict 0/5
88%Must read
?Must readVote to see the score

On-Policy or Off-Policy Learning? A Systematic Study of Distillation Dynamics

In controlled strong-to-weak distillation, rollout policy is less central than token-level KL direction and learning rate, though on-policy data can improve generalization on harder reasoning tasks.

Julianna Piskorz, Antonin Berthon, Mihaela van der Schaar

Published Sep 28, 2026 · 0 citations · ▲ 194 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

EnvHarness: Awakening Static Worlds for Agent Learning

EnvHarness wraps static environments with programmable components to reshape agent behavior without altering underlying logic, improving benchmarks by up to 9.0 points while enabling continuous policy-environment co-evolution.

Chengsong Huang, Zifeng Wang, Rujun Han, Jun Yan and 13 more

Published Aug 20, 2026 · 0 citations · ▲ 175 on Hugging Face · Code ★ 619

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

74%Highly rated
?Highly ratedVote to see the score

ARIS: Autonomous Research via Adversarial Multi-Agent Collaboration

ARIS is an open-source autonomous research harness using cross-model adversarial collaboration to coordinate ML workflows and verify experimental claims.

Ruofeng Yang, Yongcan Li, Shuai Li

Published May 4, 2026 · 1 citation · ▲ 154 on Hugging Face · Code ★ 17,051

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 9 of 20 reviewers recommend it
lenient 5/5
medium 4/10
strict 0/5
88%Must read
?Must readVote to see the score

GraphForge: Training Working Agents with Graph-Anchored Workspace Synthesis

GraphForge synthesizes workspace tasks and verifiers over real file evidence graphs to train working agents, and fine-tuning Qwen3.6-27B improves GDPVal, Workspace-Bench-Lite, and SpreadsheetBench II results.

Qisheng Su, Hanchen Wang, 朱冠儒, Huicheng Jiang and 8 more

Published Sep 30, 2026 · 0 citations · ▲ 146 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

72%Highly rated
?Highly ratedVote to see the score

AREX-2: Advancing Self-Improving Agents through Long-Horizon Reflective Tasks

AREX-2 synthesizes long-horizon reflective trajectories to train a Qwen3.8-27B agent that self-improves at test time, achieving strong results on MLE-bench, Frontier-CS, and deep research benchmarks while scaling with iteration budget.

Hongjin Qian, Chaofan Li, Kun Luo, Wenqing Wei and 10 more

Published Sep 29, 2026 · 0 citations · ▲ 139 on Hugging Face · Code ★ 31

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

Adaptive Reward Routing: Dynamic Multi-Reward Optimization for Joint Audio-Video Diffusion via Forward-Process RL

Adaptive Reward Routing dynamically routes updates and balances rewards during forward-process RL for joint audio-video diffusion, consistently improving quality, alignment, and synchronization over fixed baselines.

Songlin Yang, Xiaotong Zhao, Jiacheng Zhang, Zhe Wang and 4 more

Published Sep 29, 2026 · 0 citations · ▲ 138 on Hugging Face

– ReadersNo votes yet
6/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read

Does Learning Protein Folding Generalize to Broader Reasoning?

Post-training on protein-folding data via discrete answers and continuous geometry improves structure prediction and broad reasoning across ten benchmarks.

Yong Liu, Zhanpeng Shi, Yizhou Dang, Zhongyue Zhang and 3 more

Published Sep 30, 2026 · 0 citations · ▲ 120 on Hugging Face · Code ★ 28

100% Readers1 of 1 upvoted
16/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Mid-Harness: Scaling Actions Between Model and Harness for Terminal Agents

Mid-Harness verifies candidate terminal actions at the model-harness boundary, raising TerminalBench-Lite Pass@1 from 50.00% to 68.03% and improving success at lower token cost than trajectory scaling alone.

Minki Kang, Ryo Hachiuma, Shaokun Zhang, Subhashree Radhakrishnan and 7 more

Published Sep 30, 2026 · 0 citations · ▲ 116 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read
?Must readVote to see the score

UniMate: One Unified Model to Animate Diverse Skeletons

UniMate is a unified diffusion transformer that synthesizes motion for arbitrary skeletons from text and rigged assets without test-time optimization, using topology-aware attention and a new dataset to outperform specialized animators.

Linzhan Mou, Lei, Jiahui, Zhiyang Dou, Chenyue Cai and 3 more

Published Sep 4, 2026 · 0 citations · ▲ 23 on Hugging Face · Code ★ 1,553

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

78%Highly rated
?Highly ratedVote to see the score

EvoDuet: Bilevel Co-Evolution of Web Searching and Task Solving for Scientific Discovery

EvoDuet co-evolves solutions and web queries via a retrieval gate to boost LLM discovery gains up to 82.3% across optimization tasks.

Young-Jun Lee, Jinheon Baek, Soyeong Jeong, Minki Kang and 4 more

Published Sep 30, 2026 · 0 citations · ▲ 109 on Hugging Face · Code ★ 4

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read

FrameMorrow: Future-guided Frame Selection with Prospective Tokens for Long-Horizon Video Generation

FrameMorrow guides historical frame selection via prospective tokens representing future needs, improving consistency and quality across diverse long-horizon video generators.

Bo Yin, Xiaobin Hu, Jiaqi Zhao, Shuicheng Yan

Published Sep 30, 2026 · 0 citations · ▲ 105 on Hugging Face · Code ★ 29

100% Readers1 of 1 upvoted
14/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read

Sharpening Tax in Post-Training

Post-training sharpens base model behaviors at the cost of solution coverage, introducing a quantifiable "Sharpening Tax"; a posterior-tempered group sampler reduces this tax while boosting accuracy.

Changdae Oh, Qi Zeng, Qi Qi, Andrey Zhmoginov and 6 more

Published Oct 1, 2026 · 0 citations · ▲ 102 on Hugging Face · Code ★ 25

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

76%Highly rated
?Highly ratedVote to see the score

WorldAuditBench: Interactive 3D World Auditing with Multimodal Agents

WorldAuditBench benchmarks interactive 3D world auditing with multimodal agents, finding success rates of 6.6% to 42.3% versus 83.4% human performance.

Ziyan Jiang, Jingbo Yang, Jiabao Ji, Yujian Liu and 4 more

Published Sep 30, 2026 · 0 citations · ▲ 102 on Hugging Face · Code ★ 4

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

Predictive Credit: Measuring What Scientific Explanations Add to Experimental Forecasts

Predictive credit for scientific explanations is measured via paired forecasts, but gains over descriptions remain unconfirmed across Tox21, OpenML, and controlled settings.

Jingjie Ning, Xueqi Li, Yibo Kong, Dongting Li

Published Sep 29, 2026 · 0 citations · ▲ 101 on Hugging Face

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read
?Must readVote to see the score

Prefill-Free Cross-Family KV Cache Transfer for Heterogeneous Multi-Agent LLMs

HeteroFold enables prefill-free cross-family KV cache transfer between frozen heterogeneous LLM agents, accelerating 32K context transfer up to 10.7x while matching text-based multi-agent performance.

Vincent-Daniel Yun, Woosang Lim, Haneul Yoo, Sungjoo Yoo and 2 more

Published Sep 26, 2026 · 0 citations · ▲ 95 on Hugging Face · Code ★ 1

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Beyond Memory: Harnessing Long-Horizon Agents with Explicit Belief States

PoS maintains explicit belief states for long-horizon LLM agents, detects belief trapping, and recovers to achieve top results across four benchmarks.

Yu Luo, Jiamin Jiang, Yimin Zuo, Xidao Wen and 8 more

Published Oct 1, 2026 · 0 citations · ▲ 93 on Hugging Face · Code ★ 28

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

83%Must read

Scaling Trajectories for Complex Tasks through Recursive Self-Rewrite

Recursive Self-Rewrite uses diverse harnesses and recursive revision to rewrite successful terminal trajectories for supervised fine-tuning, boosting pass@3 by up to 7.6x on hard benchmarks.

Zongxia Li, Yucheng Shi, Zhongzhi Li, Junyao Yang and 6 more

Published Oct 2, 2026 · 0 citations · ▲ 91 on Hugging Face

– ReadersNo votes yet. 1 from authors or colleagues not counted
13/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

RSIGame: Autonomous Agentic Game Development with Recursive Self-improvement

RSIGame uses recursive self-improvement with local and global loops to autonomously refine generated games, surpassing one-shot GPT-5.5 scores while cutting generation tokens by 11x.

Wenyi Wu, Minghao Fu, Jieyu You, Kun Zhou and 9 more

Published Sep 30, 2026 · 0 citations · ▲ 91 on Hugging Face · Code ★ 125

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read

MotorMind: Scaffolding General Vision Language Models for Zero-Shot Robot Manipulation

MotorMind connects general vision-language models to deterministic robot control via mid-level actions and feedback loops, achieving 66.7% zero-shot success on LIBERO-PRO and 95% on real robots without task-specific training or external tools.

Bingxuan Li, Siqi Song, Yizhuo Wu, Jiarui Yao and 2 more

Published Sep 29, 2026 · 0 citations · ▲ 90 on Hugging Face

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

78%Highly rated
?Highly ratedVote to see the score

Hierarchical Continuous Diffusion Language Models

HC-DLM couples discrete token generation with a continuous latent trajectory via a unified variational denoising objective, outperforming diffusion baselines on Sudoku, Countdown, and language modeling.

Hui Ren, Zihan Li, Chang Liu, Huidong Liu and 1 more

Published Oct 1, 2026 · 0 citations · ▲ 89 on Hugging Face · Code ★ 57

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

72%Highly rated
?Highly ratedVote to see the score

World Observer: Joint Actor-Observer Generation for Persistent World Modeling

World Observer jointly generates actor and panoramic observer views to continuously model out-of-view dynamics via shared geometric warping and observer sinks.

Hyunwook Choi, Dahyun Chung, Hyunsung Kim, Siyoon Jin and 3 more

Published Oct 1, 2026 · 0 citations · ▲ 85 on Hugging Face · Code ★ 30

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Agent Priors-guided Policy Learning

Agent Priors-guided Policy Learning embeds structural priors in skill interfaces to enable compositional and out-of-distribution skill generalization.

Puming (Oscar) Jiang, Tao Hu, Haozhe Du, Yibo Li and 3 more

Published Sep 28, 2026 · 0 citations · ▲ 84 on Hugging Face · Code ★ 3

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read

World Action Modeling with Progressive Visual Planning

ProWAM predicts sparse visual sub-goals and actions via progressive planning, achieving state-of-the-art long-horizon robotic control and strong zero-shot real-world generalization.

Fei Zhang, Zhaochong An, Duncan Frost, Yikai Wang and 4 more

Published Oct 1, 2026 · 0 citations · ▲ 83 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

76%Highly rated
?Highly ratedVote to see the score

Learning Meta-Skills for Agent Harness Design in Test-Time AI4AI

A Builder learns reusable meta-skills from target feedback to construct execution harnesses that boost target performance on unseen tasks. Meta-skills improve macro-average scores by 8.95 points over no-skill construction and 12.02 over direct delivery.

Cheng Qian, Kunlun Zhu, Beibin Li, Zhenhailong Wang and 1 more

Published Sep 29, 2026 · 0 citations · ▲ 83 on Hugging Face · Code ★ 9

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read
?Must readVote to see the score

ActiveSaddler: Automated Curriculum Learning for Agent Harness Optimization

ActiveSaddler automates curriculum learning for agent harness optimization via non-stationary bandits that adapt training scenarios to evolving failure patterns, boosting Pass@1 by 4.4, 7.5 points.

Sungho Park, Wonjoong Kim, Jue Zhang, Wook-Shin Han and 7 more

Published Oct 1, 2026 · ▲ 82 on Hugging Face

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 4/5
medium 8/10
strict 0/5
76%Highly rated
?Highly ratedVote to see the score

On-Policy Parameter Update Direction Underlies Generalization in LLM Post-Training

On-policy methods continuously adjust parameter update directions, unlike consistent SFT updates; constraining SFT to these directions via OPSFT transfers on-policy generalization advantages to supervised fine-tuning.

Shufan Shen, Zhongni Hou, Junshu Sun, Yufei Zhang and 4 more

Published Sep 29, 2026 · 0 citations · ▲ 81 on Hugging Face

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read

Native Action-Prior Learning from Videos for World Action Models

NAVA-WAM pretrains robot action policies directly from observation-only videos via flow-matching and joint attention, improving control accuracy and label efficiency.

Zhaochong An, Fei Zhang, Menglin Jia, Duncan Frost and 9 more

Published Oct 2, 2026 · 0 citations · ▲ 81 on Hugging Face

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

74%Highly rated
?Highly ratedVote to see the score

Native Parallel Reasoner: Reasoning in Parallelism via Self-Distilled Reinforcement Learning

NPR enables LLMs to self-evolve genuine parallel reasoning via self-distilled reinforcement learning, achieving up to 24.5% accuracy gains, 4.6x speedups, and 100% parallel execution.

Wu, Tong, Liu, Yang, Bai, Jun, Jia, Zixia and 5 more

Published Dec 8, 2025 · 0 citations · ▲ 80 on Hugging Face · Code ★ 112

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 9 of 20 reviewers recommend it
lenient 4/5
medium 5/10
strict 0/5
80%Must read
?Must readVote to see the score

EVOKE: Eliciting World Knowledge in Agents for Transferable Decision-Making

EVOKE improves LLM agent transfer by ranking actions under diverse goals at fixed states to elicit pretrained world knowledge for robust decision-making.

Yuhan Guo, Jinming Liu, Liang Xu, Ziqiang Li and 7 more

Published Sep 29, 2026 · 0 citations · ▲ 78 on Hugging Face · Code ★ 7

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

JEPA-Anything: Learning Predictive Models across Different Worlds

JEPA-Anything uses orthogonal predictive factorization to learn cross-domain predictive models that outperform baselines in vision, biology, clinical, control, molecular, physical, and weather domains.

Taoyong Cui, Zhongyao Wang, Xinyue Xu, Weiyang Liu and 9 more

Published Sep 17, 2026 · 0 citations · ▲ 77 on Hugging Face · Code ★ 261

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

A Missing Piece for Trustworthy AI Reviewers: From Benchmarking Rhetorical Robustness to SciCore Review

Rhetorical robustness requires stable judgments across content-preserving rewrites and discrimination across papers; SciCore improves both via dual-branch science-core review.

Chenguang Wang, Ming Li, Chengrui Fan, Jianpeng Chen and 3 more

Published Sep 30, 2026 · 0 citations · ▲ 76 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

X-Tree: Tokenizing Reusable Experience for Efficient Agent Generalization

X-Tree learns reusable hierarchical skills from agent trajectories and improves success rates up to 5.8% across web and science benchmarks.

Sitao Cheng, Xunjian Yin, Zhiyuan Sun, Yuxuan Li and 3 more

Published Sep 26, 2026 · 0 citations · ▲ 76 on Hugging Face · Code ★ 2

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Transformers Stop Thinking Too Early, and a Tiny LoRA Fixes It

Pretrained transformers stop following references after 1.4, 3.6 lines, but a rank-8 LoRA at one early layer extends computation to 50, 160 lines without changing frozen weights.

Zehao Jin, Ruixuan Deng, 君然 王

Published Sep 29, 2026 · 0 citations · ▲ 75 on Hugging Face · Code ★ 3

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

72%Highly rated
?Highly ratedVote to see the score

On the Geometry of On-Policy Distillation

On-policy distillation updates occupy a sparse, low-dimensional parameter subspace that is functionally sufficient and geometrically distinct from supervised fine-tuning and reinforcement learning.

Zhennan Shen, Yanshu Li, Qingyu Yin, Chak Tou Leong and 5 more

Published Jun 5, 2026 · 0 citations · ▲ 75 on Hugging Face

– ReadersNo votes yet. 1 from authors or colleagues not counted
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 8 of 20 reviewers recommend it
lenient 3/5
medium 4/10
strict 1/5
78%Highly rated

Imagine3D-LLM: Teaching MLLMs to Imagine 3D Scenes Before Answering

Imagine3D-LLM learns compact scene representations via learnable summary tokens decoded into 3D Gaussian splatting with photometric loss, improving multi-view spatial reasoning benchmarks.

Jaewoo Jung, Hyeonseo Yu, Honggyu An, Jisang Han and 9 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published Sep 29, 2026 · ▲ 72 on Hugging Face · Code ★ 37

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 4/5
medium 6/10
strict 1/5