Good Papers

Must read

This year's highest-rated papers

92%Must read

Science or Slop?: Benchmarking and Mitigating Scientific Slop in AI-Generated Papers

A benchmark of 390 AI papers measures scientific slop across structure, argument, and artifacts; a harness reduces the AI-human gap by 63% via evidence-grounded revision.

Yerim Oh, Young-Jun Lee, Jaewoo Ahn, Gunhee Kim and 1 more

Published Sep 30, 2026 · 0 citations · ▲ 55 on Hugging Face · Code ★ 13

100% Readers1 of 1 upvoted
17/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read

MotorMind: Scaffolding General Vision Language Models for Zero-Shot Robot Manipulation

MotorMind connects general vision-language models to deterministic robot control via mid-level actions and feedback loops, achieving 66.7% zero-shot success on LIBERO-PRO and 95% on real robots without task-specific training or external tools.

Bingxuan Li, Siqi Song, Yizhuo Wu, Jiarui Yao and 2 more

Published Sep 29, 2026 · 0 citations · ▲ 90 on Hugging Face

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read

DEPICT: Scoring Text-to-Image Alignment by Answer Agreement

DEPICT scores text-to-image alignment via expected agreement between image and caption answers, boosting negation accuracy to 88% and exceeding fine-tuned evaluators on human correlation benchmarks.

Vasco Ramos, Sandra Godinho Silva, Joao Magalhaes, Ricardo Rei and 1 more

Published Oct 2, 2026 · 0 citations · ▲ 3 on Hugging Face

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read

Does Learning Protein Folding Generalize to Broader Reasoning?

Post-training on protein-folding data via discrete answers and continuous geometry improves structure prediction and broad reasoning across ten benchmarks.

Yong Liu, Zhanpeng Shi, Yizhou Dang, Zhongyue Zhang and 3 more

Published Sep 30, 2026 · 0 citations · ▲ 120 on Hugging Face · Code ★ 28

100% Readers1 of 1 upvoted
16/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read

OSWorld-Pro: Process-based Evaluation for Computer Use Agents

OSWorld-Pro introduces process-based evaluation with 2,800 subgoals across 300 tasks, revealing top models achieve only 75.7% subgoal success versus 83.4% end-state performance and identifying distinct failure modes like irrelevant actions and click errors.

Zhilin Wang, Shaokun Zhang, Yifan Zhang, Hao E. Zhang and 8 more

Published Sep 21, 2026 · 0 citations · ▲ 15 on Hugging Face

100% Readers1 of 1 upvoted
16/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 1/5
91%Must read

HuatuoGPT-3: RL-Only Domain Adaptation from Base Models

OnePO enables RL-only medical domain adaptation via adaptive objective evolution and teacher retirement, yielding HuatuoGPT-3 that surpasses frontier models.

Junying Chen, Xinyuan Xie, Ziniu Li, Wenyuan Gu and 6 more

Published Oct 5, 2026 · ▲ 15 on Hugging Face · Code ★ 12

100% Readers1 of 1 upvoted
16/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 1/5
91%Must read

StateM: Reaching 95.3% Raw Accuracy, or a \$15 Frontier Run, on Terminal-Bench 2.1 via Harness Scaling

StateM improves long-horizon agent accuracy via durable-state harness scaling without model changes, reaching 95.3% on Terminal-Bench 2.1 and cutting API costs to about $15 versus $574.68.

Ziheng Qin, Yaxin Lu, Zhangyang Atlas Wang, Kai Wang

Published Aug 15, 2026 · 0 citations · ▲ 452 on Hugging Face · Code ★ 1,312

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 2/5
91%Must read

DeskForge: Dense Supervision from Desktop Environments for Computer-Use Agents

DeskForge generates dense desktop supervision via controllable real-app environments, yielding 1.2M observations that improve GUI grounding and long-horizon computer-use task completion.

A. Said Gurbuz, Ahmed Nassar, Sunghwan Hong, Marc Pollefeys and 1 more

Published Oct 1, 2026 · 0 citations · ▲ 10 on Hugging Face · Code ★ 4

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

UndoBench: Separating Task Competence from Recovery Capability in Tool-Using AI Agents

UndoBench separates tool-using agent competence from fault recovery via paired enterprise workflow trials, finding 83.54% nominal success but only 46.72% recovery success with phase-dependent vulnerabilities.

Dolly Sah, Tanmay Sah, Harshul Jain, Tanya Sah

Published Oct 4, 2026 · ▲ 11 on Hugging Face · Code ★ 1

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 3/5
91%Must read

Sharpening Tax in Post-Training

Post-training sharpens base model behaviors at the cost of solution coverage, introducing a quantifiable "Sharpening Tax"; a posterior-tempered group sampler reduces this tax while boosting accuracy.

Changdae Oh, Qi Zeng, Qi Qi, Andrey Zhmoginov and 6 more

Published Oct 1, 2026 · 0 citations · ▲ 102 on Hugging Face · Code ★ 25

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

CurveCodec 2: Skeleton-agnostic animation compression with a learned entropy model

CurveCodec 2 predicts quantized skeletal curves from past values and learns residual entropy models to reduce animation storage to 0.22-0.37x of ACL with verified error bounds.

Mingyi Shi, Huancheng Lin, Xuelin Chen, Taku Komura

Published Oct 3, 2026 · ▲ 4 on Hugging Face · Code ★ 5

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 4/5
medium 9/10
strict 4/5
91%Must read

QuantWM: Temporally Consistent 2-Bit KV Cache Quantization for Video World Models

QuantWM is a training-free 2-bit KV cache quantization framework for video world models that preserves attention logits and token selection to eliminate temporal flickering while achieving up to 6.20x memory compression.

Jiaqi Zhao, Xiaobin Hu, Bo Yin, Junpeng Jiang and 2 more

Published Sep 22, 2026 · 0 citations · ▲ 13 on Hugging Face

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 2/5
91%Must read
?Must readVote to see the score

Can We Defend Against AI-Generated Video Attacks on Real-World Crisis Events? A Systematic Evaluation of Detectors, Generators and Social Dissemination

The RA-Bench benchmark reveals current detectors fail to consistently identify AI-generated crisis videos, which become harder to detect after social dissemination and frequently mislead humans.

Shuo Liang, Yixing Ma, Pengfei Zhou, Zhenglin Wan and 32 more

Published Aug 14, 2026 · 0 citations · ▲ 287 on Hugging Face · Code ★ 132

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 4/5
91%Must read

Rethinking Long-Video Efficiency: A Joint Allocation Perspective on Frames, Pixels, and Front-End Latency

LoHi trades per-frame resolution for denser temporal sampling via low-resolution streams plus sparse high-resolution frames, boosting long-video accuracy up to 10.6 points and cutting front-end latency up to 7x.

Sixun Dong, Wei Li, Andong Deng, Qi Qian and 3 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published Oct 3, 2026 · ▲ 13 on Hugging Face

– ReadersNo votes yet. 1 from authors or colleagues not counted
17/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 3/5
91%Must read

False Frontiers: Diagnosing and Mitigating Co-Cheating in Self-Evolving Search Agents

Self-evolving search agents suffer co-cheating where proposers and solvers mutually reinforce errors; CrossFit partitions sources to cross-fit agreement and cuts false agreement by over half, boosting downstream search by 8+ points.

Meijia Chen, Hao Li, Zheng Lu, Hongshan Lin and 11 more

Published Sep 30, 2026 · 0 citations · ▲ 670 on Hugging Face

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Learning Functional Subspaces for Neural Network Compression

LSP learns low-rank subspaces end-to-end via joint orthogonal projector optimization to reduce transformer memory and compute while outperforming local criteria at high compression ratios.

Massimo Bini, Anders Christensen, Stephan Alaniz, Judah Goldfeder and 4 more

Published Sep 30, 2026 · 0 citations · ▲ 1 on Hugging Face

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

OpenART: Scaling Agent Red Teaming via Open-Ended Environment Evolution

OpenART scales agent red teaming via open-ended environment evolution across 10,000 stateful scenarios, with EMHA achieving 85% attack success that grows with complexity.

Yunhao Chen, Xin Wang, Yixu Wang, Yi Liu and 5 more

Published Aug 1, 2026 · 0 citations · ▲ 266 on Hugging Face · Code ★ 231

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 3/5
91%Must read
?Must readVote to see the score

Where Does Retrieval-Based Open-Ended Evaluation Fail? Automatic Taxonomy Induction from Long-Form Medical Answer Factuality Verification

Automatic taxonomies reveal retrieval and verifier reasoning failures persist across scaled medical retrieve-then-verify systems, showing fundamental open-ended evaluation limits.

Heyuan Huang, Jirui Dai, Alexandra DeLucia, Sonal Joshi and 4 more

Published Sep 24, 2026 · 0 citations · ▲ 12 on Hugging Face

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 2/5
90%Must read
?Must readVote to see the score

From Evidence to Action: How Tool-Using Agents Fail

Tool-using agents often fail by acting before establishing required evidence or leaving multi-action workflow prerequisites unresolved, despite accurate static action assessment. SafeActBench reveals failures stem from how agents use established evidence during execution, not just missing informatio

Hongzhan Lin, Shidong Cao, Ziyang Luo, Wenhao Chai and 2 more

Published Oct 6, 2026 · ▲ 20 on Hugging Face · Code ★ 3

100% Readers1 of 1 upvoted
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 3/5
90%Must read
?Must readVote to see the score

World Action Learning via Interaction-Centric Spectral Latent Guidance

WING distills interaction-centric latent actions from egocentric video and uses cross-embodiment spectral low-frequency guidance to transfer them to robot policies, achieving high success rates on LIBERO, RoboTwin, RoboCasa, and real-world tasks.

Zhiming Liu, Yikun Miao, Ying Chen, Hongrui Yin and 6 more

Published Oct 2, 2026 · 0 citations · ▲ 20 on Hugging Face

100% Readers1 of 1 upvoted
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

90%Must read
?Must readVote to see the score

World Models' Last Exam in Physics

World Models' Last Exam in Physics benchmarks video models via 40 measurement-based physics tasks, finding the best model scores 57.76/100 with widespread inconsistencies.

Mingju Gao, Qingle Liu, Yuzhao Peng, Xinjie Lin and 7 more

Published Oct 6, 2026 · ▲ 2 on Hugging Face

100% Readers1 of 1 upvoted
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 3/5
89%Must read
?Must readVote to see the score

A Missing Piece for Trustworthy AI Reviewers: From Benchmarking Rhetorical Robustness to SciCore Review

Rhetorical robustness requires stable judgments across content-preserving rewrites and discrimination across papers; SciCore improves both via dual-branch science-core review.

Chenguang Wang, Ming Li, Chengrui Fan, Jianpeng Chen and 3 more

Published Sep 30, 2026 · 0 citations · ▲ 76 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

LMBuild: Evaluating LLM Agents for Generating Buildable and Functional Structures

LMBuild evaluates LLM agents on generating buildable, functional 3D structures and finds physical operability and functional affordance remain challenging despite improved soundness.

Jiateng Liu, Rushi Wang, Cheng Qian, Xuejun Zhang and 8 more

Published Oct 3, 2026 · ▲ 24 on Hugging Face · Code ★ 1

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
89%Must read
?Must readVote to see the score

PDE-JEPA: Predictive Representation Learning of Latent Dynamics Modeling for Parametric PDEs

PDE-JEPA introduces predictive masked-latent pretraining with geometry projection and structured latent predictors for parametric PDE dynamics, reducing errors by 33.4% in-distribution and 51.4% on unseen parameters.

Zhentao Tan, Jianrong Zhang, Ruijie Quan, Yi Yang

Published Sep 28, 2026 · 0 citations · ▲ 53 on Hugging Face · Code ★ 9

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read

World Action Modeling with Progressive Visual Planning

ProWAM predicts sparse visual sub-goals and actions via progressive planning, achieving state-of-the-art long-horizon robotic control and strong zero-shot real-world generalization.

Fei Zhang, Zhaochong An, Duncan Frost, Yikai Wang and 4 more

Published Oct 1, 2026 · 0 citations · ▲ 83 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Self-Generated Feedback Destabilizes Test-Time Training: A Causal Decomposition of Long-Horizon Adaptation

Self-generated feedback in long-horizon test-time training causes weight updates that improve synthetic text but degrade real-text prediction, and settlement on independent evidence prevents this failure.

Cheng Luo, Bing Li, Bernard Ghanem

Published Oct 4, 2026 · ▲ 19 on Hugging Face · Code ★ 1

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 4/5
medium 9/10
strict 3/5
89%Must read
?Must readVote to see the score

AGO AI Quality Gate: Evidence-First Release Decisions for Retrieval-Augmented Generation

AGO is an evidence-first quality gate for RAG that treats judge errors and missing data as explicit outcomes, using stratified beta-binomial gates and mandatory meta-evaluation to reduce unsafe promotion to 22.2%-35.1% versus 29.3%-41.8% for naive gates.

Giulio Zeloni, Enrico Lo Conte, Salvatore Rionero, Giuseppe Santoro and 2 more

Published Oct 1, 2026 · 0 citations · ▲ 13 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

JLD: Perceptual Distance Through A Jacobian Lens

JLD defines a perceptual image distance via a Jacobian-derived metric tensor from frozen vision encoders, achieving state-of-the-art correlation with human judgments and resolution robustness.

Shreshth Saini, Balu Adsumilli, Alan C. Bovik

Published Oct 5, 2026 · ▲ 3 on Hugging Face · Code ★ 3

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
89%Must read
?Must readVote to see the score

Old Ideas, Novel Problems: The Instability of LLM-Based Novelty Evaluation

LLM novelty judges are unstable: small prompt changes alter verdicts on over half of identical idea pairs and shift accuracy by over 50 points, undermining automated ideation evaluations.

Noy Sternlicht, Simra Shahid, Peter Jansen, Daniel S. Weld and 2 more

Published Oct 1, 2026 · 0 citations

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Multilingual GSM-Symbolic: What determines capability transfer across languages?

Multilingual GSM-Symbolic introduces matched math problems across 15 languages to show model size, resource level, reasoning, and typology determine cross-lingual transfer, with size and reasoning closing low-resource gaps but not typological ones.

Kenneth Enevoldsen, Riley Herchert, Sofie Mosegaard, Dan Saattrup Smart and 21 more

Published Oct 2, 2026 · 0 citations · ▲ 47 on Hugging Face · Code ★ 4

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

PointWAM: 3D World Action Modeling for Dexterous Robotic Manipulation

PointWAM forecasts 3D point trajectories of scenes and hands in a shared space-time frame to guide dexterous robot manipulation, improving DexJoCo success by 56.9 points with video pre-training.

Chunghyun Park, Beomjun Kim, Seungcheol Park, 권희승 and 4 more

Published Oct 2, 2026 · 0 citations · ▲ 42 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

MM-ABC: Towards Generalist Mobile Manipulation via Seeing, Coordinating and Imagining

MM-ABC is a mobile manipulation foundation model combining multi-level vision features, future imagination supervision, and masked joint attention to coordinate arm-base actions, achieving up to 99.1% success across benchmarks and 83% in real-world tasks.

Qiwei Liang, Guangyu Chen, Shaolong Zhu, Zikuan Xiao and 5 more

Published Sep 28, 2026 · 0 citations · ▲ 5 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
89%Must read

Certification of Real Images through Calibrated Content Authentication

Deepfake detectors degrade to 76% accuracy and near-zero under attacks, so calibrated reconstruction-based authentication bounds false real-image certification to 1%.

Sarim Hashmi, Abdelrahman Elsayed, Mohammed Talha Alam, Samuele Poppi and 1 more

Published Oct 5, 2026 · ▲ 13 on Hugging Face · Code ★ 2

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
89%Must read
?Must readVote to see the score

Rethinking Token Reweighting for SFT: Suppress, Reverse, and Extrapolate Learned Features

Existing token-reweighting methods cannot reverse harmful SFT features; SCALE uses frozen SFT deltas with entropy-guided gates to suppress, reverse, or extrapolate them, improving math and code results.

Cunchun Li, Haonan He, Yifan Gao, Minglei Li and 3 more

Published Sep 27, 2026 · 0 citations · ▲ 11 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 2/5
89%Must read
?Must readVote to see the score

RRSI: Regularized Recursive Self-Improvement of Agent Harnesses

RRSI regularizes recursive agent harness self-improvement via annealed edit budgets, trajectory exploration, and critical selection to boost out-of-distribution performance and reduce token use. It improves up to 14.1 points in-distribution and 4.7 points out-of-distribution while cutting policy tok

Peng Xia, Rujun Han, Zifeng Wang, Yanfei Chen and 10 more

Published Sep 21, 2026 · 0 citations · ▲ 222 on Hugging Face · Code ★ 1,274

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
89%Must read
?Must readVote to see the score

EyeRobot 2.0: Active Gaze for Precise Manipulation without Wrist Cameras

EyeRobot 2.0 uses active gaze and fixation-relative frames to enable precise bimanual manipulation with only a single stereo camera, outperforming passive stereo by 40% in real-world trials and doubling ego-plus-wrist success under occlusion.

Kush Hari, Justin H. Kerr, Nidhya Shivakumar, Samarth Mahapatra and 6 more

Published Oct 2, 2026 · 0 citations · ▲ 10 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

ProgressCompass: Embodied Progress Reward Models Are Lost Without the Right Context

Embodied progress reward models fail at long tasks due to missing context, but ProgressCompass supplies needed context to cut progress estimation errors by up to 82%.

Jianshu Zhang, Keyi Wu, Chengxuan Qian, Xiyuan Yang and 5 more

Published Sep 29, 2026 · 0 citations · ▲ 11 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

OPUS: Towards Efficient and Principled Data Selection in Large Language Model Pre-training in Every Iteration

OPUS defines optimizer-induced update-space data utility for dynamic LLM pre-training selection, outperforming full-scale baselines with minimal overhead.

Shaobo Wang, Xuan Ouyang, Tianyi Xu, Yuzheng Hu and 8 more

Published Feb 5, 2026 · 0 citations · ▲ 354 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
89%Must read
?Must readVote to see the score

MolmoAct2: Action Reasoning Models for Real-world Deployment

MolmoAct2 is an open vision-language-action model with a specialized reasoning backbone, open action tokenizer, continuous-action expert, and adaptive reasoning that outperforms closed and open baselines across embodied reasoning and robot deployment benchmarks.

Haoquan Fang, Jiafei Duan, Donovan Clay, Sam Wang and 25 more

Published May 4, 2026 · 0 citations · ▲ 357 on Hugging Face · Code ★ 794

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 3/5
89%Must read
?Must readVote to see the score

Equal Ranking Quality, Different Decisions: Measuring and Reducing Order Dependence in LLM Scorers

LLM scorers with equal ranking quality make unstable threshold and preference decisions under candidate reordering, and order-consistency fine-tuning fixes it without harming quality.

Markus Frohmann, Mahdiyar Alavi, Elizabeth Lingg, Navid Rekabsaz

Published Aug 27, 2026 · 0 citations · ▲ 17 on Hugging Face · Code ★ 2

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
89%Must read

Sharpen Without Search: On-Policy Distillation of Sequence-Level Power Distribution

On-policy power distillation trains models to generate sharpened answers directly, improving single-sample math reasoning by up to 27.3 points and outperforming multi-candidate sampling and reward-based methods.

Erfan Baghaei Potraghloo, Seyedarmin Azizi, Arya Fayyazi, Saeid Shokoufa and 3 more

Published Oct 5, 2026 · ▲ 4 on Hugging Face · Code ★ 1

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 4/5
medium 9/10
strict 3/5
89%Must read
?Must readVote to see the score

DAEDALUS: Bootstrapping Agent Memory from Self-Generated Tasks

DAEDALUS bootstraps reusable agent memory from self-generated practice tasks without oracles, improving success rates by up to 15.9 points across benchmarks.

Antoine Edy, Max Conti, Victor Xing, Marc-Antoine Allard and 2 more

Published Oct 6, 2026 · ▲ 5 on Hugging Face · Code

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 1/5
89%Must read
?Must readVote to see the score

QuantCode Model: Specializing Language Models for Executable Algorithmic Trading Code

QuantCode specializes LLMs for executable trading code via framework pretraining and validated fine-tuning, boosting backtest success to 83.5% while revealing specialization trade-offs in tool use and repair.

Alexey Chernysh, Orkhan Ekhtibarov, Dmitry Zmitrovich

Published Sep 30, 2026 · ▲ 11 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 3/5
89%Must read
?Must readVote to see the score

Labels Override Definitions in Jev-Style Typed Decision Models

Typed decision models exhibit option-label bias because prompts prepend labels to definitions, letting label semantics override rules; removing labels or altering formatting fixes it.

Seyedarmin Azizi, Erfan Baghaei Potraghloo, Massoud Pedram

Published Oct 1, 2026 · 0 citations · ▲ 5 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

HLA-WM: Hybrid Linear Attention for Long-Horizon Video World Models

HLA-WM combines geometry-guided retrieval with recurrent linear attention to fix long-range forgetting in video world models, improving 60-second consistency metrics by up to 28.5% with 12× lower memory and no retraining.

Zhuokun Chen, Feng Chen, Xi Lin, Xiyu Wu and 3 more

Published Oct 5, 2026 · ▲ 6 on Hugging Face · Code ★ 2

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
89%Must read
?Must readVote to see the score

GeoSET: Generalist Foundation Model for SAR-to-EO Image Translation

GeoSET is a generalist SAR-to-EO translation model pretrained on 3 million diverse pairs and adapted via LoRA, achieving state-of-the-art results across six benchmarks.

Jeonghyeok Do, Munchurl Kim

Published Sep 26, 2026 · 0 citations · ▲ 6 on Hugging Face · Code ★ 3

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

CARM: Cancellation-Aware Response Masking for LLM Reinforcement Learning

CARM prevents opposing token-level probability changes from canceling in sequence-level masking by using absolute log-ratios, improving RL reasoning and code benchmarks over geometric-mean masking.

Yafei Zhang, Songshuo Lu, Sicong Liao, Zhi Chen and 1 more

Published Oct 1, 2026 · 0 citations

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

SlimWise: Decoupling Expert Pruning Across Prefill and Decode for Efficient MoE Serving

SlimWise decouples MoE expert pruning across prefill and decode phases to boost serving throughput without sacrificing accuracy via direct KV cache reuse and selective distillation.

Gunho Park, Kyoungho Jeun, Juntaek Oh, Byeongjun Shin and 2 more

Published Sep 28, 2026 · 0 citations · ▲ 5 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read

FrameMorrow: Future-guided Frame Selection with Prospective Tokens for Long-Horizon Video Generation

FrameMorrow guides historical frame selection via prospective tokens representing future needs, improving consistency and quality across diverse long-horizon video generators.

Bo Yin, Xiaobin Hu, Jiaqi Zhao, Shuicheng Yan

Published Sep 30, 2026 · 0 citations · ▲ 92 on Hugging Face · Code ★ 26

100% Readers1 of 1 upvoted
14/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

CtrlCache: Accelerating Interactive Video World Models with Control-Aware Caching

CtrlCache accelerates interactive video world models via control-aware caching that detects action changes to reuse transformer residuals and apply frequency-mixed history guidance, achieving up to 1.41x speedups with improved quality.

Shangye Song, Dong Gong, Hong Jia, Yun Sing Koh and 1 more

Published Oct 6, 2026 · ▲ 1 on Hugging Face · Code

100% Readers1 of 1 upvoted
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 1/5
88%Must read
?Must readVote to see the score

Taming VLAs under Robot Execution Errors: Self-Compensation and Stress Testing

Self-compensating VLA adapts online to robot execution errors via residual feedback, improving success over 30 points on physical arms and outperforming training-time robustness methods on RoboStress.

Sohyun Lee, Yoonjae Baek, Jaesang Won, Jinnyeong Kim and 4 more

Published Sep 29, 2026 · 0 citations · ▲ 18 on Hugging Face

100% Readers1 of 1 upvoted
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Periscope: Extending Frozen Language Models Beyond Their Context Window

Periscope arranges text chunks in a grid to build an evidence map via local and strided probes, letting frozen language models answer questions across multi-million-token contexts with sublinear cost and small GPU memory.

Mohamed Eltahir, Anas Obayd, Raed Rashid, Abdulrahman Alghamdi and 4 more

Published Oct 2, 2026 · ▲ 8 on Hugging Face · Code ★ 1

100% Readers1 of 1 upvoted
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 4/5
medium 8/10
strict 2/5
88%Must read
?Must readVote to see the score

OneStreamer: Unifying Perception, Memory, and Proactive Response in Streaming Video Interaction

OneStreamer unifies streaming video perception, memory, and proactive response via shared generation, achieving top results on eight benchmarks with a 4B model.

Xiangyu Zeng, Yuandong Yang, Zhiqiu Zhang, Yuhan Zhu and 20 more

Published Oct 1, 2026 · 0 citations · ▲ 229 on Hugging Face · Code ★ 157

100% Readers1 of 1 upvoted
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

GraphForge: Training Working Agents with Graph-Anchored Workspace Synthesis

GraphForge synthesizes workspace tasks and verifiers over real file evidence graphs to train working agents, and fine-tuning Qwen3.6-27B improves GDPVal, Workspace-Bench-Lite, and SpreadsheetBench II results.

Qisheng Su, Hanchen Wang, 朱冠儒, Huicheng Jiang and 8 more

Published Sep 30, 2026 · 0 citations · ▲ 146 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Autoregressive Drillhole Modelling Under Distribution Shift

DrillBench benchmarks autoregressive drillhole modeling, finding lithology-sequence models transfer more robustly than spatial methods, and combining pretraining with retrieval improves cross-province generalization.

Yihao Ding, Daniel Yitian Su, Yiran Zhang, Christopher M. Gonzalez and 1 more

Published Oct 1, 2026 · 0 citations

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

StudentSim: Training LLM-based Student Simulators

StudentSim trains LLM student simulators via pooled training and per-student specialization, outperforming GPT-5.4 on behavioral fidelity and guidance responsiveness across chess, writing, and math.

Ke Yang, Chenglong Wang, Michel Galley, Chandan Singh and 3 more

Published Sep 1, 2026 · 0 citations · ▲ 495 on Hugging Face · Code ★ 53

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 2/5
88%Must read
?Must readVote to see the score

When to Switch: Reliable Action-Chunk Extension for Vision-Language-Action Models

RACE predicts subskill transition timing to extend VLA action chunks reliably, reducing stop-and-go idle time ~5x on real robots while improving success rates.

Seonghoon Yu, Dongwon Kim, HyungRok Jung, Yoonjae Baek and 3 more

Published Oct 5, 2026 · ▲ 13 on Hugging Face · Code ★ 3

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 1/5
88%Must read
?Must readVote to see the score

UnAct: Gradient-Free Unlearning via Targeted Activation Intervention

UnAct uses gradient-free targeted activation interventions to unlearn model classes from few forget images without gradients, labels, or retained data, matching or exceeding SSD and LFSSD accuracy across datasets and preventing network collapse with scarce data.

Saeed Abdul Muizz, Aayat Rafiq, Iqra Altaf Gillani, Janibul Bashir

Published Oct 3, 2026 · ▲ 4 on Hugging Face · Code ★ 1

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 2/5
88%Must read
?Must readVote to see the score

Self-Supervised Scaling of Terminal Environments for Scientific Domains

Software-in-the-loop reconstruction scales terminal-agent training by deriving verified tasks from existing scientific workflows without manual references, improving Terminal-Bench 2 performance to 53.56%.

Zhongzhi Li, Yucheng Shi, Zongxia Li, Junyao Yang and 7 more

Published Oct 2, 2026 · 0 citations · ▲ 10 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Dynamic Harness Search: Building Multi-Agent Systems Per-Query via Prediction

SHIFT predicts harness utility via a local LLM to search multi-agent structures per query, achieving ~80% mean accuracy across benchmarks while reducing execution tokens by 32%.

Som Sagar, Shasha Li, Hejie Cui, Ransalu Senanayake and 1 more

Published Oct 2, 2026 · ▲ 10 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 4/5
medium 8/10
strict 3/5
88%Must read
?Must readVote to see the score

Video2Skill: From Streaming Experience to Reusable Embodied Skills

Video2Skill benchmarks streaming embodied skill discovery, showing VLMs group manipulation events poorly and rarely expand skill libraries despite supervised fine-tuning.

Jianshu Zhang, Ce Zhang, Xiyuan Yang, Chenwei Xu and 5 more

Published Sep 29, 2026 · 0 citations · ▲ 11 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

YuE2: Unifying Symbolic and Audio Music Generation at Frontier Quality

YuE2 unifies symbolic and audio music generation through symbolic planning, producing readable scores and full-song audio that outperform public baselines and rival proprietary generators.

Ruibin Yuan, Jiahao Pan, Junyan Jiang, Zhiyue Wu and 31 more

Published Sep 27, 2026 · 0 citations · ▲ 245 on Hugging Face · Code ★ 10,871

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Noise Out, Bias In: Targeted Bias Injection in Diffusion Language Models via Closed-Loop Activation Steering

Targeted bias injection via closed-loop activation steering exploits diffusion language model denoising trajectories to steer frozen models toward adversarial demographic answers with minimal corruption.

Sarim Hashmi, Mukul Ranjan, Abdelrahman Elsayed, Muhammad Umer Sheikh and 2 more

Published Oct 5, 2026 · ▲ 14 on Hugging Face · Code ★ 3

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 1/5
88%Must read
?Must readVote to see the score

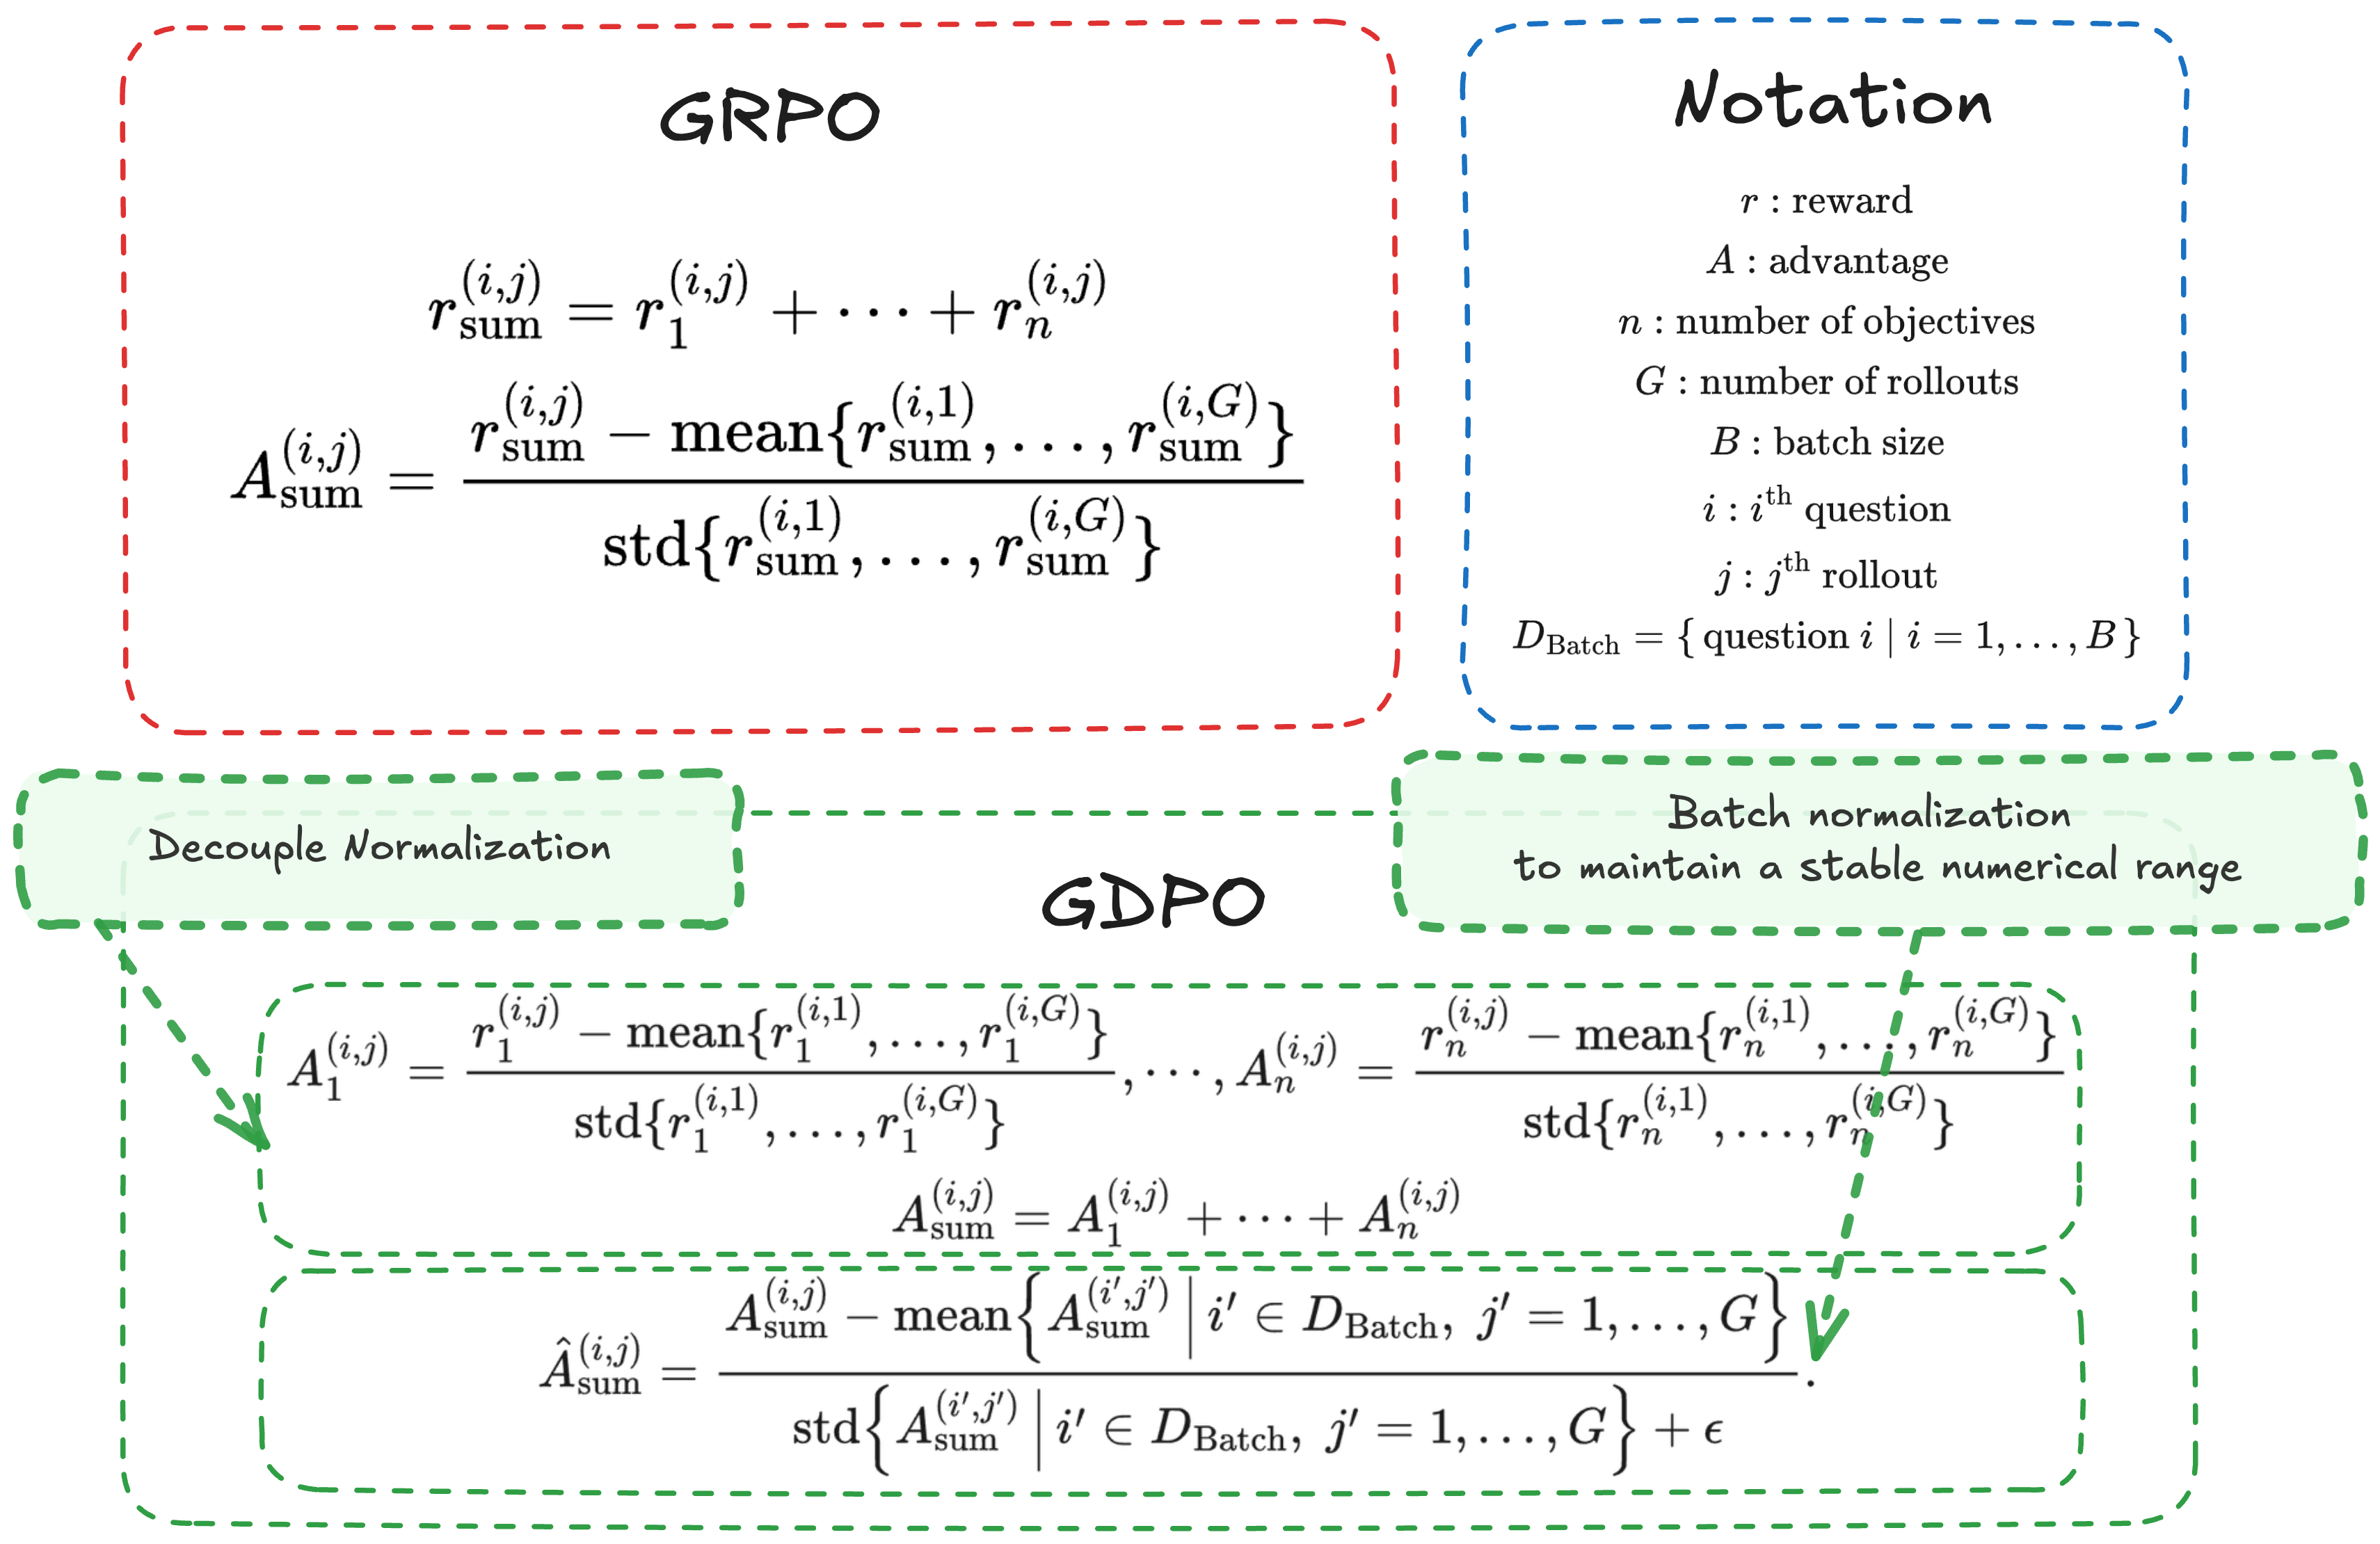
GDPO: Group reward-Decoupled Normalization Policy Optimization for Multi-reward RL Optimization

GDPO decouples per-reward normalization in multi-reward RL to prevent advantage collapse, improving training stability and outperforming GRPO on reasoning and coding tasks.

Shih-Yang Liu, Xin Dong, Ximing Lu, Shizhe Diao and 9 more

Published Jan 8, 2026 · 0 citations · ▲ 235 on Hugging Face · Code ★ 512

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 1/5
88%Must read
?Must readVote to see the score

Accent Analogy Guidance: More Speaker Similarity at Equal Accent in Cross-Lingual Voice Cloning

Accent analogy guidance subtracts estimated accent directions for cross-lingual voice cloning, raising speaker similarity above identity-accent trade-off curves across several open TTS models.

Yoomee Cho, Jisun Lee

Published Sep 24, 2026 · 0 citations · ▲ 4 on Hugging Face · Code

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 2/5
88%Must read
?Must readVote to see the score

ALoDLM: Adaptively Looped Diffusion Language Models

ALoDLM applies token-adaptive latent recurrence to diffusion language models, allocating computation by difficulty to close the quality gap with autoregressive models at 1.7B and 8B scales.

Liancheng Fang, Zhuowei Li, Youngeun Kim, Tianchen Zhao and 9 more

Published Oct 3, 2026 · ▲ 55 on Hugging Face · Code ★ 4

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 4/5
medium 9/10
strict 2/5
88%Must read
?Must readVote to see the score

EnvHarness: Awakening Static Worlds for Agent Learning

EnvHarness wraps static environments with programmable components to reshape agent behavior without altering underlying logic, improving benchmarks by up to 9.0 points while enabling continuous policy-environment co-evolution.

Chengsong Huang, Zifeng Wang, Rujun Han, Jun Yan and 13 more

Published Aug 20, 2026 · 0 citations · ▲ 175 on Hugging Face · Code ★ 618

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 1/5
88%Must read
?Must readVote to see the score

Auditing Web Agent Evaluation on WebArena-Lite: Human Review of Outcomes and Trajectories

Human audit of 165 WebArena-Lite tasks recovers 5.45, 8.49% evaluator-missed successes, reveals trajectory errors like looping, and shows guide text and MASM improve results.

Chengguang Gan, Zimeng He, Yoshihiro Tsujii, Ken-ichiro Kobayashi and 2 more

Published Oct 1, 2026 · 0 citations

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Agent Priors-guided Policy Learning

Agent Priors-guided Policy Learning embeds structural priors in skill interfaces to enable compositional and out-of-distribution skill generalization.

Puming (Oscar) Jiang, Tao Hu, Haozhe Du, Yibo Li and 3 more

Published Sep 28, 2026 · 0 citations · ▲ 84 on Hugging Face · Code ★ 3

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

The Other Half of the Memory Wall: Serving 35B MoEs from SSD with Trained Routing Prediction

Edge0 predicts next-layer MoE routing one token ahead to stream experts from SSD, serving 35B-class MoEs at 20 tok/s within 3 GiB active memory on a 24 GB machine via recovery LoRA adapters.

Yu Lin, Yiming Wang, Runyuan Cai, Liu, Hanze and 1 more

Published Sep 16, 2026 · 0 citations · ▲ 25 on Hugging Face · Code ★ 3,293

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 1/5
88%Must read
?Must readVote to see the score

On-Policy or Off-Policy Learning? A Systematic Study of Distillation Dynamics

In controlled strong-to-weak distillation, rollout policy is less central than token-level KL direction and learning rate, though on-policy data can improve generalization on harder reasoning tasks.

Julianna Piskorz, Antonin Berthon, Mihaela van der Schaar

Published Sep 28, 2026 · 0 citations · ▲ 194 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Context Language Models

Context language models treat context as self-modified files to learn context management, outperforming external strategies with lower compute and enabling in-context and parametric learning of management strategies.

Rulin Shao, Shannon Zejiang Shen, Junjie Oscar Yin, Yuetai Li and 9 more

Published Sep 29, 2026 · 0 citations · ▲ 40 on Hugging Face · Code ★ 571

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

VeriHarness: Scaling Agentic Verification for Long-Horizon Tasks

VeriHarness turns fixed base LLMs into agentic verifiers with workspaces and evidence tools, achieving top selection scores and 6.2, 6.4 point gains over single rollouts on long-horizon tasks.

Caiqi Zhang, Rujun Han, Zifeng Wang, Zoey CuiZhu and 3 more

Published Oct 1, 2026 · 0 citations · ▲ 49 on Hugging Face · Code ★ 42

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Foundations of Proactive Agents: Principles, Technical Layers, and Proactivity-Gym

Proactive LLM agents need joint optimization of task capability, temporal compute allocation, and user trust, with Proactivity-Gym exposing evaluation gaps and human preference for unobtrusive assistance.

Jio Oh, Seunghyun Do, Youngjun Lee, Steven Euijong Whang and 1 more

Published Sep 29, 2026 · 0 citations · ▲ 22 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Learning from Runtime Feedback through Failure-Bank Self-Evolution for Vision-Language-Action Models

FailBank turns runtime shield feedback into persistent VLA policy updates via failure-bank self-evolution, raising success rates up to 25.4 points and cutting policy-induced cost up to 35.6%.

Mingyue Cui, Zheyuan Liu, Yihan Zhu, Zheyuan Zhang and 1 more

Published Sep 30, 2026 · 0 citations · ▲ 15 on Hugging Face · Code ★ 2

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

KeyRec: Bounded Visual Memory for Streaming and Long-Video Understanding

KeyRec creates bounded visual memory via recent caches and structured event banks to enable efficient long-video and streaming understanding with only 10% of visual tokens, outperforming compressed baselines.

Zihan Chen, Xuejian Rong, Xiaojuan Wang, Boqing Gong and 3 more

Published Sep 26, 2026 · 0 citations · ▲ 11 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

More Choices, Fewer Decisions: Ordinal-Scale Bias in JEV-like Direct-Decision Models

Direct-decision JEV models show ordinal scale-utilization bias, compressing decisions to 26, 76% of gold support despite high accuracy, but BA-LoRA post-training improves utilization to 86%.

Tianxiang Gao, Jinzhe Li, Zhiyuan Li, Yi Chang and 1 more

Published Sep 30, 2026 · 0 citations · ▲ 60 on Hugging Face · Code ★ 3

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Language Models that Play Chess and Explain Their Moves

Queen, a 4B-parameter chess-language model, plays at grandmaster level and explains moves via cross-attention to a silent expert encoder and iterative Bellman-style explanation distillation, surpassing larger frontier models.

Adithya Bhaskar, Jeffrey Cheng, Danqi Chen

Published Oct 2, 2026 · 0 citations · ▲ 31 on Hugging Face · Code ★ 18

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

MetaRubric: Learning to Reward for Rubric-Based Reinforcement Learning

MetaRubric fixes vacuous rubric credit via evidence-aware optimization and counterfactual rubric adaptation, improving PubMedQA accuracy by up to 20.40 points over static-judge GRPO.

Yuxuan Fan, Jaehong Yoon

Published Oct 2, 2026 · 0 citations · ▲ 22 on Hugging Face · Code ★ 2

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read

PaLoRA: Paced Low-Rank Adaptation for Continual Learning

PaLoRA derives an optimal rank-aware pacing law for LoRA continual learning that adaptively restricts gradient scaling to prevent forgetting, improving long-horizon benchmark accuracy by 4%.

Yuxuan Li, Fanhu Zeng, Hao Tang

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published Oct 3, 2026 · ▲ 9 on Hugging Face · Code ★ 2

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 1/5
88%Must read
?Must readVote to see the score

FairRSFM: A Biome-Aware Benchmark and Debiasing Framework for Remote Sensing Foundation Models

FairRSFM benchmarks remote sensing foundation models by biome to expose hidden ecological performance disparities and tests debiasing methods without backbone updates. Aggregate metrics consistently mask large biome-dependent gaps, though mitigation effectiveness varies by model and task.

Md Aminur Hossain, Omkumar Vaghasiya, Rajeev Ranjan Dwivedi, Vinod Kurmi and 1 more

Published Oct 5, 2026 · ▲ 5 on Hugging Face · Code

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 2/5
88%Must read
?Must readVote to see the score

Match the Distribution, Not the Compute: Post-Training Multi-Token Prediction Heads

Post-training multi-token prediction heads on ~2.5B chain-of-thought tokens match pretraining speedups with 10^3-10^4x less data, while chain-aware verification and adaptive head selection boost throughput up to 16%.

Prachi Badarayani, Aidan Jay, Chenghui Zhou, Dayquan Julienne and 7 more

Published Oct 1, 2026 · 0 citations

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Mid-Harness: Scaling Actions Between Model and Harness for Terminal Agents

Mid-Harness verifies candidate terminal actions at the model-harness boundary, raising TerminalBench-Lite Pass@1 from 50.00% to 68.03% and improving success at lower token cost than trajectory scaling alone.

Minki Kang, Ryo Hachiuma, Shaokun Zhang, Subhashree Radhakrishnan and 7 more

Published Sep 30, 2026 · 0 citations · ▲ 116 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Transformers Stop Thinking Too Early, and a Tiny LoRA Fixes It

Pretrained transformers stop following references after 1.4, 3.6 lines, but a rank-8 LoRA at one early layer extends computation to 50, 160 lines without changing frozen weights.

Zehao Jin, Ruixuan Deng, 君然 王

Published Sep 29, 2026 · 0 citations · ▲ 75 on Hugging Face · Code ★ 3

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Base Models Can Reason By Taking a Cue From Training Data

Fixing initial token cues in base models boosts reasoning to match RL performance, with effects traced to training data associations that can be causally edited.

Sophie L. Wang, Amil Dravid, Rulin Shao, Kevin Farhat and 2 more

Published Oct 5, 2026 · ▲ 12 on Hugging Face · Code ★ 2

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 4/5
medium 9/10
strict 2/5
88%Must read
?Must readVote to see the score

A Safe Action Is Not Enough: Feasible-Future Decoding for Vision-Language-Action Policies

Feasible-future decoding reranks VLA actions by future safe-completion mass, reducing cumulative safety costs by up to 57.5% without retraining or rollouts.

Tu Nguyen, Matthieu Zimmer, Vu Anh Vu, Ziyi Wang and 3 more

Published Oct 4, 2026 · ▲ 3 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 1/5
88%Must read
?Must readVote to see the score

GUI-HARVEST: Self-Improving GUI Agents through Evidence-Driven Harness Evolution

GUI-HARVEST optimizes executable harnesses for frozen GUI agents by aligning visual effects, comparing task runs, and consolidating failure patterns into reusable source edits, improving OSWorld-Verified by up to 12.33 points.

Geyi Yang, Zikun Qu, Xiang Li, Zhiyong Wang and 3 more

Published Oct 1, 2026 · 0 citations · ▲ 5 on Hugging Face · Code ★ 2

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Code Owns the Simulation, Jev Owns the Evaluation

Judgment models excel at evaluation but fail at simulation, yet pairing them with code simulation yields expert control.

Yaodong Yang, Hongyao Tang, Yi Ma, Xingyu Fan and 3 more

Published Oct 1, 2026 · 0 citations

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read

Rethinking Cross-Tokenizer On-Policy Distillation: From Alignment Coverage to Supervision Reliability

Cross-tokenizer on-policy distillation achieves comparable accuracy with strict top-16 shared-vocabulary supervision versus full coverage, while expanded span supervision reduces accuracy due to conflicting gradients, motivating prioritization of supervision reliability over alignment coverage.

Bingxi Hou, Guochao Jiang, Guofeng Quan, Weiqing Li and 3 more

Published Oct 6, 2026 · ▲ 40 on Hugging Face

100% Readers1 of 1 upvoted
13/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 13 of 20 reviewers recommend it
lenient 4/5
medium 7/10
strict 2/5
86%Must read
?Must readVote to see the score

Learning Steadily: Accumulating Relative Point Margin Scores for Face Image Quality Assessment

CARPM-FIQA accumulates relative point margin scores across training epochs to stabilize face image quality estimates, reducing variance and improving ranking stability near top performance.

Guray Ozgur, Tahar Chettaoui, Eduarda Caldeira, Marco Huber and 3 more

Published Sep 15, 2026 · ▲ 6 on Hugging Face

100% Readers1 of 1 upvoted
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 13 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 0/5
86%Must read
?Must readVote to see the score

EditHero: A Benchmark for Long-Horizon Part-Level 3D Editing and Vibe Modeling

EditHero benchmarks long-horizon part-level 3D editing via sequential instructions and target images, finding agentic code-based methods preserve unedited regions better but are slower than non-agentic regeneration.

Ruihan Yu, Yu-Ju Tsai, Muyao Niu, Runyi Li and 8 more

Published Oct 1, 2026 · 0 citations · ▲ 50 on Hugging Face · Code ★ 12

100% Readers1 of 1 upvoted
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

AutoSciBench: Autonomous Benchmark Generation for Evaluating Scientific Agents

AutoSciBench autonomously generates and iteratively adapts scientific agent benchmarks via recipes and concepts, reducing solver accuracy by over 22 points versus human benchmarks while improving quality ratings.

Dongki Kim, Namkyeong Lee, Surag Nair, Carl Edwards and 6 more

Published Oct 4, 2026 · ▲ 17 on Hugging Face

100% Readers1 of 1 upvoted
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 13 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 1/5
86%Must read
?Must readVote to see the score

WEFT: Scaling Tool-Use Post-Training for General-Purpose Agents

WEFT evolves whole agentic interaction systems for tool-use post-training, outperforming environment-scaling baselines by up to 12.27 points across benchmarks.

Bo Mao, Hang He, Linting Wang, Lizhi Lin and 16 more

Published Sep 29, 2026 · 0 citations · ▲ 19 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

SimuVerity: Benchmarking Agents for Engineering-Grade Simulink Model Generation

SimuVerity benchmarks text-to-executable Simulink generation across engineering domains, finding best agents score only 42.86 and structural similarity poorly predicts engineering performance.

Ruiqi Zhang, Jiahao Wang, Mingxuan Li, Haichen Luo and 8 more

Published Oct 1, 2026 · ▲ 47 on Hugging Face · Code ★ 19

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 2/5
86%Must read
?Must readVote to see the score

Foresight: planning future perception in streaming VLMs without retraining

FORESIGHT uses dual-stream anticipatory planning in frozen streaming VLMs to dynamically configure future perception, improving online benchmarks by up to 18.7 points without retraining.

Ashok Prasad Neupane, Dipan Bartaula, Ankit Belbase, Saugat Adhikari and 4 more

Published Oct 2, 2026 · 0 citations · ▲ 3 on Hugging Face · Code

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

TextReg: Mitigating Prompt Distributional Overfitting via Regularized Text-Space Optimization

TextReg mitigates prompt distributional overfitting via regularized text-space optimization, improving out-of-distribution accuracy by up to 16.5% over prior methods.

傅卢成, Ye Yu, Yiyang Wang, Yiqiao Jin and 3 more

Published May 20, 2026 · 0 citations · ▲ 7 on Hugging Face · Code

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 0/5
86%Must read
?Must readVote to see the score

SkillOpt: Executive Strategy for Self-Evolving Agent Skills

SkillOpt treats agent skills as external state optimized via bounded text edits validated on held-out scores, improving accuracy up to 24.8 points with stable transfer.

Yifan Yang, Ziyang Gong, Weiquan Huang, Qihao Yang and 11 more

Published May 22, 2026 · 2 citations · ▲ 266 on Hugging Face · Code ★ 18,062

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 4/5
medium 8/10
strict 2/5
86%Must read
?Must readVote to see the score

UNREAL: Unifying Retrieval and Long-Context with a Single Model

UNREAL unifies retrieval and long-context evidence selection via frozen LLM representations with minimal parameters, outperforming state-of-the-art retrievers and improving long-context accuracy substantially.

Edan Kinderman, Elad Hoffer, Yochai Blau, Brian Chmiel and 3 more

Published Oct 6, 2026 · ▲ 15 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 4/5
medium 7/10
strict 3/5
86%Must read

Recursive Multi-Agent Systems

RecursiveMAS scales multi-agent collaboration through recursive latent-space computation via RecursiveLink and inner-outer loop co-optimization, improving accuracy by 8.3% with 1.2-2.4x speedup and 34.6%-75.6% token reduction over baselines.

Jiaru Zou, Rui Pan, Ruizhong Qiu, Pan Lu and 7 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published Apr 28, 2026 · 0 citations · ▲ 239 on Hugging Face · Code ★ 961

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 2/5