CROSS introduces a pre-commitment localization layer using continuous SE(3) pose branches and Gaussian-mixture filtering to reject false matches, improving long-term robot relocalization and semantic navigation under severe scene changes.
BitDance is an autoregressive image generator that predicts binary visual tokens via a diffusion head and next-patch decoding, achieving state-of-the-art FID with far fewer parameters and much faster inference.
MedVIGIL evaluates medical vision-language models under broken visual evidence via clinician-supervised probes, revealing a 14.1-point gap between top models and radiologist reliability.
Fine-tuning LLMs on documents that flag claims as false makes them believe those claims, with belief rates jumping from 2.5% to 88.6%, though local negation phrasing largely prevents it.
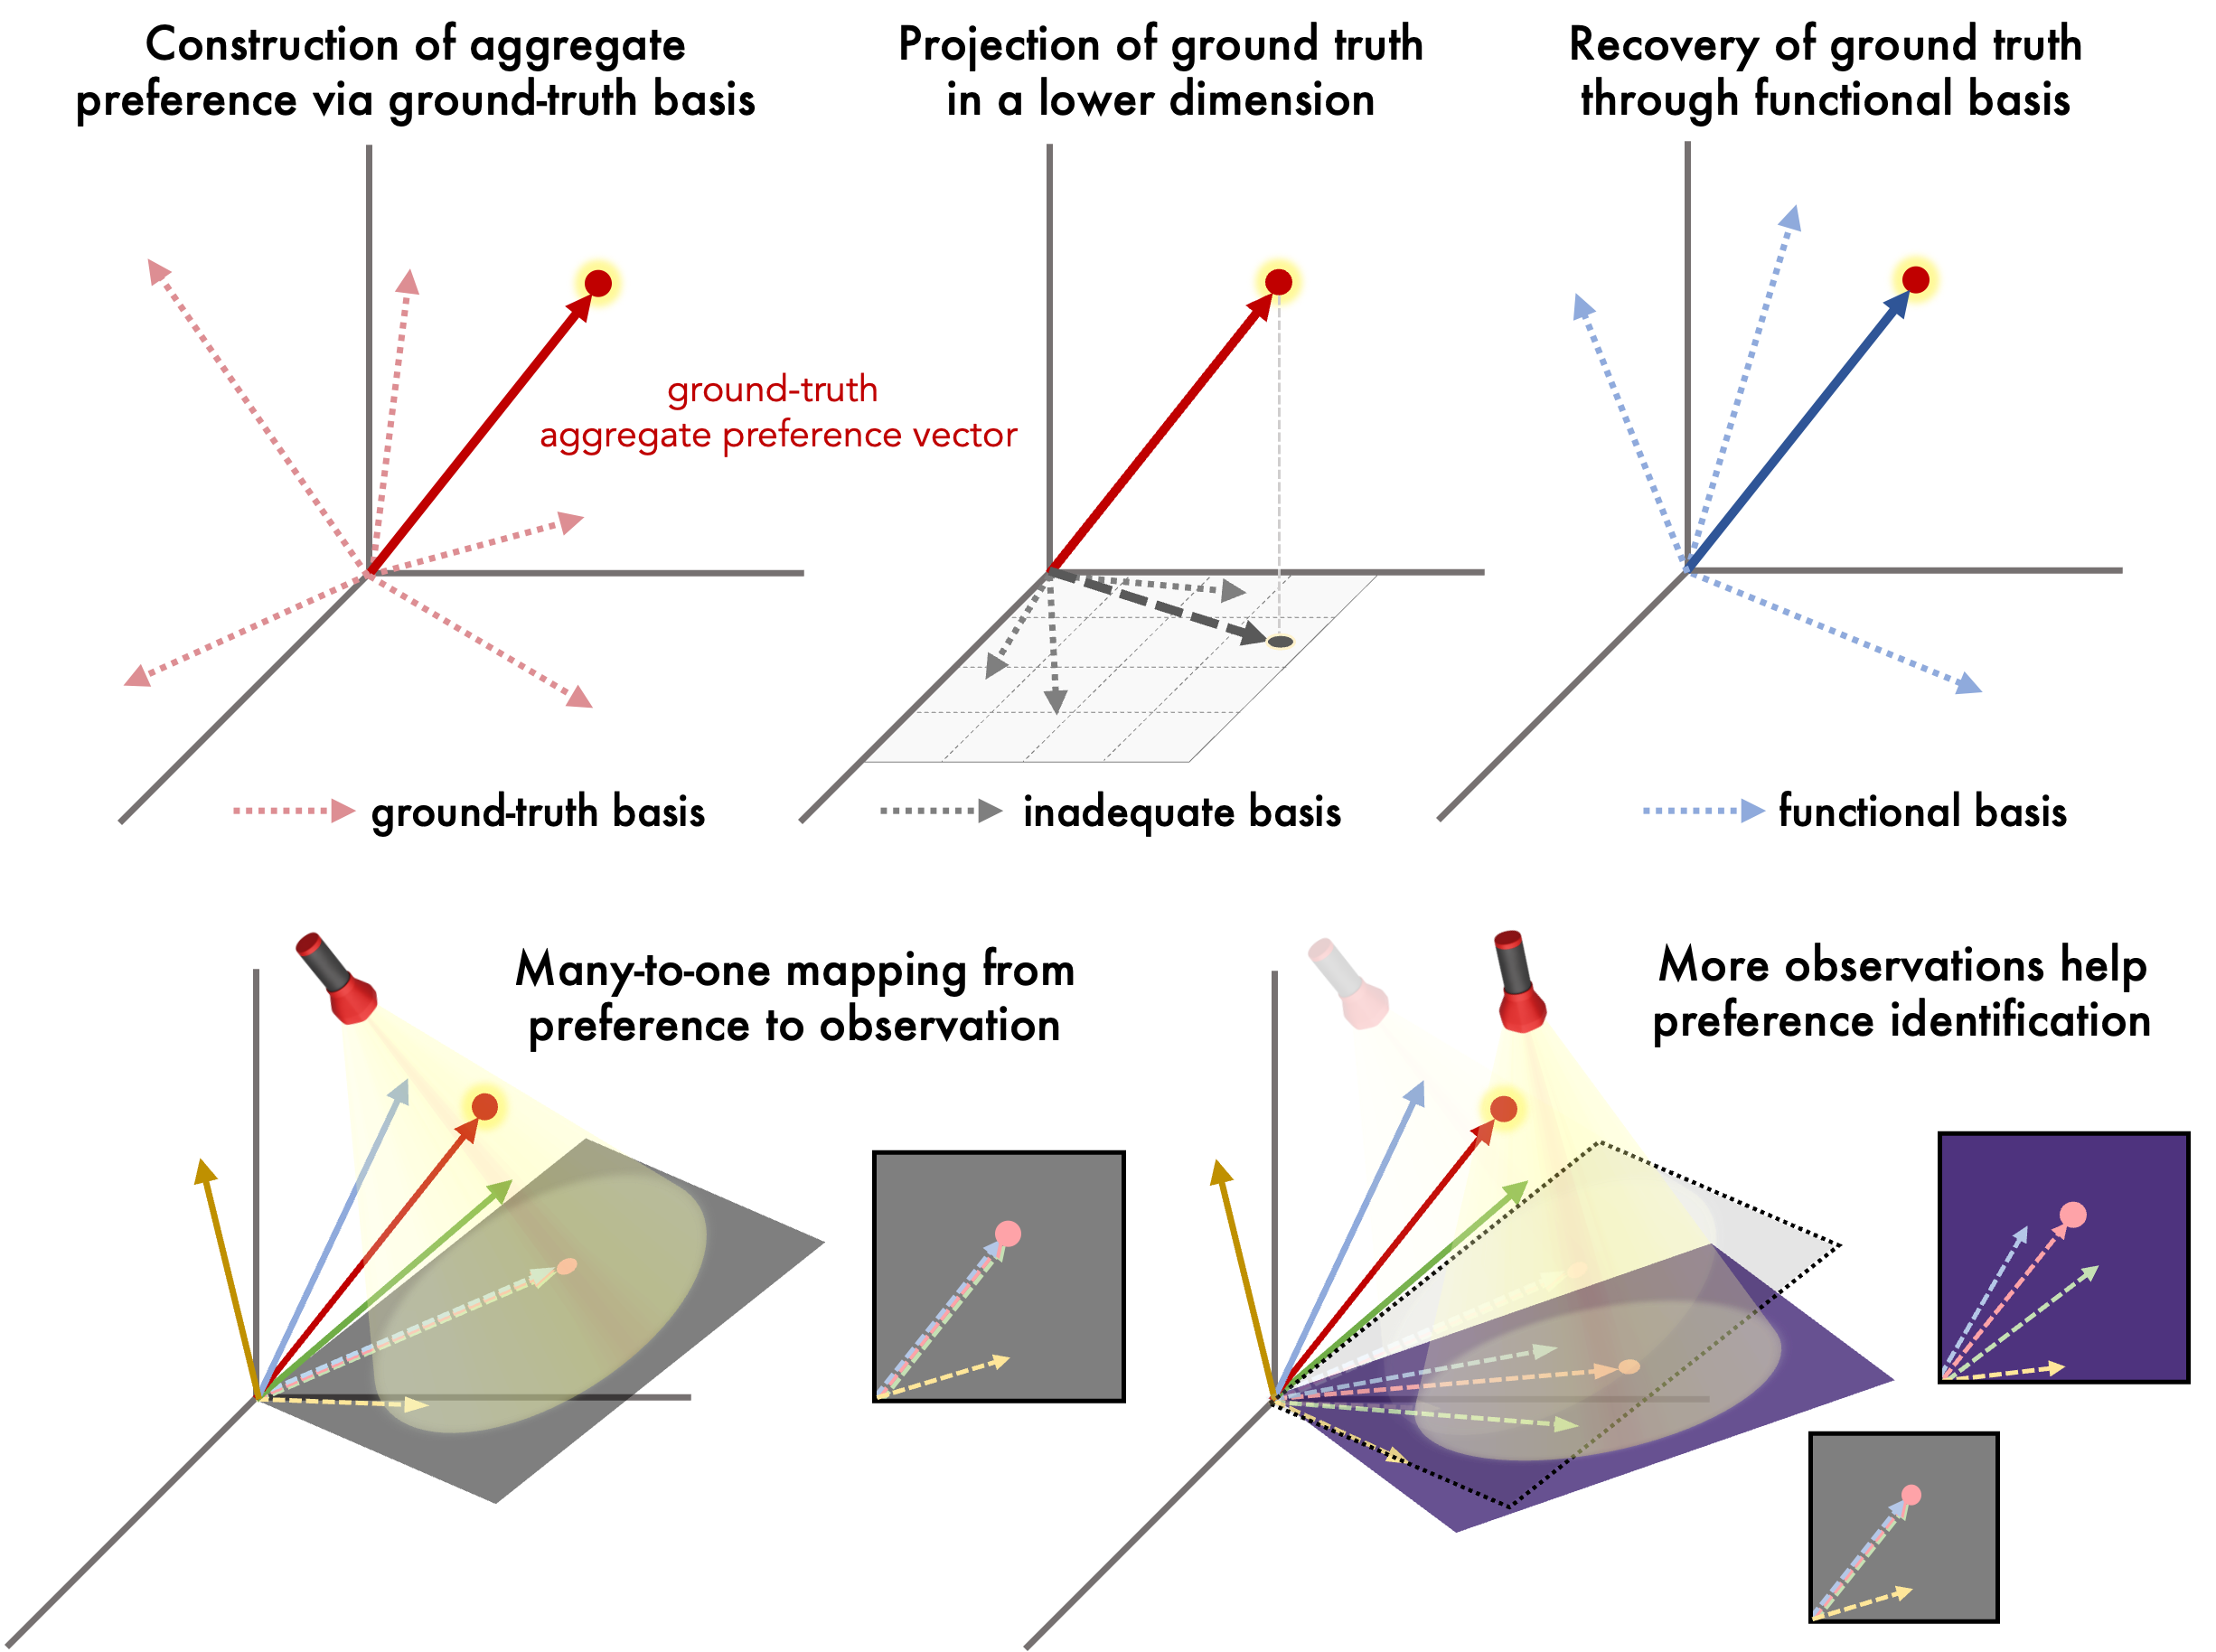
P2P uses adaptive prompting and L1-regularized regression to build compact LLM ensembles that emulate human preferences at low cost without fine-tuning. It achieves 0.014 test MSE on American Trends Panel surveys for about $0.80 each and outperforms supervised baselines with under 3% of their traini
OneSearch-V2 uses thought-augmented query understanding and reasoning self-distillation to improve generative search, boosting item CTR by 3.98% without added latency.
UFCOD uses diffusion score geometry to enable cross-domain OOD detection with ~100 unlabeled ID samples and no retraining, achieving 93.7% AUROC across 12 benchmarks with ~500x sample efficiency gains.