Good Papers

Showing papers from University of Texas at Arlington Show all papers

45%Niche pick
?Niche pickVote to see the score

gHAWK: Structural Encoding for Scalable Training of Graph Neural Networks on Knowledge Graphs

Humera Sabir, Fatima Farooq, Ashraf Aboulnaga

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Learning Data-free Universal Adversarial Perturbation with Hybrid Priors and Gradient-Guided Sharpness Regularization

Zhi Tan, Jiazheng Cui, Wenwen Zhang, Yiran Liu and 3 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

MVPISplat: Multi-View Photometric Inconsistency for Defending 3D Gaussian Splatting Attacks

Md Mahedi Hasan Rigan, Nicole Meng, Miao Yin, Yingjie Lao and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Towards Matrix-Parallel and Feature-Scalable 3D Gaussian Splatting Rendering on GPUs

Yangming Zhang, Siyi Wu, Jian Wang, Bingzhe Li and 4 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Mitigating Data Heterogeneity Effect in Client-Reshuffling-Based Federated Learning

Su Zhang, Peiran Yu, Heng Huang

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
67%Highly rated
?Highly ratedVote to see the score

UniPro: Unified Multi-Mode Medical Image Segmentation from 2D Images to 3D Volumes via Propagation

Bangwei Guo, Yunhe Gao, Meng Ye, Yang Zhou and 4 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
2/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 2 of 20 reviewers recommend it
lenient 2/5
medium 0/10
strict 0/5
83%Must read
?Must readVote to see the score

LEAD: Length-Efficient Adaptive and Dynamic Reasoning for Large Language Models

LEAD adaptively calibrates reasoning length via online self-adaptive rewards, achieving highest accuracy and efficiency scores with shorter outputs than base reasoning models.

Songtao Wei, Yi Li, Zhikai Li, Xu Hu and 6 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 6 on Hugging Face · Code ★ 4

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 13 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 0/5
78%Highly rated
?Highly ratedVote to see the score

Leveraging Latent Visual Reasoning in Silence

Latent visual reasoning enhances multimodal training despite being largely unused at inference; attention-based reinforcement learning preserves its benefits by promoting latent-text interaction during training.

Dongyao Zhu, Zhen Wang, Xi Xiao, Han Jiang and 6 more

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 4/5
medium 6/10
strict 1/5
89%Must read
?Must readVote to see the score

A World Model of Radiologist Reading for Medical Image Representation Learning

GazeWorld models radiologist eye-tracking as fixation trajectories through images to pretrain medical representations that achieve state-of-the-art diagnostic and gaze prediction accuracy without requiring real gaze data at inference.

Yiwei Li, Zihao Wu, huaqin zhao, Yifan Zhou and 4 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 3/5
71%Highly rated
?Highly ratedVote to see the score

Low-Rank Adaptation for Critic Learning in Off-Policy Reinforcement Learning

Low-rank adaptation regularizes critic learning by constraining updates to low-dimensional subspaces via frozen base weights, reducing loss and improving off-policy RL performance.

Yuan Zhuang, Yuexin Bian, Sihong He, Jie Feng and 6 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 7 of 20 reviewers recommend it
lenient 4/5
medium 3/10
strict 0/5
71%Highly rated
?Highly ratedVote to see the score

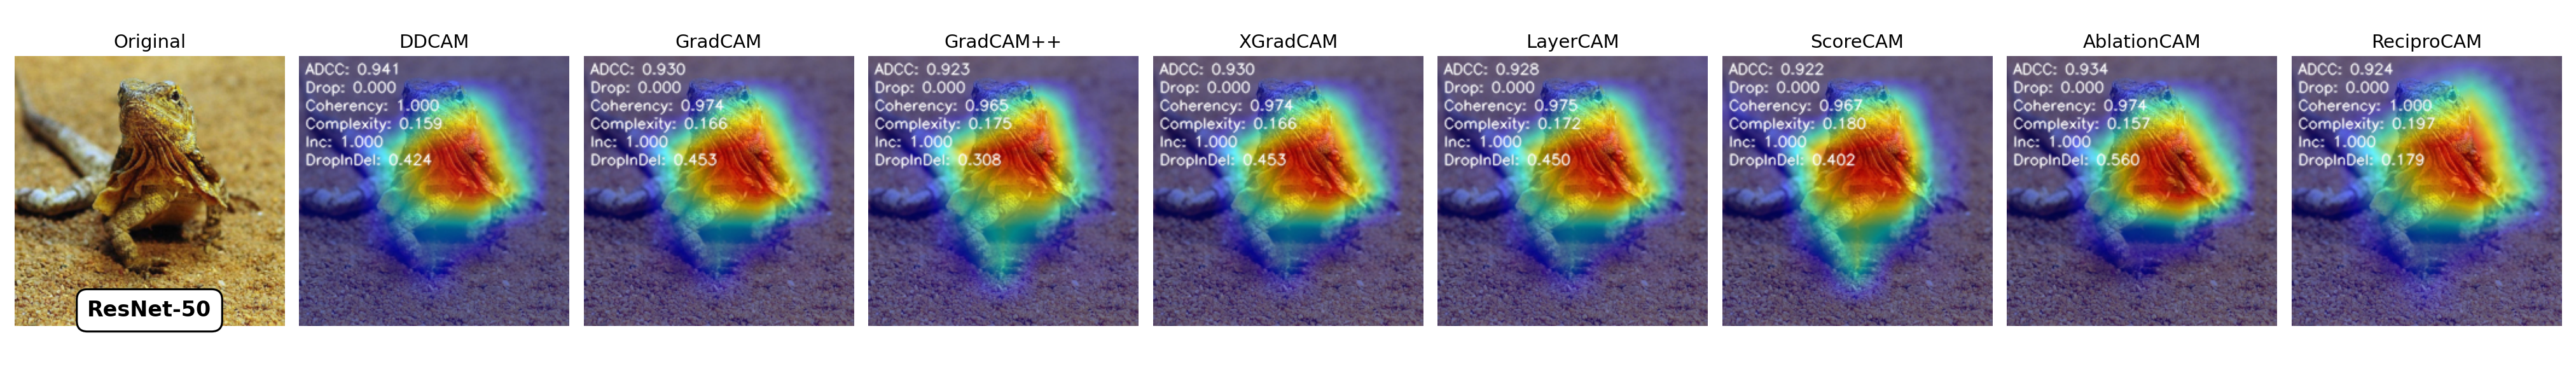
DD-CAM: Minimal Sufficient Explanations for Vision Models Using Delta Debugging

DD-CAM uses delta debugging to find minimal sufficient vision-model units, yielding more faithful, accurate saliency maps than CAM methods.

Krishna Khadka, Yu Lei, Raghu Kacker, D. R Kuhn

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 7 of 20 reviewers recommend it
lenient 4/5
medium 3/10
strict 0/5