DD-CAM: Minimal Sufficient Explanations for Vision Models Using Delta Debugging
DD-CAM uses delta debugging to find minimal sufficient vision-model units, yielding more faithful, accurate saliency maps than CAM methods.
Published 2026Atlanta Poster Session 4 · Thu, Dec 10, 4:30 PM–7:30 PM local time · Hall C1arXiv ↗OpenReview ↗
Only vote on papers you've read. Sign in with GitHub to vote.
Abstract
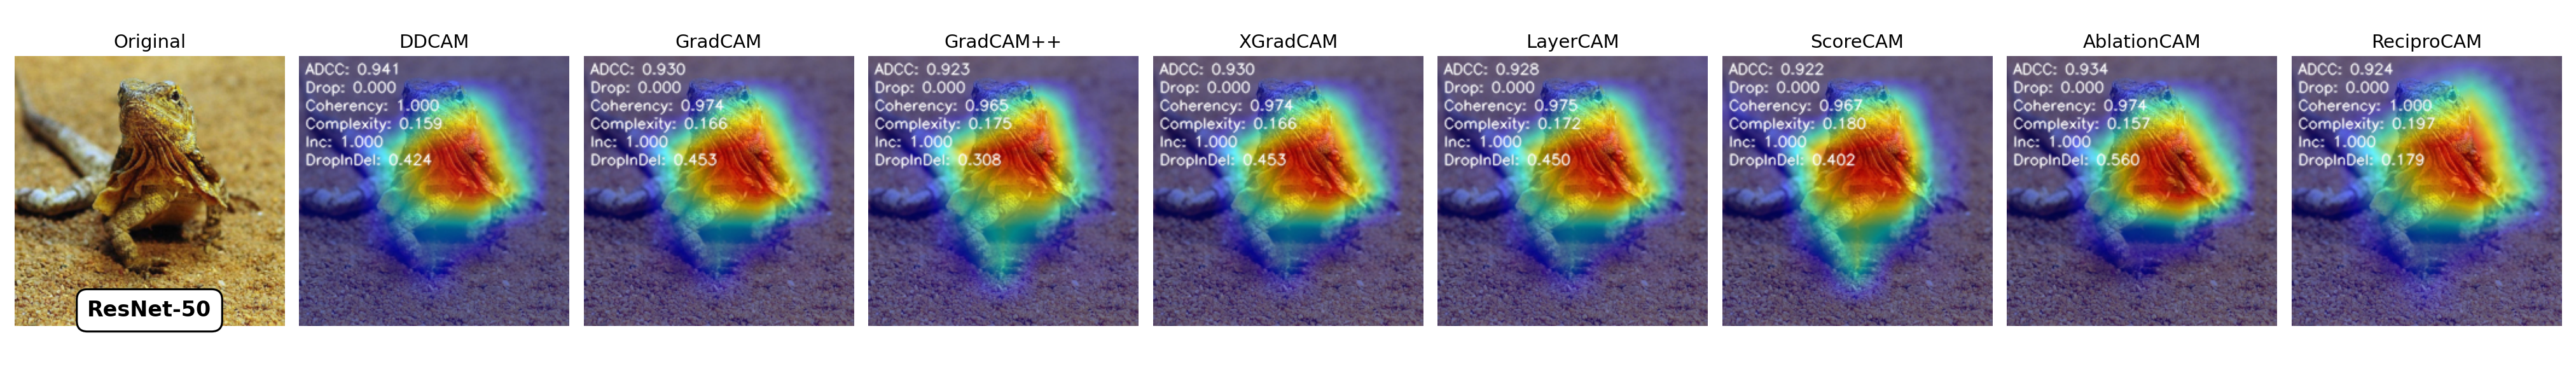
We introduce a gradient-free framework for identifying minimal, sufficient, and decision-preserving explanations in vision models by isolating the smallest subset of representational units whose joint activation preserves predictions. Unlike existing approaches that aggregate all units, often leading to cluttered saliency maps, our approach, DD-CAM, identifies a 1-minimal subset whose joint activation suffices to preserve the prediction (i.e., removing any unit from the subset alters the prediction). To efficiently isolate minimal sufficient subsets, we adapt delta debugging, a systematic reduction strategy from software debugging, and configure its search strategy based on unit interactions in the classifier head: testing individual units for models with non-interacting units and testing unit combinations for models in which unit interactions exist. We then generate minimal, prediction-preserving saliency maps that highlight only the most essential features. Our experimental evaluation demonstrates that our approach can produce more faithful explanations and achieve higher localization accuracy than the state-of-the-art CAM-based approaches.