Good Papers

Showing RL for LLMs Show all papers

82%Must read
?Must readVote to see the score

Sherpa: Teaching LLMs to Teach Adaptively

Sherpa uses multi-turn reinforcement learning to train LLM teachers that adapt instructions to diverse student archetypes, improving student performance by 20.5 points and pedagogy scores to 79.2%.

Weixian Xu, Yanzhe Zhang, Zora Zhiruo Wang, Changyu Chen and 1 more

Published Oct 6, 2026 · ▲ 3 on Hugging Face · Code

100% Readers1 of 1 upvoted
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 0/5
84%Must read
?Must readVote to see the score

TRACE: Rollout-Guided Quantization-Aware Training for FP4 Reinforcement Learning of MoE Language Models

TRACE aligns FP4 quantization between RL training and rollout paths via rollout-guided quantization-aware training for MoE language models, achieving BF16-comparable RL performance with up to 5.4x rollout speedup.

Xin Wang, Hao Yu, Zhengyang Zhuge, Bochao Mao and 8 more

Published Oct 6, 2026 · ▲ 15 on Hugging Face

100% Readers1 of 1 upvoted
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 1/5
80%Must read
?Must readVote to see the score

NeMo-DCR: Bit-Exact Delta-Compressed Refit for Scalable Agentic RL at Trillion-Parameter Scale

NeMo-DCR bit-exactly refits trillion-parameter policies by streaming delta-compressed weight changes via affine mappings and XOR masks, cutting 1T cross-region refits from 87.5 minutes to 150 seconds.

Songlin Jiang, Zhiyu Li, Terry Kong, Yu Yao and 4 more

Published Oct 6, 2026 · ▲ 6 on Hugging Face · Code ★ 2,048

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 4/5
medium 6/10
strict 2/5
84%Must read
?Must readVote to see the score

HiPLEX: Hierarchical Policy Factorization for Full Duplex Speech Language Models

HiPLEX factorizes full-duplex speech policies into timing and content controllers to jointly optimize interaction dynamics via reinforcement learning. It lowers takeover rates, reduces interruption latency, and improves human-like turn timing versus GRPO.

Kyudan Jung, Hyunsin Park, Yoonhyung Lee, Jinhwan Park and 4 more

Published Oct 6, 2026

100% Readers1 of 1 upvoted
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 1/5
76%Highly rated
?Highly ratedVote to see the score
NeurIPS 2026RL for LLMs

Rationale-Guided Policy Optimization: Learning to Reason with Adaptive Rationale Scaffolding

RGPO adaptively uses ground-truth rationales as temporary scaffolds to generate improved responses for on-policy RL, then transfers only higher-reward model outputs back, reducing reward sparsity and improving text and multimodal reasoning.

Hoang Phan, Minh Pham, Chau Pham, Chinmay Hegde and 2 more

Published Oct 5, 2026 · ▲ 7 on Hugging Face · Code ★ 1

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 10 of 20 reviewers recommend it
lenient 4/5
medium 6/10
strict 0/5
78%Highly rated
?Highly ratedVote to see the score

LoGRA: Scaling LLM Reinforcement Learning with Low-Rank Gradient Sketches

LoGRA reduces LLM reinforcement learning memory by up to 45.7% via low-rank gradient sketches and predicted-KL step control, enabling 27B-parameter training on single nodes.

Shaokun Zhang, Yifan Zhang, Jian Hu, Yueying Li and 4 more

Published Oct 5, 2026 · ▲ 11 on Hugging Face

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 5/10
strict 1/5
80%Must read
?Must readVote to see the score

OPD Before RL: Warm-Starting Rubric-Based RL with On-Policy Distillation

Rubric-privileged on-policy distillation before reinforcement learning improves open-ended task scores and reduces reward hacking versus supervised fine-tuning baselines.

Xinpeng Wang, Wei Shi, Yu-Chia Chen, Maria Zontak and 2 more

Published Oct 2, 2026 · 0 citations · ▲ 3 on Hugging Face

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

MetaRubric: Learning to Reward for Rubric-Based Reinforcement Learning

MetaRubric fixes vacuous rubric credit via evidence-aware optimization and counterfactual rubric adaptation, improving PubMedQA accuracy by up to 20.40 points over static-judge GRPO.

Yuxuan Fan, Jaehong Yoon

Published Oct 2, 2026 · 0 citations · ▲ 22 on Hugging Face · Code ★ 2

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read

Sharpening Tax in Post-Training

Post-training sharpens base model behaviors at the cost of solution coverage, introducing a quantifiable "Sharpening Tax"; a posterior-tempered group sampler reduces this tax while boosting accuracy.

Changdae Oh, Qi Zeng, Qi Qi, Andrey Zhmoginov and 6 more

Published Oct 1, 2026 · 0 citations · ▲ 102 on Hugging Face · Code ★ 25

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

From Gradients to Capabilities: Understanding Multi-Teacher On-Policy Distillation

Multi-teacher on-policy distillation integrates RL teacher gradients via loss averaging, Adam smoothing, and BF16 rounding, with averaging rules significantly altering math accuracy outcomes.

Siqi Zhu, Suozhi Huang, Kaixuan Zhang, Yuheng Yang and 3 more

Published Oct 1, 2026 · 0 citations · ▲ 13 on Hugging Face

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Does Scaling Reinforcement Learning Really Require More Training?

SURGE extracts stronger policies from fixed RL histories via spectral fusion of checkpoints, exceeding native training-curve accuracy without extra training or inference cost.

Bangji Yang, Jiajun Fan, MA Hongba, Ruihan Guo and 1 more

Published Oct 1, 2026 · 0 citations

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

83%Must read
?Must readVote to see the score

My FAULT: Self-Diagnosis as Credit Assignment in Self-Evolving Agentic Reinforcement Learning

FAULT turns self-diagnosed errors into step-level credit via terminal outcome anchoring and evidence-checked cost learning, recovering 95% signal coverage on ALFWorld and improving long-horizon agentic RL.

Yihua Zhu, Qianying Liu, Weixu Qiao, Xuan Ren and 9 more

Published Oct 1, 2026 · 0 citations

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read
?Must readVote to see the score

Function-Structured Reinforcement Learning with Executable Verifiers for Mathematical Reasoning

FSG-RL connects subproblem graphs with Python code and multi-verifier feedback to improve math reasoning, raising final-answer accuracy from 43.25% to 67.50% over supervised fine-tuning.

Zihan Liu, Xurong Xie

Published Oct 1, 2026 · 0 citations

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

CARM: Cancellation-Aware Response Masking for LLM Reinforcement Learning

CARM prevents opposing token-level probability changes from canceling in sequence-level masking by using absolute log-ratios, improving RL reasoning and code benchmarks over geometric-mean masking.

Yafei Zhang, Songshuo Lu, Sicong Liao, Zhi Chen and 1 more

Published Oct 1, 2026 · 0 citations

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read
?Must readVote to see the score

Make Sparse Rewards Count: Density-Aware Reward Aggregation for Multi-Reward RL

DARA corrects batch-level reward imbalance via inverse-square-root active-group density weights, accelerating multi-reward RL training by up to 65% with no objective change.

Tong Zheng, Skylar Zhai, Zhan Cheng, Tianming Sha and 6 more

Published Sep 30, 2026 · 0 citations · ▲ 64 on Hugging Face · Code ★ 2

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

70%Highly rated
?Highly ratedVote to see the score

Small RL Controller, Large Language Model: RL-Guided Adaptive Sampling for Test-Time Scaling

A lightweight RL controller formulates adaptive sampling as an MDP to balance LLM answer correctness, latency, and computation cost at test time.

Runpeng Dai, Tong Zheng, Rui Liu, Chengsong Huang and 1 more

Published Jun 2, 2026 · 0 citations · ▲ 13 on Hugging Face

– ReadersNo votes yet
5/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read
?Must readVote to see the score

Too Correct to Learn: Reinforcement Learning on Saturated Reasoning Data

Reinforcement learning on saturated reasoning data causes mode collapse as advantage signals vanish; CUTS sampling and Mixed-CUTS restore diversity, boosting AIME25 accuracy by up to 15.1%.

Zhenwen Liang, Yujun Zhou, Sidi Lu, Xiangliang Zhang and 2 more

Published Apr 20, 2026 · 0 citations

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

76%Highly rated
?Highly ratedVote to see the score

AI Can Learn Scientific Taste

RLCF trains AI to judge and propose high-impact research ideas via community feedback, showing learned scientific taste generalizes across fields and time.

Jingqi Tong, Mingzhe Li, Hangcheng Li, Yongzhuo Yang and 19 more

Published Mar 15, 2026 · 0 citations · ▲ 316 on Hugging Face · Code ★ 433

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

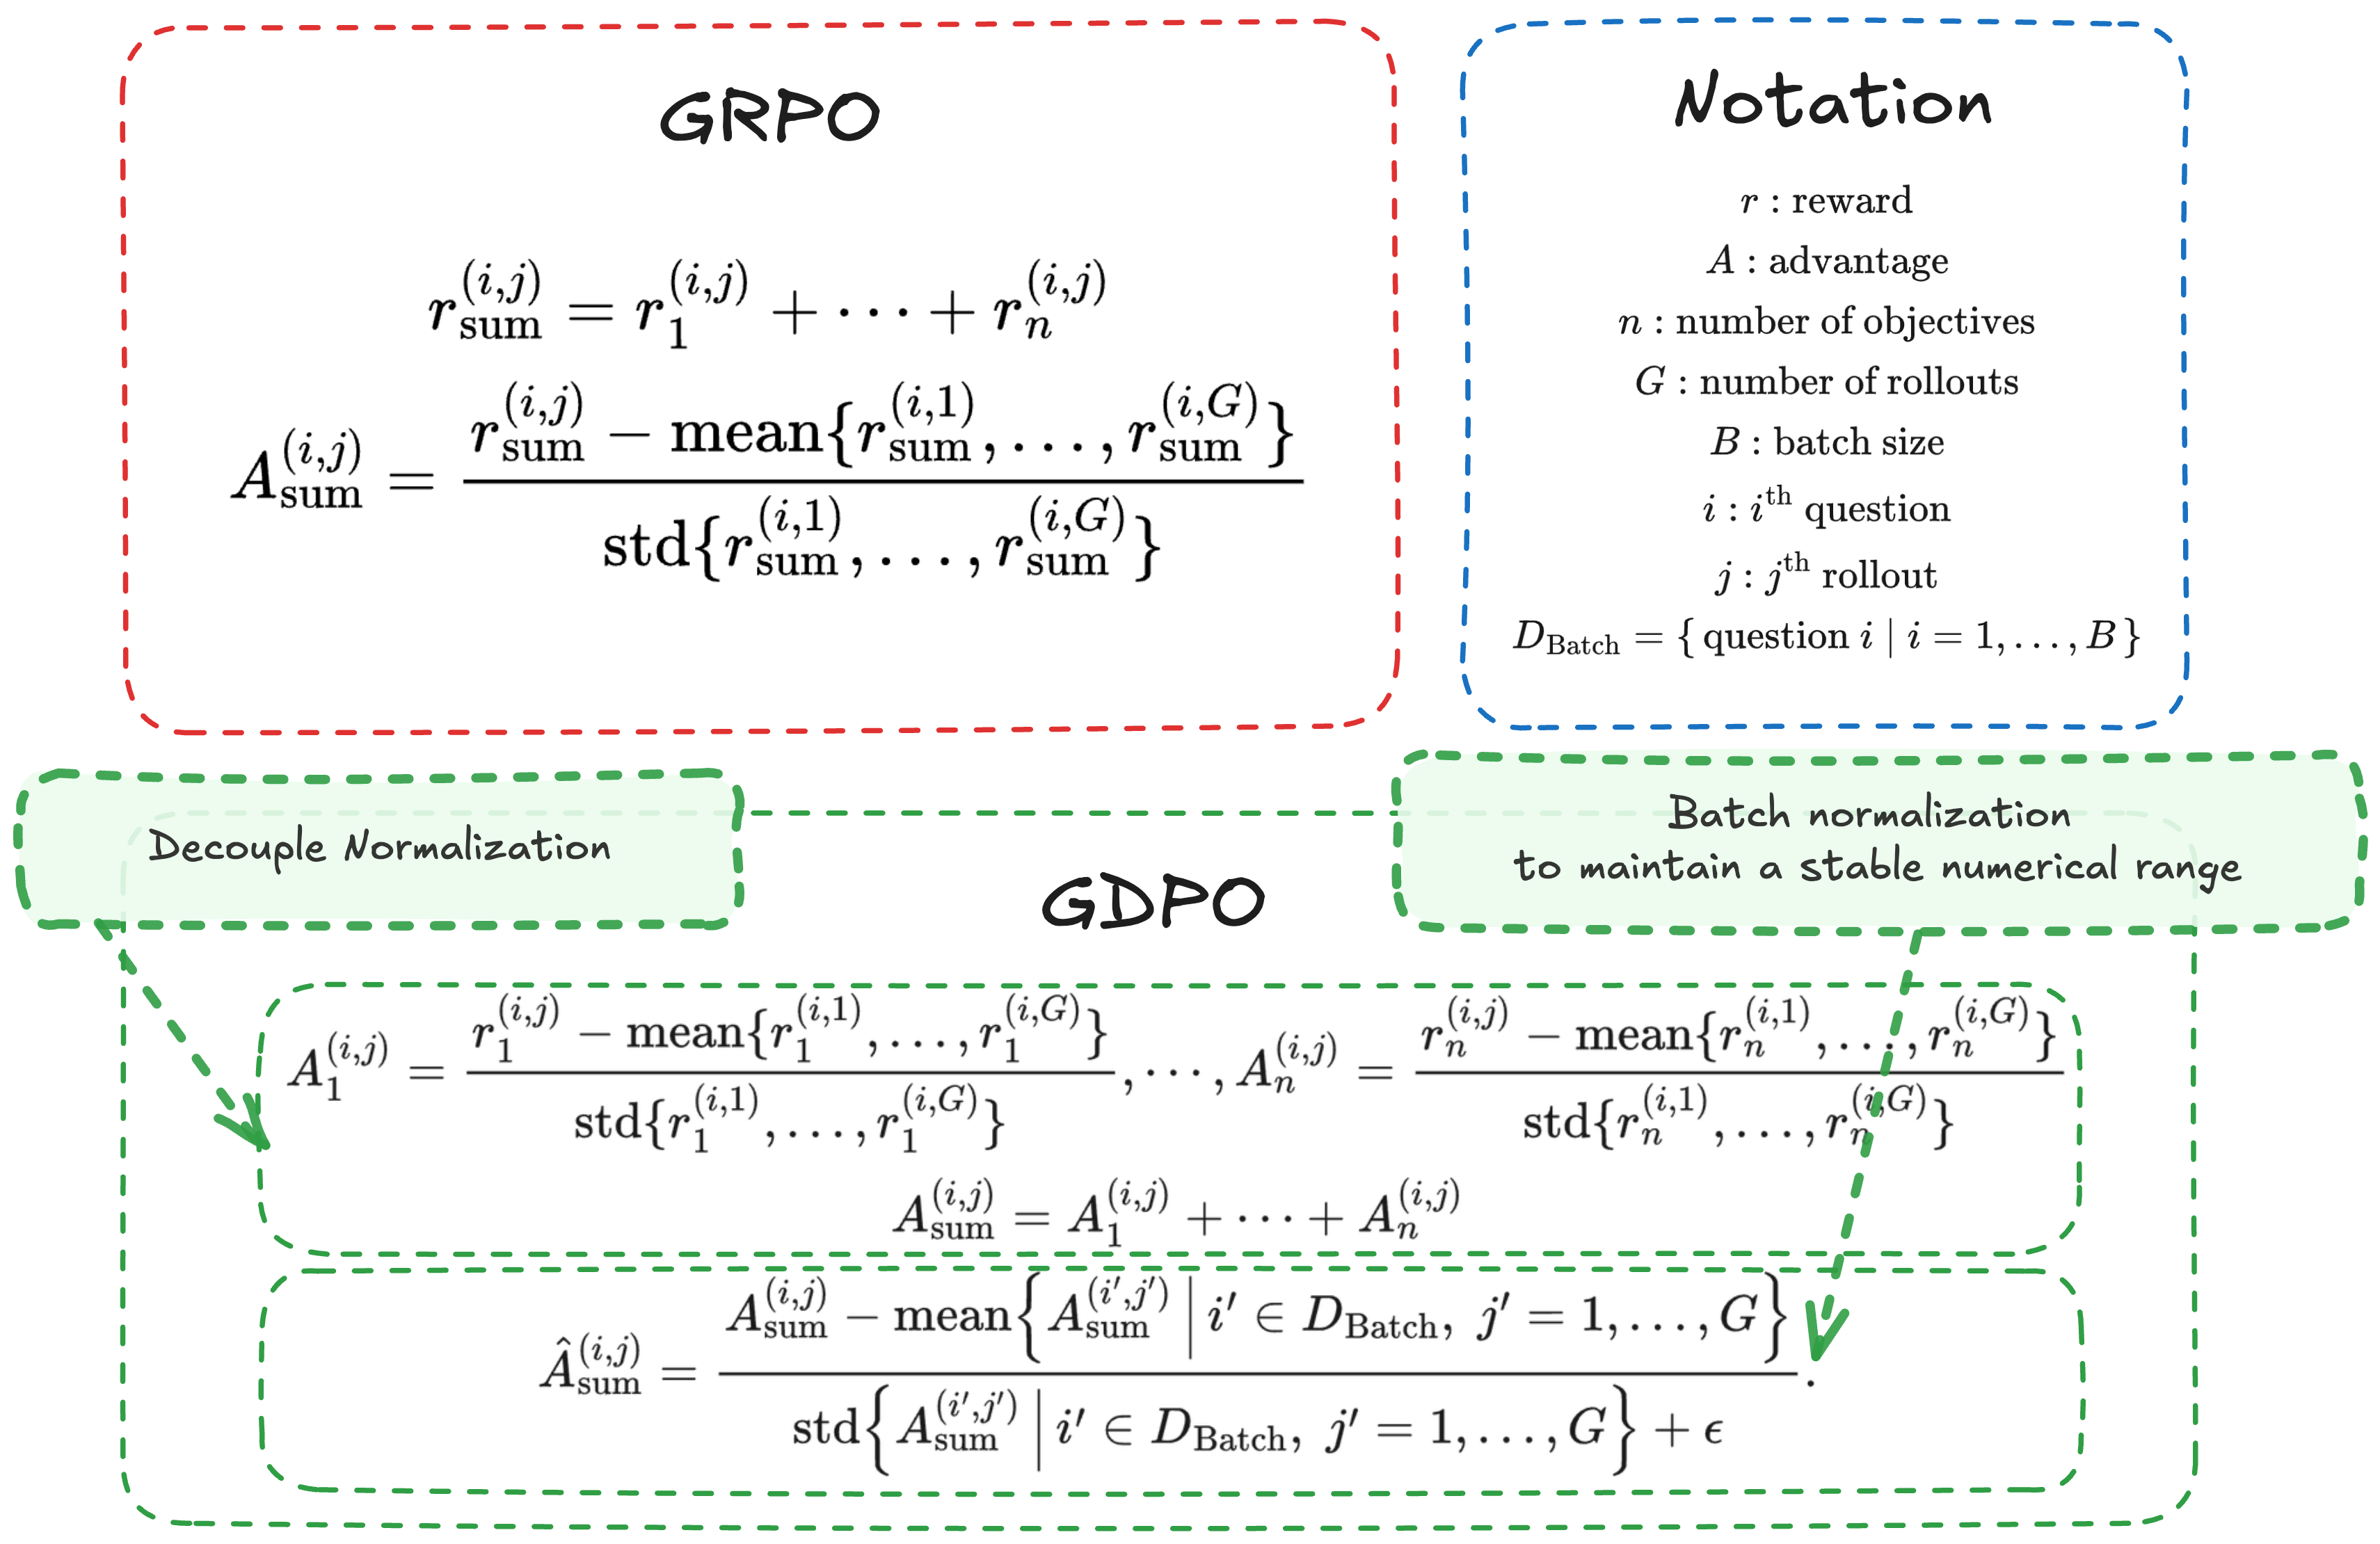
GDPO: Group reward-Decoupled Normalization Policy Optimization for Multi-reward RL Optimization

GDPO decouples per-reward normalization in multi-reward RL to prevent advantage collapse, improving training stability and outperforming GRPO on reasoning and coding tasks.

Shih-Yang Liu, Xin Dong, Ximing Lu, Shizhe Diao and 9 more

Published Jan 8, 2026 · 0 citations · ▲ 235 on Hugging Face · Code ★ 512

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

83%Must read
?Must readVote to see the score

Too Correct to Learn: Reinforcement Learning on Saturated Reasoning Data

Standard RL collapses on saturated reasoning data due to vanishing advantage signals, so CUTS sampling and Mixed-CUTS training restore exploration and boost AIME25 Pass@1 by 15.1%.

Zhenwen Liang, Yujun Zhou, Sidi Lu, Xiangliang Zhang and 2 more

Published 2026 · 0 citations

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

74%Highly rated
?Highly ratedVote to see the score

Native Parallel Reasoner: Reasoning in Parallelism via Self-Distilled Reinforcement Learning

NPR enables LLMs to self-evolve genuine parallel reasoning via self-distilled reinforcement learning, achieving up to 24.5% accuracy gains, 4.6x speedups, and 100% parallel execution.

Wu, Tong, Liu, Yang, Bai, Jun, Jia, Zixia and 5 more

Published Dec 8, 2025 · 0 citations · ▲ 80 on Hugging Face · Code ★ 112

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

83%Must read
?Must readVote to see the score

Parallel-R1: Towards Parallel Thinking via Reinforcement Learning

Parallel-R1 uses a progressive curriculum combining supervised warmup and reinforcement learning to train large language models in parallel reasoning, achieving significant gains on math benchmarks by treating parallel thinking as a temporary exploration scaffold that unlocks higher final performanc

Zheng, Tong, Hongming Zhang, Wenhao Yu, Xiaoyang Wang and 6 more

Published Sep 9, 2025 · 0 citations · ▲ 105 on Hugging Face · Code ★ 265

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Highly rated
?Highly ratedVote to see the score

Co-Evolving Policy Distillation

Co-Evolving Policy Distillation co-trains experts via bidirectional online policy distillation during RLVR to avoid divergence and absorption gaps, integrating multi-modal reasoning to surpass domain-specific experts.

Naibin Gu, Chenxu Yang, Qingyi Si, Chuanyu Qin and 6 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 67 on Hugging Face

100% Readers1 of 1 upvoted
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 10 of 20 reviewers recommend it
lenient 2/5
medium 7/10
strict 1/5
91%Must read
?Must readVote to see the score

ECHO: Terminal Agents Learn World Models for Free

ECHO trains terminal agents to predict environment responses for dense supervision, doubling GRPO pass@1 on TerminalBench-2.0.

Vaishnavi Shrivastava, Ahmed Awadallah, Dimitris Papailiopoulos

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 7 on Hugging Face

– ReadersNo votes yet. 1 from authors or colleagues not counted
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 18 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 3/5
45%Niche pick
?Niche pickVote to see the score

VSPO: Vector-Steered Policy Optimization for Controllable Model Behavior

Xuechen Zhang, Zijian Huang, Kai Yang, Weijia Zhang and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Self-Calibrated GUI Reward Model via Inverse Dynamic Modeling

Zeyi Sun, Shengyuan Ding, Xingpeng Xia, Jinsong Li and 3 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

A Theoretical Framework for Self-Play Theorem Proving Algorithms

Thomas Chen, Zhiyuan Li

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Large Discrete Policy: Advancing Explicit Behavior Modeling with Stochastic Iterative Scoring

Zhenxin Li, Nadine Chang, Xinglong Sun, Jingde Chen and 7 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Are we really tilting? The mechanics of reward guidance in flow and diffusion models

Sanjit Dandapanthula, Nicholas Boffi

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Never Stop Learning: Test-Time Reinforcement Learning for Vision-Language-Action Models

Xinying Yi, Jingjing Jiang, Chao Ma

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

WATERFALL: Workflow for Adaptive Training with Evolutionary Reward Formulation and Automated Learning Loops

Eleftherios Triantafyllidis, Filippos Christianos, Zhibin Li, Bernd Bickel

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Negative-Only Policy Optimization for One-Sided Verifiable Rewards

Jiacheng Xu, Shuo He, Fuxiang Zhang, Chaojie Wang and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

RAHF: Reward-Amplified Human Feedback for Closed-Loop Policy Fine-Tuning

Haoyuan Cai, Seth Zhao, Jason Zhang, Bolei Zhou

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score
NeurIPS 2026RutgersRL for LLMs

Compositional Policy Optimization with Language Models

Wensen Mao, Yuanlin Duan, He Zhu

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

$f$-GRPO & Beyond: Divergence-Based Reinforcement Learning Algorithms for General LLM Alignment

Rajdeep Haldar, Lantao Mei, Guang Lin, Yue XING and 1 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

GraphMemRL: Action-Native Reinforcement Learning for Persistent Graph Memory Construction

Bingcheng Dong, Shenglan Liu, Sifan Zhang, Jirui Tian and 1 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

PRISM:Disentangling Preference Distributions for Generative Ranking

zhangkai wu, Kaize Shi, Xu Zhang, Zhihong Cui and 1 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Train at the Moving Edge: Rollout-Efficient RL for Large Reasoning Models

Jiahao Wu, Ning Lu, Shengcai Liu, Kun Wang and 5 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Reasoning Warm-up: Scaling Label-free RL via Verifiable Surrogate Rewards

Jun Nie, Bo Han, Jiaqi Fan, Yonggang Zhang and 3 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Agent$^2$ RL-Bench: Can LLM Agents Engineer Agentic RL Post-Training?

Wanyi Chen, Xiao Yang, Xu Yang, Tianming Sha and 6 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Principled Policy Optimization for LLMs via Self-Normalized Importance Sampling

Huiyang Shao, Xintong Zhang, Junyi Liu

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Stable and Granular Policy Optimization for Generative Recommendation

Muyu Zou, Haibo Xing, Hao Deng, Zhezheng Hao and 5 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Reinforcement Learning with Verifiable Physics: Post-training LLMs for PDE Solver Generation

Pengfei Cai, Utkarsh Utkarsh, Alan Edelman, Christopher Rackauckas and 1 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

67%Highly rated
?Highly ratedVote to see the score

Imitation Dominates Reinforcement: Direct In-Context RL Is Closer to ICL Than RL

Minchan Kwon, Seunghee Koh, Sunghyun Baek, Minsung Bae and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
2/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 2 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 1/5
45%Niche pick
?Niche pickVote to see the score

SPRM: From Cooperative Games to Marginal-Contribution Process Reward Modeling

Yu Bao, Pak Lon Ip, Qiyu Ruan, Xitong Gao and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Efficient Gradient-Aware Asynchronous Reinforcement Learning for LLM Post-Training

Songhan Yang, Jie Wang, Yinqi Bai, Tong Xialiang and 3 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score
NeurIPS 2026RL for LLMs

Correctable Fork Tokens: Verifier-Anchored Selective Credit Assignment for Tool-Integrated RLVR

Shuqi Yin

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
67%Highly rated
?Highly ratedVote to see the score

Multi-Turn RL Makes Small Language Model Competitive for Optimization Modeling

Xinzhi Zhang, Zeyi Chen, Humishka Zope, Hugo Barbalho and 5 more

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
2/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 2 of 20 reviewers recommend it
lenient 2/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Relaxed On-Policy Distillation: Selective Credit Allocation for Scaling Reasoning Efficiently

Jongwoo Ko, Sara Abdali, Young Jin Kim, Tianyi Chen and 1 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score
NeurIPS 2026TongjiRL for LLMs

TPO: Tri-level Distributionally Robust Learning for OOD Direct Preference Optimization

Chengtao Jian, Kai Yang

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Auto-Rubric as Reward: From Implicit Preference to Explicit Generative Criteria

Juanxi Tian, Fengyuan Liu, Jiaming Han, Yilei Jiang and 5 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Are Easier or Harder Examples Better? Rethinking Data Selection for Reward Models and Preference Optimization

Kevin Christian Wibisono, Aya Ismail, Pedro O. Pinheiro, Yixin Wang and 3 more

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

C-GRPO: Conformal Group Relative Policy Optimization

Arya Fayyazi, Seyedarmin Azizi, Mehdi Kamal, Massoud Pedram

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

SDAE: Semantic-Diversity-Aware Exploration for Efficient Reinforcement Learning in Large Language Models

Jianwen Sun, Wangzi Shi, Sannyuya Liu, Zhiming Wang and 3 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

LADDERS: Length-Aware Data Distribution and Existing-Response Speculation for Fast RL Rollout Generation

Shengpeng Yin, Hui-Ling Zhen, Xing Li, Mingxuan Yuan and 2 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score
NeurIPS 2026SpotlightStanfordU WashingtonRL for LLMs

Rethinking Visual Reasoning in Text-to-Image Reward Modeling

Shiye Su, Xiaohan Wang, Ludwig Schmidt, Serena Yeung-Levy

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Reward Shaping to Improve Language Model Query Generation

Shicheng Liu, Zeyu Zhang, LEI LU, Kexuan Sun and 1 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

When Scores Conflict with Preferences: Calibrated Drift Control for Heterogeneous DPO

Ping Liu, Yan Yan

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

From Ideas to Code: Tree-structured Policy Optimization for Automated Algorithm Design with LLMs

Rui Zhang, Ping Guo, Liyong Lin, Zhichao Lu and 1 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Merging RLVR-Trained Experts via Policy-Shift-Guided Spectral Alignment

Geeho Kim, MINSIK CHOI, Kyle Min, Young Geun Kim and 1 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Cornerstones or Stumbling Blocks? Deciphering the Rock Tokens in On-Policy Distillation

Yuxuan Jiang, Runchao Li, Shubhashis Roy Dipta, Dawei Li and 1 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

67%Highly rated
?Highly ratedVote to see the score

How Data Scales in Agentic Reinforcement Learning: Laws and Synthesis Strategies

Bowei He, Yankai Chen, Xiaokun Zhang, Changjiang Han and 3 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
2/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 2 of 20 reviewers recommend it
lenient 1/5
medium 1/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

HyperSkill: Training-Free Omnimodal GRPO via Hypergraph-Indexed Skill-Library Evolution

Haoran Luo, Shangkai Lin, Jinyang Wu, XINLIANG ZHOU and 1 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Predicting Human-Gain Curves under Local Proxy Optimization from Repeated Ratings

Moonwon Choi, Kisung Nam, Seunggeun Lee

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Aligning LLMs Toward Multi-Turn Conversational Outcomes Using Iterative RLHF

Daniel Jiang, Ankur Samanta, Yukai Yang, Jalaj Bhandari and 2 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

CTRL: Continual Test-Time Reinforcement Learning for Large Language Models

Chu Zhao, Enneng Yang

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

SPRING: Solver-guided Process Rewards for Novel Logical Reasoning Steps Generation

Muhammad Asif Ali, Mohammad Raza, Wenqing Wang, Huan Wang

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Control Reinforcement Learning: Token-Level Mechanistic Analysis via Learned SAE Feature Steering

Seonglae Cho, Zekun Wu, Adriano Koshiyama

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Reward Budgeting Reduces Premature Convergence in Reinforcement Learning for LLM Reasoning

Mengni Jia, Mengyu Zhou, xiaoxi jiang, Guanjun Jiang

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Fast-RL: Accelerating Reinforcement Learning for LongCoT Reasoning Models

Sitong Wu, Haoru Tan, bin xia, Bei Yu and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Historical Relative Policy Optimization for Bootstrapping LLM Reasoning

Sitong Wu, Haoru Tan, Bei Yu, Xiaojuan Qi and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Unveiling Entropy-Performance Decoupling in Agentic RL for Tool-Integrated Reasoning

Yirong Zeng, Shen You, Yufei Liu, Hao Cong and 9 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

ASTOR: Multi-Task Code Reinforcement Learning via Utility-Driven Coordination

Yujia Chen, Yang Ye, Xiao Chu, Yuchi Ma and 1 more

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

MaxIM: Maximally Informative Incremental Summarization via Reinforcement Learning

Jihwan Jeong, Guy Tennenholtz, Yinlam Chow, Chih-wei Hsu and 1 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Stop Calling It Reinforcement Learning in Language Models Without Clear Improvement Claims: Decision-Process Cards as a Reporting Standard

Anvi Kohli, Vedant Khandelwal, Rishit Agarwal, Rahul Maity and 1 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score
NeurIPS 2026BaiduRL for LLMs

Knowledge-Level Consistency Reinforcement Learning: Dual-Fact Alignment for Long-Form Factuality

Junliang Li, Yucheng Wang, Yan Chen, Yu Ran and 4 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Reformulate LLM Reinforcement Learning for Stable Training under Black-box Discrepancy

Jiashun Liu, Runze Liu, Xu Wan, Jing Liang and 2 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

The Heel of RLVR: Benchmark Glory Should Not Outpace Honest Measurement

Shuo Yang, Chiyu Ma, Kexin Huang, Jinda Lu and 10 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

The Capability Frontier of GRPO

Rithvik Redrouthu, Jackson Stokes

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

OPPO: Bayesian Value Recursion for Token-Level Credit Assignment in Policy Optimization

Yu Li, Rui Miao, Tian Lan, Zhengling Qi

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

Show 20 more papers