Good Papers

Showing Optimization Show all papers

45%Niche pick
?Niche pickVote to see the score

Generalization Analysis of Biased Stochastic Gradient Methods for Minimax Problems

Shuang Zeng, Yunwen Lei, Yiming Ying

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score
NeurIPS 2026SpotlightPekingOptimization

How Can SignSGD Outperform SGD? A Functional Scaling Law Perspective

Zilin Wang, Binghui Li, Jia-Nan Wang, Lean Wang and 2 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Diversity Maximization: Algorithms for Distant $k$-Subsets

Shayan C Jahan, Hamed Abdi, Ali Ahmadi, Javier Marinković and 1 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Stable Max Coverage Under a Cardinality Constraint

Themistoklis Haris, Fabian Spaeh, Nithin Varma, Yuichi Yoshida

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Scalable Supervised Optimal Transport of Gaussian Mixture Models

Damin Kühn, Michael T Schaub

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Reliable Clustering and Quantization via Distortion-Constrained Optimal Transport

Tianhao Wu, Wei Zhang, Haoran Pang, Haoran YANG and 1 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Neural Dual Bounds: Valid-by-Construction JGLP Warm-Starts for MAP and Constrained MAP

Akshay Vyas, Shivvrat Arya, Brij Malhotra, Tahrima Rahman and 2 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Optimizing Analytic Constants via AI-Guided Lean Proof Refinement

Rahul Saha, Alan Li, Anton Xue, Adam Klivans and 3 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score
NeurIPS 2026PekingOptimization

Query Lower Bounds for Approximating the Top Eigenvector of Asymmetric Matrices

Kun Chen, Zhihua Zhang

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

GEAR: A GPU-Accelerated Global Solver for Nonlinear Programs via Linear Bound Propagation

Duo Zhou, Hesun Chen, Xiangru Zhong, Grani A. Hanasusanto and 1 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Differentiable Range-Partition Entropy for Entropy-Sensitive Geometric Algorithms

Ibne Farabi Shihab, Sanjeda Akter, Anuj Sharma

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Fully First-Order Algorithms for Online Non-Convex Bilevel Optimization

Tingkai Jia, Ting Wang, Cheng Chen

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Algorithms for Linear Equations with Min and Max Operators Under (Absolutely) Halting Condition

Krishnendu Chatterjee, Ruichen Luo, Raimundo Saona, Jakub Svoboda

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Efficient Algorithms for Distributed Saddle Problems

Ruichen Luo, Anton Rodomanov, Sebastian Stich

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Gibbs Gradient Descent: A Langevin Approach to Optimization

Oussama Zekri, Anna Korba, Nicolas Boulle

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

On Generalization in Bilevel Optimization with Overparameterized Models

Fares El Khoury, Edouard Pauwels, Samuel Vaiter, Michael Arbel

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Gradient Descent on Two ReLU Neurons: Global Landscape and Bifurcation Dynamics

Binghua Li, Mengzhe Li, Denny Wu, Tianhao Wang

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Follow the Regularized Leader Does Not Converge in Constrained Optimization

Ioannis Anagnostides, Ioannis Panageas, Nikolas Patris, Tuomas Sandholm

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 1/5
45%Niche pick
?Niche pickVote to see the score

$\gamma$-weakly $\theta$-up-concavity: A Unified Framework for Non-Convex Optimization Beyond DR-Submodular and OSS Functions

Mohammad Pedramfar, Vaneet Aggarwal

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Dual-Space Preconditioning for Variational Inequalities and Root-Finding Problems

Jan Quan, Konstantinos Oikonomidis, Alexander Bodard, Panagiotis Patrinos

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Orthogonal Updates for the Win: Towards Accelerated Adaptive Minimax Optimization

Zhiwei Zhai, Xinyu Wang, Wenjing Yan, Lei Ding and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Curvature-Dependent Lower Bounds for Riemannian Online Convex Optimization

Hibiki Fukushima, Shinji Ito

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

On the Necessity of Guidance Decay: From Three-Phase Analysis in Gaussian Mixture Models to Dynamic Optimization

Yiyu Qiu, Ruofeng Yang, Tong Yu, Shuai Li

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Pairwise AUC Optimization Needs Corrective Power: A Unified View

Jia Chen, Zhiyong Yang, Shilong Bao, Qianqian Xu and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Sharper Regret Bounds for Shampoo

Dahngoon Kim, Min-hwan Oh

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

A Unified Semismooth Newton Approach to Multitask and Multivariate Square-Root Lasso Problems

Dongwon Kim, Taehyoung Kim, Sungdong Lee, Joong-Ho (Johann) Won

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Certifiably Optimal Robust Angular Synchronization

Daniel Barath, Keisuke Tateno, Marc Pollefeys, Federico Tombari

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Hessian-Dependent Sample Complexity in Zeroth-Order Stochastic Optimization: Suboptimality of Convex-Support Sampling and Optimal Sample Complexity

Mengtian Hong, Jason Lee, Qian Yu

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

ZO-F2: Low-variance Fisher preconditioner via bilinear estimation for zeroth-order optimization

Hiroshi Sawada, Yuya Hikima, Kenta Niwa

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score
NeurIPS 2026YandexOptimization

Understanding Gradient Orthogonalization for Deep Learning via Non-Euclidean Trust-Region Optimization

Dmitry Kovalev

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Homological Barriers to Stable Local Nash Dynamics in Quadratic Zero-Sum Games

Ashkan Soleymani, Gabriele Farina, Patrick Jaillet, Georgios Piliouras

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Runtime Analysis of Cartesian Genetic Programming on MAX: A Proven Exponential Speedup

Duc-Cuong Dang, Roman Kalkreuth, Andre Opris

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 1/5
45%Niche pick
?Niche pickVote to see the score

High-probability Convergence of Gradient Methods under Markovian Stochasticity

Polina Podzorova, Nikolay Spitsyn, Savelii Chezhegov, Aleksandr Beznosikov

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Sparse Updates Generalize Better Than Optimization: Stability Analysis for Randomized Subspace Descent

Yifei Liang, Yan Sun, Yifei Cheng, Haobo Fu and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Concise Reasoning Through the Lens of Lagrangian Optimization

Chengqian Gao, Haonan Li, Taylor Killian, Jianshu She and 5 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Continuous p-adic Optimization

Julian Salazar, Dimitri Kanevsky, Matt Harvey, Pascal Getreuer and 1 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Riemannian Lyapunov Framework: Optimization as Closed-Loop Control on Riemannian Manifolds

Yixuan Wang, Omkar Sudhir Patil, Warren Dixon

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Median-of-Means under Structured Heavy-Tailed Noise: High-Probability Bounds for Clipped Stochastic Optimization

Ahmed El Bajdali, Ohad Shamir, Samuel Horváth, Eduard Gorbunov

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

On Computing Diverse Solutions in the Earth Movers Distance

Aritra Banik, Mayank Goswami, Abhishek Sahu

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Accelerated last-iterate convergence of Extragradient via power-law stepsizes

Yue Wu, Weiqiang Zheng, Yang Cai, Haipeng Luo

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Dynamic Optimistic Constrained OCO with Memory via Delay Equivalence

Mohammed ABDULLAH, George Iosifidis, Salah Eddine ELAYOUBI, Tijani Chahed

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Your Hypergradient is Skewed: Antithetic Neumann Estimation for Bilevel Optimization

Jason Bohne, Pawel Polak, Gary Kazantsev, David Rosenberg

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

A Cross-Interaction Neural Architecture for Submodular Functions

SOUTRIK SARANGI, Aditya Singh, Vansh Maheshwari, Abir De

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Submodular Clustering beyond $1-1/e$

Kiarash Banihashem, Mohammadhossein Bateni, Hossein Esfandiari, Samira Goudarzi and 1 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Matrix Recovery Via Symmetric Rank-one Measurements With Random Unit-modulus Vectors

Tongyu Zhou, Wei Zhang

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Do We Need Asynchronous SGD? On the Near-Optimality of Synchronous Methods

Grigory Begunov, Alexander Tyurin

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 1/5
57%Worth a look
?Worth a lookVote to see the score

A Stability Analysis of AdamW: Unstable Equilibria and Non-Convergence

Baiyu Su, Lizhang Chen, Qiang Liu

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 1/5
76%Highly rated
?Highly ratedVote to see the score

Sharp Capacity Scaling of Spectral Optimizers in Learning Associative Memory

Spectral optimizer Muon exceeds SGD associative memory capacity, matching Newton's method with first-order updates and larger critical batch sizes.

Juno Kim, Eshaan Nichani, Denny Wu, Alberto Bietti and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

74%Highly rated
?Highly ratedVote to see the score

Post-ADC Inference: Valid Inference After Active Data Collection

Post-ADC inference provides valid p-values and confidence intervals for data-dependent targets after active data collection by correcting adaptive sampling and selection biases without assuming the black-box function form.

Shuichi Nishino, Tomohiro Shiraishi, Teruyuki Katsuoka, Ichiro Takeuchi

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

76%Highly rated
?Highly ratedVote to see the score

Time-Sensitive Anytime-Valid Testing

A time-sensitive testing-by-betting framework favors early rejection via time-weighted rewards, yielding Bellman-optimal e-processes and an exponential-decay-optimal criterion recovering classical growth-rate optimality at large scales.

Eugenio Clerico, Tobias Wegel, Iskander Azangulov, Patrick Rebeschini

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read
?Must readVote to see the score

Optimal Hidden-Target Learning for Online Inventory Optimization on General Convex Sets

Hidden-target projection minimizes regret for online inventory optimization on general convex sets, improving dependence on common-demand probability to inverse square root with matching lower bound, plus polylogarithmic and adaptive dynamic guarantees.

Anthony Pineci, Yunzong Xu

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

70%Highly rated
?Highly ratedVote to see the score

Information-Geometric Forward Policy Training in GFlowNets

GFlowNet forward-policy training uses trajectory Fisher-Rao geometry to derive structure-aware natural gradients and decomposable second-moment updates.

Yordan Raykov, Rodrigo Veiga

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
5/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

Sinkhorn Based Associative Memory Retrieval Using Spherical Hellinger Kantorovich Dynamics

A Sinkhorn-based dense associative memory for point-cloud measures uses spherical Hellinger-Kantorovich dynamics to retrieve patterns with exponential capacity and robust convergence.

Aratrika Mustafi, Soumya Mukherjee

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
6/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

72%Highly rated
?Highly ratedVote to see the score

Move on Muon : A Hamiltonian probability gradient flow perspective of Muon optimizer

Regularized Muon induces a Hamiltonian probability gradient flow with mirror-descent structure, yielding exponential convergence under gradient dominance and mean-field propagation of chaos.

Aratrika Mustafi, Soumya Mukherjee, Bharath Sriperumbudur

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Curvature Beyond Positivity: Greedy Guarantees for Arbitrary Submodular Functions

Curvature is extended to arbitrary submodular functions, yielding greedy multiplicative approximation guarantees that apply even to negative-valued objectives.

Yixin Chen, Alan Kuhnle

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

72%Highly rated
?Highly ratedVote to see the score

Direct Acceleration of Stochastic Root-Finding Without Variance Reduction and Regularization

A dual-anchor mechanism accelerates stochastic root-finding to O(ε⁻³) without variance reduction or regularization, reaching near-optimal O(ε⁻²) for strongly monotone cases.

TaeHo Yoon, Nicolas Loizou

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

74%Highly rated
?Highly ratedVote to see the score

Sobolev Regularized MMD Gradient Flow

Sobolev-regularized MMD gradient flow penalizes witness function gradients to ensure global convergence without isoperimetric assumptions, applying to both sampling and generative modeling.

Chenyang Tian, Bharath Sriperumbudur, Arthur Gretton, Zonghao Chen

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

72%Highly rated
?Highly ratedVote to see the score

Multi-Variable Conformal Prediction: Optimizing Prediction Sets without Data Splitting

Multi-variable conformal prediction extends calibration to vector-valued scores with multiple variables, removing data splitting while preserving coverage and yielding smaller, more stable prediction sets.

Laura Lützow, Simone Garatti, Marco Campi, Lars Lindemann and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

72%Highly rated
?Highly ratedVote to see the score

Difference of Convex Programming in the Wasserstein Space with Applications to MMD Optimization

A difference-of-convex convex-concave procedure is lifted to Wasserstein space for non-convex measure optimization, yielding almost-stationary iterates and explicit decompositions for MMD and energy distance with faster convergence.

Clément Bonet, Pierre-Cyril Aubin-Frankowski, Youssef Mroueh

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

70%Highly rated
?Highly ratedVote to see the score

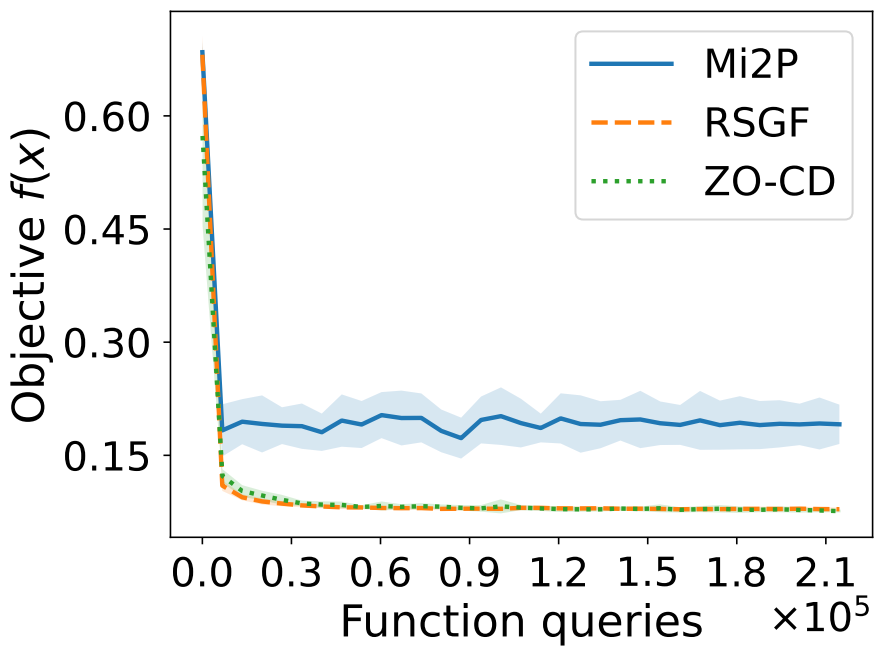
From Cursed to Competitive: Closing the ZO–FO Gap via Input-to-State Stability

Using input-to-state stability, zeroth-order optimization achieves first-order convergence rates without extra dimension dependence when perturbations are small.

Amir Ali Farzin, Philipp Braun, Iman Shames

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
5/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

70%Highly rated
?Highly ratedVote to see the score

Achieving Better Local Regret Bound for Online Non-Convex Bilevel Optimization

An adaptive algorithm achieves optimal O(1+V_T) local regret for online non-convex bilevel optimization with O(T log T) gradient evaluations, and a window-based method attains optimal Ω(T/W²) window-averaged regret via single-loop updates.

Tingkai Jia, Haiguang Wang, Ting Wang, Cheng Chen

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
5/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

Learning-Augmented Approximation for Unrelated-Machines Makespan Scheduling

A learning-augmented algorithm for unrelated-machine makespan scheduling uses heavy-job predictions to achieve (1+ε)-approximation that smoothly degrades to 2-approximation as error grows.

Kaito Baba, Evripidis Bampis, Georgios Mitropoulos

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
6/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

74%Highly rated
?Highly ratedVote to see the score

Understanding the Curse of Unrolling

Non-asymptotic analysis explains the curse of unrolling, early derivative divergence when differentiating through iterative algorithms, and shows that truncating early iterations mitigates it while reducing memory, with warm-starting providing implicit truncation in bilevel optimization.

Sheheryar Mehmood, Florian Knoll, Peter Ochs

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

70%Highly rated
?Highly ratedVote to see the score

Factor Augmented High-Dimensional SGD

FSGD is a streaming SGD method that uses latent factor representations for high-dimensional tasks, achieving scalable optimization with theoretical convergence guarantees including factor estimation error.

Shubo Li, Yuefeng Han, Xiufan Yu

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
4/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

Compute Efficiency and Serial Runtime Tradeoffs for Stochastic Momentum Methods

Heavy ball and ASGD face compute-efficiency versus serial-runtime tradeoffs in linear regression, with heavy ball extending SGD's efficient batch window by up to √κ and ASGD trading small-batch efficiency for runtime on fast-decaying spectra.

Depen Morwani, Alexandru Meterez, Pranav Nair, Sham Kakade

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

70%Highly rated
?Highly ratedVote to see the score

Constrained Stochastic Spectral Preconditioning Converges for Nonconvex Objectives

Proximal preconditioned stochastic gradient methods extend Muon/Scion to nonconvex constrained optimization with heavy-tailed noise convergence and faster variance-reduced variants.

Konstantinos Oikonomidis, Jan Quan, Kimon Antonakopoulos, Antonio Silveti-Falls and 2 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
5/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

72%Highly rated
?Highly ratedVote to see the score

Mirror Descent-Ascent for mean-field min-max problems

Mirror descent-ascent achieves O(N^{-1/2}) and O(N^{-2/3}) convergence to mean-field Nash equilibria via infinite-dimensional dual Bregman analysis.

Razvan-Andrei Lascu, Mateusz Majka, Lukasz Szpruch

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

70%Highly rated
?Highly ratedVote to see the score

Stochastic Optimization with Random Search

Random search for stochastic optimization works under weaker smoothness assumptions and achieves faster convergence via variance-reduced variants using translation invariance to balance noise.

El Mahdi Chayti, Taha EL BAKKALI EL KADI, Omar Saadi, Martin Jaggi

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
4/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

Faster Rates For Federated Variational Inequalities

Refined analysis and a new LIPPAX algorithm improve federated stochastic variational inequality convergence rates and reduce client drift.

Guanghui Wang, Satyen Kale

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Beyond the Half Approximation: Fair and Efficient Online Class Matching

Threshold-based algorithms achieve constant class envy-freeness and exceed 1/2 utilitarian welfare in online class matching, with near-matching upper bounds characterizing fairness costs.

Sander Borst, Max Springer

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read
?Must readVote to see the score

Intrinsic Muon: Spectral Optimization on Riemannian Matrix Manifolds

Intrinsic Muon extends norm-constrained matrix optimization to Riemannian manifolds via canonical intrinsic norms, yielding closed-form updates and convergence rates independent of factor conditioning.

Yibang Li, Bihari L Pandey, Ravi Sah, Andi Han and 3 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

78%Highly rated
?Highly ratedVote to see the score

Functional Gradient Descent with Adaptive Representations

Functional gradient descent with adaptive representations converges to stationary points or global minimizers despite approximation errors and outperforms fixed approximations and neural network baselines.

Daniel Csillag, Rodrigo Schuller, Pedro Dall’Antonia, Leonidas Guibas and 2 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

70%Highly rated
?Highly ratedVote to see the score

Beyond Maximum Likelihood: Variational Inequality Estimation for Generalized Linear Models

A variational-inequality framework estimates generalized linear models via equilibrium conditions, yielding finite-sample bounds, asymptotic normality, and improved stability over maximum likelihood for non-canonical links.

Linglingzhi Zhu, Jonghyeok Lee, Yao Xie

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
5/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

Jacobian Descent for Multi-Objective Optimization

Jacobian descent resolves multi-objective gradient conflicts via projection to improve convergence and enable instance-wise risk minimization.

Pierre Quinton, Valérian Rey

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

70%Highly rated
?Highly ratedVote to see the score

Selling Information While Being an Interested Party

The paper studies an interested seller algorithmically selling information to budget-constrained buyers to maximize revenue and induce desirable actions, proving optimal menu protocols are polynomial-time computable and analyzing single-policy restrictions.

Francesco Bacchiocchi, Matteo Castiglioni, Alberto Marchesi, Giulia Romano and 1 more

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
5/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

72%Highly rated
?Highly ratedVote to see the score

Stochastic Dynamic Barrier Perturbed Gradient Methods for Nonconvex Simple Bilevel Optimization

SDBPG adaptively perturbs dual formulations to stabilize multipliers near lower-level stationary points, yielding first explicit sample-complexity guarantees for stochastic nonconvex simple bilevel optimization.

Mohammad Mahdi Ahmadi, Jincheng Cao, Aryan Mokhtari, Erfan Yazdandoost Hamedani

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

83%Must read
?Must readVote to see the score

Select-then-differentiate: Solving Bilevel Optimization with Manifold Lower-level Solution Sets

Under local PŁ conditions, unique optimistic lower-level selection ensures hyper-gradient differentiability via pseudoinverses, yielding HG-MS with manifold-dependent convergence and strong LLM reweighting results.

Saeed Masiha, Zebang Shen, Negar Kiyavash, Niao He

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read
?Must readVote to see the score

Adaptively Incorporating Directional Hints into Zeroth-Order Optimization

CV-ZOD adaptively integrates directional hints into zeroth-order optimization, achieving rates that interpolate between first- and zeroth-order convergence based on hint quality without prior knowledge.

Alexander Ryabchenko, Jian Qian, Wenlong Mou

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

Approximate Envy-Free Allocations up to any k Goods

For any k>2, (k+1)/(k+2)-EFkX allocations always exist and are computable in polynomial time, yielding 3/4-EF2X for any number of agents and 2/3-EF X for eight agents.

Aris Filos-Ratsikas, Georgios Kalantzis, Fangxiao Wang

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
6/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

72%Highly rated
?Highly ratedVote to see the score
NeurIPS 2026U IowaOptimization

Penalty-Based First-Order Methods for Bilevel Optimization with Minimax and Constrained Lower-Level Problems

Penalty-based first-order methods solve bilevel minimax optimization without lower-level strong convexity, achieving O(ε^-4) deterministic and O(ε^-9) stochastic complexity.

Yiyang Shen, Yutian He, Weiran Wang, Qihang Lin

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

Dynamic k-center clustering with lifetimes

A dynamic k-center model with known lifetimes achieves deterministic (2+ε)-approximation with amortized updates and linear memory, plus a (6+ε)-approximation with worst-case updates and sublinear memory.

Simone Moretti, Paolo Pellizzoni, Andrea Pietracaprina, Geppino Pucci

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

74%Highly rated
?Highly ratedVote to see the score

Polynomial-Time Algorithm for Thiele Voting Rules with Voter Interval Preferences

A polynomial-time algorithm computes optimal Thiele committees for voter-interval preferences via a concavity theorem and Lagrangian relaxation.

Pasin Manurangsi, Krzysztof Sornat

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

70%Highly rated
?Highly ratedVote to see the score

Adaptive Delayed-Update Cyclic Algorithm for Variational Inequalities

ADUCA is a parameter-free cyclic algorithm for Minty variational inequalities that uses delayed operator updates to avoid line searches and achieves near-optimal global oracle complexity.

Yi Wei, Xufeng Cai, Jelena Diakonikolas

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
5/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

83%Must read
?Must readVote to see the score

The Stability of Online Algorithms in Performative Prediction

No-regret online algorithms unconditionally converge to mixed performatively stable equilibria via randomized martingale arguments, avoiding distribution-response assumptions and PPAD hardness.

Gabriele Farina, Juan C Perdomo

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

78%Highly rated
?Highly ratedVote to see the score

Dynamic Regret in Online Convex Optimization with Indicator Switching Costs

A meta-learning framework with randomized lazy FTRL and movement-aware mixing achieves near-optimal dynamic regret with indicator switching costs and adapts to both switch counts and path length without prior knowledge.

Naram Mhaisen, George Iosifidis

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

72%Highly rated
?Highly ratedVote to see the score

Skip the Hessian, Keep the Rates: Globalized Semismooth Newton with Lazy Hessian Updates

Globalized semismooth Newton with lazy Hessian updates achieves global and superlinear convergence for nonsmooth optimization without per-step second-order evaluations, yielding substantial speedups.

Amal Alphonse, Pavel Dvurechenskii, Clemens Sirotenko

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

Phases of Muon: When Muon Eclipses SignSGD

Spectral optimizer analysis reveals three phases where Muon's SignSVD preconditions covariance differently than SignSGD.

Elliot Paquette, Noah Marshall, Lucas Benigni, Guangyuan Wang and 2 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

Group Distributionally Robust Optimization with Flexible Sample Queries

A GDRO algorithm via flexible sample queries and a prediction-with-limited-advice game achieves high-probability error O(√(∑ m/r_j)/t) with consistent sample complexity O(m log m/ε²).

Haomin Bai, Dingzhi Yu, Shuai Li, Haipeng Luo and 1 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
6/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

70%Highly rated
?Highly ratedVote to see the score

Provable Speedups From Dynamic Population Sizes in Evolutionary Algorithms for Multiobjective Optimization

Dynamic population sizes provably accelerate NSGA-II and GSEMO on the CLIMB problem, yielding O(n log n) versus Ω(n^1.5) evaluations and a super-constant speedup.

Andre Opris

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
4/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

Achieving Directional-Stationarity from a Single Random Direction Step

Augmenting base methods with one random direction step achieves almost-sure d-stationarity in nonsmooth nonconvex optimization without affecting convergence rates.

Dan Greenstein, Nadav Hallak

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

78%Highly rated
?Highly ratedVote to see the score
NeurIPS 2026DukeOptimization

Simple KNN-Based Outlier Detection Achieves Robust Clustering

Simple KNN-based outlier removal achieves constant-factor robust k-means reductions with matching or better real-world clustering performance and speed.

Tianle Jiang, Yufa Zhou

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read
?Must readVote to see the score

Edge of Stability Selectively Shapes Learning Across the Data Distribution

Edge of stability selectively redistributes learning across data groups via Hessian-aligned gradients and non-vanishing magnitudes, favoring output outliers over saturated ones.

Shauna Kwag, Anakha Ganesh, Tomaso Poggio, Pierfrancesco Beneventano

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

A Provably Convergent and Practical Algorithm for Gromov–Wasserstein Optimal Transport

A projected-gradient algorithm for Gromov-Wasserstein transport uses verifiable inexact projections to guarantee convergence to stationary points with scalable reliability.

Ling Liang, Lei Yang

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

Curvature-Dependent Lower Bounds for Frank-Wolfe

Frank-Wolfe achieves Ω(T^{-p/(p-1)}) lower bounds on p-uniformly convex sets for p ≥ 3 under exact line search or short steps, matching upper bounds via low-dimensional dynamics.

Jannis Halbey, Christophe Roux, Sebastian Pokutta

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 7 of 20 reviewers recommend it
lenient 1/5
medium 4/10
strict 2/5
76%Highly rated
?Highly ratedVote to see the score

Local linear convergence of gradient methods for overparameterized Gaussian mixtures

Overparameterized Gaussian mixtures have a loss manifold of slow growth where Polyak steps achieve geometric loss reduction, and alternating short gradient steps with long Polyak steps yields local linear convergence to near-optimal solutions.

Jingxing Wang, Vasileios Charisopoulos, Maryam Fazel

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 10 of 20 reviewers recommend it
lenient 2/5
medium 6/10
strict 2/5
70%Highly rated
?Highly ratedVote to see the score

Monotone Inclusion Approach to Weakly Monotone Discrete-Time Finite-Horizon Mean-Field Games

For discrete-time finite-horizon mean-field games with state-independent transitions and weakly monotone rewards, anchored proximal gradient descent computes mean-field equilibria via monotone inclusions over occupation measures at an O(1/√T) rate without regularization or uniqueness.

Ugur Aydin, Tamer Basar, Naci Saldi

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
5/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 5 of 20 reviewers recommend it
lenient 1/5
medium 2/10
strict 2/5
70%Highly rated
?Highly ratedVote to see the score

Epistemic Pairwise Maximin Share

Epistemic pairwise maximin share (EPMMS) relaxes PMMS fairness; 4/5-EPMMS allocations exist for additive valuations, exact EPMMS for bivalued valuations, and existence holds for three additive or two-type agents despite MMS nonexistence.

Michal Feldman, Amos Fiat, Yael Nissan, Tomasz Ponitka

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
5/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 5 of 20 reviewers recommend it
lenient 0/5
medium 3/10
strict 2/5
71%Highly rated
?Highly ratedVote to see the score

Quantum Speedups for Stochastic Optimization with Heavy-Tailed Noise

Quantum estimators for heavy-tailed noise enable QNSGD and QPSGD to find ε-stationary or optimal solutions with poly(√d, ε) oracle queries, beating classical lower bounds in low dimensions.

Bin Luo, Chengchang Liu, Jonathan Allcock, Shengyu Zhang and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
6/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

70%Highly rated
?Highly ratedVote to see the score

Super-Level-Set Regression: Conditional Quantiles via Volume Minimization

Super-level-set regression directly optimizes minimum-volume prediction regions via geometric optimization, bypassing full conditional density estimation to capture complex multimodal conditional structures.

Sacha Braun, Michael Jordan, Francis Bach

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
5/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 5 of 20 reviewers recommend it
lenient 2/5
medium 3/10
strict 0/5
76%Highly rated
?Highly ratedVote to see the score

Distributed Online Convex Optimization with Compressed Communication: Optimal Regret and Applications

Compressed distributed online convex optimization achieves optimal regret via error feedback and online compression, with applications to distributed non-smooth optimization.

Sifan Yang, Danyue Li, Lijun Zhang

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 10 of 20 reviewers recommend it
lenient 2/5
medium 5/10
strict 3/5
74%Highly rated
?Highly ratedVote to see the score

Learning Augmented Exact Exponential Algorithms

Machine-learned predictions augment exact exponential subset-selection algorithms, reducing search space and runtime smoothly with prediction quality under weak independence or unknown-accuracy settings.

Tatiana Belova, Yuriy Dementiev, Danil Sagunov

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 9 of 20 reviewers recommend it
lenient 4/5
medium 3/10
strict 2/5
72%Highly rated
?Highly ratedVote to see the score

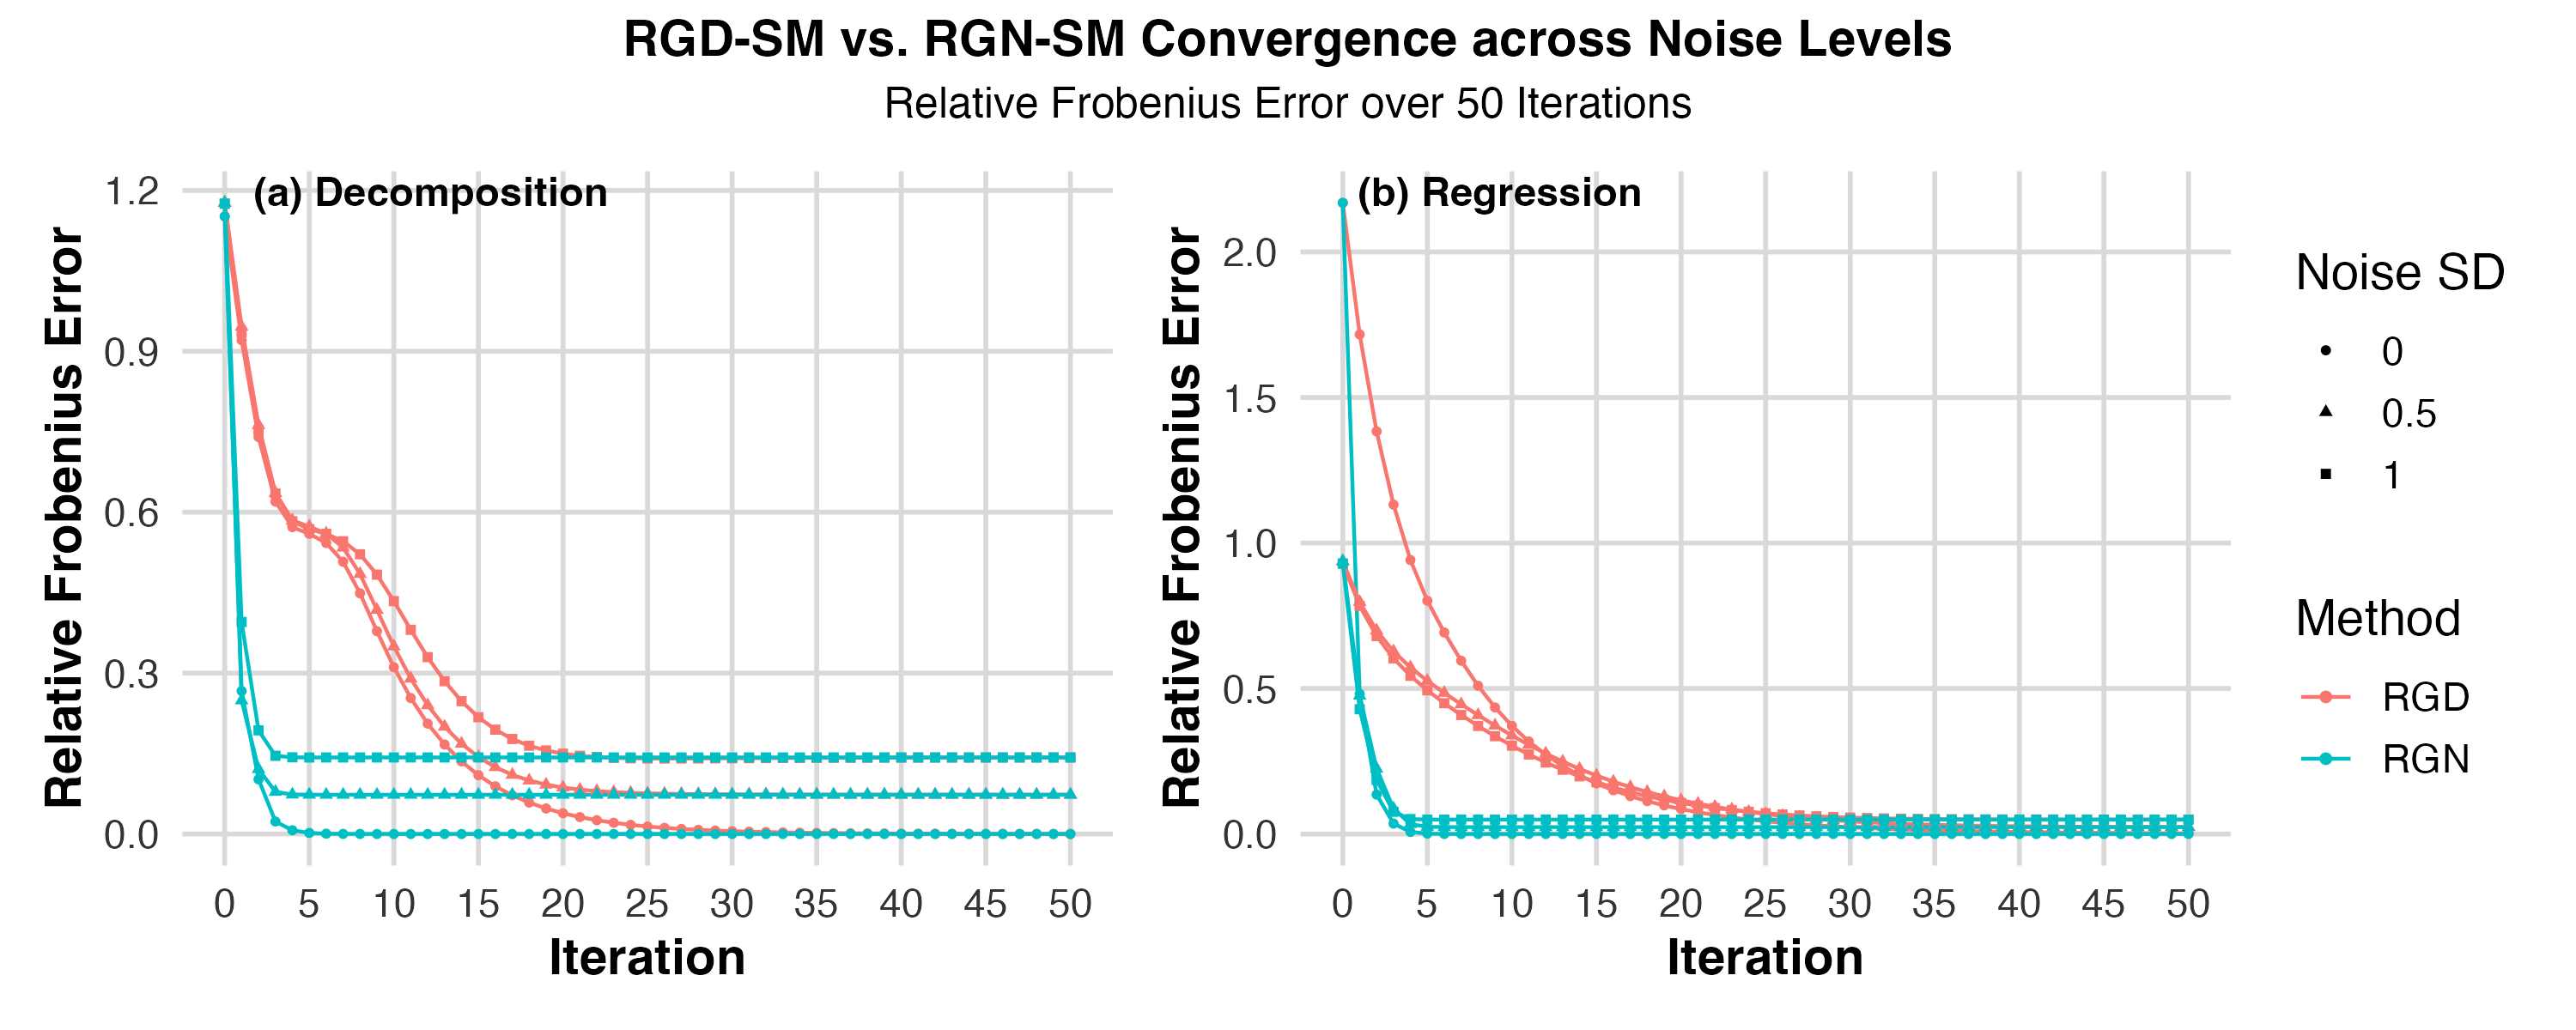
Guaranteed Noisy CP Tensor Recovery via Riemannian Optimization on the Segre Manifold

Riemannian optimization on the Segre manifold recovers noisy low-CP-rank tensors via RGD and RGN, which achieve linear and quadratic-to-linear convergence under mild noise.

Ke Xu, Yuefeng Han

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 8 of 20 reviewers recommend it
lenient 4/5
medium 2/10
strict 2/5
78%Highly rated
?Highly ratedVote to see the score

Black-Box Followers, White-Box Leaders: Partial Zeroth-Order Methods for MPECs

PZOS combines exact leader gradients with zeroth-order follower estimates for MPECs, yielding lower variance and faster convergence than black-box methods on routing and security games.

Miriam Fischer, Dario Paccagnan

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 3/5
medium 7/10
strict 1/5
78%Highly rated
?Highly ratedVote to see the score

Adam under Generalized Smoothness with Second-Moment-Type Stochastic Gradients

Adam converges with high probability on generalized-smooth objectives under only second-moment stochastic gradients, matching a sharp δ^{-1/2} confidence dependence and yielding expectation rates for p<1.

ruinan Jin, Difei Cheng, Ling Chen, Jun Luo and 2 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 2/5
medium 6/10
strict 3/5
67%Highly rated
?Highly ratedVote to see the score

A Unified Approach for Computing Wasserstein Barycenters of Discrete and Continuous Measures

A primal mirror descent algorithm computes exact Wasserstein barycenters for discrete and continuous measures in Fisher-Rao geometry with convergence guarantees.

Peng Xu, Changbo Zhu, Xiaohui Chen

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
2/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

76%Highly rated
?Highly ratedVote to see the score

From Non-Convex to Strongly Convex: Curvature-Adaptive FTPL for Online Optimization

A curvature-adaptive FTPL algorithm tunes its perturbation online to achieve O(sqrt(T)) regret for non-convex Lipschitz losses and O(log T) under linear curvature growth, with matching lower bounds.

Moses Charikar, Chirag Pabbaraju, Ambuj Tewari

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

69%Highly rated
?Highly ratedVote to see the score

Incremental Multiple Oracle

An incremental multiple-oracle framework computes approximate continuous-action game equilibria with constant memory via fixed-cardinality strategy sets without exact global best responses.

Carlos Martin, Tuomas Sandholm

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
3/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 3 of 20 reviewers recommend it
lenient 2/5
medium 1/10
strict 0/5
76%Highly rated
?Highly ratedVote to see the score

Pointwise Lipschitz Continuous Graph Algorithms

This paper proposes a linear programming-based minimum s-t cut algorithm with an optimal Lipschitz constant, yielding the first dynamic algorithm with non-trivial recourse and improved b-matching stability.

Quanquan C Liu, Grigoris Velegkas, Yuichi Yoshida, Felix Zhou

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 10 of 20 reviewers recommend it
lenient 3/5
medium 6/10
strict 1/5
78%Highly rated
?Highly ratedVote to see the score

Online Resource Allocation With General Constraints

Online resource allocation with budget and general constraints achieves near-optimal dynamic regret and bounded violations via weakly adaptive Lagrangian analysis.

Eleonora Fidelia Chiefari, Francesco Emanuele Stradi, Matteo Castiglioni, Alberto Marchesi

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 4/5
medium 6/10
strict 1/5
74%Highly rated
?Highly ratedVote to see the score

Computing Thiele Rules on Interval Elections and their Generalizations

Thiele rules are polynomial-time computable on voter-interval and linearly consistent domains via integral linear programming, and linearly consistent domains strictly contain voter-candidate interval domains, though tree-based extensions are NP-hard.

Dimitris Avramidis, Alexandra Anna Lassota, Ulrike Schmidt-Kraepelin, Adrian Vetta

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

76%Highly rated
?Highly ratedVote to see the score

Fast and Stable Gradient Approximation for Bilinear Forms of Hermitian Matrix Functions

A forward-only gradient approximation for bilinear forms of Hermitian matrix functions reuses the Lanczos pass with minimal overhead, offering provable error bounds and unconditional stability without reorthogonalization.

Navjot Singh, Kipton Barros, Sherry Li

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 10 of 20 reviewers recommend it
lenient 3/5
medium 5/10
strict 2/5
69%Highly rated
?Highly ratedVote to see the score

Optimizing the Envy Cycle Elimination Algorithm

Natural heuristics for the envy-cycle elimination algorithm improve worst-case welfare loss by jointly selecting goods and agents to maximize utility.

Karen Frilya Celine, Warut Suksompong

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
3/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 3 of 20 reviewers recommend it
lenient 1/5
medium 2/10
strict 0/5
71%Highly rated
?Highly ratedVote to see the score

The Query Complexity of Local Search in Rounds on General Graphs

This paper bounds the query complexity of multi-round local search on general graphs, proving deterministic upper and randomized lower bounds that extend grid results to arbitrary connected graphs.

Simina Branzei, Ioannis Panageas, Dimitris Paparas

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
6/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 6 of 20 reviewers recommend it
lenient 3/5
medium 2/10
strict 1/5
74%Highly rated
?Highly ratedVote to see the score

Frank-Wolfe Beyond 1/t Convergence

A local dual sharpness condition enables Frank-Wolfe to converge faster than 1/t on uniformly convex sets, bypassing standard lower bounds.

Sebastian Pokutta

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 9 of 20 reviewers recommend it
lenient 1/5
medium 6/10
strict 2/5
78%Highly rated
?Highly ratedVote to see the score

Free Heavy-Tailed Lunch for Muon: A Theoretical Justification of Empirical Success

Muon achieves optimal heavy-tailed sample complexity with dimension-independent convergence for nuclear-norm stationarity, unlike Euclidean methods.

Florian Hübler, Thomas Pethick, Suvrit Sra

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 3/5
medium 5/10
strict 3/5
78%Highly rated
?Highly ratedVote to see the score

Taking the Road Less Scheduled with Adaptive Polyak Steps

Adaptive Polyak step sizes for Schedule-Free SGD and Adam compute iteration-wise learning rates from losses and gradients, achieving anytime convergence without tuning base rates or horizons.

Dimitris Oikonomou, Matthew Buchholz, Yuen-Man Pun, Robert Gower and 1 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 3/5
medium 6/10
strict 2/5
71%Highly rated
?Highly ratedVote to see the score

Learning-Augmented Online Scheduling with Parsimonious Preemption

Learning-augmented online scheduling achieves O(1)-competitive latency with O(1) preemptions per job on parallel machines, with overhead scaling logarithmically in prediction error.

Mugen Blue, Sungjin Im, Alexander Lindermayr

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 7 of 20 reviewers recommend it
lenient 2/5
medium 4/10
strict 1/5
72%Highly rated
?Highly ratedVote to see the score

Optimizing Computational-Statistical Runtime for Wasserstein Distance Estimation

<|message_model|><|content_text|>A Sample-Sketch-Solve paradigm estimates squared Wasserstein distance between smooth distributions within ε error in near-optimal time. For α-Hölder smooth distributions on (0,1)^d it achieves ε^{-max(2,(d+1+o(1))/(1+α))} runtime, with optimal Θ(ε^{-2}) in 2D for α>1

Peter M Jacobs, Jeff M Phillips

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 8 of 20 reviewers recommend it
lenient 2/5
medium 4/10
strict 2/5
74%Highly rated
?Highly ratedVote to see the score
NeurIPS 2026MITOptimization

The Geometry of Linear Program Compression: An Exact Characterization and Learning Algorithm

Geometric characterization and fast-rate learning algorithm exactly compress linear programs into lower-dimensional equivalents preserving optimality with 1/n generalization.

Yuhan Ye, Omar Bennouna

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 9 of 20 reviewers recommend it
lenient 2/5
medium 6/10
strict 1/5
76%Highly rated
?Highly ratedVote to see the score

The Multi-Block DC Function Class: Theory, Algorithms, and Applications

Multi-block DC programming defines a broader structured nonconvex class with polynomial decompositions and constructive formulations for deep networks, plus convergent batch and stochastic algorithms.

Sayedpouria Fatemi, Hoomaan Maskan, Alp Yurtsever, Suvrit Sra

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

72%Highly rated
?Highly ratedVote to see the score

A Reduction from Delayed to Immediate Feedback for Online Convex Optimization with Improved Guarantees

A reduction framework converts online convex optimization with delayed feedback into immediate feedback, improving delay-dependent regret bounds for both first-order and bandit settings via continuous-time decomposition.

Alexander Ryabchenko, Idan Attias, Dan Roy

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 8 of 20 reviewers recommend it
lenient 2/5
medium 4/10
strict 2/5
74%Highly rated
?Highly ratedVote to see the score

A Single-Sample Polylogarithmic Regret Bound for Nonstationary Online Linear Programming

A re-solving algorithm achieves O(log² n) regret in nonstationary online linear programming using just one sample per distribution via dynamic programming and dual methods.

Haoran Xu, Owen Shen, Peter W Glynn, Yinyu Ye and 1 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 9 of 20 reviewers recommend it
lenient 4/5
medium 3/10
strict 2/5
78%Highly rated
?Highly ratedVote to see the score
NeurIPS 2026KAISTOptimization

Understanding Schedule-Free Methods in Nonconvex Optimization: Rate Guarantees and Escaping Saddles

Schedule-Free gradient and stochastic gradient descent achieve optimal nonconvex convergence rates and escape strict saddles with small perturbations via Lyapunov analysis.

Jiseok Chae, Donghwan Kim

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

78%Highly rated
?Highly ratedVote to see the score

Fully Distributed Tâtonnement for Chores Markets

Multiplicative tâtonnement uses local per-chore excess-demand updates to converge to competitive equilibrium in CCH disutility chores markets. It achieves O(1/ε²) approximate equilibrium rates with better constants and runs substantially faster in practice.

Bhaskar Ray Chaudhury, Christian Kroer, Ruta Mehta, Tianlong Nan

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 1/5
medium 7/10
strict 3/5
71%Highly rated
?Highly ratedVote to see the score
NeurIPS 2026TempleOptimization

Nonconvex Decentralized Stochastic Bilevel Optimization under Heavy-Tailed Noise

A normalized variance-reduced decentralized bilevel algorithm handles heavy-tailed noise without clipping and achieves convergence guarantees for nonconvex problems.

Xinwen Zhang, Yihan Zhang, Heng Liang, Hongchang Gao

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 7 of 20 reviewers recommend it
lenient 3/5
medium 3/10
strict 1/5
76%Highly rated
?Highly ratedVote to see the score

Finite-Sample Performance of Gradient Descent in Logistic Regression with Gaussian Design

Gradient descent for logistic regression with Gaussian design achieves O(√(‖θ*‖₂⁵d/n)) ℓ₂ error with linear convergence, and a sharper Θ(√(‖θ*‖₂d/n)) rate is tight in high dimensions.

Junren Chen, Arya Mazumdar

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 10 of 20 reviewers recommend it
lenient 2/5
medium 5/10
strict 3/5
88%Must read
?Must readVote to see the score

Perfect Parallelization in Mini-Batch SGD with Classical Momentum Acceleration

Classical momentum acceleration improves proportionally with mini-batch size for quadratic interpolation optimization, enabling perfect parallelization of stochastic gradient computations.

Sachin Garg, Michal Derezinski

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 2/5
Show 20 more papers