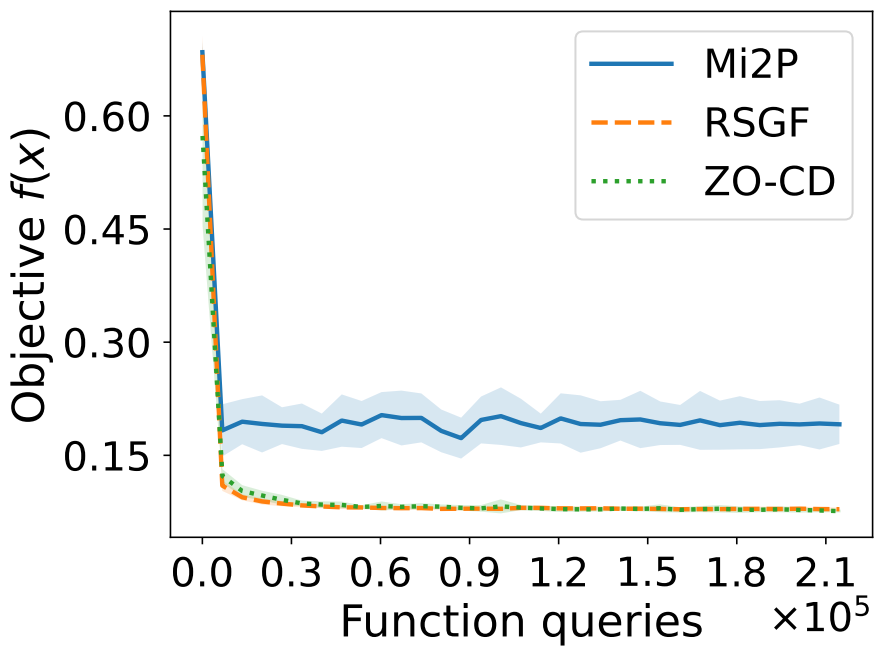
Post-ADC inference provides valid p-values and confidence intervals for data-dependent targets after active data collection by correcting adaptive sampling and selection biases without assuming the black-box function form.
A time-sensitive testing-by-betting framework favors early rejection via time-weighted rewards, yielding Bellman-optimal e-processes and an exponential-decay-optimal criterion recovering classical growth-rate optimality at large scales.
Hidden-target projection minimizes regret for online inventory optimization on general convex sets, improving dependence on common-demand probability to inverse square root with matching lower bound, plus polylogarithmic and adaptive dynamic guarantees.
A Sinkhorn-based dense associative memory for point-cloud measures uses spherical Hellinger-Kantorovich dynamics to retrieve patterns with exponential capacity and robust convergence.
Regularized Muon induces a Hamiltonian probability gradient flow with mirror-descent structure, yielding exponential convergence under gradient dominance and mean-field propagation of chaos.
Curvature is extended to arbitrary submodular functions, yielding greedy multiplicative approximation guarantees that apply even to negative-valued objectives.
A dual-anchor mechanism accelerates stochastic root-finding to O(ε⁻³) without variance reduction or regularization, reaching near-optimal O(ε⁻²) for strongly monotone cases.
Sobolev-regularized MMD gradient flow penalizes witness function gradients to ensure global convergence without isoperimetric assumptions, applying to both sampling and generative modeling.
Multi-variable conformal prediction extends calibration to vector-valued scores with multiple variables, removing data splitting while preserving coverage and yielding smaller, more stable prediction sets.
A difference-of-convex convex-concave procedure is lifted to Wasserstein space for non-convex measure optimization, yielding almost-stationary iterates and explicit decompositions for MMD and energy distance with faster convergence.
Using input-to-state stability, zeroth-order optimization achieves first-order convergence rates without extra dimension dependence when perturbations are small.
An adaptive algorithm achieves optimal O(1+V_T) local regret for online non-convex bilevel optimization with O(T log T) gradient evaluations, and a window-based method attains optimal Ω(T/W²) window-averaged regret via single-loop updates.
A learning-augmented algorithm for unrelated-machine makespan scheduling uses heavy-job predictions to achieve (1+ε)-approximation that smoothly degrades to 2-approximation as error grows.
Non-asymptotic analysis explains the curse of unrolling, early derivative divergence when differentiating through iterative algorithms, and shows that truncating early iterations mitigates it while reducing memory, with warm-starting providing implicit truncation in bilevel optimization.
FSGD is a streaming SGD method that uses latent factor representations for high-dimensional tasks, achieving scalable optimization with theoretical convergence guarantees including factor estimation error.
Heavy ball and ASGD face compute-efficiency versus serial-runtime tradeoffs in linear regression, with heavy ball extending SGD's efficient batch window by up to √κ and ASGD trading small-batch efficiency for runtime on fast-decaying spectra.
Random search for stochastic optimization works under weaker smoothness assumptions and achieves faster convergence via variance-reduced variants using translation invariance to balance noise.
Threshold-based algorithms achieve constant class envy-freeness and exceed 1/2 utilitarian welfare in online class matching, with near-matching upper bounds characterizing fairness costs.
Functional gradient descent with adaptive representations converges to stationary points or global minimizers despite approximation errors and outperforms fixed approximations and neural network baselines.
A variational-inequality framework estimates generalized linear models via equilibrium conditions, yielding finite-sample bounds, asymptotic normality, and improved stability over maximum likelihood for non-canonical links.
The paper studies an interested seller algorithmically selling information to budget-constrained buyers to maximize revenue and induce desirable actions, proving optimal menu protocols are polynomial-time computable and analyzing single-policy restrictions.
SDBPG adaptively perturbs dual formulations to stabilize multipliers near lower-level stationary points, yielding first explicit sample-complexity guarantees for stochastic nonconvex simple bilevel optimization.
Under local PŁ conditions, unique optimistic lower-level selection ensures hyper-gradient differentiability via pseudoinverses, yielding HG-MS with manifold-dependent convergence and strong LLM reweighting results.
CV-ZOD adaptively integrates directional hints into zeroth-order optimization, achieving rates that interpolate between first- and zeroth-order convergence based on hint quality without prior knowledge.
For any k>2, (k+1)/(k+2)-EFkX allocations always exist and are computable in polynomial time, yielding 3/4-EF2X for any number of agents and 2/3-EF X for eight agents.
A dynamic k-center model with known lifetimes achieves deterministic (2+ε)-approximation with amortized updates and linear memory, plus a (6+ε)-approximation with worst-case updates and sublinear memory.
ADUCA is a parameter-free cyclic algorithm for Minty variational inequalities that uses delayed operator updates to avoid line searches and achieves near-optimal global oracle complexity.
A meta-learning framework with randomized lazy FTRL and movement-aware mixing achieves near-optimal dynamic regret with indicator switching costs and adapts to both switch counts and path length without prior knowledge.
Globalized semismooth Newton with lazy Hessian updates achieves global and superlinear convergence for nonsmooth optimization without per-step second-order evaluations, yielding substantial speedups.
A GDRO algorithm via flexible sample queries and a prediction-with-limited-advice game achieves high-probability error O(√(∑ m/r_j)/t) with consistent sample complexity O(m log m/ε²).
Dynamic population sizes provably accelerate NSGA-II and GSEMO on the CLIMB problem, yielding O(n log n) versus Ω(n^1.5) evaluations and a super-constant speedup.
Augmenting base methods with one random direction step achieves almost-sure d-stationarity in nonsmooth nonconvex optimization without affecting convergence rates.
Edge of stability selectively redistributes learning across data groups via Hessian-aligned gradients and non-vanishing magnitudes, favoring output outliers over saturated ones.
A projected-gradient algorithm for Gromov-Wasserstein transport uses verifiable inexact projections to guarantee convergence to stationary points with scalable reliability.
Frank-Wolfe achieves Ω(T^{-p/(p-1)}) lower bounds on p-uniformly convex sets for p ≥ 3 under exact line search or short steps, matching upper bounds via low-dimensional dynamics.
Overparameterized Gaussian mixtures have a loss manifold of slow growth where Polyak steps achieve geometric loss reduction, and alternating short gradient steps with long Polyak steps yields local linear convergence to near-optimal solutions.
For discrete-time finite-horizon mean-field games with state-independent transitions and weakly monotone rewards, anchored proximal gradient descent computes mean-field equilibria via monotone inclusions over occupation measures at an O(1/√T) rate without regularization or uniqueness.
Epistemic pairwise maximin share (EPMMS) relaxes PMMS fairness; 4/5-EPMMS allocations exist for additive valuations, exact EPMMS for bivalued valuations, and existence holds for three additive or two-type agents despite MMS nonexistence.
Quantum estimators for heavy-tailed noise enable QNSGD and QPSGD to find ε-stationary or optimal solutions with poly(√d, ε) oracle queries, beating classical lower bounds in low dimensions.
Super-level-set regression directly optimizes minimum-volume prediction regions via geometric optimization, bypassing full conditional density estimation to capture complex multimodal conditional structures.
Compressed distributed online convex optimization achieves optimal regret via error feedback and online compression, with applications to distributed non-smooth optimization.
Machine-learned predictions augment exact exponential subset-selection algorithms, reducing search space and runtime smoothly with prediction quality under weak independence or unknown-accuracy settings.
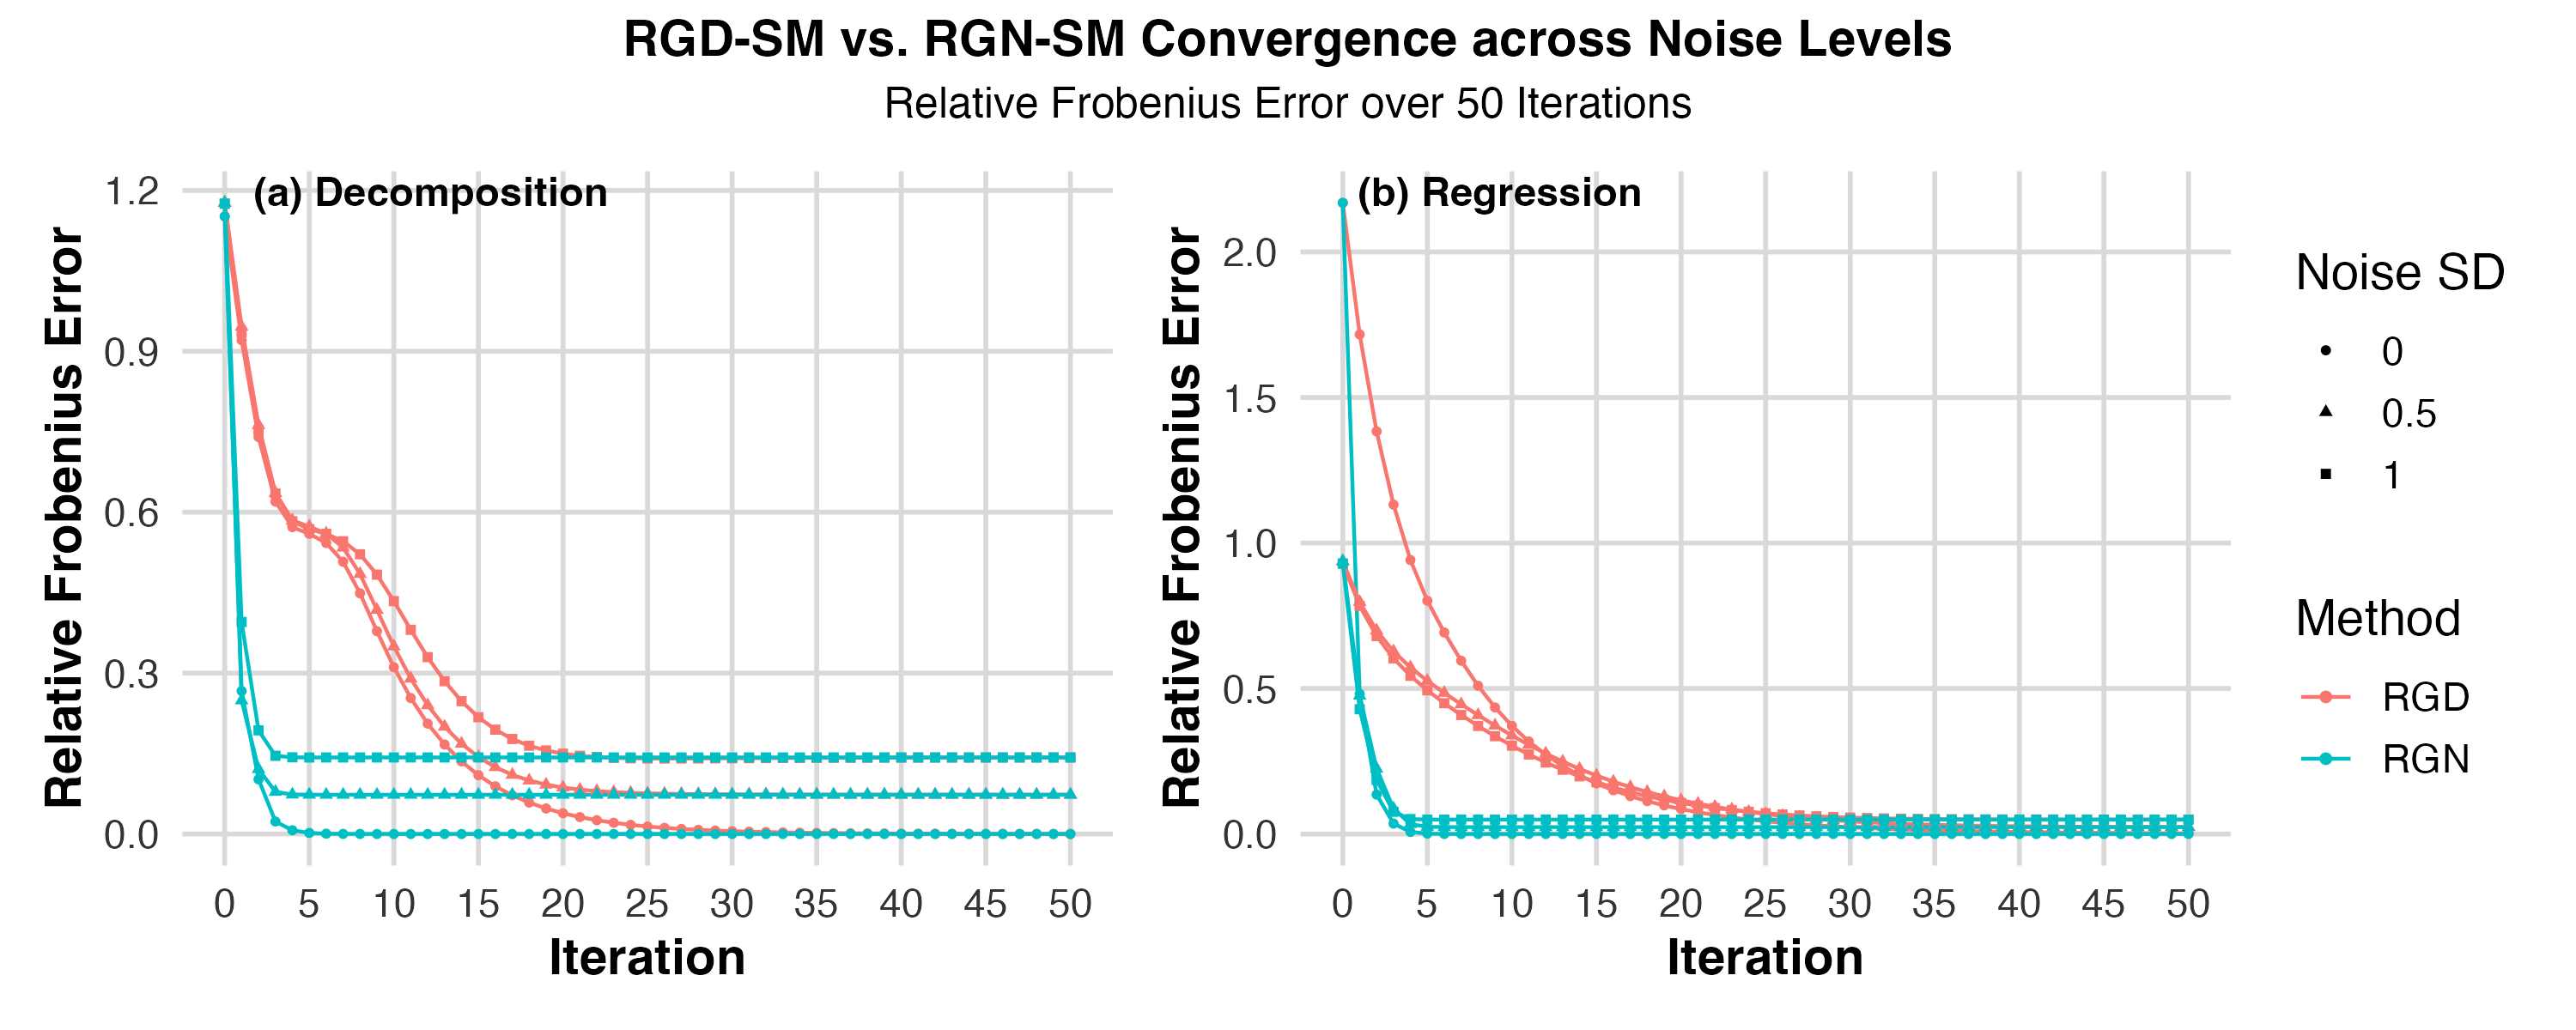
Riemannian optimization on the Segre manifold recovers noisy low-CP-rank tensors via RGD and RGN, which achieve linear and quadratic-to-linear convergence under mild noise.
PZOS combines exact leader gradients with zeroth-order follower estimates for MPECs, yielding lower variance and faster convergence than black-box methods on routing and security games.
Adam converges with high probability on generalized-smooth objectives under only second-moment stochastic gradients, matching a sharp δ^{-1/2} confidence dependence and yielding expectation rates for p<1.
A primal mirror descent algorithm computes exact Wasserstein barycenters for discrete and continuous measures in Fisher-Rao geometry with convergence guarantees.
A curvature-adaptive FTPL algorithm tunes its perturbation online to achieve O(sqrt(T)) regret for non-convex Lipschitz losses and O(log T) under linear curvature growth, with matching lower bounds.
An incremental multiple-oracle framework computes approximate continuous-action game equilibria with constant memory via fixed-cardinality strategy sets without exact global best responses.