Good Papers

Showing Instruction tuning Show all papers

78%Highly rated

Latent-MOPD: Latent Multi-Teacher On-Policy Distillation

Latent-MOPD distills multi-teacher LLM specialists via hidden-state and prediction-level on-policy supervision, outperforming token-only and representation-only baselines across math, code, and logic benchmarks.

Zhengyu Fang, Seoyeon Hong, Jie Yang, Muyang Li and 3 more

Published Oct 1, 2026 · 0 citations · ▲ 63 on Hugging Face

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

78%Highly rated
?Highly ratedVote to see the score

Local Support Learning

Local Support Learning pairs weight adapters with GMM gating to keep updates local, resolving catastrophic forgetting in LLMs up to 7B parameters without prior data.

Assaf Ben-Kish, Akarsh Kumar, James Glass, Raja Giryes

Published Oct 1, 2026 · 0 citations · ▲ 25 on Hugging Face · Code ★ 13

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read
?Must readVote to see the score

LLM2Jev: LLMs Are Already Jev-Style Decision Models -- When and How to Fine-Tune Them

LLM2Jev extracts calibrated Jev-style decisions from LLM token probabilities via training-free inference or tree-factorized fine-tuning, showing strong 4B models already match specialized decision models while fine-tuning mainly helps weaker backbones and specific tasks without degrading generation.

Yinheng Li, Justin Wagle

Published Oct 1, 2026 · 0 citations · ▲ 6 on Hugging Face

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

76%Highly rated
?Highly ratedVote to see the score

FedFit: Federated Fine-Tuning of LLMs via Vector-Bank Parameterization and Quantization

FedFit reduces federated LLM fine-tuning overhead via vector-bank adapter parameterization and quantization, resolving LoRA aggregation conflicts to achieve up to 100x compression with comparable perplexity.

Hang Zou, Chao Zhang, Yuzhi Yang, Yu Tian and 2 more

Published Oct 1, 2026 · 0 citations

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Rethinking Token Reweighting for SFT: Suppress, Reverse, and Extrapolate Learned Features

Existing token-reweighting methods cannot reverse harmful SFT features; SCALE uses frozen SFT deltas with entropy-guided gates to suppress, reverse, or extrapolate them, improving math and code results.

Cunchun Li, Haonan He, Yifan Gao, Minglei Li and 3 more

Published Sep 27, 2026 · 0 citations · ▲ 11 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

78%Highly rated
?Highly ratedVote to see the score

ScopeIF: Improving Scope-Aware Precise Instruction-Following in Large Language Models via Graded Reward Modeling

ScopeIF improves LLM instruction-following via graded reward modeling and scope-aware constraints, enabling small models to match frontier performance.

Bosi Wen, Yilin Niu, Xiaoying Ning, Ying Zhang and 2 more

Published Sep 26, 2026 · 0 citations

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read
?Must readVote to see the score

From Personal to Collective: On the Role of Local and Global Knowledge in LLM Personalization

LoGo augments individual user signals with evolving global and community-level behavioral patterns via adaptive mediation, improving LLM personalization and reducing overfitting.

Zehong Wang, Junlin Wu, Zhaoxuan Tan, Bolian Li and 3 more

Published 2026 · 0 citations

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

69%Highly rated
?Highly ratedVote to see the score

Instant Personalized Large Language Model Adaptation via Hypernetwork

A hypernetwork enables instant personalized large language model adaptation by generating user-specific parameters directly from user data.

Zhaoxuan Tan, Zixuan Zhang, Haoyang Wen, Zheng Li and 7 more

Published 2026 · 1 citation

– ReadersNo votes yet. 1 from authors or colleagues not counted
3/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

72%Highly rated
?Highly ratedVote to see the score

Instruction Tuning for Large Language Models: A Survey

Instruction tuning surveys supervised fine-tuning of LLMs on instruction-output pairs to align next-word prediction with human intent, covering datasets, training, applications, and limitations.

Shengyu Zhang, Linfeng Dong, Xiaoya Li, Sen Zhang and 7 more

Published Nov 17, 2025 · 79 citations

– ReadersNo votes yet
8/21 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

Instruction Tuning for Story Understanding and Generation with Weak Supervision

Weak to Strong Instruction Tuning improves story understanding and generation by training models on instructions of varying clarity, outperforming state-of-the-art baselines.

Yangshu Yuan, Heng Chen, Christian Ng

Published Jan 26, 2025 · 0 citations

– ReadersNo votes yet
6/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Stronger Models are NOT Stronger Teachers for Instruction Tuning

Stronger models are not stronger teachers for instruction tuning due to teacher-student incompatibility; a compatibility-adjusted reward metric predicts effective generators.

Zhangchen Xu, Fengqing Jiang, Luyao Niu, Lin, Bill Yuchen and 1 more

Published Nov 11, 2024 · 0 citations · ▲ 39 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

78%Highly rated
?Highly ratedVote to see the score

Model Swarms: Collaborative Search to Adapt LLM Experts via Swarm Intelligence

Model Swarms uses swarm intelligence to collaboratively adapt LLM experts in weight space, improving over baselines by up to 21% with minimal data and no tuning.

Shangbin Feng, Zifeng Wang, Yike Wang, Sayna Ebrahimi and 8 more

Published Oct 15, 2024 · 2 citations

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

QA-LoRA: Quantization-Aware Low-Rank Adaptation of Large Language Models

QA-LoRA proposes quantization-aware low-rank adaptation that quantizes LLM weights during fine-tuning and merges adapters into quantized models without accuracy loss.

Yuhui Xu, Lingxi Xie, Xiaotao Gu, Xin Chen and 5 more

Published Sep 26, 2023 · 21 citations · ▲ 46 on Hugging Face · Code ★ 148

– ReadersNo votes yet
6/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.
72%Highly rated
?Highly ratedVote to see the score

LoraHub: Efficient Cross-Task Generalization via Dynamic LoRA Composition

LoraHub dynamically combines existing LoRA modules without extra parameters or gradients to generalize to unseen tasks with few examples, trading some accuracy for much lower inference token costs versus in-context learning.

Chengsong Huang, Qian Liu, Lin, Bill Yuchen, Tianyu Pang and 2 more

Published Jul 25, 2023 · 7 citations · ▲ 34 on Hugging Face · Code ★ 668

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

SDS-LoRA: Overcoming Anisotropic Gradient Scaling in Low-Rank Adaptation

JungHun Oh, Sungyong Baik, Kyoung Mu Lee

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

LEAN: Library-Based Adaptation for Asynchronous, Federated Fine-Tuning

Erdong Hu, Yuxin Tang, Zhimin Ding, Christopher Jermaine

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

ToPA: Block-wise Toeplitz Adaptation for Expressive and Efficient Fine-Tuning

Sicong Li, Qianqian Xu, Zhiyong Yang, Zitai Wang and 3 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

67%Highly rated
?Highly ratedVote to see the score

Adaptive Fine-Tuning Scheduler for Multi-Tenant Edge LLM via Convergence-Aware Bandits

Yandi Li, Jianxiong Guo, Yupeng Li, Zhiqing Tang and 2 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
2/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 2 of 20 reviewers recommend it
lenient 2/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

VoluCore: Spanning Teacher Representations with Volumetric Coresets for Data-Efficient LLM Distillation

Wang Xi, Yue Wang

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Mask-Conditioned Gradient Masking for Fine-Tuning Mixture-of-Experts Diffusion Language Models

Yiru Tang, Kun Zhou, Xin Zhao, Jing Sha and 2 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Co-evolution: A "One-to-many" LLM Fine-Tuning Paradigm

Dapeng Jiang, Haichuan Tan, Wenxuan Song, Dianqiao Lei and 2 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

LoRAtorio: An intrinsic approach to LoRA Skill Composition

Niki Foteinopoulou, Ignas Budvytis, Stephan Liwicki

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

ENGINE: Endogenous Variational MultiScale Optimization for Zeroth-Order LLM Fine-Tuning

Zhuoli Ouyang, Changxi Chi, Siyuan Li, Tailin Wu

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

FedLoVA: Value-Only Aggregation for Federated LoRA Fine-Tuning of Large Language Models

Ensieh Khazaei, Baturalp Buyukates, Dimitrios Hatzinakos

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Efficient Collaborative LLM Fine-Tuning over Heterogeneous Mobile Devices via Many Backbones to One Side-Network Tuning

Xingke Yang, Liang Li, Sicong Li, Liwei Guan and 5 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Rethinking LoRA Initialization for Robust Asymmetric Learning Rates

Disen Liao, Yaoliang Yu

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Irreducible Supervision Enables Compositional Generalization in Post-Training

Ellen Ma, Nikhil Anand

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

SAFE-DRIFT: Data Selection for Supervised Fine-tuning with Controllable Off-Target Drifts

Yeo Jin Jung, Yating Liu, Lalchand Pandia, Claire Donnat

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

BQ-LoRA: Binary-Quantized Low-Rank Adapters as Implicit Regularizers for Parameter-Efficient Fine-Tuning

Juyoung Park, Heejun Lee

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Beyond Structural Agnosticism: Stable-Rank-Guided LoRA for Structure-Aware Fine-Tuning

Yuanyang Cao, Xichun Liu, Fuwei Zhang, Meiqin Liu and 1 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Beyond Decoupled PEFT: Geometry-Aware Low-Rank Adaptation via Riemannian Reparameterization

Yuanyang Cao, Xichun Liu, Haitao Jiang, Jianji Wang

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
69%Highly rated
?Highly ratedVote to see the score

Fine-tuning Does Not Reach All: Uneven Safety and Knowledge Dynamics in Language Models

Ziwei Wang, Xinwei Guo, Jiaxin Zhang, Guanhua Chen and 6 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
3/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 3 of 20 reviewers recommend it
lenient 1/5
medium 1/10
strict 1/5
57%Worth a look
?Worth a lookVote to see the score

No Model Required: Text Entropy Rate Filtering Prevents Iterative Fine-Tuning Collapse

Lewis Mitchell

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 1/5
57%Worth a look
?Worth a lookVote to see the score

SAFTAC: Simulation-Augmented Fine-Tuning of Open-Source LLMs for Analog Circuit Design

Junsheng Huang, Yifan Sun, Zhuoer Zhang, Ning Wei and 6 more

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

HALO: Heterogeneous-Aware LoRA Optimization via Rank Allocation and Client-Aware Projection

XiaoHua Feng, Yuyuan Li, Jiayuan Fang, Fengyuan Yu and 5 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Aligned LoRA Updates via Intrinsic Geometry for Federated Low-Rank Adaptation

Yihao Yang, Jian Liang, Wenke Huang, He Li and 2 more

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

DISTMOE: Rehearsal-free Routing in Mixture-of-Experts for Distributed Instruction Tuning

Mainak Singha, Niccolò Biondi, Elisa Ricci, Subhankar Roy

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Geometry-Aware Zeroth-Order Optimization for Fine-Tuning Quantized LLMs

Shaocong Ma, Weidong Cai, Heng Huang

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

FLoRA-Chef: Making A Good LoRA Recipe in Federated Generalization

Wenwen He, Wenke Huang, Yiyan Qi, He Li and 3 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Modulating Merging Strengths via Joint Loss Estimation for LoRA-based Continual Learning

Kun Gu, De Cheng, Zhipeng Xu, Lingfeng He and 2 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

67%Highly rated
?Highly ratedVote to see the score

When Catastrophic Inheritance Meets Forgetting in Continual Adaptation of Foundation Models

Quanyu Zhang, Zhongyi Han, Zhenxue Chen, Xiao-Long Yin and 2 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
2/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 2 of 20 reviewers recommend it
lenient 1/5
medium 1/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Towards Identifying Dominant Low-Rank Subspaces in Zeroth-Order Fine-Tuning

Jinjie Fang, Chengxun Jin, Yi Chang, Bin Gu

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

PriSM: Prior-guided Shared-basis Mixture Personalization for LLMs under Sparse User Histories

Hea Eun Lee, Hyungi Lee, Jangho Kim

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

From Weeks to Hours: Fast and Principled SFT Curation for LLM

Hongyi Henry Jin, Wenhan Yang, Meysam Ghaffari, Carlos Morato and 1 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Mechanistic Insights into LoRA: Layer Sparsity for Adaptive Fine-Tuning via Path Patching

Fei Zuo, Yizhou Huang, Kezhi Wang

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Class-Incremental Learning via LoRA-based Elastic Ensemble of Experts

Ruilong Yu, Fei Ye, Zhiyuan Ren, Qihe Liu and 3 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Finetuning with Sampling: Make SFT Generalize, Not Forget

Aayush Karan, Sitan Chen, Yilun Du

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

When Does Subspace Direction Matter for LoRA? Regime Analysis of the Magnitude Principle in Few-Shot Adaptation

Nischal Subedi, Cencheng Shen, Peng Zhao

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Memory-Efficient Federated Fine-Tuning of LLMs via Block-wise Progressive Training

Qianyue Cao, Zongwei Zhu, Boyu Li, Yi Xiong and 2 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

DRIVE: Fine-tuning via Data Contribution- and Diversity-aware Weighting with Prior Regularization

qing liu, Xinrui Chen, Weiyao Zhu, Yi Du and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Structure vs. Chaos: Asymmetric Entropic Optimization for Enforcing Instruction Hierarchy

Tianxiao Huang, Xinwei Liu, Zitong Shi, Yuxin Wu and 4 more

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Strong Post-Training from Permissive, Reasoning-Dominant, Web-Scale Pretraining

Harsh Raj, Ali Elganzory, Marianna Nezhurina, Victor May and 4 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Align Before Aggregation: Basis-Consistent Federated LoRA under Heterogeneous Ranks

Pengpeng Qiao, Yang Cao, Lingling Zhang, Guo Cheng and 4 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
91%Must read
?Must readVote to see the score

Crowded in B-Space: Calibrating Shared Directions for LoRA Merging

LoRA merging interference mainly stems from shared output-side B directions; calibrating them via Pico improves merged adapter accuracy across benchmarks and can exceed joint-training performance.

Yixuan Tang, Yi Yang

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026 · ▲ 6 on Hugging Face

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 18 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 3/5
80%Must read
?Must readVote to see the score

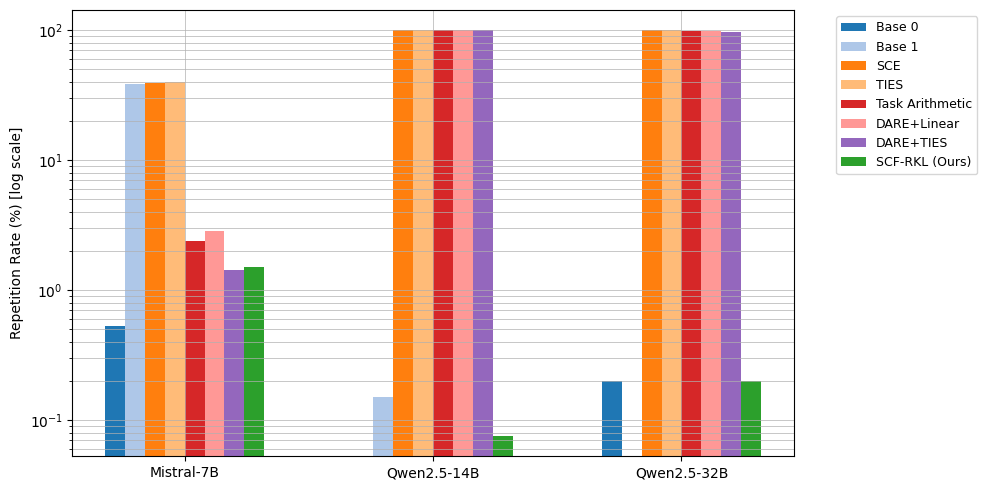
Beyond Parameter Arithmetic: Sparse Complementary Fusion for Distribution-Aware Model Merging

SCF-RKL merges models via sparse, reverse-KL-guided updates that reduce interference and stabilize generation across 24 benchmarks.

Weihong Lin, Lin Sun, Qilong Shi, Aomufei Yuan and 5 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

RotMoLE: Enhancing Mixture of Low-Rank Experts through Rotational Gating Mechanism

RotMoLE adds a rotation gate to MoE-LoRA experts that rotates rather than merely scaling selected experts, improving specialization and performance on multi-task and multilingual benchmarks.

Mengyang Sun, MaoChuan Dou, Tao Feng, Dan Zhang and 4 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
6/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

78%Highly rated
?Highly ratedVote to see the score

Subliminal Learning Is Steering Vector Distillation

Subliminal learning is steering vector distillation where students learn teachers' hidden traits via single steering vectors, requiring adaptive optimizers and failing across models.

Camila Blank, Agam Bhatia, Senthooran Rajamanoharan, Arthur Conmy and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 4/5
medium 6/10
strict 1/5
74%Highly rated
?Highly ratedVote to see the score

Trust the Direction, Search the Step: Zero-and-First-Order Methods for LLM Fine-Tuning

ZFO decouples direction selection from step-size via zeroth-order curvature estimates along first-order directions, improving LLM fine-tuning with minimal overhead.

Cristian McGee, El Houcine Bergou, Aritra Dutta

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

74%Highly rated
?Highly ratedVote to see the score

SMoA: Spectrum Modulation Adapter for Parameter-Efficient Fine-Tuning

SMoA modulates spectra via block-diagonal Hadamard low-rank branches to expand representational coverage under small parameter budgets, outperforming LoRA on multiple tasks.

Yongkang Liu, Xing Li, Mengjie Zhao, Shanru Zhang and 6 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 9 of 20 reviewers recommend it
lenient 3/5
medium 5/10
strict 1/5
91%Must read
?Must readVote to see the score

Distilling What Matters: Confidence-Aware Selective Distillation for Large Language Models

CaRE-KD uses confidence-gated adaptive divergence and batch-level rejection to improve LLM distillation, boosting instruction-following, coding, and math benchmarks over strong baselines.

Ayan Sengupta, Vaibhav Seth, Tanmoy Chakraborty

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 2/5
78%Highly rated
?Highly ratedVote to see the score

On the Construction and Implications of Low-Loss Valleys in LoRA-based Bayesian Inference

LoRA-Curve constructs continuous low-loss Bézier valleys between independent LoRA optima, improving Bayesian model averaging and predictive mutual information without sacrificing accuracy.

Daniel Dold, Emanuel Sommer, Julius Kobialka, Oliver Dürr and 1 more

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

78%Highly rated
?Highly ratedVote to see the score

When the Merge Coefficient Stops Mattering: Proximity Regularized Merging for Continual LoRA Adaptation

Proximity Regularized Merging improves continual LoRA by training mergeable task vectors via proximal penalties, reducing interference and broadening coefficient stability.

Yixuan Liu, Yuhao Sun, Sen Song, Li Jin

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

Scalable Variational Bayesian Fine-Tuning of LLMs via Orthogonalized Low-Rank Adapters

PoLAR-VBLL uses orthogonalized low-rank adapters with Bayesian last-layer inference to fine-tune LLMs with scalable, well-calibrated uncertainty quantification.

Haotian Xiang, Bingcong Li, Qin Lu

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
6/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 6 of 20 reviewers recommend it
lenient 4/5
medium 2/10
strict 0/5
70%Highly rated
?Highly ratedVote to see the score

POME: Post Optimization Model Edit via Muon-Style Projection

POME applies truncated SVD to weight-update differences to equalize dominant directions and prune noise, boosting fine-tuned LLM performance by up to 2.5% with no extra cost.

Yong Liu, di fu, Yang Luo, Zirui Zhu and 3 more

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 1 on Hugging Face · Code ★ 14

– ReadersNo votes yet
5/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Innocuous-Seeming Data, Latent Ideology: Ideological Generalisation in Finetuned LLMs

Finetuning LLMs on narrow, benign datasets causes broad ideological shifts across unrelated domains while preserving capabilities, with finetuning amplifying shifts beyond few-shot prompting to extreme outputs.

Robert Graham, Edward Stevinson, Yariv Barsheshat

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

78%Highly rated
?Highly ratedVote to see the score

One Algorithm, Two Goals: Dual Scoring for Parameter and Data Selection in LLM Fine-Tuning

A shared gradient-interaction scoring rule unifies parameter and data selection for LLM fine-tuning via DualSFT, improving joint efficiency and trade-offs.

Xinrui Chen, Liu Yang, Ou Wu

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 4/5
medium 7/10
strict 0/5
88%Must read
?Must readVote to see the score

Learning Rate Matters: Vanilla LoRA May Suffice for LLM Fine-tuning

Vanilla LoRA matches variant performance within 1-2% when learning rates are tuned, and differing optimal rates stem from Hessian eigenvalue variations.

Yu-Ang Lee, Ching-Yun Ko, Pin-Yu Chen, Mi-Yen Yeh

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 7 on Hugging Face · Code ★ 13

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

83%Must read
?Must readVote to see the score

The Hidden Power of Scaling Factor in LoRA Optimization

LoRA's scaling factor dominates optimization by amplifying task signals without increasing drift, outperforming learning rate adjustments. The optimal alpha follows a sublinear square-root law with rank, revealing insufficient scaling in existing heuristics. Proposed LoRA-alpha restores principled s

Zicheng Zhang, Haoran Li, Jiaxing Wang, Guoqiang Gong and 9 more

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026 · ▲ 12 on Hugging Face

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 13 of 20 reviewers recommend it
lenient 3/5
medium 8/10
strict 2/5
76%Highly rated
?Highly ratedVote to see the score

Estimating and Orthogonalizing Unknown Pre-training Gradients for Continual Fine-tuning of Large Language Models

EoupCT estimates unknown pre-training gradients via learnable pseudo-data prompts and orthogonalizes updates to preserve general knowledge during continual LLM fine-tuning.

Bing Wang, Changchun Li, Xin-Qiang Cai, Lin Y Wu and 3 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 10 of 20 reviewers recommend it
lenient 5/5
medium 5/10
strict 0/5
72%Highly rated
?Highly ratedVote to see the score

Online Data Selection for Instruction Tuning via Gaussian Processes

GAIA casts instruction-tuning data selection as global Gaussian-process utility estimation with adaptive strategy fusion, yielding dynamic-regret guarantees and outperforming batch-constrained baselines.

Jun Wang, Quoc Phong Nguyen, Julien Monteil, Vu Nguyen

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 8 of 20 reviewers recommend it
lenient 4/5
medium 4/10
strict 0/5
74%Highly rated
?Highly ratedVote to see the score

AdaPreLoRA: Adafactor Preconditioned Low-Rank Adaptation

AdaPreLoRA unifies LoRA optimizers via invertible Jacobian surrogates and Adafactor preconditioners, yielding efficient, accurate low-rank updates with minimal memory overhead.

Ziyun Liu, Fengmiao Bian, Jian-Feng CAI

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 2 on Hugging Face

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 9 of 20 reviewers recommend it
lenient 3/5
medium 5/10
strict 1/5
80%Must read
?Must readVote to see the score

ChunkFT: Byte-Streamed Optimization for Memory-Efficient Full Fine-Tuning

ChunkFT enables memory-efficient full-parameter fine-tuning via dynamically activated sub-tensors, cutting 7B model memory to 13.72GB and outperforming baselines.

Yongkang Liu, Zijing Wang, Mengjie Zhao, Ercong Nie and 6 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 0/5
80%Must read
?Must readVote to see the score

SEAD: Competence-Aware On-Policy Distillation via Entropy-Guided Supervision

SEAD uses entropy-guided supervision at token, phase, and prompt levels to cut wasteful gradients and achieves +4.8 average accuracy over vanilla on-policy distillation.

Michael Lee, Zelei Cheng, Yu Wang, Renkun Ni and 3 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 3/5
medium 9/10
strict 0/5
80%Must read
?Must readVote to see the score

LOFT: Low-Rank Orthogonal Fine-Tuning via Task-Aware Support Selection

LOFT separates orthogonal PEFT subspaces from transformations to enable task-aware support selection, improving efficiency-performance trade-offs across language, vision, and reasoning tasks.

Lanxin Zhao, Bamdev Mishra, Pratik Kumar Jawanpuria, Lequan Lin and 3 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 4/5
medium 8/10
strict 0/5
86%Must read
?Must readVote to see the score

Mixture-Trained Merging for Unified Multi-Objective Models

Mixture-Trained Merging trains multi-objective branches on biased data mixtures to enable compatible weight-space merging, outperforming naive merging while preserving distinct capabilities.

SeongHyeon Kim, Chaeyun Jang, Seungyoo Lee, Jiyeon Ham and 3 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 2/5
91%Must read
?Must readVote to see the score

Beyond LoRA vs. Full Fine-Tuning: Gradient-Guided Optimizer Routing for LLM Adaptation

MoLF dynamically routes optimizer updates between full fine-tuning and LoRA to match or beat the stronger static method across tasks, and its efficient variant surpasses AdaLoRA and AdaMix by up to 11.70 points.

Haozhan Tang, Xiuqi Zhu, Xinyin Zhang, Boxun Li and 2 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
18/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 18 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 3/5
83%Must read
?Must readVote to see the score

From Experts to Sub-experts: Fine-grained Parameter-Efficient Fine-Tuning for MoE LLMs

NSFT decomposes MoE experts into channel groups to enable sub-expert-level parameter-efficient fine-tuning that outperforms expert-level methods with fewer trainable parameters.

Zhentao Tan, Chang Liu, Yao Liu, Yue Wu and 1 more

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 13 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 0/5