Good Papers

Showing Efficient inference & serving Show all papers

78%Highly rated
?Highly ratedVote to see the score

Closing the Context Gap: Activation Alignment for Tabular In-Context Learning

Activation alignment trains a linear map to align partial-context student activations with full-context teacher activations, significantly improving tabular in-context learning efficiency and recovering much of the performance gap.

Yoel Zeldes

Published Oct 5, 2026 · ▲ 5 on Hugging Face · Code ★ 1

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 4/5
medium 6/10
strict 1/5
88%Must read
?Must readVote to see the score

Match the Distribution, Not the Compute: Post-Training Multi-Token Prediction Heads

Post-training multi-token prediction heads on ~2.5B chain-of-thought tokens match pretraining speedups with 10^3-10^4x less data, while chain-aware verification and adaptive head selection boost throughput up to 16%.

Prachi Badarayani, Aidan Jay, Chenghui Zhou, Dayquan Julienne and 7 more

Published Oct 1, 2026 · 0 citations

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

91%Must read
?Must readVote to see the score

Learning Functional Subspaces for Neural Network Compression

LSP learns low-rank subspaces end-to-end via joint orthogonal projector optimization to reduce transformer memory and compute while outperforming local criteria at high compression ratios.

Massimo Bini, Anders Christensen, Stephan Alaniz, Judah Goldfeder and 4 more

Published Sep 30, 2026 · 0 citations · ▲ 1 on Hugging Face

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

SlimWise: Decoupling Expert Pruning Across Prefill and Decode for Efficient MoE Serving

SlimWise decouples MoE expert pruning across prefill and decode phases to boost serving throughput without sacrificing accuracy via direct KV cache reuse and selective distillation.

Gunho Park, Kyoungho Jeun, Juntaek Oh, Byeongjun Shin and 2 more

Published Sep 28, 2026 · 0 citations · ▲ 5 on Hugging Face

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read
?Must readVote to see the score

Prefill-Free Cross-Family KV Cache Transfer for Heterogeneous Multi-Agent LLMs

HeteroFold enables prefill-free cross-family KV cache transfer between frozen heterogeneous LLM agents, accelerating 32K context transfer up to 10.7x while matching text-based multi-agent performance.

Vincent-Daniel Yun, Woosang Lim, Haneul Yoo, Sungjoo Yoo and 2 more

Published Sep 26, 2026 · 0 citations · ▲ 95 on Hugging Face · Code ★ 1

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

The Other Half of the Memory Wall: Serving 35B MoEs from SSD with Trained Routing Prediction

Edge0 predicts next-layer MoE routing one token ahead to stream experts from SSD, serving 35B-class MoEs at 20 tok/s within 3 GiB active memory on a 24 GB machine via recovery LoRA adapters.

Yu Lin, Yiming Wang, Runyuan Cai, Liu, Hanze and 1 more

Published Sep 16, 2026 · 0 citations · ▲ 25 on Hugging Face · Code ★ 3,293

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

70%Highly rated
?Highly ratedVote to see the score

TETRIS: Optimal Draft Token Selection for Batch Speculative Decoding

TETRIS selects optimal draft tokens for batch speculative decoding, improving inference speed and efficiency across varied batch sizes.

Zhaoxuan Wu, Zijian Zhou, Arun Kumar Verma, Alok Prakash and 2 more

Published 2025 · 0 citations

– ReadersNo votes yet
4/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Efficient Memory Management for Large Language Model Serving with PagedAttention

PagedAttention applies OS virtual memory and paging to LLM key-value caches, reducing waste and duplication to boost vLLM throughput 2-4x over existing systems.

Woosuk Kwon, Zhuohan Li, Siyuan Zhuang, Ying Sheng and 5 more

Published Sep 12, 2023 · 50 citations · ▲ 76 on Hugging Face · Code ★ 86,094

– ReadersNo votes yet
16/21 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

DyRA: Dynamic Residual Approximation for Efficient Matrix Multiplication in DNNs

Daewon Chae, Hyunwon Chung, Changwoo Lee, Hun-Seok Kim

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Map-Guided Caching: A Global Perspective for Efficient Diffusion Transformer

Jiaqi Ji, Ran Yang, Bo Wei, Hui Li and 1 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
67%Highly rated
?Highly ratedVote to see the score

The $1/\mathcal{W}$ Law: Context Length is the Dominant Energy Lever in LLM Inference Fleets

Huamin Chen, Xunzhuo Liu, Yuhan Liu, Junchen Jiang and 3 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
2/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 2 of 20 reviewers recommend it
lenient 2/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Adaptive Entropy-Sparing for Efficient Reasoning

Cong Jiang, Xiaofeng Zhang, Tom Ko, Zheng Zhang

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

TokenRouter: Efficient Serving System for Token-Level LLM Routing

Tianyu Fu, Tengxuan Liu, Ruoxi Wang, Yixin Dong and 3 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

67%Highly rated
?Highly ratedVote to see the score

LLMs Optimizing LLMs: Automated MegaKernel Generation for Inference Acceleration

Weiqiang Xiong, Shaohui Peng, Wenyi Li, Hao Lu and 7 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
2/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 2 of 20 reviewers recommend it
lenient 2/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Accelerating the Inference Era with AI-Driven, Globally Optimized HW/SW Co-Design

Miria Feng, Fangzhao Zhang, Adrian G Lafuente, Mert Pilanci and 1 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Efficient Tree Draft for Long-Context Speculative Decoding

Brian J Chan, Ning-Chi Huang, Kai-Chiang Wu

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

VALOR: Vector-Aware Low-Rank Restructuring of Neural Networks for RISC-V Inference

Zhihao Xu, Xiaoning Du, Bixin Li, Wang Lulu and 2 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Pacing Branch Parallelism in LLM Serving

Swapnil Gandhi, Siva Kumar Sastry Hari, Bill Dally, Christos Kozyrakis

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

SPECS: Faster Test-Time Scaling through Speculative Drafts and Dynamic Switching

Mert Cemri, Nived Rajaraman, Rishabh Tiwari, Xiaoxuan Liu and 5 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

μLM: Rethinking Sub-100M Language Models through Memory-First Design

Zijie Chen, Guiyun Fan, Haiming Jin

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Learning Hierarchical Patch Splitting Policies for Faster Vision Transformers

Aditya Gupta, Jean S Dandurand, Kai Qiu, Rohan Choudhury and 1 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
67%Highly rated
?Highly ratedVote to see the score

FELPS: Fair and Efficient Scheduling for Multi-LoRA Serving System

Yukai Ding, Chuang Hu, Fangcheng Fu, Xinyan Li and 5 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
2/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 2 of 20 reviewers recommend it
lenient 2/5
medium 0/10
strict 0/5
67%Highly rated
?Highly ratedVote to see the score

Keep or Preempt? Termination-Aware Scheduling for LLM Serving with Speculative Decoding

Ziyu Cheng, Songtao Guo, Mingyan Li, Chang Han and 2 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
2/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

PAC Reasoning: Controlling the Performance Loss for Efficient Reasoning

Hao Zeng, Jianguo Huang, Bingyi Jing, Hongxin Wei and 1 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

HALO-VGGT: Heterogeneity-Aware Lightweight Online Compression Allocator for Efficient VGGT

Xueling Wang, Yiwen Wang, Siqi Cai, Chen Zhang and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

IdealCache: Rethinking Cache Scheduling in Diffusion Transformers via Ideal Trajectories

shang xue, Li Zhu, Ping Chen

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
67%Highly rated
?Highly ratedVote to see the score

KVFocus: A Perturbation-Theoretic Token-Risk Score for Selective KV Cache Reuse in RAG

Shizhuo Zhang, Nuowen Kan, Chenglin Li, Rui-Xiao Zhang and 9 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
2/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Beyond FLOPs: Train-Full, Deploy-Partial Multi-Exit Inference via Selective Lightweight IC Ensemble

Bitchan Eom, Eunchan Kim

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

ProjKAN: Model Compression via KAN Projections to Bridge the Hypothesis and Capacity Gaps

Ferhat Arslan, Weihong Guo, Shuo Li

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

CompilerKV: Risk-Adaptive KV Cache Compression via Offline Experience Compilation

Ning Yang, Chengzhi Wang, Yibo Liu, Baoliang Tian and 1 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Attribution-Guided Exit Policy for Reliable Early-Exit Inference

Haseena R P, Muhammed Ashrah, Ajith Abraham

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Taking Low-Rank LLM Compression a Step Further: A Global Perspective with Fused Inference

Xinhao Huang, Yuqiang He, Zeyi Wen

Paris Poster Session 1, Wed, Dec 9, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

The Dormant Spiking Neuron: A State-Driven Mechanism for Efficient Spiking Neural Networks

Ruichen Ma, Yicai Chen, Pujun Zhou, Yue Zuo and 4 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

HybridCache: Enhancing Prefix Caching for Linear–Softmax Language Models

Xin Wang, Hao Yu, Yi Zhang, jianwei zhang and 4 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Fast-dLLM++: Fr\'{e}chet Profile Decoding for Faster Diffusion LLM Inference

Siva Rajesh Kasa, Yasong Dai, Sumit Negi, Hongdong Li

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Beyond Adjacent Layers: Graph-Guided Layer Fusion for Compressing Large Language Models

Usama Muhammad, Summer Y Jung

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

In STeP: Speculative Tensor Parallelism for Concurrent Heterogeneous Inference of LLMs

Viren Luke Radhakrishnan, Dhruva Kashyap, Pranav K Nayak, Chiranjib Bhattacharyya and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
67%Highly rated
?Highly ratedVote to see the score

Learning Cost-Efficient Autoscaling for Latency-Constrained Disaggregated LLM Serving

Fu Luo, Binbin Chen, Qing Luo, Linhui Xu and 2 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
2/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Efficient Decoder Scaling Strategy for Constructive Neural Routing Solvers

Qing Luo, Fu Luo, Ke LI, Zhenkun Wang

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

FlashFFN: Multi-Head Decomposition Enables I/O-Aware Feed-Forward Network

Minshen Zhang, Xiang Hu, Jianguo Li, Wei Wu and 1 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Diffusion Tree Search for Inference Time Adaptation of Material Foundation Models

Daniel Levy, Vineet Jain, Tara Akhound-Sadegh, Oumar Kaba and 1 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Accelerating Long-Context LLM Prefill via Layer-wise Progressive Token Pruning in Local Deployment

Zhongxiang Wei, Zhaohan Wang, Zhixiong Zhang, Jin Zhao and 1 more

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Global Importance Estimation for KV Cache Eviction

Seojin Kim, Noseong Park

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Neural Compression of Long ADMM Trajectory for Multiparametric Quadratic Program

Liang Wu, Bo Yang, Xu Yang, Honghui Zheng and 2 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

67%Highly rated
?Highly ratedVote to see the score

Why Speculative Decoding Works Better Than Predicted on Sparse MoE Models

Ekagra Ranjan, Komal Teru, Bharat Venkitesh, Acyr Locatelli

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
2/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 2 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 1/5
76%Highly rated
?Highly ratedVote to see the score

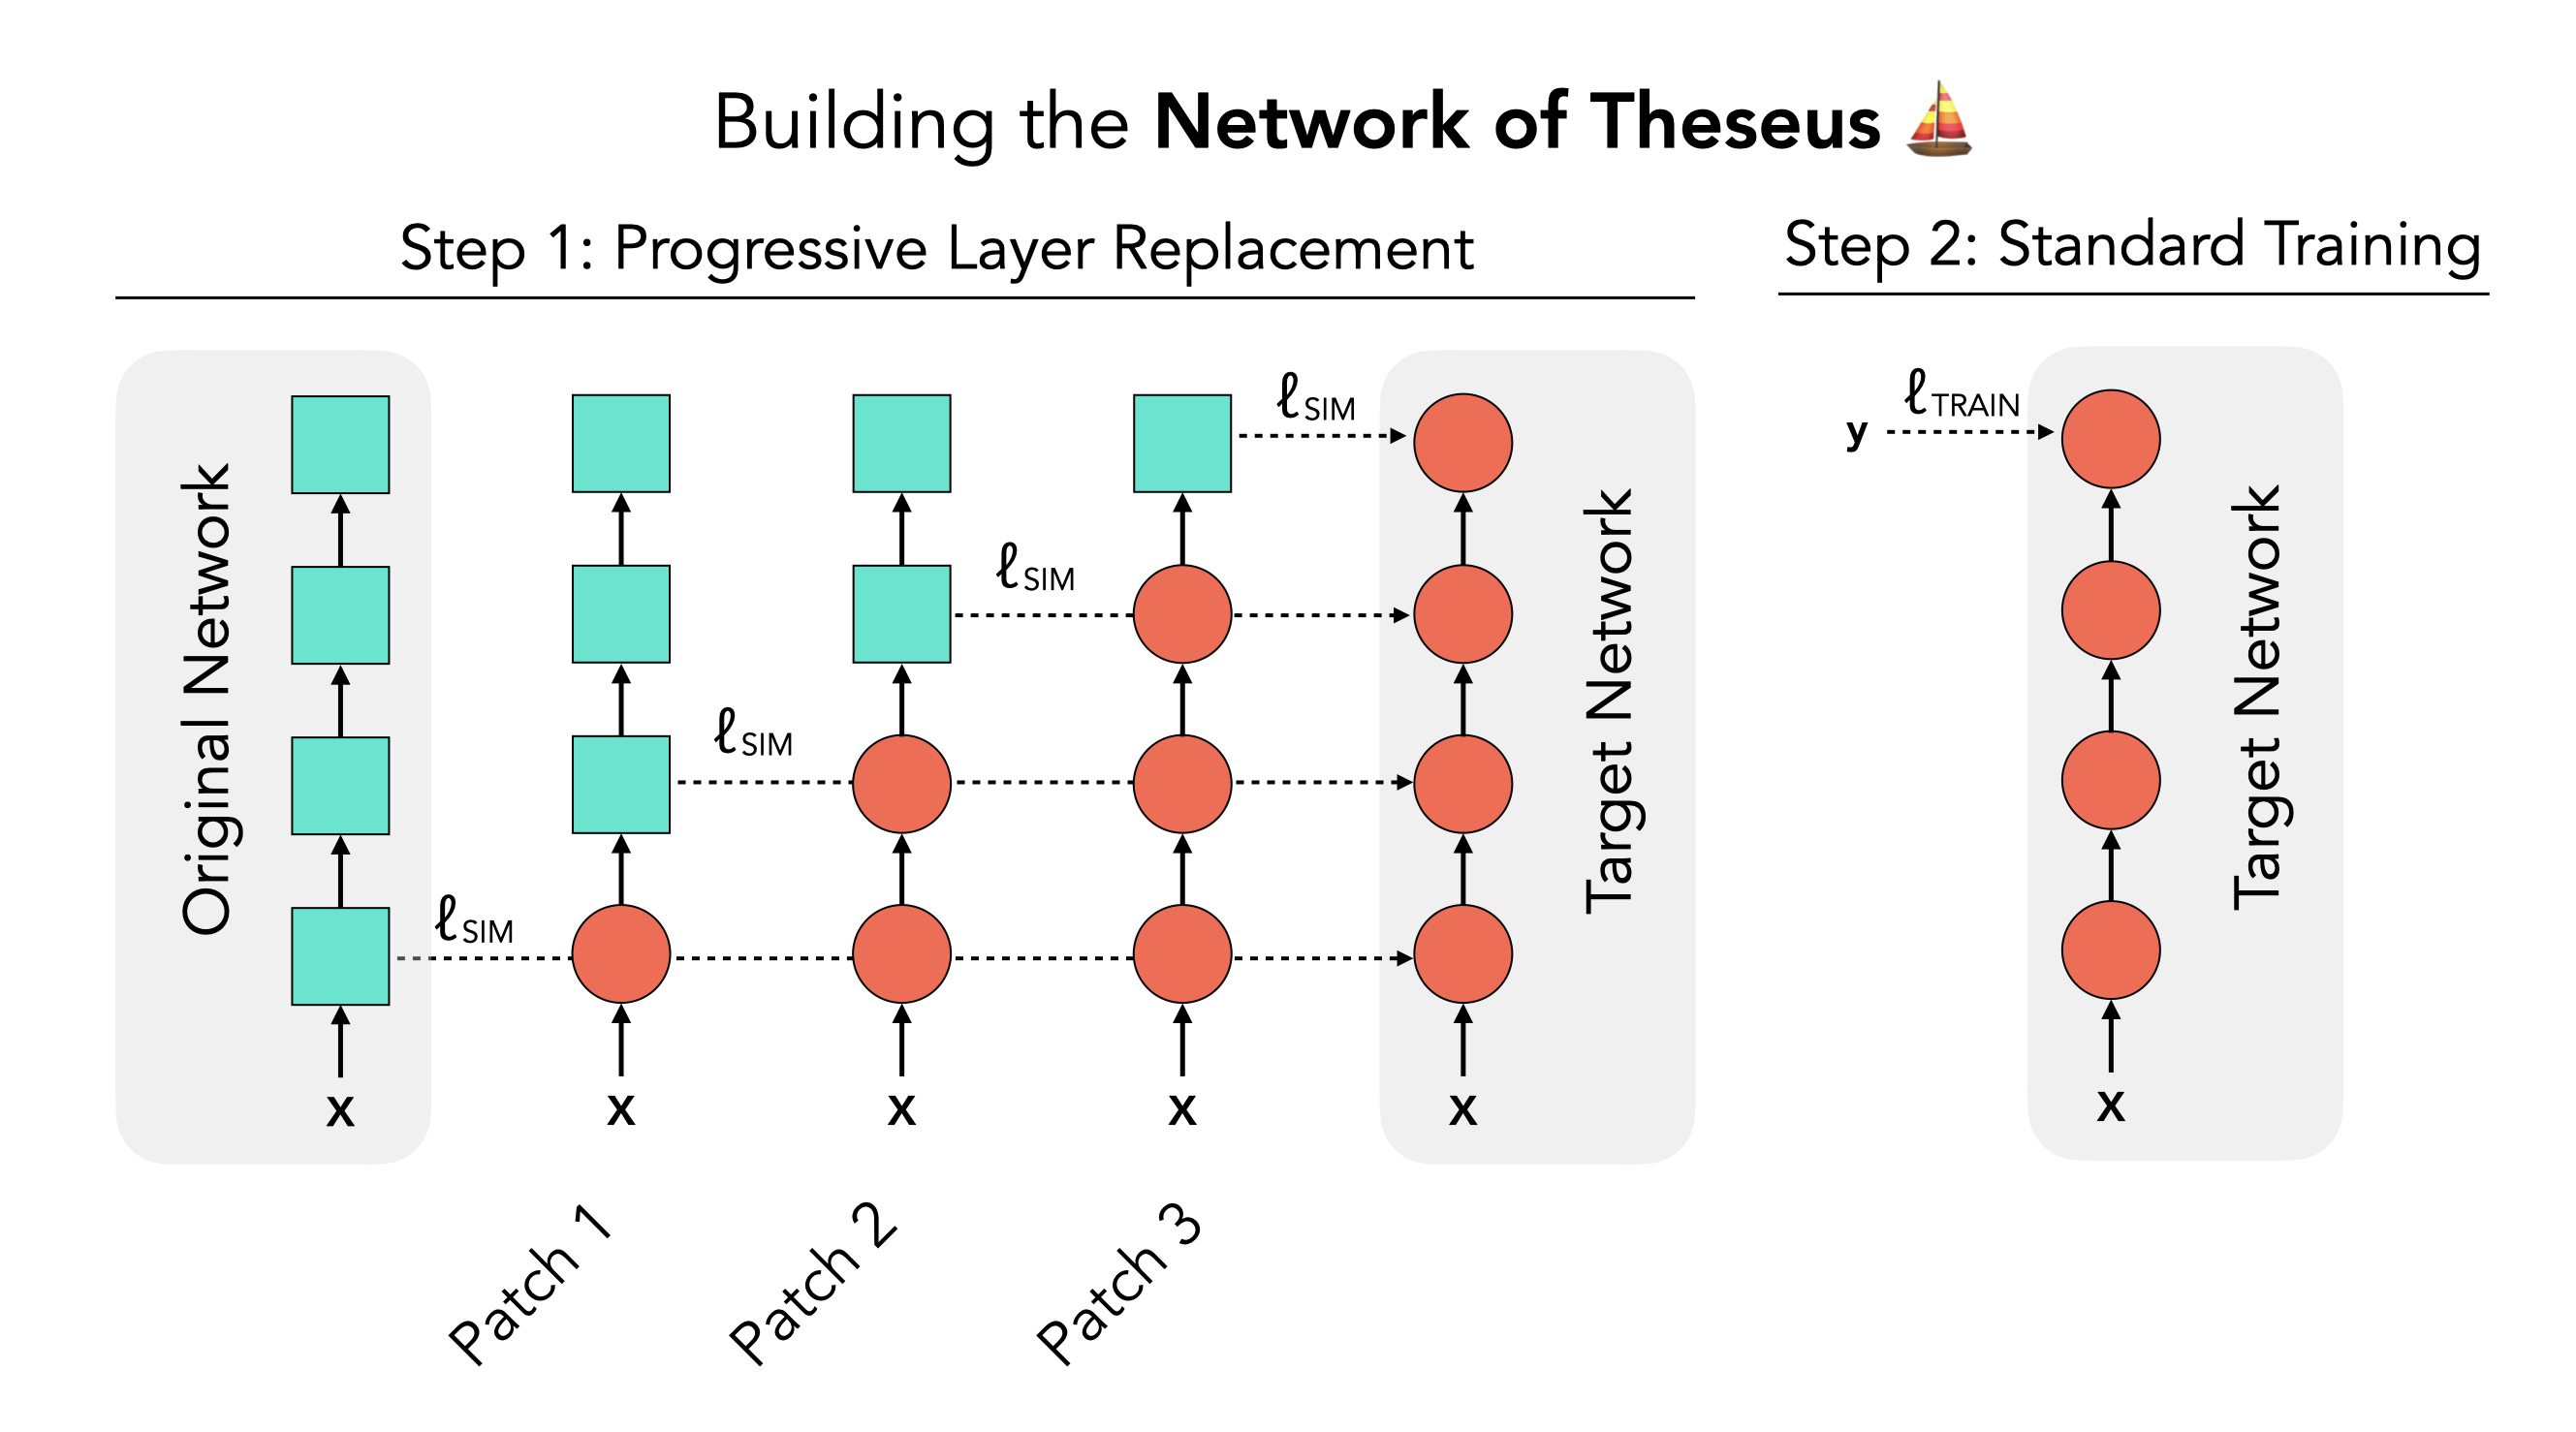
Network of Theseus (Like the ship)

Network of Theseus progressively replaces guide network modules with a different target architecture via representational alignment, preserving performance across vastly different deployed architectures.

Vighnesh Subramaniam, Colin Conwell, Boris Katz, Andrei Barbu and 1 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

Flash-SD-KDE: Accelerating SD-KDE with Tensor Cores

Reordering SD-KDE to expose matrix multiplications enables Tensor Core GPU acceleration, yielding up to 47x faster score-debiased density estimation at million-sample scales.

Elliot Epstein, Rajat Vadiraj Dwaraknath, John Winnicki

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
6/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

83%Must read
?Must readVote to see the score

Beyond Selection: Token Parameterization for Extreme Visual Token Compression

Braco separates token compression into basis truncation and coordinate organization via coupled compressibility and learnability objectives, achieving 95.2% accuracy at up to 144x compression with 84-87% lower prefill FLOPs and up to 36% speedup.

Rui Zhong, YU LI, Zheyu Yan, Cheng Zhuo

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 7 on Hugging Face · Code ★ 2

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

78%Highly rated
?Highly ratedVote to see the score

SimSD: Simple Speculative Decoding in Diffusion Language Models

SimSD proposes a plug-and-play masking strategy that enables token-level speculative decoding in diffusion language models, achieving up to 7.46x faster throughput without training.

Junxia Cui, Haotian Ye, Runchu Tian, Hongcan Guo and 8 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 4/5
medium 6/10
strict 1/5
72%Highly rated
?Highly ratedVote to see the score

SnapMLA: Efficient Long-Context MLA Decoding via Hardware-Aware FP8 Quantized Pipelining

SnapMLA improves long-context MLA decoding throughput up to 1.91x via hardware-aware FP8 quantization and pipeline optimization while preserving benchmark quality.

Yifan Zhang, Zunhai Su, Shuhao Hu, YangRui and 4 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

78%Highly rated
?Highly ratedVote to see the score

NPUsper: Eliminating Redundant Computation for Real-Time Whisper on Mobile NPUs

NPUsper eliminates redundant Whisper computation on mobile NPUs via online hallucination detection and chunked decoding to cut latency, TTFT, and power.

Hojeong Lee, Si H Lee, Sungwon Woo, Chengpo Yan and 2 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 0/5
76%Highly rated
?Highly ratedVote to see the score

UniPrefill: Universal Long-Context Prefill Acceleration via Block-wise Dynamic Sparsification

UniPrefill accelerates long-context prefill via block-wise dynamic sparsification, achieving up to 2.1x TTFT speedup and seamless vLLM integration.

Qihang Fan, Huaibo Huang, zhiyingwu, Bingning Wang and 1 more

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026 · ▲ 20 on Hugging Face · Code ★ 46

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

TERMINATOR: Learning Optimal Exit Points for Early Stopping in Chain-of-Thought Reasoning

Terminator learns optimal early-exit points for chain-of-thought reasoning to cut token lengths by 14%-55% and boost inference speed over 2x with minimal accuracy loss.

Alliot Nagle, Jakhongir Saydaliev, Dhia Garbaya, Michael Gastpar and 2 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 19 on Hugging Face

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

86%Must read
?Must readVote to see the score

Distilling Sequential Computation in Transformer Language Models

A lightweight merge module replaces token spans with surrogate embeddings, cutting Transformer sequence lengths by up to 40% with minimal accuracy loss and no retraining.

Zixuan Lan, Jessica Yang, Yanhong Li, Karen Livescu and 1 more

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 1/5
78%Highly rated
?Highly ratedVote to see the score

EchoKV: Efficient KV Cache Compression via Similarity-Based Reconstruction

EchoKV reduces KV cache memory via similarity-based reconstruction of discarded components, enabling on-demand compression without altering projections and outperforming existing methods.

Shiyu Ji, Yixuan Wang, Yijun Liu, Qingfu Zhu and 1 more

Paris Poster Session 3, Thu, Dec 10, 12:30 PM–2:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 0/5
83%Must read
?Must readVote to see the score

SEED: Self-Speculative Decoding via Implicit Encoder–Decoder

SEED reinterprets decoder-only transformers as implicit encoder-decoders to reuse deep representations for fast self-speculative drafting, achieving up to 2.7x speedup.

Hankun Lin, Patrick Pynadath, Ruqi Zhang

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 13 of 20 reviewers recommend it
lenient 4/5
medium 8/10
strict 1/5
71%Highly rated
?Highly ratedVote to see the score

SageSched: Efficient LLM Scheduling Confronting Demand Uncertainty and Hybridity

SageSched predicts LLM output-length distributions and schedules via compute-and-memory cost models, improving efficiency by over 28.7%.

Zhenghao Gan, Yichen Bao, Yifei Liu, Chen Chen and 2 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 7 of 20 reviewers recommend it
lenient 4/5
medium 3/10
strict 0/5
86%Must read
?Must readVote to see the score

Geometry-Aware Online Scheduling for LLM Serving: From Theoretical Bound to System Practice

Proposing geometry-aware online scheduling via Smallest Volume First improves LLM serving's worst-case competitive ratio from 48 to 3 and reduces latency in vLLM.

Li Kong, Qi Qi, Yinyu Ye, Zijie Zhou

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 4/5
medium 7/10
strict 3/5
92%Must read
?Must readVote to see the score

LowRankArena: A Standardized Evaluation Platform for SVD-Based LLM Compression

LowRankArena standardizes SVD-based LLM compression evaluation and reveals that method rankings and speedups depend heavily on backbone and workload under aligned protocols.

Zishan Shao, Lixun Zhang, Kangning Cui, Wenhao Wu and 9 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 1 on Hugging Face

– ReadersNo votes yet
19/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 19 of 20 reviewers recommend it
lenient 5/5
medium 10/10
strict 4/5
80%Must read
?Must readVote to see the score

PatchKV: Weight Space Compensation of KV Cache

PatchKV improves KV cache compression by computing a context-specific weight patch via ridge regression to align compressed and full-cache activations, preserving long-context accuracy without increasing per-query cost.

Chanryeol Lee, Chanhyuk Lee, Yeonwoo Choi, Donggyun Kim and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 5/5
medium 7/10
strict 0/5
86%Must read
?Must readVote to see the score

Adaptive Mass-Segmented KV Compression for Long-Context Reasoning

AMS replaces global token eviction with adaptive region-aware KV quotas to prevent reasoning block wipe-out, boosting long-context performance without extra attention overhead.

Junzhe Yang, Xiaoyu Shen

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 0/5
76%Highly rated
?Highly ratedVote to see the score

SplitZip: Ultra Fast Lossless KV Compression for Disaggregated LLM Serving

SplitZip is a GPU-friendly lossless KV cache compressor using fixed-length exponent codes and sparse escape streams to achieve 613 GB/s compression and 2182 GB/s decompression, speeding up disaggregated LLM serving by up to 1.32x.

Yipin Guo, Siddharth Joshi

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read
?Must readVote to see the score

SpecBlock: Block-Iterative Speculative Decoding with Dynamic Tree Drafting

SpecBlock drafts block-iterative trees with hidden-state path dependence and adaptive branching, cutting EAGLE-3 drafting cost by about half while boosting speedup 8, 19%.

Weijie Shi, Qiang Xu, fan deng, Yaguang Wu and 8 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 3 on Hugging Face

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 4/5
medium 7/10
strict 1/5
86%Must read
?Must readVote to see the score

Flash-dLLM: IO-Aware KV Caching and Parallel Decoding for Fast, Memory-Efficient Diffusion LLMs

Flash-dLLM accelerates diffusion LLM inference via I/O-aware fused KV caching and self-draft verification, achieving up to 11x speedups.

Quan Nguyen-Tri, Mukul Ranjan, Zhiqiang Shen

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 37 on Hugging Face · Code ★ 18

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

70%Highly rated
?Highly ratedVote to see the score

Justitia: Fair and Efficient Scheduling of Task-parallel LLM Agents with Selective Pampering

Justitia schedules task-parallel LLM agents via memory-centric cost prediction and virtual-time fair queuing to improve efficiency while preserving fairness and worst-case delays.

Mingyan Yang, Guanjie Wang, Manqi Luo, Yifei Liu and 5 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
5/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 5 of 20 reviewers recommend it
lenient 4/5
medium 1/10
strict 0/5
91%Must read
?Must readVote to see the score

AgentKVShift: Efficient KV Cache Reuse for Agentic Memory Systems

AgentKVShift uses probe-guided KV residual correction to reuse agentic memory caches with near-full accuracy at 10-30% recompute, yielding 2-3.5x prefill speedups.

Nilesh Pandey, Jason Kong, Lanxiang Hu, Quanling Zhao and 4 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 3/5
83%Must read
?Must readVote to see the score

TreeGraft: Adaptive Multi-Drafter Grafting for Tree-Based Speculative Decoding

TreeGraft combines small and large drafters with a scheduler to build shared draft trees, boosting speculative decoding by 15.1% over single-drafter methods.

Jiaming Fan, Daming Cao, Canchen Huang, Jiale Fu and 5 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 13 of 20 reviewers recommend it
lenient 4/5
medium 7/10
strict 2/5
78%Highly rated
?Highly ratedVote to see the score

MARS: Enabling Autoregressive Models Multi-Token Generation

MARS fine-tunes autoregressive models to predict multiple tokens per forward pass without architectural changes, matching baseline accuracy while achieving 1.5-1.7x throughput and adjustable real-time speed via confidence thresholds.

Ziqi Jin, Lei Wang, Ziwei Luo, Aixin Sun

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 36 on Hugging Face · Code ★ 30

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 0/5
78%Highly rated
?Highly ratedVote to see the score

Efficient Serving for Dynamic Agent Workflows with Prediction-based KV-Cache Management

PBKV predicts future agent invocations in dynamic LLM workflows to manage KV-cache reuse, achieving up to 1.85x speedup over LRU.

Haoyu Zheng, Fangcheng Fu, Jia Wu, Binhang Yuan and 5 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 5/10
strict 1/5
78%Highly rated
?Highly ratedVote to see the score

KV Packet: Recomputation-Free Context-Independent KV Caching for LLMs

KV Packet treats cached documents as immutable packets with lightweight trainable adapters to eliminate KV cache recomputation, achieving near-zero FLOPs and lower TTFT with comparable F1.

Chuangtao Chen, Grace Li Zhang, Xunzhao Yin, Cheng Zhuo and 2 more

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026 · ▲ 10 on Hugging Face · Code ★ 39

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 0/5
80%Must read
?Must readVote to see the score

TALON: Confidence-Aware Speculative Decoding with Adaptive Token Trees

TALON is a training-free adaptive tree expansion framework for speculative decoding that allocates draft token budgets across layers to construct context-dependent deep-and-narrow or shallow-and-wide trees, achieving up to 5.16x speedup over autoregressive decoding.

Tianyu Liu, Qitan Lv, Yuhao Shen, Jun Zhang and 2 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 4/5
medium 7/10
strict 1/5
80%Must read
?Must readVote to see the score

Fast KVzip: Efficient and Accurate LLM Inference with Gated KV Eviction

Fast KVzip uses lightweight sink-attention gates to evict up to 70% of KV caches with negligible overhead, maintaining near-lossless LLM performance across long-context, code, and math tasks via forward-only, task-agnostic training.

Jang-Hyun Kim, Dongyoon Han, Sangdoo Yun

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 8 on Hugging Face · Code ★ 31

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 1/5
83%Must read
?Must readVote to see the score

Scalable Derivative Gaussian Processes via Exact Gradient Reduction

TERA introduces exact gradient reduction for derivative GPs, reducing inference cost to O(dm²+m⁶) per target with flat scaling in dimension d while preserving the model and improving predictive accuracy.

Hyunseok Seung, Matthias Katzfuss

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 13 of 20 reviewers recommend it
lenient 3/5
medium 8/10
strict 2/5
74%Highly rated
?Highly ratedVote to see the score

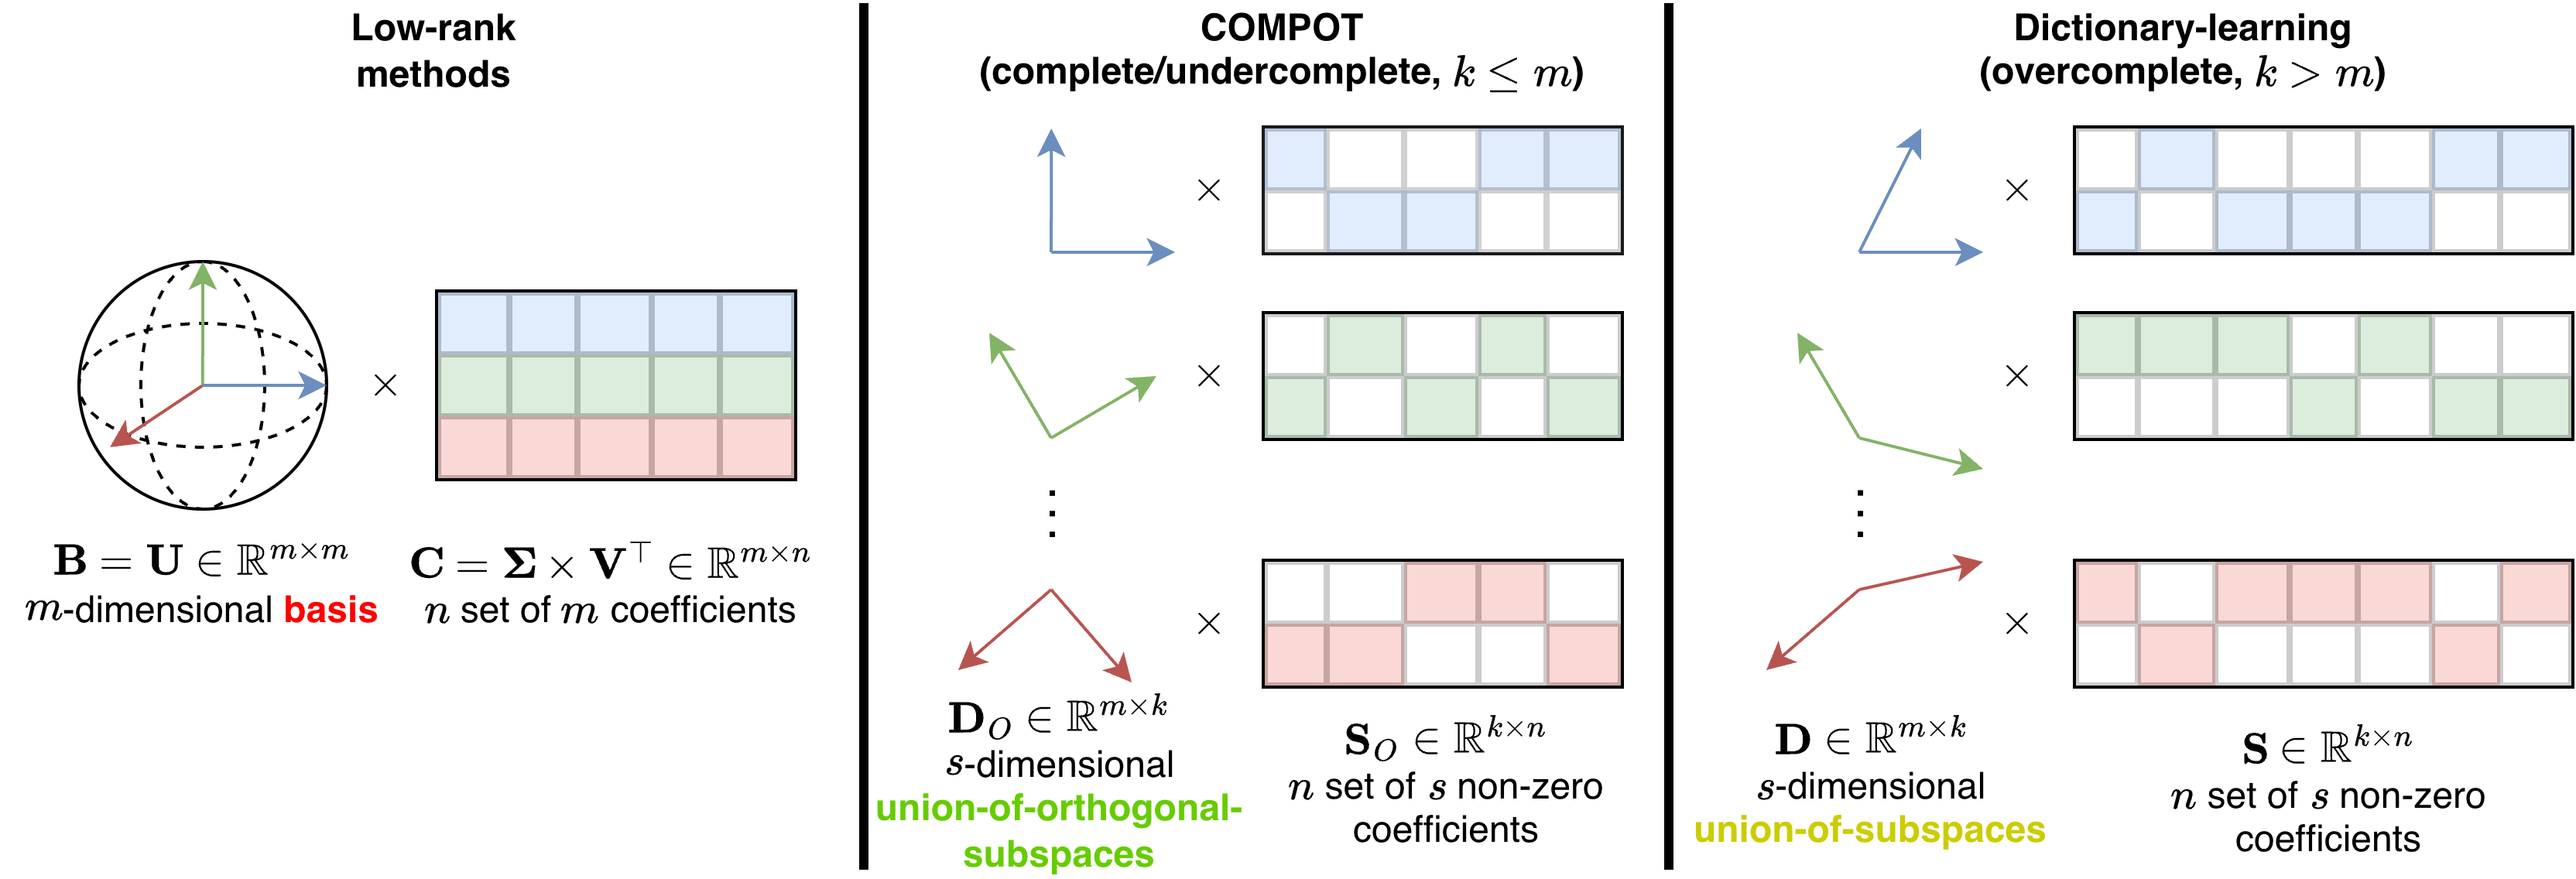
COMPOT: Calibration-Optimized Matrix Procrustes Orthogonalization for Transformers Compression

COMPOT proposes training-free transformer compression via orthogonal dictionaries and closed-form sparse factorization with dynamic layer-wise budget allocation. It achieves superior quality-compression trade-offs versus low-rank and sparse baselines and integrates with quantization.

Denis Makhov, Dmitriy Shopkhoev, Magauiya Zhussip, Ammar Ali and 2 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 9 on Hugging Face

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 9 of 20 reviewers recommend it
lenient 5/5
medium 4/10
strict 0/5
83%Must read
?Must readVote to see the score

Dynamic Delayed Tree Expansion For Improved Multi-Path Speculative Decoding

Systematic evaluation finds traversal verification dominates multi-path speculative decoding, so delayed tree expansion and a dynamic neural selector boost optimal-transport verification to surpass it by 5% throughput.

Rahul K Thomas, Teo Kitanovski, Micah Goldblum, Arka Pal

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 13 of 20 reviewers recommend it
lenient 3/5
medium 8/10
strict 2/5
78%Highly rated
?Highly ratedVote to see the score

Tackling the Data-Parallel Load Balancing Bottleneck in LLM Serving: Practical Online Routing at Scale

BalanceRoute uses online F-score routing to cut DP load imbalance and boost LLM serving throughput at scale.

Tianci Bu, Yuan Lyu, Zixi Chen, Chendong Song and 5 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 0/5
80%Must read
?Must readVote to see the score

Elastic Spectral State Space Models for Train-Once Budgeted Inference

ES-SSM enables train-once deployment across budgets by truncating spectral SSM channels, yielding smooth quality-cost curves and competitive compact models.

Dachuan Song, Junyu Yin, Zechen Hu, Xuan Wang

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 4/5
medium 8/10
strict 0/5
80%Must read
?Must readVote to see the score

BASTION: Budget-Aware Speculative Decoding with Tree-structured Block Diffusion Drafting

BASTION uses budget-aware tree-structured block diffusion drafting and adaptive expansion to achieve up to 6.61x speedup over autoregressive decoding, outperforming baselines by 39%.

Soowon Oh, Nam Cao, Yujin Kim, Hojung Jung and 3 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 2/5
medium 9/10
strict 1/5