Good Papers

Showing papers from Singapore University of Technology and Design Show all papers

72%Highly rated
?Highly ratedVote to see the score

Diptych: Scoped, AI-Interpreted Comparison for Reference Listening in Music Production

Diptych lets musicians define comparison scopes for reference listening, helping surface differences experts partially support while avoiding overreaching AI judgments.

Chongjun Zhong, Abhinaba Roy, Archishman Ghosh, Kejun Zhang and 1 more

Published Sep 30, 2026 · 0 citations · ▲ 20 on Hugging Face

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 8 of 20 reviewers recommend it
lenient 3/5
medium 4/10
strict 1/5
78%Highly rated
?Highly ratedVote to see the score

DEFINE: Exemplar-Guided Accent Control for Zero-Shot TTS

DEFINE decouples speaker identity and accent in zero-shot TTS via separate audio exemplars and a single guidance weight, generalizing accent control beyond training accents with high speaker similarity.

Ambuj Mehrish, Abhinaba Roy, Alex Ivanov, T. Ahmed and 1 more

Published Sep 26, 2026 · 0 citations · ▲ 32 on Hugging Face · Code ★ 2

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 4/5
medium 6/10
strict 1/5
69%Highly rated
?Highly ratedVote to see the score

Text-Based AI Tools for Research Integrity Must Be Audited on Linguistic Fairness Before Deployment

Shuai Shao, Yongkang Wan, Daoyin Dang, Lanyun Zhu and 4 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
3/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 3 of 20 reviewers recommend it
lenient 2/5
medium 1/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Recursive Semantic Divergence for LLM Agent Consistency

Harshavardhan Abichandani, Penny Chong, Atin Ghosh, Daniel Dahlmeier

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

AIR: Rethinking Image-Text Offset Alignment in Multimodal Contrastive Representation Space

Guimeng Liu, Milad Abdollahzadeh, Ngai-Man (Man) Cheung

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
67%Highly rated
?Highly ratedVote to see the score

MLLM-Edit: Benchmarking Image Forgery Detection and Localization under MLLM-based Editing

Zeqin Yu, Ye Tian, Jian Zhang, Jiangqun Ni and 3 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
2/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 2 of 20 reviewers recommend it
lenient 2/5
medium 0/10
strict 0/5
74%Highly rated
?Highly ratedVote to see the score

Diffusion Masked Pretraining for Dynamic Point Cloud

DiMP applies diffusion modeling to masked tube-center inference and inter-frame motion prediction, eliminating positional leakage and deterministic trajectory collapse to improve dynamic point cloud pretraining.

Zhuoyue Zhang, Yiding Sun, Chaowei Fang, Haozhe Cheng and 3 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 9 of 20 reviewers recommend it
lenient 4/5
medium 5/10
strict 0/5
78%Highly rated
?Highly ratedVote to see the score

DC-SAE: Deep Compression Semantic Autoencoder for Faster Diffusion Convergence

DC-SAE combines semantic and pixel-level encoders to achieve 32x compression with high fidelity and faster diffusion convergence. It achieves 29.79 PSNR and 3.37 gFID on ImageNet 512x512, outperforming prior high-compression tokenizers by large margins.

Xu Huang, Ye Huang, Zijun Liao, Yuwei Niu and 5 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 42 on Hugging Face · Code ★ 18

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 4/5
medium 6/10
strict 1/5
89%Must read
?Must readVote to see the score

LangMap: A Human-Verified Benchmark for Hierarchical Open-Vocabulary Goal Navigation

LangMap introduces human-verified hierarchical open-vocabulary navigation benchmarks across scene, room, region, and instance levels with 18K tasks, and PlaNaVid achieves top RGB-only success via planning and memory.

Bo Miao, Weijia Liu, Jun Luo, Lachlan Shinnick and 7 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 1 on Hugging Face · Code ★ 53

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 2/5
76%Highly rated
?Highly ratedVote to see the score

GenCOPE: Syn2Real Generalized Category-Level Object Pose Estimation for Robotic Picking

GenCOPE achieves synthetic-to-real generalized category-level object pose estimation via 2D/3D semantic consistency and cross-modality fusion using only global features, outperforming prior methods on REAL275 and Wild6D.

Jian Liu, Wei Sun, Zhenqi Dai, Hui Yang and 3 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 10 of 20 reviewers recommend it
lenient 5/5
medium 5/10
strict 0/5
83%Must read
?Must readVote to see the score

CodeScaler: Scaling Code LLM Training and Test-Time Inference via Reward Models

CodeScaler uses a reward model to scale code LLM training and inference without test cases, improving benchmarks by up to 14.64 points and cutting latency tenfold.

Xiao Zhu, Xinyu Zhou, Boyu Zhu, Hanxu Hu and 4 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 24 on Hugging Face · Code ★ 50

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 13 of 20 reviewers recommend it
lenient 4/5
medium 7/10
strict 2/5
80%Must read
?Must readVote to see the score

Online Learning on Hidden-Convex Losses via Algorithmic Equivalence: Optimal Regret, Geometric Barrier, and Bandit Feedback

Online gradient descent achieves optimal O(sqrt(T)) regret for hidden-convex losses via sharper discrete equivalence, with a necessary Hessian compatibility condition and O(T^{3/4}) bandit regret.

Anas Barakat, Andreas Kontogiannis, Vasilis Pollatos, Ioannis Panageas and 1 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 1/5
medium 6/10
strict 5/5
78%Highly rated
?Highly ratedVote to see the score

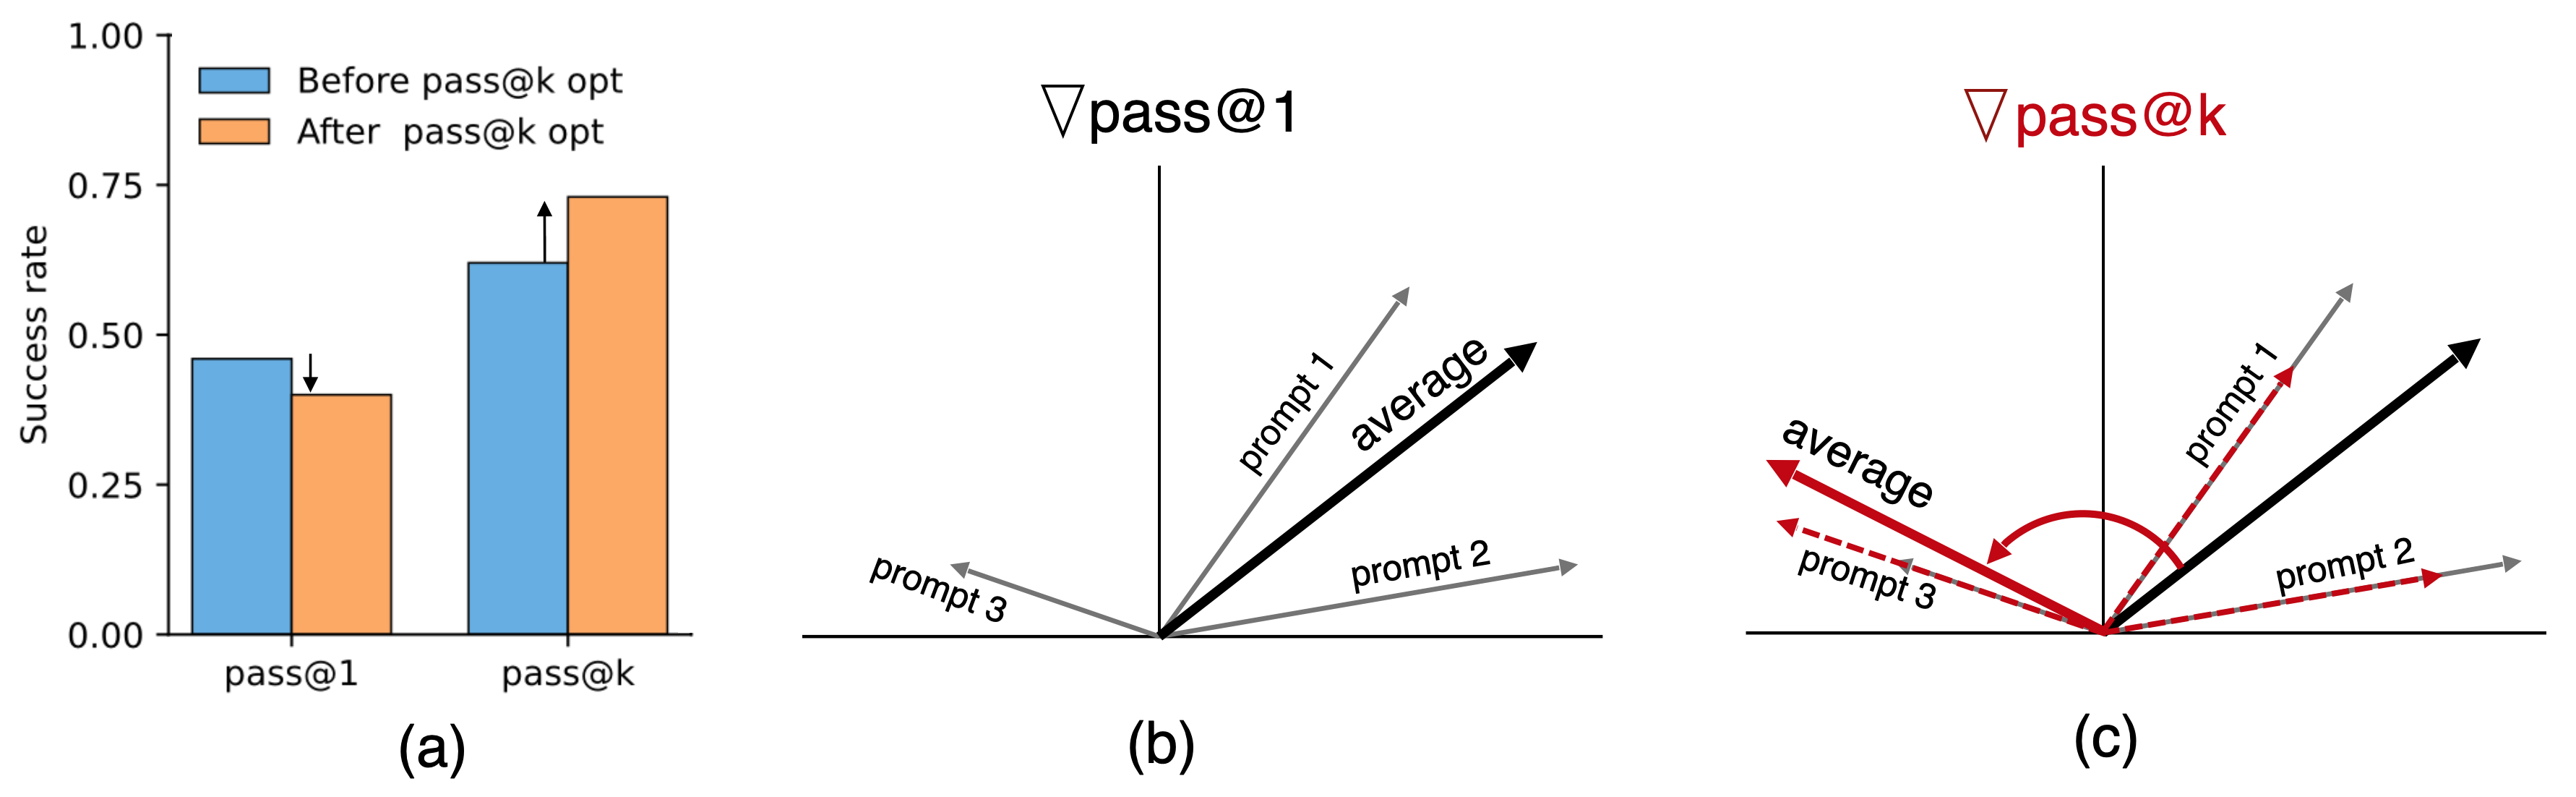
Why Pass@k Optimization Can Degrade Pass@1: Prompt Interference in LLM Post-Training

Pass@k optimization degrades pass@1 via prompt interference, as its gradients conflict by upweighting negatively interfering, low-success prompts.

Anas Barakat, Souradip Chakraborty, Khushbu Pahwa, Amrit Singh Bedi

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 5/10
strict 1/5
91%Must read
?Must readVote to see the score

MiroEval: Benchmarking Multimodal Deep Research Agents in Process and Outcome

MiroEval benchmarks multimodal deep research agents via process and outcome evaluation across 100 real-world tasks, finding process quality predicts outcomes and multimodal tasks reduce scores by 3, 10 points.

Fangda Ye, Yuxin Hu, Pengxiang Zhu, Yibo Li and 18 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 69 on Hugging Face · Code ★ 52

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 3/5
83%Must read
?Must readVote to see the score

Harnessing Agentic Evolution

AEvo formulates agentic evolution as an interactive environment where a meta-agent edits the evolution procedure to steer long-horizon search, achieving up to 26% relative improvement over baselines.

Jiayi Zhang, Yongfeng Gu, Jianhao Ruan, Maojia Song and 8 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 13 of 20 reviewers recommend it
lenient 4/5
medium 7/10
strict 2/5
80%Must read
?Must readVote to see the score

Video-Zero: Self-Evolution Video Understanding

Video-Zero improves video understanding via annotation-free questioner-solver co-evolution centered on temporally localized evidence, boosting 13 benchmark results.

ruixu zhang, Deyi Ji, Lanyun Zhu, Xuanyi Liu and 3 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 4/5
medium 7/10
strict 1/5