Good Papers

Showing papers from MIT CSAIL Show all papers

57%Worth a look
?Worth a lookVote to see the score

PEEK: Context Map as an Orientation Cache for Long-Context LLM Agents

Zhuohan Gu, Qizheng Zhang, Omar Khattab, Samuel Madden

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Hear, Localize, and Reason: Spatially Aware Scene Understanding for Audio-visual LLMs

Sung-Bin Kim, Lee Jung-Mok, Jinwoo Jung, Oh Hyun-Bin and 3 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

FacEDiT: Talking Head Video Editing via Facial Motion Infilling

Sung-Bin Kim, Joohyun Chang, David Harwath, Tae-Hyun Oh

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
76%Highly rated
?Highly ratedVote to see the score

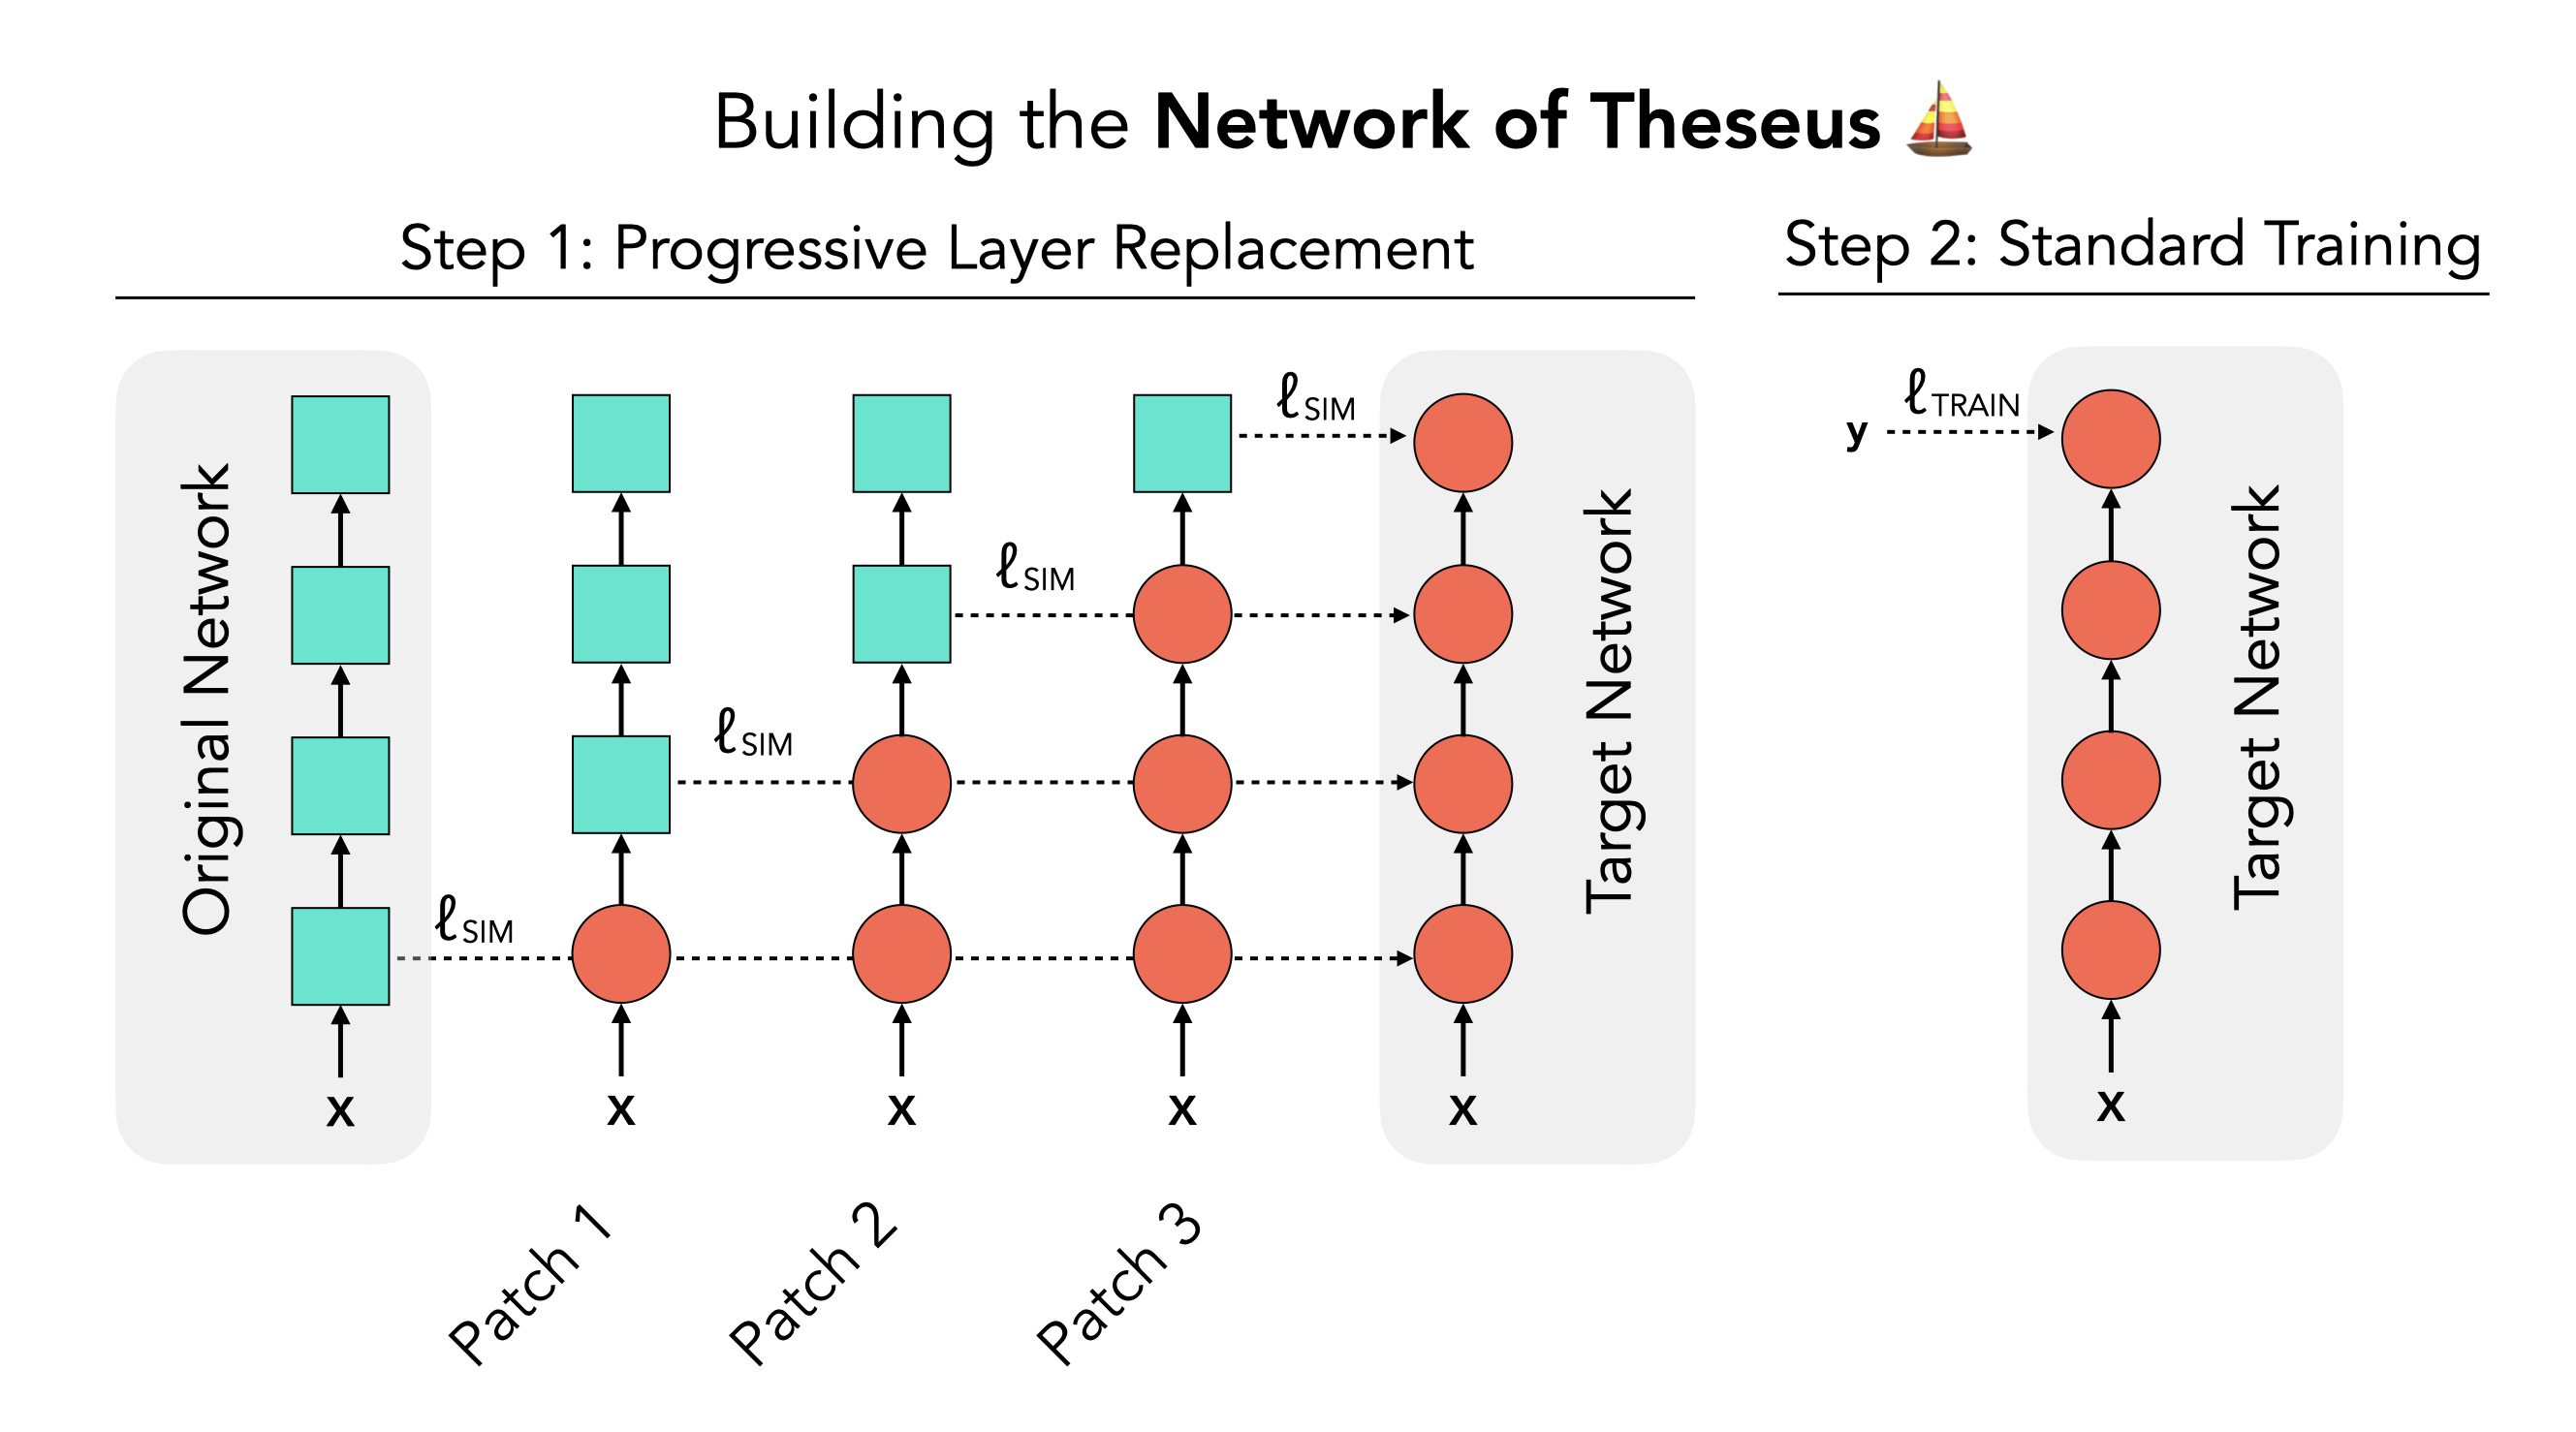
Network of Theseus (Like the ship)

Network of Theseus progressively replaces guide network modules with a different target architecture via representational alignment, preserving performance across vastly different deployed architectures.

Vighnesh Subramaniam, Colin Conwell, Boris Katz, Andrei Barbu and 1 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 10 of 20 reviewers recommend it
lenient 3/5
medium 6/10
strict 1/5
80%Must read
?Must readVote to see the score

RigidFormer: Learning Rigid Dynamics using Transformers

RigidFormer is a transformer that learns mesh-free rigid-body dynamics via object-level anchors and differentiable Kabsch projection, outperforming mesh-based baselines with faster inference and scalability to 200+ objects.

Zhiyang Dou, Minghao Guo, Haixu Wu, Doug Roble and 2 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 13 on Hugging Face · Code ★ 93

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 4/5
medium 7/10
strict 1/5