Good Papers

Showing Unified multimodal models Show all papers

82%Must read
?Must readVote to see the score

Sensor-Language-Action Models

Sensor-Language-Action modeling unifies multimodal sensors, language, and actions via a semantic interface, and OpenSLA achieves superior hierarchical prediction and explanation with zero-shot generalization.

Yuekai Xu, Zitao Shuai, Yuzhe Yang

Published Oct 6, 2026 · ▲ 1 on Hugging Face · Code ★ 1

100% Readers1 of 1 upvoted
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 5/10
strict 1/5
72%Highly rated
?Highly ratedVote to see the score

Prism: Dynamic Sparse Attention for Native 2K Joint Video-Audio Generation Model Training

Prism introduces dynamic sparse attention via adaptive macro-zone block shapes guided by visual variance and cross-modal attention for 2K joint video-audio generation, yielding 2.5x training speedup and improved quality.

Shuyuan Tu, Qi Tian, Yinming Huang, Yue Wu and 7 more

Published Oct 4, 2026 · ▲ 8 on Hugging Face · Code ★ 56

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 8 of 20 reviewers recommend it
lenient 4/5
medium 4/10
strict 0/5
72%Highly rated

Kandinsky 6.0 Video: Foundation Models for Synchronized Video and Audio Generation

Kandinsky 6.0 Video introduces diffusion models that generate synchronized 5-second audio-video clips with lip-sync via a dual-stream CrossDiT architecture, with the 29B-parameter Pro version outperforming its predecessor and matching top competitors in speech quality.

Team Kandinsky, Julia Agafonova, Bulat Akhmatov, Mikhail Aksyutin and 36 more

Published Oct 4, 2026 · ▲ 132 on Hugging Face · Code ★ 151

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 8 of 20 reviewers recommend it
lenient 5/5
medium 3/10
strict 0/5
78%Highly rated
?Highly ratedVote to see the score

Octrees as an Explicit 3D Language

OctLLM represents 3D geometry via sparse octree tokens and trains separate 3D branches to achieve state-of-the-art multimodal 3D generation and understanding without degrading language ability.

Ran Dan, Si‐Tong Wei, Pengfei Xiong, Wei Zhang and 2 more

Published Oct 1, 2026 · 0 citations · ▲ 11 on Hugging Face · Code ★ 12

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

72%Highly rated

UniEvo-VL: An On-policy Self-Distillation Training Recipe for Multimodal Model Self-improvement

UniEvo-VL improves multimodal image generation via self-distillation that minimizes divergence between student and critique-conditioned teacher diffusion distributions during self-correction. Experiments on Qwen2.5-Image improve GenEval scores from 0.747 to 0.808 without external teachers.

Fang Wu, Da Xing, Yanjie Huang, Junxi Wang and 15 more

Published Sep 30, 2026 · 0 citations · ▲ 292 on Hugging Face

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

Adaptive Reward Routing: Dynamic Multi-Reward Optimization for Joint Audio-Video Diffusion via Forward-Process RL

Adaptive Reward Routing dynamically routes updates and balances rewards during forward-process RL for joint audio-video diffusion, consistently improving quality, alignment, and synchronization over fixed baselines.

Songlin Yang, Xiaotong Zhao, Jiacheng Zhang, Zhe Wang and 4 more

Published Sep 29, 2026 · 0 citations · ▲ 138 on Hugging Face

– ReadersNo votes yet
6/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

76%Highly rated
?Highly ratedVote to see the score

HelixWorld: A Real-time Interactive Audio-Visual World Model

HelixWorld is a real-time interactive audio-visual world model that synchronizes visual scenes and spatial stereo sound under user control at 24 FPS, surpassing silent models in acoustic immersion.

Lei Ke, Jiahao Pan, Zeyue Tian, Jiaming Wang and 12 more

Published Sep 29, 2026 · 0 citations · ▲ 32 on Hugging Face · Code ★ 623

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

74%Highly rated
?Highly ratedVote to see the score

PixelUMM: Encoder-Free Unified Image and Video Understanding and Generation

PixelUMM is an encoder-free unified model for image and video understanding and generation that represents images as spatial patches and videos as spatiotemporal tubelets, achieving competitive performance across tasks.

Cong Wei, Xuanchi Ren, Bryan Chu, Weiming Ren and 7 more

Published Sep 29, 2026 · 0 citations · ▲ 32 on Hugging Face · Code ★ 161

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

Orca: The World is in Your Mind

Orca is a world foundation model that learns a unified latent space via next-state prediction from video and language, enabling scalable text, image, and action generation.

Yihao Wang, Yuheng Ji, Mingyu Cao, Yanqing Shen and 36 more

Published Jun 29, 2026 · 0 citations · ▲ 511 on Hugging Face · Code ★ 1,021

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

76%Highly rated
?Highly ratedVote to see the score

ERNIE 5.0 Technical Report

ERNIE 5.0 is a trillion-parameter unified autoregressive multimodal model using sparse MoE and elastic training to support diverse understanding and generation tasks.

Haifeng Wang, Hua Wu, Tian Wu, Yu Sun and 36 more

Published Feb 4, 2026 · 2 citations · ▲ 268 on Hugging Face

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

78%Highly rated
?Highly ratedVote to see the score

LTX-2: Efficient Joint Audio-Visual Foundation Model

LTX-2 is an open-source 14B/5B audiovisual transformer generating synchronized high-quality video and audio with state-of-the-art open-source quality at low computational cost.

Yoav HaCohen, Benny Brazowski, Nisan Chiprut, Yaki Bitterman and 25 more

Published Jan 6, 2026 · 0 citations · ▲ 197 on Hugging Face · Code ★ 9,606

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

78%Highly rated
?Highly ratedVote to see the score

Tuna-2: Pixel Embeddings Beat Vision Encoders for Multimodal Understanding and Generation

Tuna-2 replaces vision encoders with patch embeddings for end-to-end pixel-space multimodal understanding and generation, achieving state-of-the-art results that outperform encoder-based designs at scale.

Zhiheng Liu, Weiming Ren, Xiaoke Huang, Shoufa Chen and 11 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 70 on Hugging Face · Code ★ 756

– ReadersNo votes yet. 1 from authors or colleagues not counted
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 4/5
medium 6/10
strict 1/5
45%Niche pick
?Niche pickVote to see the score

MSCR: Jointly Balancing Modality Utilization and Discovering Synergistic Information

Xinyu Chen, Liangjian Wen, Jiang Duan, Dongkai Wang and 6 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

MEME: Lightweight Hierarchical Mixture-of-Experts for Unified Affective Computing

Yinan Zhang, Haoyu Zhang, Tianshu Yu

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

DiM$^3$: Bridging Multilingual and Multimodal Models via Direction- and Magnitude-Aware Merging

Zijing Wang, Mingyang Wang, Ercong Nie, Yongkang Liu and 5 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Benchmarking and Optimizing Multimodal Structured Generation: The OracleGraph Dataset and PRISM Framework

Zhihong Sun, Qi Fan, Pan Liu, Yang Yi and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

FuseAdapt: Adaptation-Space Fusion for Multi-Modal Semantic Segmentation with Missing Modalities

Xin Zhang, Robby Tan

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

COSMIO: A Benchmark for Cross-Survey Modality Imputation

Dichang Zhang, Yixuan Shao, Jiali Cui, Haotian Yin and 7 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Concurrent Image Understanding and Generation: Self-Correcting Coupled Markov Jump Process

Minh-Quan Le, Armand Comas, Alexandros Lattas, Stylianos Moschoglou and 6 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

SING-CH: Task-Scale-Agnostic Lifelong Cross-Modal Hashing on Statistical Manifolds

Haoran Yang, Junge Chen, Jun Long, Zhan Yang

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

A Unified Audio Language Model with Text-Aligned Factorized Audio Tokenization

Dongchao Yang, Yuanyuan Wang, Songxiang Liu, Dading Chong and 2 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Reliability-Coupled Manifold-Aware Diffusion for Missing-Modality Inference

Yiming Ren, Yuhao Fang, Qing Zhou, Ming Li and 4 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

HyperSkill: Multi-Modal Skill Learning on the Unit Hypersphere

Erdemt Bao, JunChen, Weijun Qin, Shaopeng Li and 5 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Multimodal Context-Aware Human Motion Generation with Language, Vision, and Object

Junyu Shi, Yong Sun, Zhiyuan Zhang, Lijiang LIU and 3 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

WorldVLA: A Unified Vision-Language-Action and World Model

Jun CEN, Siteng Huang, Yuqian Yuan, Kehan Li and 10 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Latent Reasoning in Continuous Space for Unified Multimodal Models

Byungwoo Jeon, Yoonwoo Jeong, Hyunseok Lee, Minsu Cho and 1 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Holistic EvoLution via Intrinsic eXchange for Unified Multimodal Models

Shenghao Dong, Yuhang Yu, Bo Li, Jinwei Chen and 1 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Probe-Guided Gradient Balancing for Multimodal Learning

Vu Vo, Haytham Fayek, Thuy T Nguyen

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

A Unified Image and Video Encoder for Multimodal LLMs

Tongtian Yue, Zikang Liu, Longteng Guo, Handong Li and 8 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

MMTA: Benchmarking Multimodal Temporal Analysis with Time Series, Text, and Vision

Ziyang Zhang, Shenyi Li, Yilin wang, Ziyun Cui and 3 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Attribution-Guided Shared-Private Decoupling for Noise-Reduced Audio-Visual Representation Learning

Linge Wang, Yingying Chen, Bingke Zhu, Lu Zhou and 3 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

M3-HNTM: Hyperspherical Multimodal Topic Modeling with Symbolic and Contextual Evidence

Zhiwen Luo, Dayu Guo, Manar Amayri, Nizar Bouguila and 3 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

FusionNeXt: Sequence-First 3D Multi-Modal Fusion in the Era of LLMs

Yu Hong, Xiaosong Jia, Songbur Wong, Yanhao Liu and 3 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Two Drifts, One Principle: Conflict-Aware Spectral Consolidation for Multimodal Continual Learning

Haiyi Zhang, Qianyi Cai, Hanqing Wang, Zilin Wang and 6 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

BRACE: Bipolar Reference-Aware Calibration and Estimation for Incomplete Multimodal Learning

Ruiting Dai, Zesen Cai, XiaoYu Zhao, Yiting Huang and 3 more

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Context-Aware Generative Imputation for Robust Multimodal Learning in Missing Modality Scenarios

Jungwon Choi, Juho Lee

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Beyond 3 Million Tokens: A Multi-Modal Foundation Model for Full-Resolution Heliophysics

Sujit Roy, Johannes Schmude, Ata A Asanjan, Thorsten Kurth and 12 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

MSC-Mol: Modality-Synergy Contrasting for Multimodal Molecular Representation Learning

Ziyu Fan, Enqi Dong, Yahan Li, Shuhong Liu and 5 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

VocalGrad: Evaluating Acoustic Perception in Audio Language Models

Koki Ryu, Hitomi Yanaka

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

An Efficient Cross-modal Feature Reconstruction Model for Multimodal Multi-class Anomaly Detection

Zhenghan Wang, Zhihui Luo, Haitao Hu, Wengang Cheng

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

CoDeRNet: Selective Cross-Task Routing under Heterogeneous Supervision for Change Detection and Captioning

Eunki Cho, Hyeon Bae Kim, Seong Tae Kim

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

M*: A Modular, Extensible, Serving System for Multimodal Models

Atindra Jha, Naomi Sagan, Keisuke Kamahori, Irmak Sivgin and 8 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Bridging 1D, 2D, and 3D with Any-to-Any Multimodal Modeling

Jason Toskov, Oriol Barbany, Rishubh Singh, Jinya Sakurai and 9 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

No Free Alignment: Observability-Aware Alignment for Multimodal Heterogeneous Learning

Canran Xiao, Puning Zhao, Enneng Yang, XIAOCHUN CAO and 2 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

NeuroNTP - A Generalizable Multimodal Foundation Model for Epilepsy

József Kovács, Amadeus Hauser, Gudrun Gröppel, Wolfgang Narzt and 1 more

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Full-Duplex Speech-Motion Model for Dyadic Interaction

Koki Nagano, Hongyu Liu, Wookie Park, Tianye Li and 7 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

67%Highly rated
?Highly ratedVote to see the score

Complexity-Aware LoRA Aggregation for Modality-Heterogeneous Federated Person Re-identification

Kunyang Lv, Wenke Huang, Wenwen He, Bin Yang and 2 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
2/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 2 of 20 reviewers recommend it
lenient 2/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Unaligned Image Guided Denoising via Cross-modal Conditional Flow Matching

Runmin Zhang, Linshan Li, Si-Yuan Cao, Zhu Yu and 3 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Sparse Multimodal Switching State-Space Models for Regime-Dependent Neural Connectivity under Partial Observations

Rahul K Sharma, Feng Liu, Xiaochen Xian

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

XMNoise2Clean: Cross-Modal Denoising Under Sparse Data

Hirad Yazdankhah, Chris Metzler

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Subset-Conditioned Boundary Compensation for Missing-Modality Multimodal Classification

Zesen Cai, Lisi Mo, Yifan Fang, Yandong Yan and 3 more

Paris Poster Session 2, Wed, Dec 9, 5:00 PM–7:00 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Mixture of Probes: Learning with Privileged Modalities in Multimodal LLMs Through Probing

Dominick Reilly, Qiyu Wu, Hiromi Wakaki, Srijan Das and 1 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

LEAF: Language-EEG Aligned Foundation Model for Brain-Computer Interfaces

Muyun Jiang, Shuailei Zhang, Zhenjie Yang, Wu Mengjun and 9 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

Split and Bridge: Multimodal Generation via Diffusion Bridging

Ahmad Arrabi, Xiaohan Zhang, Xingyu Li, Safwan Wshah

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

WaveMamba: Wave-Inspired Cross-Modal Fusion for Robust event-image Semantic Segmentation

Adeel F Mirza, Zaiyue Yang, Muntazir Hussain

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

HYDRA: Representation Harmonized Tokenization for Multimodal Generation and Understanding

Xuerui Qiu, Yutao Cui, Guozhen Zhang, Junzhe Li and 8 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Read, Parse, Describe: Unified Document Parsing with Visual Element Description Generation

Yuheng Chen, Yufan Chen, Zhuojun Cai, Ruiping Liu and 7 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

One Unified Representation: Resolving the Appearance-Semantics Dilemma via Structural Regularization

RUIQI YANG, Fei Zhou, Yi Zhang, Liang Li and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

PM1: A Multimodal Foundation Model for Genomes, Phenotypes, and Images at Biobank Scale

Christophe Thomassin, Marçal Comajoan Cara, Margarita Geleta, David Bonet and 3 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

A Unified Spectral Theory of Multimodal Losses

Yu-Ang Cheng, Sixuan Chen, Zhouyang Lu, Xizheng Yu and 2 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

GeoPMR: Preserving Relational and Hierarchical Geometry in Multimodal Molecular Representation Learning

Lusheng Li, Menglin Yang

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

45%Niche pick
?Niche pickVote to see the score

Unpaired Canonical Correlation Analysis

Nir Ben-Ari, Ronen Talmon, Uri Shaham

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

57%Worth a look
?Worth a lookVote to see the score

Geometric Alignment without Functional Equivalence: A Layer-wise Analysis of the Speech-Text Modality Gap

Ming-Hao Hsu, Xiaohai Tian, Jun Zhang, Lu Lu and 2 more

Paris Poster Session 6, Fri, Dec 11, 2:30 PM–4:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
45%Niche pick
?Niche pickVote to see the score

MODULE: A Mutual-Promoting Deep Unfolding Framework Towards Degradation-Robust Multi-modal Image Fusion

Han Xu, Yunfei Deng, Jiayi Ma, Guangcan Liu

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
74%Highly rated
?Highly ratedVote to see the score

DCVD: Dual-Channel Cross-Modal Fusion for Joint Vulnerability Detection and Localization

DCVD jointly detects vulnerable functions and localizes vulnerable statements via dual-channel cross-modal fusion with explicit multi-granularity supervision, outperforming state-of-the-art baselines.

Wenxin Tang, Wenbin Li, Junliang Liu, Jingyu Xiao and 9 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

74%Highly rated
?Highly ratedVote to see the score

AnyMo: Scaling Any-Modality Conditional Motion Generation with Masked Modeling

AnyMo introduces OmniHuMo dataset with 5,000 hours of multimodal motion data and proposes a masked modeling framework for scalable any-modality conditional motion synthesis with flexible spatial and stylistic control.

Yiheng Li, Zhuo Li, RuiBing Hou, Yingjie Chen and 3 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 2 on Hugging Face

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

When Integral Meets Decomposition: A Signal-Level Self-Supervised Feature Decompose Paradigm for Multi-Modal Image Fusion

A signal-level self-supervised paradigm reformulates multimodal feature decomposition via 1D integral constraints, achieving state-of-the-art fusion performance without ground-truth feature maps.

Zeyu Wang, Jiayu Wang, Haiyu Song, Haoran Duan

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read
?Must readVote to see the score

VSRo-200: A Romanian Visual Speech Recognition Dataset for Studying Supervision and Multimodal Robustness

VSRo-200 introduces a 200-hour Romanian lip-reading dataset to benchmark supervision quality, domain shift, and multimodal robustness in low-resource visual speech recognition.

Iulia-Maria Udrea, Alexandra Diaconu, Bogdan Alexe

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

Unifying Contrastive and Generative Objectives for Visual Understanding and Text-to-Image Generation

DREAM unifies contrastive and generative objectives via Masking Warmup, yielding joint visual understanding gains and faster, higher-quality text-to-image generation.

Chao Li, Tianhong Li, Sai V Nuthalapati, Hong-You Chen and 8 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 6 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 4/5
medium 9/10
strict 2/5
71%Highly rated
?Highly ratedVote to see the score

Meow-Omni 1: A Multimodal Large Language Model for Feline Ethology

Meow-Omni 1 integrates video, audio, physiological time-series, and text to reach 71.16% feline intent recognition, outperforming baseline multimodal models.

Jucheng Hu, Zhangquan Chen, Yulin Chen, Chengjie Hong and 8 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 3 on Hugging Face

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read
?Must readVote to see the score

ELSA3D: Elastic Semantic Anchoring for Unified 3D Understanding and Generation

ELSA3D introduces elastic semantic anchoring to unify 3D understanding and generation via scale-matched cross-modal routing, achieving state-of-the-art results with roughly half the FLOPs and latency.

Tianjiao (Joey) Yu, Xinzhuo Li, Yifan Shen, Onkar Susladkar and 3 more

Atlanta Poster Session 5, Fri, Dec 11, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read
?Must readVote to see the score

MindAlign: Bridging EEG, Vision, and Language for Zero-Shot Visual Decoding

MindAlign aligns EEG, vision, and language via tri-modal contrastive learning to achieve 54.1% zero-shot visual decoding accuracy on Things-EEG2.

Zexuan Chen, Sichao Liu, Runhao Lu, Huichao Qi and 3 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

88%Must read

MulTaBench: Benchmarking Multimodal Tabular Learning with Text and Image

MulTaBench benchmarks 40 multimodal tabular datasets and shows target-aware tuning of text and image embeddings improves predictive performance over frozen embeddings.

Alan Arazi, Eilam Shapira, Shoham Grunblat, Mor Ventura and 7 more

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026 · ▲ 142 on Hugging Face

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Only vote on papers you've read. Sign in with GitHub to vote.

76%Highly rated
?Highly ratedVote to see the score

MOSAIC-CONUS: A Multimodal, Multi-Temporally Paired dataset for Earth Sciences

MOSAIC-CONUS introduces a point-indexed multimodal Earth observation dataset over the contiguous U.S. with cross-sensor alignment tables and benchmarks for geospatial AI embeddings.

Abhishek Potnis, Youssef Hussein, Waqwoya Abebe, JangHyeon Lee and 6 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

83%Must read
?Must readVote to see the score

LARGO: Low-Rank Hypernetwork for Handling Missing Modalities

LARGO uses low-rank weight-space hypernetworks via CP decomposition to unify missing-modality models, outperforming state-of-the-art on BraTS and ISLES benchmarks.

Niels Vyncke, Pooya Ashtari, Aleksandra Pizurica

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

78%Highly rated
?Highly ratedVote to see the score

Fine-tuning language encoding models on slow fMRI improves prediction for fast ECoG

Fine-tuning language models on slow fMRI improves fast ECoG encoding predictions despite lower temporal resolution, with performance scaling with fMRI data volume.

Aditya Vaidya, Richard Antonello, Alexander Huth

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 4/10
strict 2/5
78%Highly rated
?Highly ratedVote to see the score

Native Audio-Visual Alignment for Generation

NAVA proposes native audio-visual alignment with an Align-then-Fuse MMDiT architecture for joint audio-video generation, achieving superior synchronization, video quality, and timbre control with 6.3B parameters.

Longbin Ji, Guan Wang, xuan wei, Chenye Yang and 4 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026 · ▲ 31 on Hugging Face · Code ★ 226

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

71%Highly rated
?Highly ratedVote to see the score

SemMSA: Latent Semantic-Aided Robust Multimodal Sentiment Analysis with Incomplete Data

SemMSA uses LLM-derived latent semantics and spectral alignment to robustly analyze multimodal sentiment with incomplete data, achieving state-of-the-art results.

Wenhao Li, Zhibin Wu, Chong Xiao, Qiangchang Wang

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

74%Highly rated
?Highly ratedVote to see the score

SceneBind: Binding What and Where Across Vision, Audio, and Language

SceneBind binds vision, audio, and language via semantic-spatial entities and matching to achieve state-of-the-art cross-modal scene retrieval and spatial grounding.

Mingfei Chen, Zijun Cui, Ruoke Zhang, Hyeonggon Ryu and 1 more

Atlanta Poster Session 3, Thu, Dec 10, 10:00 AM–1:00 PM, Hall C1 · Published 2026

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 9 of 20 reviewers recommend it
lenient 5/5
medium 4/10
strict 0/5
91%Must read
?Must readVote to see the score

When to Align, When to Predict: A Phase Diagram for Multimodal Learning

Under structured cross-modal nuisance correlation, cross-modal alignment and prediction have complementary failure modes partitioned by separation ratios into four regimes, with a data-driven procedure identifying preferred objectives and when neither beats single-modality baselines.

Ilay Kamai, Hugues Van Assel, Aviv Regev, Hagai B Perets and 1 more

Paris Poster Session 5, Fri, Dec 11, 11:30 AM–1:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

89%Must read
?Must readVote to see the score

Standing on the Shoulders of Giants: Rethinking EEG Foundation Model Pretraining via Multi-Teacher Distillation

Multi-teacher distillation pretrains EEG foundation models using vision and time-series teachers via masked latent denoising, outperforming self-supervised methods with 75% less pretraining data.

Chenqi Li, Yu Liu, Shuo Zhang, Timothy Denison and 1 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
16/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 16 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 3/5
74%Highly rated
?Highly ratedVote to see the score

Edit-R2: Context-Aware Reinforcement Learning for Multi-Turn Image Editing

Edit-R2 uses reinforcement learning to reconstruct session intent and jointly optimize reasoning and generation for multi-turn image editing. It improves instruction following and consistency over accumulated constraints on the MICE-Bench benchmark.

Yuxiao YE, Haoran He, Fangyuan Kong, Xintao Wang and 3 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 9 of 20 reviewers recommend it
lenient 5/5
medium 4/10
strict 0/5
80%Must read
?Must readVote to see the score

MIRAGE: Adaptive Multimodal Gating for Whole-Brain fMRI Encoding

MIRAGE predicts whole-brain fMRI from audiovisual stimuli via adaptive multimodal gating, outperforming unimodal feature aggregation with interpretable cortical modality patterns.

Abdulkadir Gokce, Badr AlKhamissi, Martin Schrimpf

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · Code ★ 6

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

80%Must read
?Must readVote to see the score

Minimizing Modality Gap from the Input Side: Your Speech LLM Can Be a Prosody-Aware Text LLM

TextPro-SLM minimizes speech-text modality gap by feeding prosody-aware text inputs to LLMs, cutting the gap at 3B and 7B scales with only ~1,000 hours of audio.

Wenqian Cui, Xiao-Hui Li, Daxin Tan, Qiyong Zheng and 1 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 12 of 20 reviewers recommend it
lenient 4/5
medium 7/10
strict 1/5
88%Must read
?Must readVote to see the score

Model Guides You How to Draw: Adaptive Visual Gating for Unified Multimodal Reasoning

AdaViG uses internal generation-intent and visual-fidelity signals to abort unhelpful visual reasoning steps early, improving multimodal reasoning accuracy by up to 5.7% while cutting visual generation costs by 25-91%.

Wenxi Gao, Guanxi Lu, Didi Zhu, Hao Chen and 4 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
15/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 15 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 2/5
76%Highly rated
?Highly ratedVote to see the score

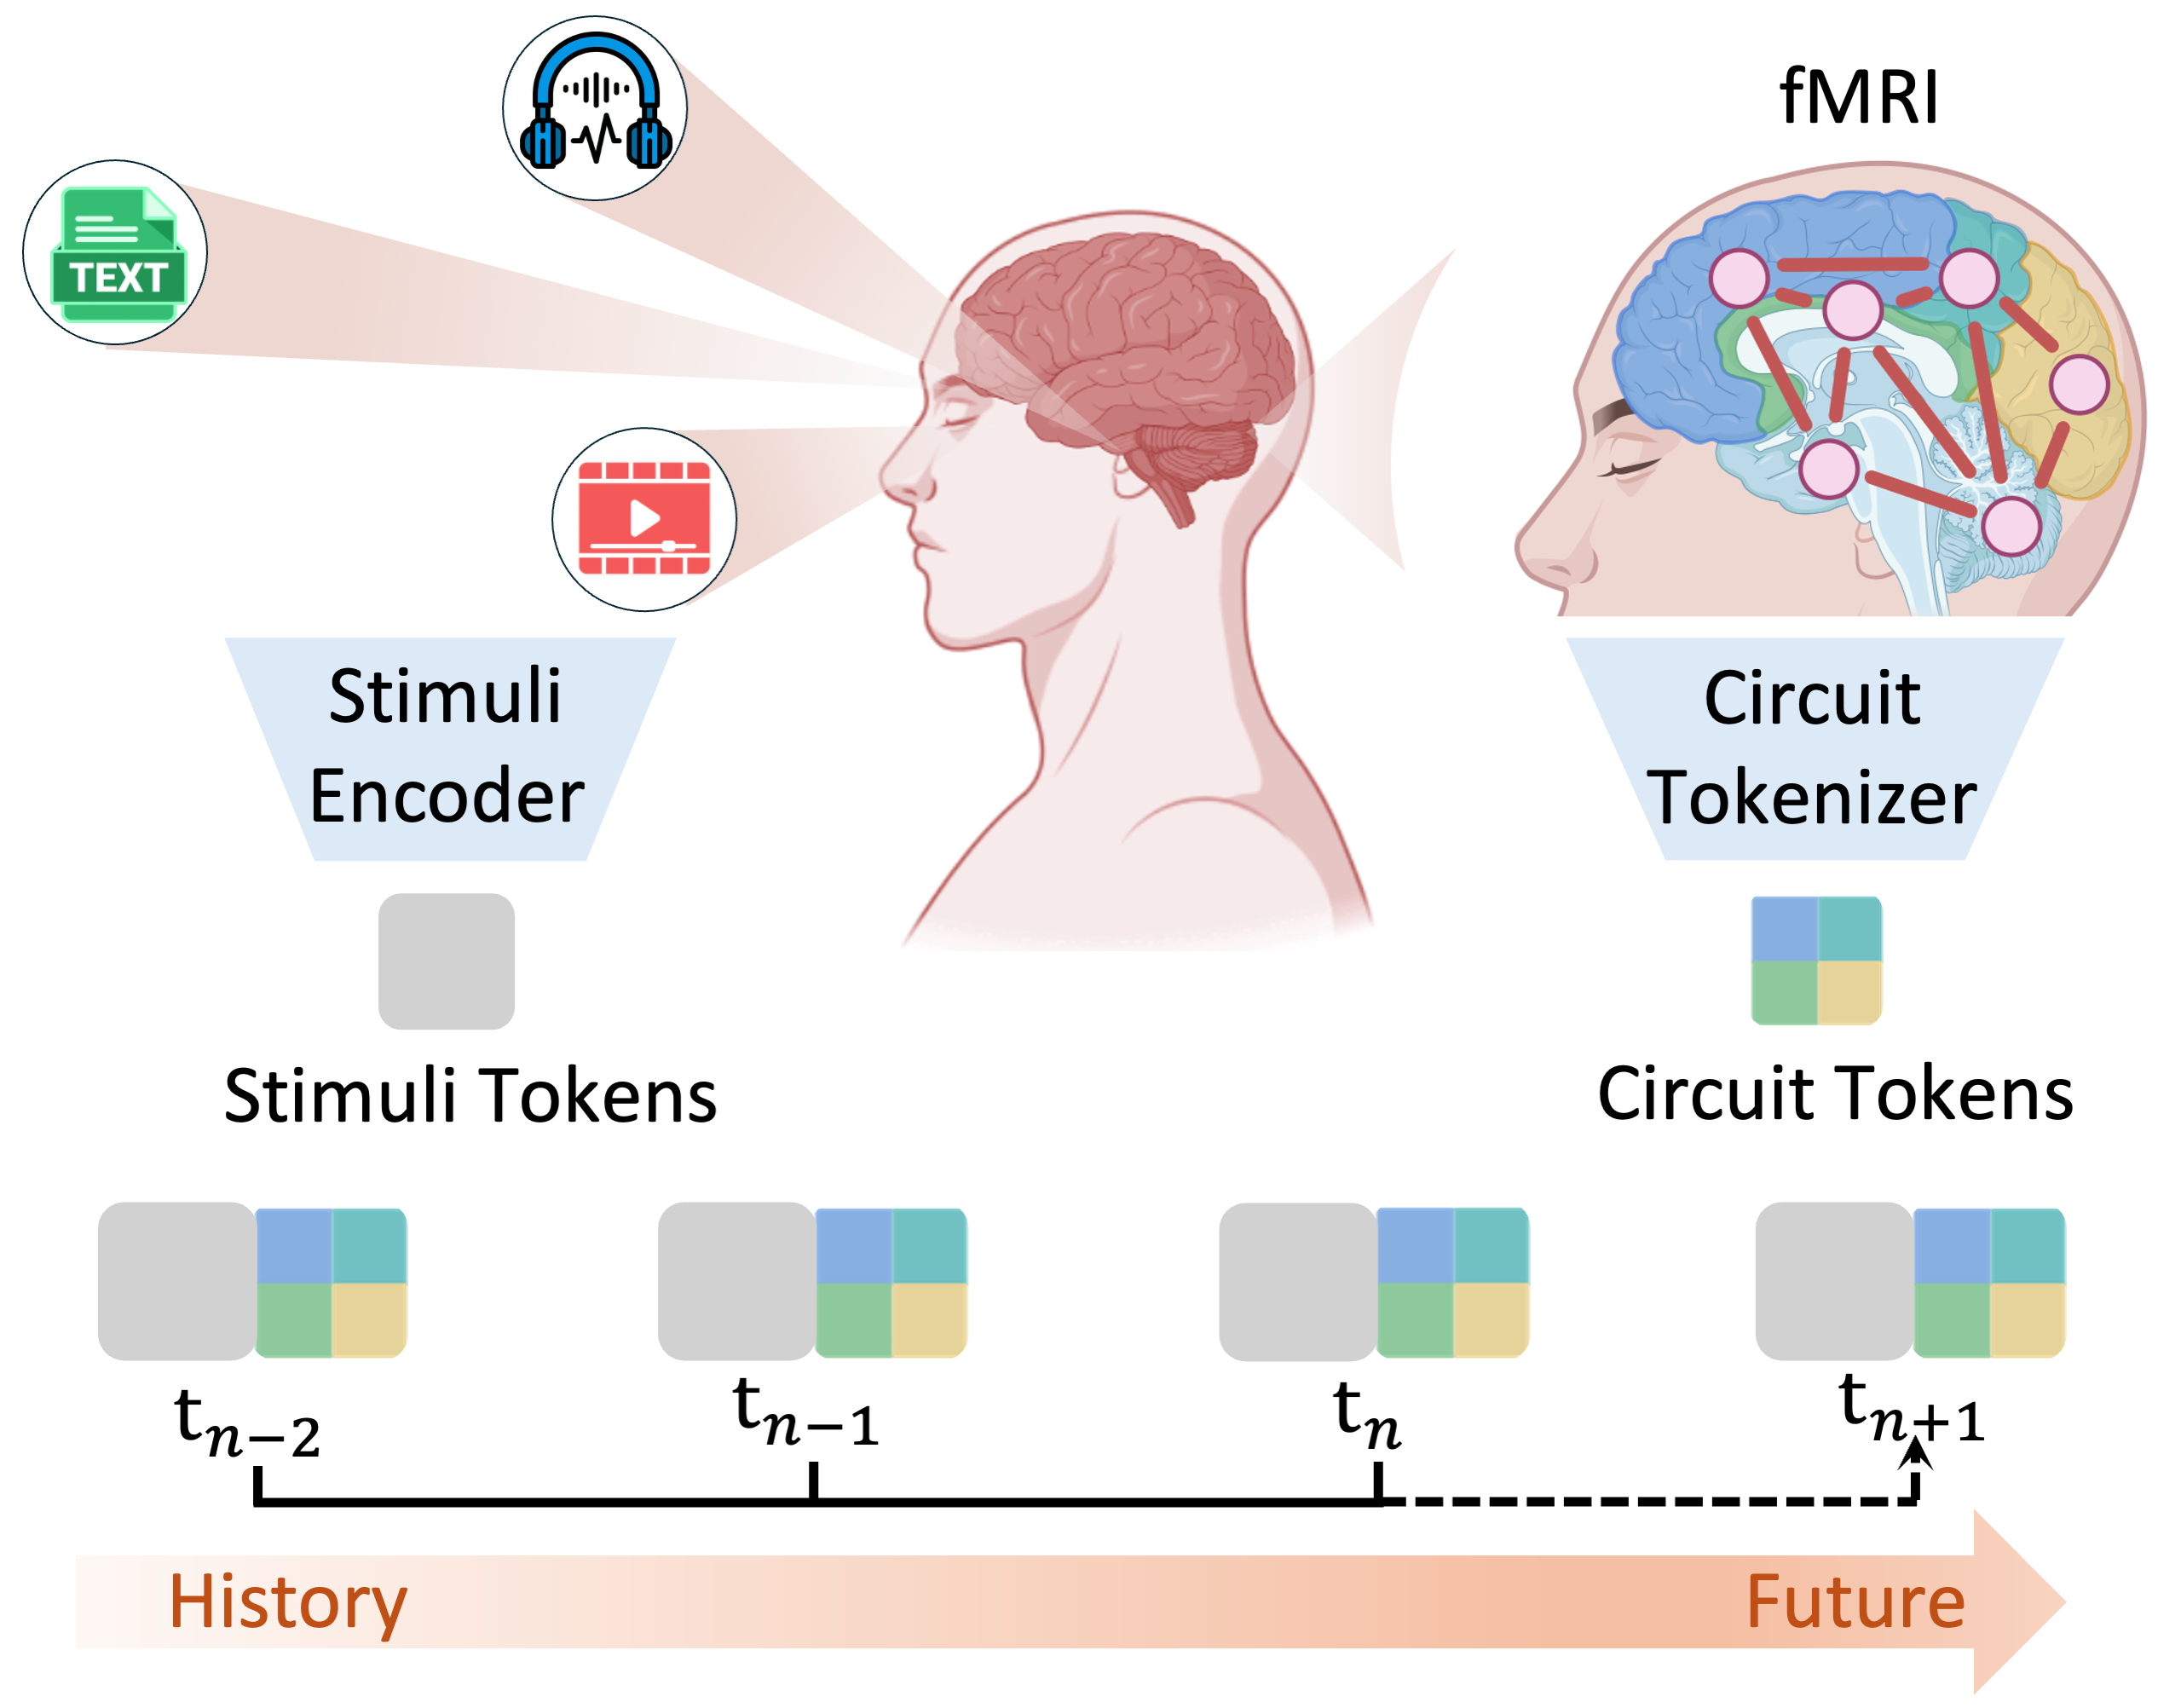
BrainVista: Modeling Naturalistic Brain Dynamics as Multimodal Next-Token Prediction

BrainVista models brain dynamics via multimodal next-token prediction with network tokenizers and stimulus masking, achieving state-of-the-art fMRI encoding and up to 36% better long-horizon rollout correlations.

Xuanhua Yin, Ted Zhao, Lina Yao, Weidong Cai

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

72%Highly rated
?Highly ratedVote to see the score

STARFlow2: Bridging Language Models and Normalizing Flows for Unified Multimodal Generation

STARFlow2 unifies multimodal generation by vertically interleaving a pretrained vision-language model with an autoregressive normalizing flow under shared causal masking, enabling cache-friendly interleaved text-image generation with strong benchmark performance.

Ying Shen, Tianrong Chen, Yuan Gao, Yizhe Zhang and 5 more

Atlanta Poster Session 6, Fri, Dec 11, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 13 on Hugging Face

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 8 of 20 reviewers recommend it
lenient 2/5
medium 6/10
strict 0/5
76%Highly rated
?Highly ratedVote to see the score

UniPath: Adaptive Coordination of Understanding and Generation for Unified Multimodal Reasoning

UniPath adaptively selects reasoning paths across understanding and generation to improve unified multimodal reasoning via diverse coordination strategies.

Haoyue Bai, Yinyi Luo, Wenwen Wang, Qingsong Wen and 1 more

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026 · ▲ 3 on Hugging Face

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

76%Highly rated
?Highly ratedVote to see the score

Baton: Explicit Semantic Blueprints for Joint Video-Audio Generation

Baton introduces explicit semantic blueprints via a multimodal planner and relative positional encoding for synchronized joint video-audio generation.

Shuyuan Tu, Qi Tian, Zihan Yang, Yue Wu and 8 more

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 10 of 20 reviewers recommend it
lenient 4/5
medium 6/10
strict 0/5
80%Must read
?Must readVote to see the score

The Design Space of Tri-Modal Masked Diffusion Models

A tri-modal masked diffusion model pretrained from scratch on text, image-text, and audio-text data achieves strong cross-modal generation and introduces an SDE-based batch-size reparameterization.

Louis Bethune, Victor Guilherme Turrisi da Costa, Bruno Mlodozeniec, Pau Rodriguez and 20 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 4 on Hugging Face

– ReadersNo votes yet
12/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

72%Highly rated
?Highly ratedVote to see the score

OBJECT-UNI: A Unified Model for Object-Centric Spatial Understanding and Controllable Generation

Object-Uni unifies object-centric spatial understanding and controllable generation via explicit pose variables, improving pose reasoning and geometrically consistent synthesis.

Mining Tan, yinuo Wang, Ziqi Zhou, Weize Quan and 5 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 8 of 20 reviewers recommend it
lenient 4/5
medium 4/10
strict 0/5
74%Highly rated
?Highly ratedVote to see the score

Beyond Spatial-Domain Supervision: A Relation Constrained Space for Multi-Modal Image Fusion

Proposed relation-constrained supervision shifts multi-modal image fusion from spatial sources to a learned relation space via aligned DINO and CLIP features, improving results across backbones.

Zeyu Wang, Mingyu Ge, Haiyu Song, Haoran Duan

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
9/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 9 of 20 reviewers recommend it
lenient 3/5
medium 6/10
strict 0/5
78%Highly rated
?Highly ratedVote to see the score

ES-Merging: Biological MLLM Merging via Embedding Space Signals

ES-Merging estimates merging coefficients from embedding space signals to combine biological multimodal models, improving cross-modal reasoning and single-modal knowledge preservation.

Wonbin Lee, Dongki Kim, Sung Ju Hwang

Sydney Poster Session 6, Thu, Dec 10, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 0/5
72%Highly rated
?Highly ratedVote to see the score

RePercENT: Scaling Disentangled Representation Learning Beyond Two Modalities

RePercENT scales disentangled multimodal representation learning beyond two modalities via a plug-and-play framework that extracts shared and unique factors with formal guarantees and lower complexity.

Vasiliki Rizou, Pascal Frossard, Dorina Thanou

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
8/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 8 of 20 reviewers recommend it
lenient 4/5
medium 4/10
strict 0/5
78%Highly rated
?Highly ratedVote to see the score

LatentUM: Unleashing the Potential of Interleaved Cross-Modal Reasoning via a Latent-Space Unified Model

LatentUM unifies modalities in a shared latent space to enable efficient interleaved cross-modal reasoning and generation, achieving state-of-the-art visual planning and self-reflective generation results.

Jiachun Jin, Zetong Zhou, Xiao Yang, Hao Zhang and 3 more

Sydney Poster Session 2, Tue, Dec 8, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026 · ▲ 29 on Hugging Face · Code ★ 63

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 5/10
strict 1/5
86%Must read
?Must readVote to see the score

G$^2$TR: Generation-Guided Visual Token Reduction for Separate-Encoder Unified Multimodal Models

G²TR uses generation-branch signals to reduce visual tokens in unified multimodal models, cutting prefill computation by 1.94× while preserving reasoning and editing performance.

Junxian Li, Kai Liu, Zizhong Ding, Zhixin Wang and 3 more

Sydney Poster Session 1, Tue, Dec 8, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
14/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 14 of 20 reviewers recommend it
lenient 5/5
medium 9/10
strict 0/5
83%Must read
?Must readVote to see the score

Semantic Motion Anchors: Bridging Motion and Meaning in Co-Speech Gestures

Semantic motion anchors discretize gesture motion into verbalized primitives to align text and gestures, improving retrieval and generation by capturing communicative intent over low-level kinematics.

Varsha Suresh, Mohammad Mahdi Abootorabi, Mohamed Salman, M. Hamza Mughal and 4 more

Paris Poster Session 4, Thu, Dec 10, 5:30 PM–7:30 PM, Paris Poster Hall · Published 2026

– ReadersNo votes yet
13/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 13 of 20 reviewers recommend it
lenient 5/5
medium 8/10
strict 0/5
Show 20 more papers