Good Papers

Showing papers from Yale University & Cisco Foundation AI Show all papers

45%Niche pick
?Niche pickVote to see the score

Demystifying Classifier-Free Guidance for Auto-Regressive Image Generation

Zhiling Zhou, Jiachun Pan, Fengzhuo Zhang, Dirk Bergemann and 1 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
69%Highly rated
?Highly ratedVote to see the score

Rethinking "RL Generalizes, SFT Memorizes": The Role of SFT Data

Yunlong Hou, Fengzhuo Zhang, Yuan Cheng, Jiachun Pan and 2 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
3/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 3 of 20 reviewers recommend it
lenient 1/5
medium 1/10
strict 1/5
76%Highly rated
?Highly ratedVote to see the score

Why Muon Outperforms Adam: A Curvature Perspective

Muon achieves larger one-step loss decreases than Adam via lower curvature penalties driven by reduced normalized directional sharpness rather than update scale, with advantages amplified by data imbalance and within-layer curvature.

Shuche Wang, Fengzhuo Zhang, Jiaxiang Li, Dirk Bergemann and 1 more

Atlanta Poster Session 1, Wed, Dec 9, 10:00 AM–1:00 PM, Hall C1 · Published 2026 · ▲ 10 on Hugging Face

– ReadersNo votes yet
10/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 10 of 20 reviewers recommend it
lenient 4/5
medium 4/10
strict 2/5
78%Highly rated
?Highly ratedVote to see the score

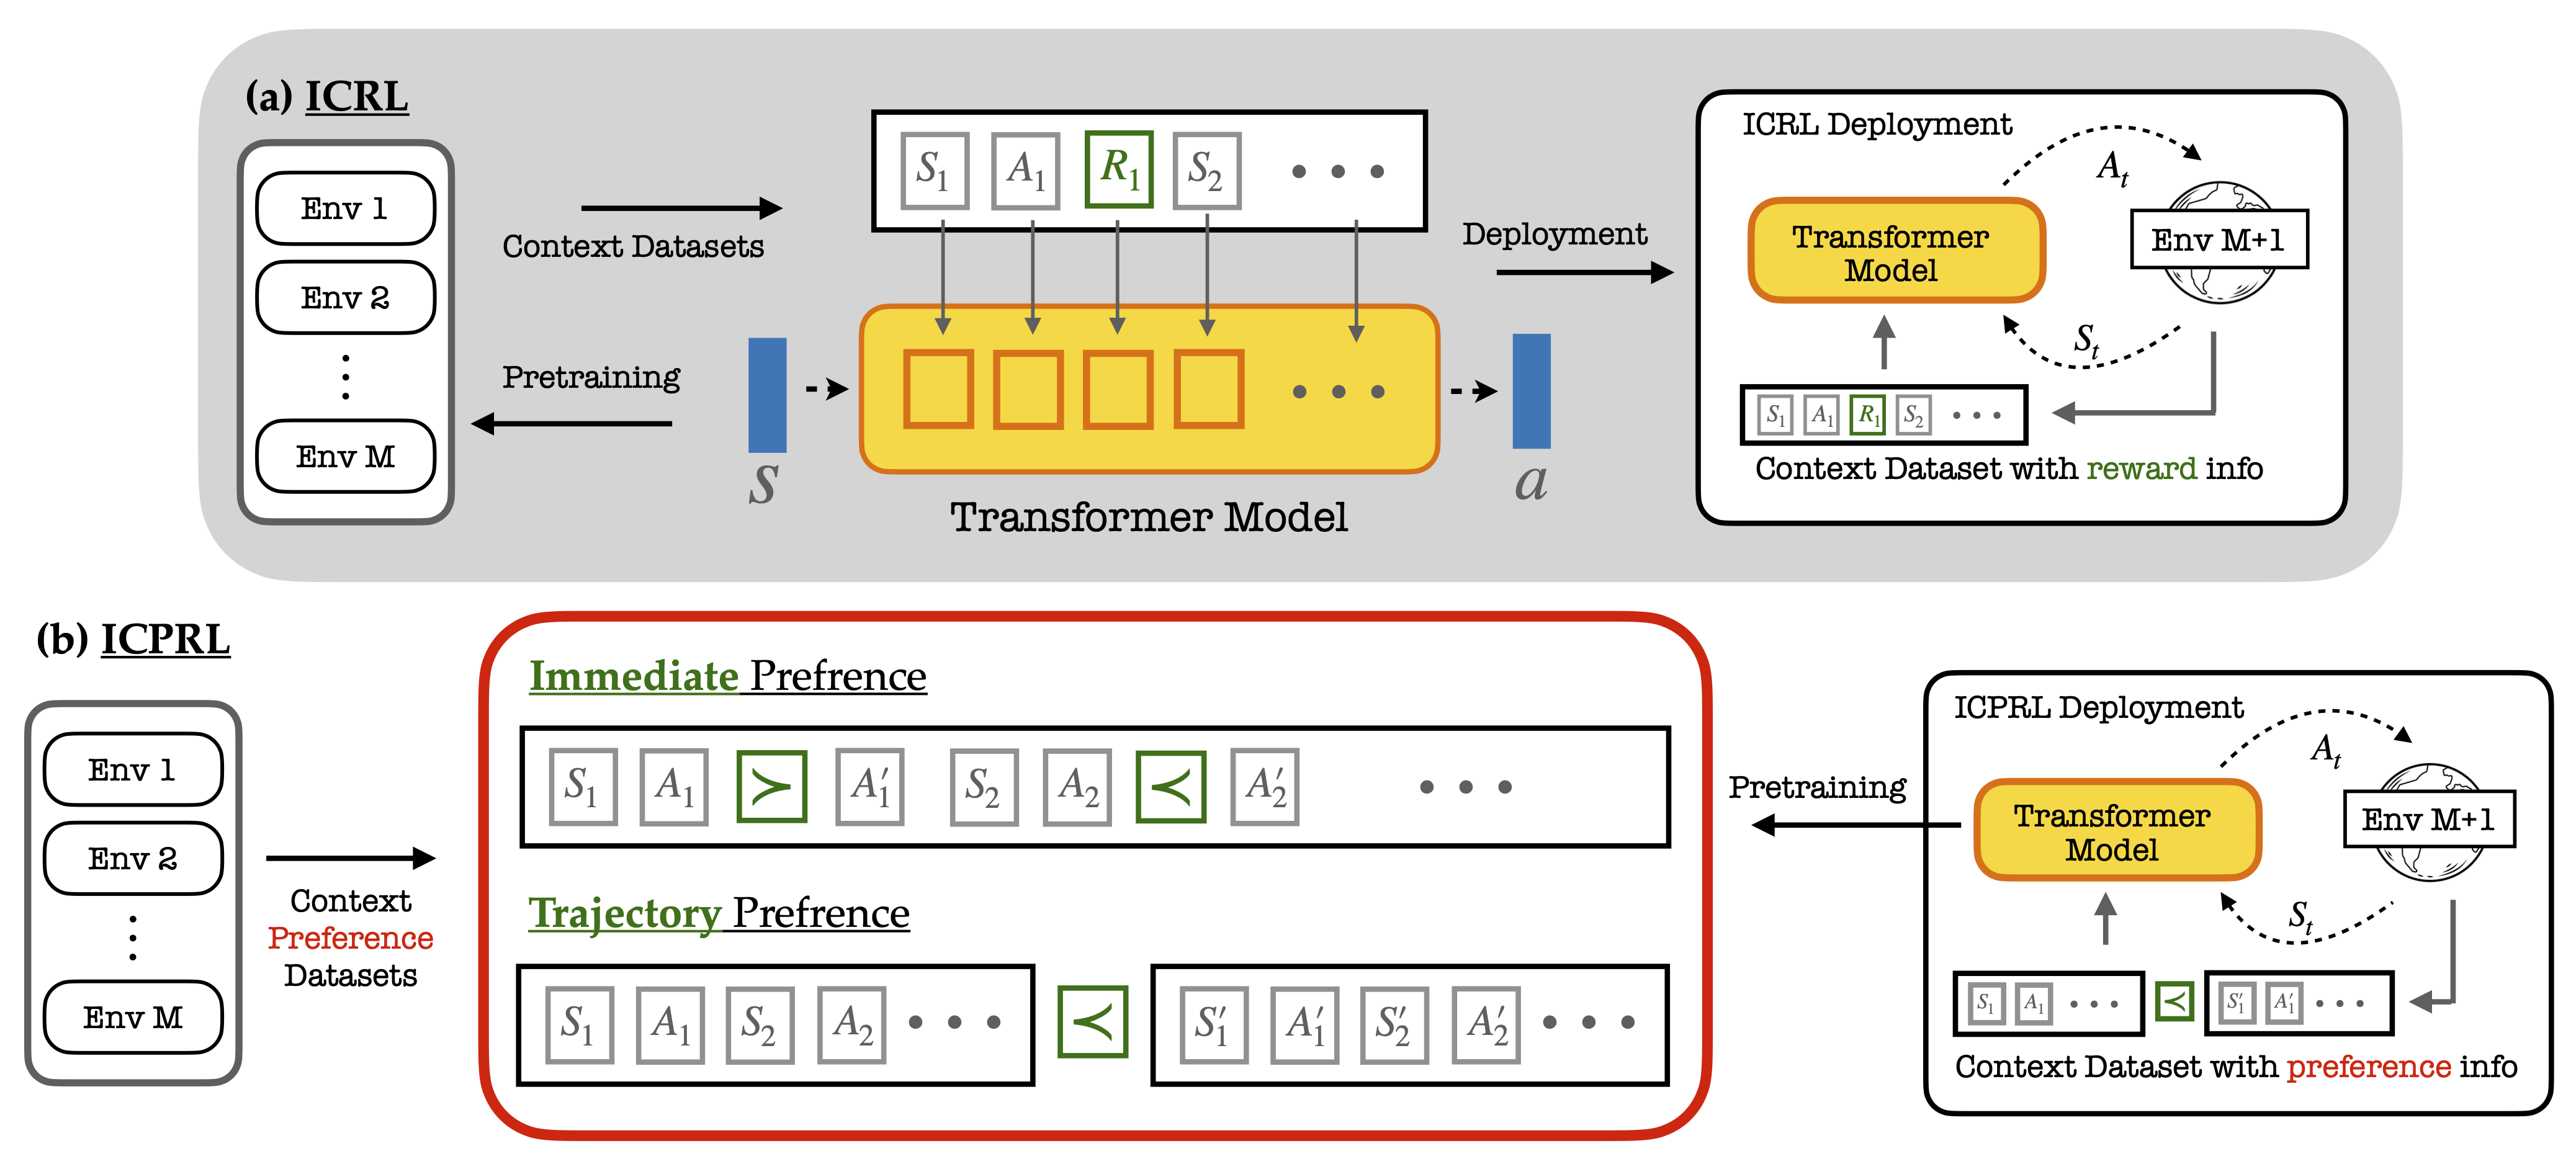
Learning in Context, Guided by Choice: A Reward-Free Paradigm for Reinforcement Learning with Transformers

In-context preference-based RL trains transformers solely on preference feedback, achieving reward-free in-context generalization comparable to fully supervised methods.

Juncheng Dong, Moyang Guo, Bowen He, Ethan Fang and 2 more

Atlanta Poster Session 2, Wed, Dec 9, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
11/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 11 of 20 reviewers recommend it
lenient 5/5
medium 6/10
strict 0/5
91%Must read
?Must readVote to see the score

INFUSER: Influence-Guided Self-Evolution Improves Reasoning

INFUSER co-evolves a question generator and solver via influence-guided rewards, improving reasoning by over 20% on math benchmarks without curated data.

Siyu Chen, Miao Lu, Beining Wu, Heejune Sheen and 6 more

Atlanta Poster Session 4, Thu, Dec 10, 4:30 PM–7:30 PM, Hall C1 · Published 2026

– ReadersNo votes yet
17/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 17 of 20 reviewers recommend it
lenient 4/5
medium 10/10
strict 3/5