CIDER is a masked-diffusion multiuser decoder using demixing and parity-aware propagation to outperform joint belief propagation by 6-100x in speed with matching error rates.
Terminator learns optimal early-exit points for chain-of-thought reasoning to cut token lengths by 14%-55% and boost inference speed over 2x with minimal accuracy loss.
DarkVGGT uses physics-aware thermal modeling and geometry-shared routing to boost feed-forward 3D reconstruction in darkness without impairing daylight performance.
TIDE injects token identity into every layer via EmbeddingMemory to fix rare-token undertraining and contextual collapse, improving language modeling and downstream performance.
Interleaved Head Attention mixes attention heads via pseudo-heads to enable cross-head reasoning, cutting parameters on synthetic tasks and improving retrieval and math benchmarks over standard multi-head attention.
CoreQ proposes a learning-free post-training quantization framework using a geometric closed-form layer-adaptive mismatch correction coefficient and successive rounding to improve LLM quantization accuracy without hyperparameter tuning.
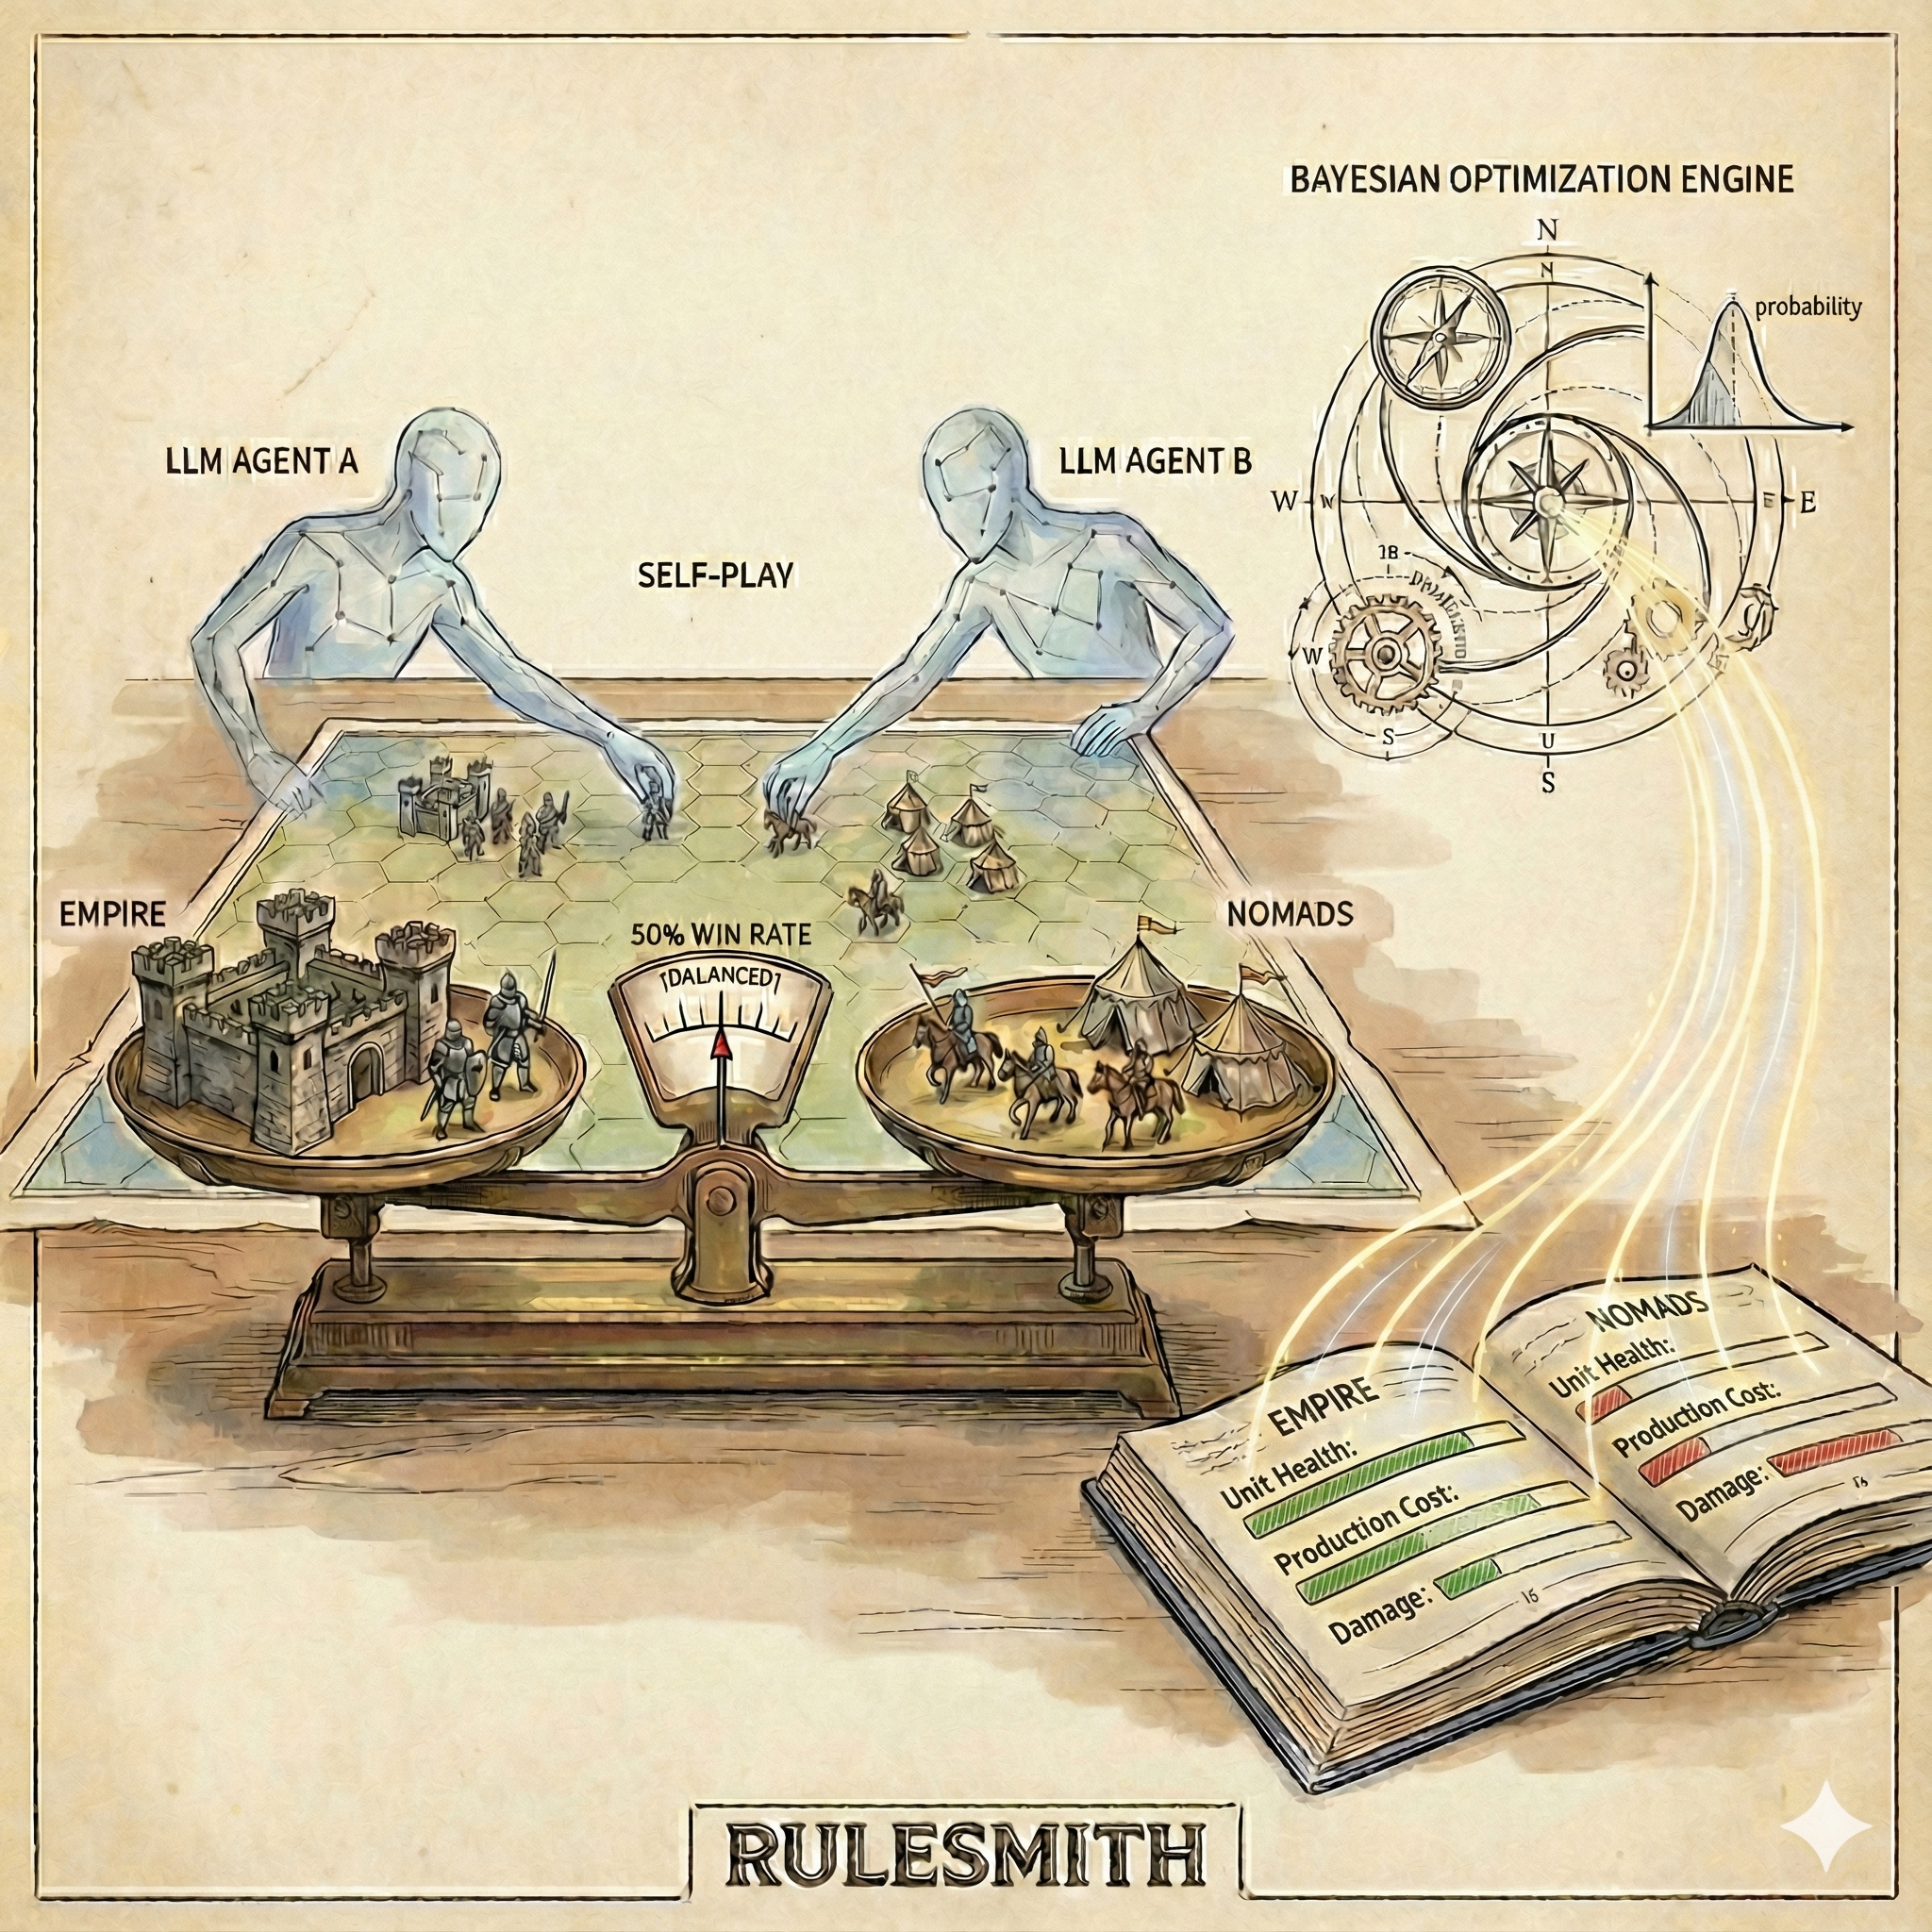
RuleSmith uses multi-agent LLM self-play and Bayesian optimization to automatically balance complex games and find highly balanced rule configurations.