Omni-Embed-Nemotron: A Unified Multimodal Retrieval Model for Text, Image, Audio, and Video
Published Oct 3, 2025▲ 4 on Hugging FacearXiv ↗
Only vote on papers you've read. Sign in to vote.
Abstract
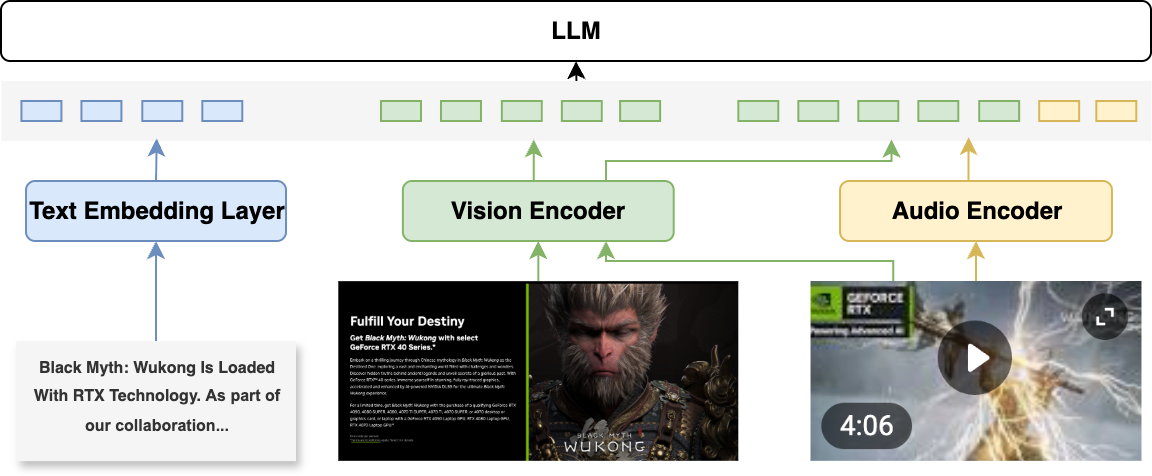
We present Omni-Embed-Nemotron, a unified multimodal retrieval embedding model developed to handle the increasing complexity of real-world information needs. While Retrieval-Augmented Generation (RAG) has significantly advanced language models by incorporating external knowledge, existing text-based retrievers rely on clean, structured input and struggle with the visually and semantically rich content found in real-world documents such as PDFs, slides, or videos. Recent work such as ColPali has shown that preserving document layout using image-based representations can improve retrieval quality. Building on this, and inspired by the capabilities of recent multimodal models such as Qwen2.5-Omni, we extend retrieval beyond text and images to also support audio and video modalities. Omni-Embed-Nemotron enables both cross-modal (e.g., text - video) and joint-modal (e.g., text - video+audio) retrieval using a single model. We describe the architecture, training setup, and evaluation results of Omni-Embed-Nemotron, and demonstrate its effectiveness in text, image, and video retrieval.