Good Papers

Showing papers from VGG, University of Oxford Show all papers

45%Niche pick
?Niche pickVote to see the score

Track4D: Representing Dense 3D Tracking for Video Diffusion Models

Yushi LAN, Zeren Jiang, Kelvin Zheng Li, Xingang Pan and 2 more

Sydney Poster Session 3, Wed, Dec 9, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
0/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 0 of 20 reviewers recommend it
lenient 0/5
medium 0/10
strict 0/5
57%Worth a look
?Worth a lookVote to see the score

Holo4D: Holistic 4D Reconstruction as Geometric Control for Video Diffusion

Yushi LAN, Zeren Jiang, Koichi Namekata, Xingang Pan and 2 more

Sydney Poster Session 4, Wed, Dec 9, 5:00 PM–8:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
1/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 1 of 20 reviewers recommend it
lenient 1/5
medium 0/10
strict 0/5
71%Highly rated
?Highly ratedVote to see the score

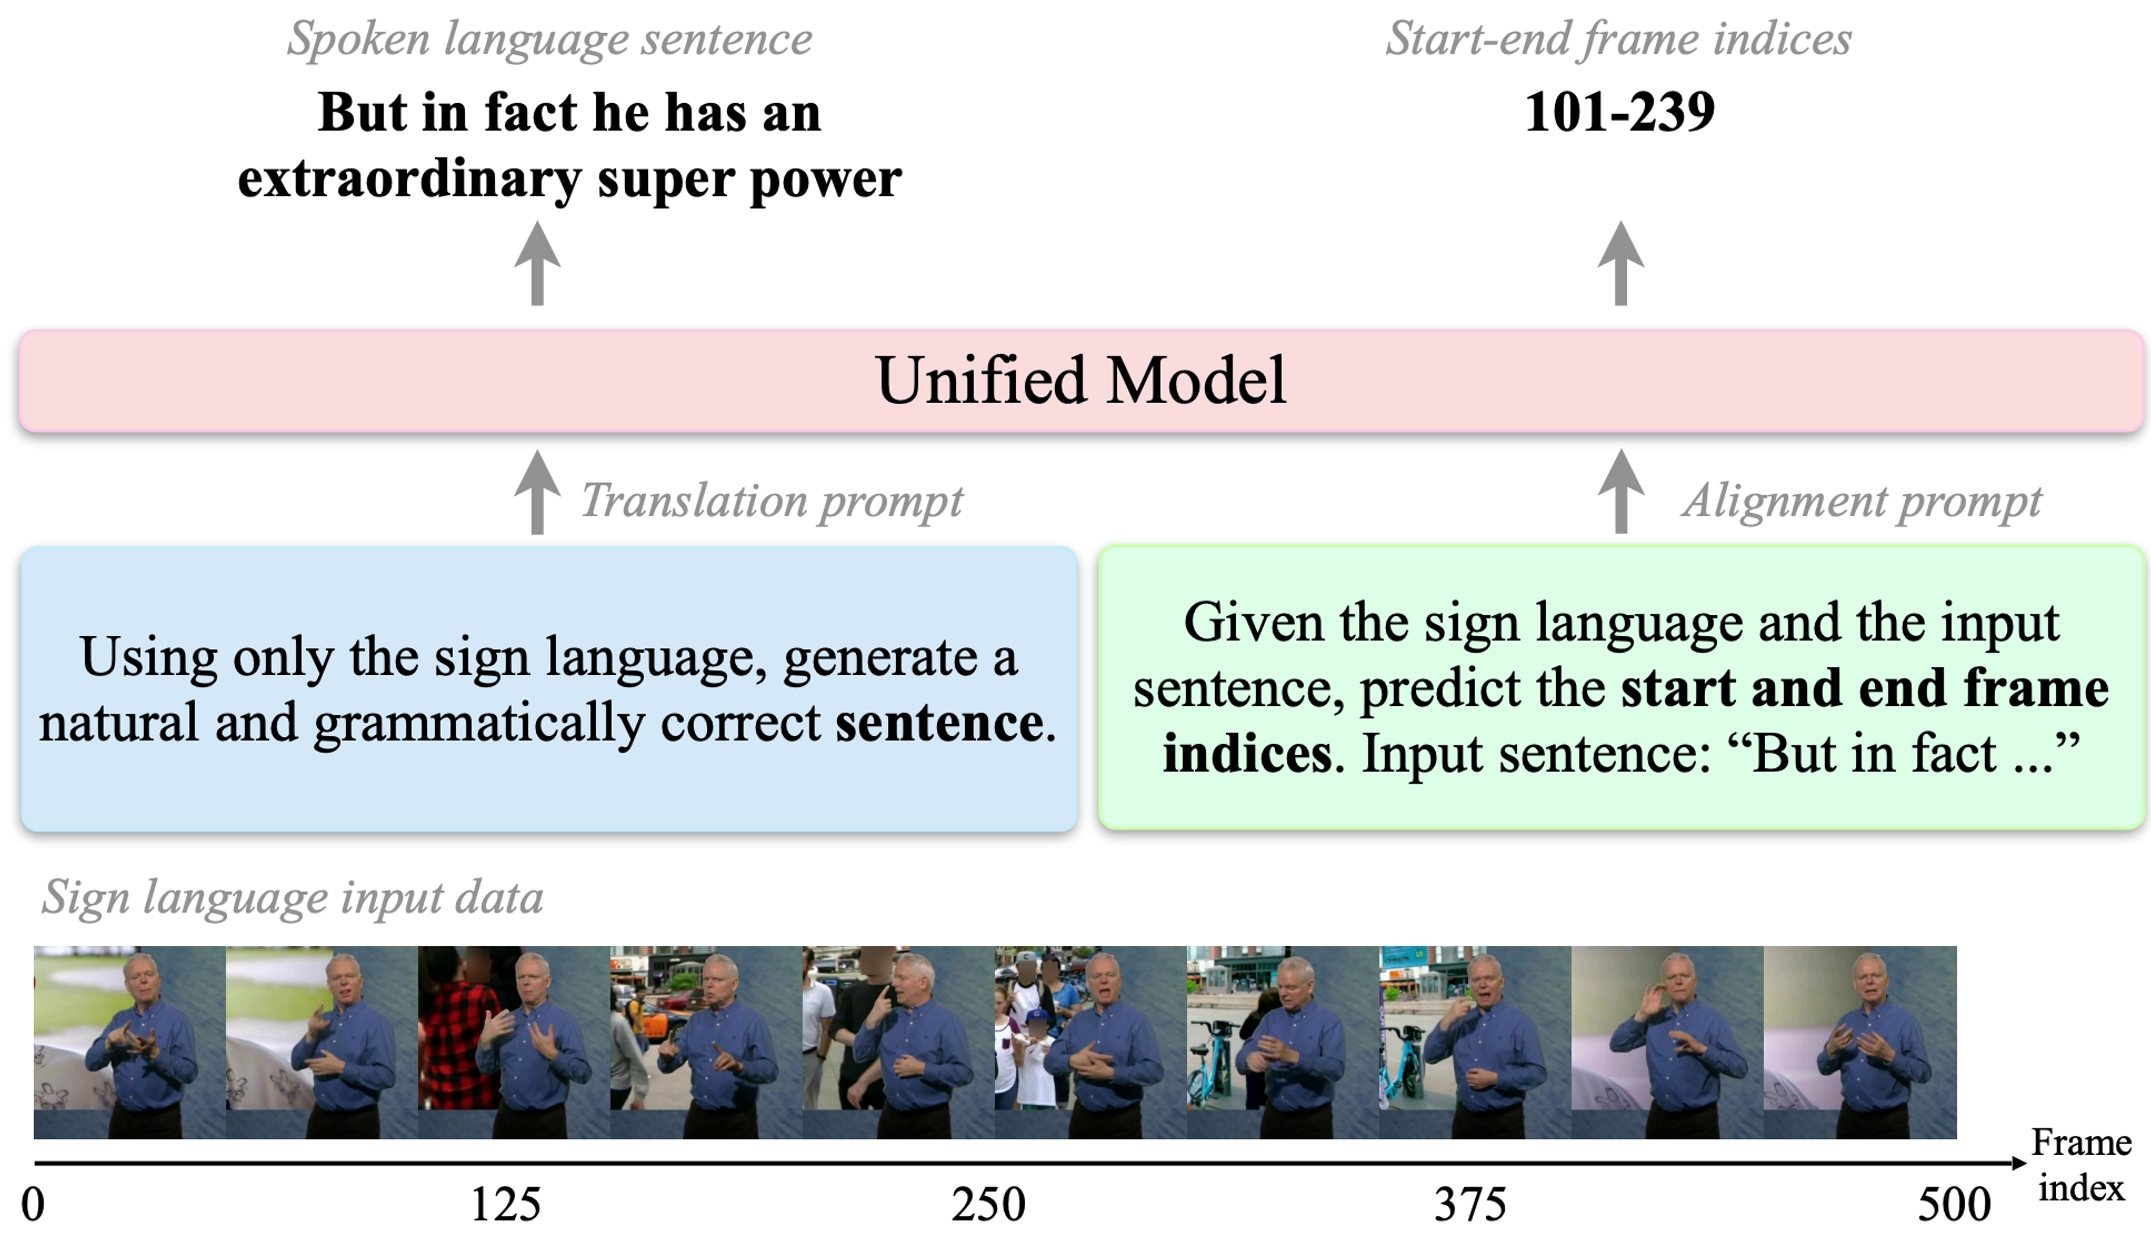
Lost in Translation, Found in Embeddings: Sign Language Translation and Alignment

A unified sign-language model with privacy-preserving keypoint inputs and sliding perceiver aggregation achieves state-of-the-art translation and alignment on BSL and generalizes to ASL.

Youngjoon Jang, Liliane Momeni, Zifan Jiang, Joon Son Chung and 2 more

Sydney Poster Session 5, Thu, Dec 10, 10:00 AM–1:00 PM, Hall 1-4 · Published 2026

– ReadersNo votes yet
7/20 AI panelreviewers recommend it

Readers and the AI panel: vote on this paper to see what they said.

Only vote on papers you've read. Sign in with GitHub to vote.

AI panel: 7 of 20 reviewers recommend it
lenient 5/5
medium 2/10
strict 0/5