Learned stochastic stopping reduces out-of-distribution variance in looped transformers by decoupling loop count from sequence length during training. It improves accuracy-stability trade-offs across algorithmic tasks, though it can stabilize suboptimal computation.
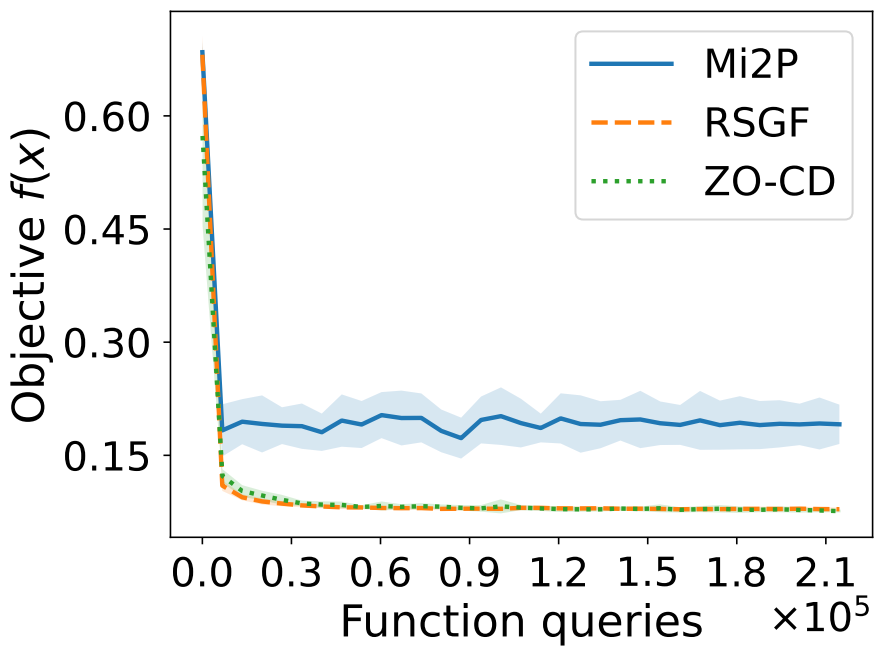
Random search for stochastic optimization works under weaker smoothness assumptions and achieves faster convergence via variance-reduced variants using translation invariance to balance noise.
Latent prediction learns hierarchical latent trees with samples constant in depth L, exponentially more efficient than token-level self-supervision, making explicit multi-scale stacking largely redundant.
Neural LoFi frames deep training as iterative spectral low-degree filtering, predicting layer-wise feature selection, concept emergence, and compositional depth via low-degree correlation dynamics.
DYSCO uses multi-view contrastive learning to recover latent dynamics and governing equations from noisy high-dimensional data, with theoretical identification guarantees and empirical validation across diverse regimes.
EyeVLM benchmarks vision-language models on gaze following and social gaze prediction, finding they lack precise gaze understanding despite training improvements.